Merge remote-tracking branch 'Evezerest/dygraph' into dygraph
 Leif
@@ -152,16 +152,6 @@ class MainWindow(QMainWindow):
|
||||
self.fileListWidget.setIconSize(QSize(25, 25))
|
||||
filelistLayout.addWidget(self.fileListWidget)
|
||||
|
||||
self.AutoRecognition = QToolButton()
|
||||
self.AutoRecognition.setToolButtonStyle(Qt.ToolButtonTextBesideIcon)
|
||||
self.AutoRecognition.setIcon(newIcon('Auto'))
|
||||
autoRecLayout = QHBoxLayout()
|
||||
autoRecLayout.setContentsMargins(0, 0, 0, 0)
|
||||
autoRecLayout.addWidget(self.AutoRecognition)
|
||||
autoRecContainer = QWidget()
|
||||
autoRecContainer.setLayout(autoRecLayout)
|
||||
filelistLayout.addWidget(autoRecContainer)
|
||||
|
||||
fileListContainer = QWidget()
|
||||
fileListContainer.setLayout(filelistLayout)
|
||||
self.fileListName = getStr('fileList')
|
||||
@@ -172,17 +162,30 @@ class MainWindow(QMainWindow):
|
||||
|
||||
# ================== Key List ==================
|
||||
if self.kie_mode:
|
||||
# self.keyList = QListWidget()
|
||||
self.keyList = UniqueLabelQListWidget()
|
||||
# self.keyList.itemSelectionChanged.connect(self.keyListSelectionChanged)
|
||||
# self.keyList.itemDoubleClicked.connect(self.editBox)
|
||||
# self.keyList.itemChanged.connect(self.keyListItemChanged)
|
||||
|
||||
# set key list height
|
||||
key_list_height = int(QApplication.desktop().height() // 4)
|
||||
if key_list_height < 50:
|
||||
key_list_height = 50
|
||||
self.keyList.setMaximumHeight(key_list_height)
|
||||
|
||||
self.keyListDockName = getStr('keyListTitle')
|
||||
self.keyListDock = QDockWidget(self.keyListDockName, self)
|
||||
self.keyListDock.setWidget(self.keyList)
|
||||
self.keyListDock.setFeatures(QDockWidget.NoDockWidgetFeatures)
|
||||
filelistLayout.addWidget(self.keyListDock)
|
||||
|
||||
self.AutoRecognition = QToolButton()
|
||||
self.AutoRecognition.setToolButtonStyle(Qt.ToolButtonTextBesideIcon)
|
||||
self.AutoRecognition.setIcon(newIcon('Auto'))
|
||||
autoRecLayout = QHBoxLayout()
|
||||
autoRecLayout.setContentsMargins(0, 0, 0, 0)
|
||||
autoRecLayout.addWidget(self.AutoRecognition)
|
||||
autoRecContainer = QWidget()
|
||||
autoRecContainer.setLayout(autoRecLayout)
|
||||
filelistLayout.addWidget(autoRecContainer)
|
||||
|
||||
# ================== Right Area ==================
|
||||
listLayout = QVBoxLayout()
|
||||
listLayout.setContentsMargins(0, 0, 0, 0)
|
||||
@@ -431,8 +434,7 @@ class MainWindow(QMainWindow):
|
||||
# ================== New Actions ==================
|
||||
|
||||
edit = action(getStr('editLabel'), self.editLabel,
|
||||
'Ctrl+E', 'edit', getStr('editLabelDetail'),
|
||||
enabled=False)
|
||||
'Ctrl+E', 'edit', getStr('editLabelDetail'), enabled=False)
|
||||
|
||||
AutoRec = action(getStr('autoRecognition'), self.autoRecognition,
|
||||
'', 'Auto', getStr('autoRecognition'), enabled=False)
|
||||
@@ -465,11 +467,10 @@ class MainWindow(QMainWindow):
|
||||
'Ctrl+Z', "undo", getStr("undo"), enabled=False)
|
||||
|
||||
change_cls = action(getStr("keyChange"), self.change_box_key,
|
||||
'Ctrl+B', "edit", getStr("keyChange"), enabled=False)
|
||||
'Ctrl+X', "edit", getStr("keyChange"), enabled=False)
|
||||
|
||||
lock = action(getStr("lockBox"), self.lockSelectedShape,
|
||||
None, "lock", getStr("lockBoxDetail"),
|
||||
enabled=False)
|
||||
None, "lock", getStr("lockBoxDetail"), enabled=False)
|
||||
|
||||
self.editButton.setDefaultAction(edit)
|
||||
self.newButton.setDefaultAction(create)
|
||||
@@ -534,9 +535,10 @@ class MainWindow(QMainWindow):
|
||||
fileMenuActions=(opendir, open_dataset_dir, saveLabel, resetAll, quit),
|
||||
beginner=(), advanced=(),
|
||||
editMenu=(createpoly, edit, copy, delete, singleRere, None, undo, undoLastPoint,
|
||||
None, rotateLeft, rotateRight, None, color1, self.drawSquaresOption, lock),
|
||||
None, rotateLeft, rotateRight, None, color1, self.drawSquaresOption, lock,
|
||||
None, change_cls),
|
||||
beginnerContext=(
|
||||
create, edit, copy, delete, singleRere, rotateLeft, rotateRight, lock, change_cls),
|
||||
create, edit, copy, delete, singleRere, rotateLeft, rotateRight, lock, change_cls),
|
||||
advancedContext=(createMode, editMode, edit, copy,
|
||||
delete, shapeLineColor, shapeFillColor),
|
||||
onLoadActive=(create, createMode, editMode),
|
||||
@@ -1105,7 +1107,9 @@ class MainWindow(QMainWindow):
|
||||
shapes = [format_shape(shape) for shape in self.canvas.shapes if shape.line_color != DEFAULT_LOCK_COLOR]
|
||||
# Can add differrent annotation formats here
|
||||
for box in self.result_dic:
|
||||
trans_dic = {"label": box[1][0], "points": box[0], "difficult": False, "key_cls": "None"}
|
||||
trans_dic = {"label": box[1][0], "points": box[0], "difficult": False}
|
||||
if self.kie_mode:
|
||||
trans_dic.update({"key_cls": "None"})
|
||||
if trans_dic["label"] == "" and mode == 'Auto':
|
||||
continue
|
||||
shapes.append(trans_dic)
|
||||
@@ -1113,8 +1117,10 @@ class MainWindow(QMainWindow):
|
||||
try:
|
||||
trans_dic = []
|
||||
for box in shapes:
|
||||
trans_dic.append({"transcription": box['label'], "points": box['points'],
|
||||
"difficult": box['difficult'], "key_cls": box['key_cls']})
|
||||
trans_dict = {"transcription": box['label'], "points": box['points'], "difficult": box['difficult']}
|
||||
if self.kie_mode:
|
||||
trans_dict.update({"key_cls": box['key_cls']})
|
||||
trans_dic.append(trans_dict)
|
||||
self.PPlabel[annotationFilePath] = trans_dic
|
||||
if mode == 'Auto':
|
||||
self.Cachelabel[annotationFilePath] = trans_dic
|
||||
@@ -1424,15 +1430,17 @@ class MainWindow(QMainWindow):
|
||||
# box['ratio'] of the shapes saved in lockedShapes contains the ratio of the
|
||||
# four corner coordinates of the shapes to the height and width of the image
|
||||
for box in self.canvas.lockedShapes:
|
||||
key_cls = None if not self.kie_mode else box['key_cls']
|
||||
if self.canvas.isInTheSameImage:
|
||||
shapes.append((box['transcription'], [[s[0] * width, s[1] * height] for s in box['ratio']],
|
||||
DEFAULT_LOCK_COLOR, box['key_cls'], box['difficult']))
|
||||
DEFAULT_LOCK_COLOR, key_cls, box['difficult']))
|
||||
else:
|
||||
shapes.append(('锁定框:待检测', [[s[0] * width, s[1] * height] for s in box['ratio']],
|
||||
DEFAULT_LOCK_COLOR, box['key_cls'], box['difficult']))
|
||||
DEFAULT_LOCK_COLOR, key_cls, box['difficult']))
|
||||
if imgidx in self.PPlabel.keys():
|
||||
for box in self.PPlabel[imgidx]:
|
||||
shapes.append((box['transcription'], box['points'], None, box['key_cls'], box['difficult']))
|
||||
key_cls = None if not self.kie_mode else box['key_cls']
|
||||
shapes.append((box['transcription'], box['points'], None, key_cls, box['difficult']))
|
||||
|
||||
self.loadLabels(shapes)
|
||||
self.canvas.verified = False
|
||||
@@ -1460,6 +1468,7 @@ class MainWindow(QMainWindow):
|
||||
def adjustScale(self, initial=False):
|
||||
value = self.scalers[self.FIT_WINDOW if initial else self.zoomMode]()
|
||||
self.zoomWidget.setValue(int(100 * value))
|
||||
self.imageSlider.setValue(self.zoomWidget.value()) # set zoom slider value
|
||||
|
||||
def scaleFitWindow(self):
|
||||
"""Figure out the size of the pixmap in order to fit the main widget."""
|
||||
@@ -1600,7 +1609,6 @@ class MainWindow(QMainWindow):
|
||||
else:
|
||||
self.keyDialog.labelList.addItems(self.existed_key_cls_set)
|
||||
|
||||
|
||||
def importDirImages(self, dirpath, isDelete=False):
|
||||
if not self.mayContinue() or not dirpath:
|
||||
return
|
||||
@@ -2238,13 +2246,22 @@ class MainWindow(QMainWindow):
|
||||
print('The program will automatically save once after confirming 5 images (default)')
|
||||
|
||||
def change_box_key(self):
|
||||
if not self.kie_mode:
|
||||
return
|
||||
key_text, _ = self.keyDialog.popUp(self.key_previous_text)
|
||||
if key_text is None:
|
||||
return
|
||||
self.key_previous_text = key_text
|
||||
for shape in self.canvas.selectedShapes:
|
||||
shape.key_cls = key_text
|
||||
if not self.keyList.findItemsByLabel(key_text):
|
||||
item = self.keyList.createItemFromLabel(key_text)
|
||||
self.keyList.addItem(item)
|
||||
rgb = self._get_rgb_by_label(key_text, self.kie_mode)
|
||||
self.keyList.setItemLabel(item, key_text, rgb)
|
||||
|
||||
self._update_shape_color(shape)
|
||||
self.keyDialog.addLabelHistory(key_text)
|
||||
|
||||
def undoShapeEdit(self):
|
||||
self.canvas.restoreShape()
|
||||
@@ -2288,9 +2305,10 @@ class MainWindow(QMainWindow):
|
||||
shapes = [format_shape(shape) for shape in self.canvas.selectedShapes]
|
||||
trans_dic = []
|
||||
for box in shapes:
|
||||
trans_dic.append({"transcription": box['label'], "ratio": box['ratio'],
|
||||
"difficult": box['difficult'],
|
||||
"key_cls": "None" if "key_cls" not in box else box["key_cls"]})
|
||||
trans_dict = {"transcription": box['label'], "ratio": box['ratio'], "difficult": box['difficult']}
|
||||
if self.kie_mode:
|
||||
trans_dict.update({"key_cls": box["key_cls"]})
|
||||
trans_dic.append(trans_dict)
|
||||
self.canvas.lockedShapes = trans_dic
|
||||
self.actions.save.setEnabled(True)
|
||||
|
||||
|
||||
@@ -9,7 +9,7 @@ PPOCRLabel is a semi-automatic graphic annotation tool suitable for OCR field, w
|
||||
### Recent Update
|
||||
|
||||
- 2022.02:(by [PeterH0323](https://github.com/peterh0323) )
|
||||
- Added KIE mode, for [detection + identification + keyword extraction] labeling.
|
||||
- Add KIE Mode by using `--kie`, for [detection + identification + keyword extraction] labeling.
|
||||
- 2022.01:(by [PeterH0323](https://github.com/peterh0323) )
|
||||
- Improve user experience: prompt for the number of files and labels, optimize interaction, and fix bugs such as only use CPU when inference
|
||||
- 2021.11.17:
|
||||
@@ -54,7 +54,10 @@ PPOCRLabel can be started in two ways: whl package and Python script. The whl pa
|
||||
|
||||
```bash
|
||||
pip install PPOCRLabel # install
|
||||
PPOCRLabel # run
|
||||
|
||||
# Select label mode and run
|
||||
PPOCRLabel # [Normal mode] for [detection + recognition] labeling
|
||||
PPOCRLabel --kie True # [KIE mode] for [detection + recognition + keyword extraction] labeling
|
||||
```
|
||||
|
||||
> If you getting this error `OSError: [WinError 126] The specified module could not be found` when you install shapely on windows. Please try to download Shapely whl file using http://www.lfd.uci.edu/~gohlke/pythonlibs/#shapely.
|
||||
@@ -67,13 +70,18 @@ PPOCRLabel # run
|
||||
```bash
|
||||
pip3 install PPOCRLabel
|
||||
pip3 install trash-cli
|
||||
PPOCRLabel
|
||||
|
||||
# Select label mode and run
|
||||
PPOCRLabel # [Normal mode] for [detection + recognition] labeling
|
||||
PPOCRLabel --kie True # [KIE mode] for [detection + recognition + keyword extraction] labeling
|
||||
```
|
||||
|
||||
#### MacOS
|
||||
```bash
|
||||
pip3 install PPOCRLabel
|
||||
pip3 install opencv-contrib-python-headless==4.2.0.32
|
||||
|
||||
# Select label mode and run
|
||||
PPOCRLabel # [Normal mode] for [detection + recognition] labeling
|
||||
PPOCRLabel --kie True # [KIE mode] for [detection + recognition + keyword extraction] labeling
|
||||
```
|
||||
@@ -90,6 +98,8 @@ pip3 install dist/PPOCRLabel-1.0.2-py2.py3-none-any.whl
|
||||
|
||||
```bash
|
||||
cd ./PPOCRLabel # Switch to the PPOCRLabel directory
|
||||
|
||||
# Select label mode and run
|
||||
python PPOCRLabel.py # [Normal mode] for [detection + recognition] labeling
|
||||
python PPOCRLabel.py --kie True # [KIE mode] for [detection + recognition + keyword extraction] labeling
|
||||
```
|
||||
@@ -156,6 +166,7 @@ python PPOCRLabel.py --kie True # [KIE mode] for [detection + recognition + keyw
|
||||
| X | Rotate the box anti-clockwise |
|
||||
| C | Rotate the box clockwise |
|
||||
| Ctrl + E | Edit label of the selected box |
|
||||
| Ctrl + X | Change key class of the box when enable `--kie` |
|
||||
| Ctrl + R | Re-recognize the selected box |
|
||||
| Ctrl + C | Copy and paste the selected box |
|
||||
| Ctrl + Left Mouse Button | Multi select the label box |
|
||||
|
||||
@@ -9,7 +9,7 @@ PPOCRLabel是一款适用于OCR领域的半自动化图形标注工具,内置P
|
||||
#### 近期更新
|
||||
|
||||
- 2022.02:(by [PeterH0323](https://github.com/peterh0323) )
|
||||
- 新增:KIE 功能,用于打【检测+识别+关键字提取】的标签
|
||||
- 新增:使用 `--kie` 进入 KIE 功能,用于打【检测+识别+关键字提取】的标签
|
||||
- 2022.01:(by [PeterH0323](https://github.com/peterh0323) )
|
||||
- 提升用户体验:新增文件与标记数目提示、优化交互、修复gpu使用等问题
|
||||
- 2021.11.17:
|
||||
@@ -57,7 +57,10 @@ PPOCRLabel可通过whl包与Python脚本两种方式启动,whl包形式启动
|
||||
|
||||
```bash
|
||||
pip install PPOCRLabel # 安装
|
||||
PPOCRLabel --lang ch # 运行
|
||||
|
||||
# 选择标签模式来启动
|
||||
PPOCRLabel --lang ch # 启动【普通模式】,用于打【检测+识别】场景的标签
|
||||
PPOCRLabel --lang ch --kie True # 启动 【KIE 模式】,用于打【检测+识别+关键字提取】场景的标签
|
||||
```
|
||||
> 注意:通过whl包安装PPOCRLabel会自动下载 `paddleocr` whl包,其中shapely依赖可能会出现 `[winRrror 126] 找不到指定模块的问题。` 的错误,建议从[这里](https://www.lfd.uci.edu/~gohlke/pythonlibs/#shapely)下载并安装
|
||||
##### Ubuntu Linux
|
||||
@@ -65,13 +68,18 @@ PPOCRLabel --lang ch # 运行
|
||||
```bash
|
||||
pip3 install PPOCRLabel
|
||||
pip3 install trash-cli
|
||||
PPOCRLabel --lang ch
|
||||
|
||||
# 选择标签模式来启动
|
||||
PPOCRLabel --lang ch # 启动【普通模式】,用于打【检测+识别】场景的标签
|
||||
PPOCRLabel --lang ch --kie True # 启动 【KIE 模式】,用于打【检测+识别+关键字提取】场景的标签
|
||||
```
|
||||
|
||||
##### MacOS
|
||||
```bash
|
||||
pip3 install PPOCRLabel
|
||||
pip3 install opencv-contrib-python-headless==4.2.0.32 # 如果下载过慢请添加"-i https://mirror.baidu.com/pypi/simple"
|
||||
|
||||
# 选择标签模式来启动
|
||||
PPOCRLabel --lang ch # 启动【普通模式】,用于打【检测+识别】场景的标签
|
||||
PPOCRLabel --lang ch --kie True # 启动 【KIE 模式】,用于打【检测+识别+关键字提取】场景的标签
|
||||
```
|
||||
@@ -92,6 +100,8 @@ pip3 install dist/PPOCRLabel-1.0.2-py2.py3-none-any.whl -i https://mirror.baidu.
|
||||
|
||||
```bash
|
||||
cd ./PPOCRLabel # 切换到PPOCRLabel目录
|
||||
|
||||
# 选择标签模式来启动
|
||||
python PPOCRLabel.py --lang ch # 启动【普通模式】,用于打【检测+识别】场景的标签
|
||||
python PPOCRLabel.py --lang ch --kie True # 启动 【KIE 模式】,用于打【检测+识别+关键字提取】场景的标签
|
||||
```
|
||||
@@ -137,25 +147,27 @@ python PPOCRLabel.py --lang ch --kie True # 启动 【KIE 模式】,用于打
|
||||
|
||||
### 3.1 快捷键
|
||||
|
||||
| 快捷键 | 说明 |
|
||||
|------------------|----------------|
|
||||
| Ctrl + shift + R | 对当前图片的所有标记重新识别 |
|
||||
| W | 新建矩形框 |
|
||||
| Q | 新建四点框 |
|
||||
| X | 框逆时针旋转 |
|
||||
| C | 框顺时针旋转 |
|
||||
| Ctrl + E | 编辑所选框标签 |
|
||||
| Ctrl + R | 重新识别所选标记 |
|
||||
| Ctrl + C | 复制并粘贴选中的标记框 |
|
||||
| Ctrl + 鼠标左键 | 多选标记框 |
|
||||
| Backspace | 删除所选框 |
|
||||
| Ctrl + V | 确认本张图片标记 |
|
||||
| Ctrl + Shift + d | 删除本张图片 |
|
||||
| D | 下一张图片 |
|
||||
| A | 上一张图片 |
|
||||
| Ctrl++ | 缩小 |
|
||||
| Ctrl-- | 放大 |
|
||||
| ↑→↓← | 移动标记框 |
|
||||
| 快捷键 | 说明 |
|
||||
|------------------|---------------------------------|
|
||||
| Ctrl + shift + R | 对当前图片的所有标记重新识别 |
|
||||
| W | 新建矩形框 |
|
||||
| Q | 新建四点框 |
|
||||
| X | 框逆时针旋转 |
|
||||
| C | 框顺时针旋转 |
|
||||
| Ctrl + E | 编辑所选框标签 |
|
||||
| Ctrl + X | `--kie` 模式下,修改 Box 的关键字种类 |
|
||||
| Ctrl + R | 重新识别所选标记 |
|
||||
| Ctrl + C | 复制并粘贴选中的标记框 |
|
||||
| Ctrl + 鼠标左键 | 多选标记框 |
|
||||
| Backspace | 删除所选框 |
|
||||
| Ctrl + V | 确认本张图片标记 |
|
||||
| Ctrl + Shift + d | 删除本张图片 |
|
||||
| D | 下一张图片 |
|
||||
| A | 上一张图片 |
|
||||
| Ctrl++ | 缩小 |
|
||||
| Ctrl-- | 放大 |
|
||||
| ↑→↓← | 移动标记框 |
|
||||
|
||||
|
||||
### 3.2 内置模型
|
||||
|
||||
|
||||
@@ -546,7 +546,7 @@ class Canvas(QWidget):
|
||||
# Give up if both fail.
|
||||
for shape in shapes:
|
||||
point = shape[0]
|
||||
offset = QPointF(2.0, 2.0)
|
||||
offset = QPointF(5.0, 5.0)
|
||||
self.calculateOffsets(shape, point)
|
||||
self.prevPoint = point
|
||||
if not self.boundedMoveShape(shape, point - offset):
|
||||
|
||||
@@ -1,6 +1,6 @@
|
||||
# -*- encoding: utf-8 -*-
|
||||
|
||||
from PyQt5.QtCore import Qt
|
||||
from PyQt5.QtCore import Qt, QSize
|
||||
from PyQt5 import QtWidgets
|
||||
|
||||
|
||||
@@ -40,6 +40,7 @@ class UniqueLabelQListWidget(EscapableQListWidget):
|
||||
qlabel.setText('<font color="#{:02x}{:02x}{:02x}">●</font> {} '.format(*color, label))
|
||||
qlabel.setAlignment(Qt.AlignBottom)
|
||||
|
||||
item.setSizeHint(qlabel.sizeHint())
|
||||
# item.setSizeHint(qlabel.sizeHint())
|
||||
item.setSizeHint(QSize(25, 25))
|
||||
|
||||
self.setItemWidget(item, qlabel)
|
||||
|
||||
@@ -32,7 +32,7 @@ PaddleOCR旨在打造一套丰富、领先、且实用的OCR工具库,助力
|
||||
- PP-OCR系列高质量预训练模型,准确的识别效果
|
||||
- 超轻量PP-OCRv2系列:检测(3.1M)+ 方向分类器(1.4M)+ 识别(8.5M)= 13.0M
|
||||
- 超轻量PP-OCR mobile移动端系列:检测(3.0M)+方向分类器(1.4M)+ 识别(5.0M)= 9.4M
|
||||
- 通用PPOCR server系列:检测(47.1M)+方向分类器(1.4M)+ 识别(94.9M)= 143.4M
|
||||
- 通用PP-OCR server系列:检测(47.1M)+方向分类器(1.4M)+ 识别(94.9M)= 143.4M
|
||||
- 支持中英文数字组合识别、竖排文本识别、长文本识别
|
||||
- 支持多语言识别:韩语、日语、德语、法语等约80种语言
|
||||
- PP-Structure文档结构化系统
|
||||
|
||||
@@ -1,5 +1,4 @@
|
||||
#!/usr/bin/env bash
|
||||
set -xe
|
||||
# 运行示例:CUDA_VISIBLE_DEVICES=0 bash run_benchmark.sh ${run_mode} ${bs_item} ${fp_item} 500 ${model_mode}
|
||||
# 参数说明
|
||||
function _set_params(){
|
||||
@@ -34,11 +33,13 @@ function _train(){
|
||||
train_cmd="python tools/train.py "${train_cmd}""
|
||||
;;
|
||||
mp)
|
||||
rm -rf ./mylog
|
||||
train_cmd="python -m paddle.distributed.launch --log_dir=./mylog --gpus=$CUDA_VISIBLE_DEVICES tools/train.py ${train_cmd}"
|
||||
;;
|
||||
*) echo "choose run_mode(sp or mp)"; exit 1;
|
||||
esac
|
||||
# 以下不用修改
|
||||
echo ${train_cmd}
|
||||
timeout 15m ${train_cmd} > ${log_file} 2>&1
|
||||
if [ $? -ne 0 ];then
|
||||
echo -e "${model_name}, FAIL"
|
||||
|
||||
@@ -56,7 +56,7 @@ PostProcess:
|
||||
thresh: 0
|
||||
box_thresh: 0.85
|
||||
min_area: 16
|
||||
box_type: box # 'box' or 'poly'
|
||||
box_type: quad # 'quad' or 'poly'
|
||||
scale: 1
|
||||
|
||||
Metric:
|
||||
|
||||
@@ -0,0 +1,139 @@
|
||||
Global:
|
||||
use_gpu: true
|
||||
epoch_num: 1500
|
||||
log_smooth_window: 20
|
||||
print_batch_step: 20
|
||||
save_model_dir: ./output/det_r50_dcn_fce_ctw/
|
||||
save_epoch_step: 100
|
||||
# evaluation is run every 835 iterations
|
||||
eval_batch_step: [0, 835]
|
||||
cal_metric_during_train: False
|
||||
pretrained_model: ./pretrain_models/ResNet50_vd_ssld_pretrained
|
||||
checkpoints:
|
||||
save_inference_dir:
|
||||
use_visualdl: False
|
||||
infer_img: doc/imgs_en/img_10.jpg
|
||||
save_res_path: ./output/det_fce/predicts_fce.txt
|
||||
|
||||
|
||||
Architecture:
|
||||
model_type: det
|
||||
algorithm: FCE
|
||||
Transform:
|
||||
Backbone:
|
||||
name: ResNet
|
||||
layers: 50
|
||||
dcn_stage: [False, True, True, True]
|
||||
out_indices: [1,2,3]
|
||||
Neck:
|
||||
name: FCEFPN
|
||||
out_channels: 256
|
||||
has_extra_convs: False
|
||||
extra_stage: 0
|
||||
Head:
|
||||
name: FCEHead
|
||||
fourier_degree: 5
|
||||
Loss:
|
||||
name: FCELoss
|
||||
fourier_degree: 5
|
||||
num_sample: 50
|
||||
|
||||
Optimizer:
|
||||
name: Adam
|
||||
beta1: 0.9
|
||||
beta2: 0.999
|
||||
lr:
|
||||
learning_rate: 0.0001
|
||||
regularizer:
|
||||
name: 'L2'
|
||||
factor: 0
|
||||
|
||||
PostProcess:
|
||||
name: FCEPostProcess
|
||||
scales: [8, 16, 32]
|
||||
alpha: 1.0
|
||||
beta: 1.0
|
||||
fourier_degree: 5
|
||||
box_type: 'poly'
|
||||
|
||||
Metric:
|
||||
name: DetFCEMetric
|
||||
main_indicator: hmean
|
||||
|
||||
Train:
|
||||
dataset:
|
||||
name: SimpleDataSet
|
||||
data_dir: ./train_data/ctw1500/imgs/
|
||||
label_file_list:
|
||||
- ./train_data/ctw1500/imgs/training.txt
|
||||
transforms:
|
||||
- DecodeImage: # load image
|
||||
img_mode: BGR
|
||||
channel_first: False
|
||||
ignore_orientation: True
|
||||
- DetLabelEncode: # Class handling label
|
||||
- ColorJitter:
|
||||
brightness: 0.142
|
||||
saturation: 0.5
|
||||
contrast: 0.5
|
||||
- RandomScaling:
|
||||
- RandomCropFlip:
|
||||
crop_ratio: 0.5
|
||||
- RandomCropPolyInstances:
|
||||
crop_ratio: 0.8
|
||||
min_side_ratio: 0.3
|
||||
- RandomRotatePolyInstances:
|
||||
rotate_ratio: 0.5
|
||||
max_angle: 30
|
||||
pad_with_fixed_color: False
|
||||
- SquareResizePad:
|
||||
target_size: 800
|
||||
pad_ratio: 0.6
|
||||
- IaaAugment:
|
||||
augmenter_args:
|
||||
- { 'type': Fliplr, 'args': { 'p': 0.5 } }
|
||||
- FCENetTargets:
|
||||
fourier_degree: 5
|
||||
- NormalizeImage:
|
||||
scale: 1./255.
|
||||
mean: [0.485, 0.456, 0.406]
|
||||
std: [0.229, 0.224, 0.225]
|
||||
order: 'hwc'
|
||||
- ToCHWImage:
|
||||
- KeepKeys:
|
||||
keep_keys: ['image', 'p3_maps', 'p4_maps', 'p5_maps'] # dataloader will return list in this order
|
||||
loader:
|
||||
shuffle: True
|
||||
drop_last: False
|
||||
batch_size_per_card: 6
|
||||
num_workers: 8
|
||||
|
||||
Eval:
|
||||
dataset:
|
||||
name: SimpleDataSet
|
||||
data_dir: ./train_data/ctw1500/imgs/
|
||||
label_file_list:
|
||||
- ./train_data/ctw1500/imgs/test.txt
|
||||
transforms:
|
||||
- DecodeImage: # load image
|
||||
img_mode: BGR
|
||||
channel_first: False
|
||||
ignore_orientation: True
|
||||
- DetLabelEncode: # Class handling label
|
||||
- DetResizeForTest:
|
||||
limit_type: 'min'
|
||||
limit_side_len: 736
|
||||
- NormalizeImage:
|
||||
scale: 1./255.
|
||||
mean: [0.485, 0.456, 0.406]
|
||||
std: [0.229, 0.224, 0.225]
|
||||
order: 'hwc'
|
||||
- Pad:
|
||||
- ToCHWImage:
|
||||
- KeepKeys:
|
||||
keep_keys: ['image', 'shape', 'polys', 'ignore_tags']
|
||||
loader:
|
||||
shuffle: False
|
||||
drop_last: False
|
||||
batch_size_per_card: 1 # must be 1
|
||||
num_workers: 2
|
||||
@@ -55,7 +55,7 @@ PostProcess:
|
||||
thresh: 0
|
||||
box_thresh: 0.85
|
||||
min_area: 16
|
||||
box_type: box # 'box' or 'poly'
|
||||
box_type: quad # 'quad' or 'poly'
|
||||
scale: 1
|
||||
|
||||
Metric:
|
||||
|
||||
@@ -0,0 +1,92 @@
|
||||
Global:
|
||||
use_gpu: True
|
||||
epoch_num: 8
|
||||
log_smooth_window: 20
|
||||
print_batch_step: 5
|
||||
save_model_dir: ./output/rec/pren_new
|
||||
save_epoch_step: 3
|
||||
# evaluation is run every 2000 iterations after the 4000th iteration
|
||||
eval_batch_step: [4000, 2000]
|
||||
cal_metric_during_train: True
|
||||
pretrained_model:
|
||||
checkpoints:
|
||||
save_inference_dir:
|
||||
use_visualdl: False
|
||||
infer_img: doc/imgs_words/ch/word_1.jpg
|
||||
# for data or label process
|
||||
character_dict_path:
|
||||
max_text_length: &max_text_length 25
|
||||
infer_mode: False
|
||||
use_space_char: False
|
||||
save_res_path: ./output/rec/predicts_pren.txt
|
||||
|
||||
Optimizer:
|
||||
name: Adadelta
|
||||
lr:
|
||||
name: Piecewise
|
||||
decay_epochs: [2, 5, 7]
|
||||
values: [0.5, 0.1, 0.01, 0.001]
|
||||
|
||||
Architecture:
|
||||
model_type: rec
|
||||
algorithm: PREN
|
||||
in_channels: 3
|
||||
Backbone:
|
||||
name: EfficientNetb3_PREN
|
||||
Neck:
|
||||
name: PRENFPN
|
||||
n_r: 5
|
||||
d_model: 384
|
||||
max_len: *max_text_length
|
||||
dropout: 0.1
|
||||
Head:
|
||||
name: PRENHead
|
||||
|
||||
Loss:
|
||||
name: PRENLoss
|
||||
|
||||
PostProcess:
|
||||
name: PRENLabelDecode
|
||||
|
||||
Metric:
|
||||
name: RecMetric
|
||||
main_indicator: acc
|
||||
|
||||
Train:
|
||||
dataset:
|
||||
name: LMDBDataSet
|
||||
data_dir: ./train_data/data_lmdb_release/training/
|
||||
transforms:
|
||||
- DecodeImage:
|
||||
img_mode: BGR
|
||||
channel_first: False
|
||||
- PRENLabelEncode:
|
||||
- RecAug:
|
||||
- PRENResizeImg:
|
||||
image_shape: [64, 256] # h,w
|
||||
- KeepKeys:
|
||||
keep_keys: ['image', 'label']
|
||||
loader:
|
||||
shuffle: True
|
||||
batch_size_per_card: 128
|
||||
drop_last: True
|
||||
num_workers: 8
|
||||
|
||||
Eval:
|
||||
dataset:
|
||||
name: LMDBDataSet
|
||||
data_dir: ./train_data/data_lmdb_release/validation/
|
||||
transforms:
|
||||
- DecodeImage:
|
||||
img_mode: BGR
|
||||
channel_first: False
|
||||
- PRENLabelEncode:
|
||||
- PRENResizeImg:
|
||||
image_shape: [64, 256] # h,w
|
||||
- KeepKeys:
|
||||
keep_keys: ['image', 'label']
|
||||
loader:
|
||||
shuffle: False
|
||||
drop_last: False
|
||||
batch_size_per_card: 64
|
||||
num_workers: 8
|
||||
@@ -1,19 +1,118 @@
|
||||
# 如何快速测试
|
||||
### 1. 安装最新版本的Android Studio
|
||||
可以从 https://developer.android.com/studio 下载。本Demo使用是4.0版本Android Studio编写。
|
||||
- [Android Demo](#android-demo)
|
||||
- [1. 简介](#1-简介)
|
||||
- [2. 近期更新](#2-近期更新)
|
||||
- [3. 快速使用](#3-快速使用)
|
||||
- [3.1 环境准备](#31-环境准备)
|
||||
- [3.2 导入项目](#32-导入项目)
|
||||
- [3.3 运行demo](#33-运行demo)
|
||||
- [3.4 运行模式](#34-运行模式)
|
||||
- [3.5 设置](#35-设置)
|
||||
- [4 更多支持](#4-更多支持)
|
||||
|
||||
### 2. 按照NDK 20 以上版本
|
||||
Demo测试的时候使用的是NDK 20b版本,20版本以上均可以支持编译成功。
|
||||
# Android Demo
|
||||
|
||||
如果您是初学者,可以用以下方式安装和测试NDK编译环境。
|
||||
点击 File -> New ->New Project, 新建 "Native C++" project
|
||||
## 1. 简介
|
||||
此为PaddleOCR的Android Demo,目前支持文本检测,文本方向分类器和文本识别模型的使用。使用 [PaddleLite v2.10](https://github.com/PaddlePaddle/Paddle-Lite/tree/release/v2.10) 进行开发。
|
||||
|
||||
## 2. 近期更新
|
||||
* 2022.02.27
|
||||
* 预测库更新到PaddleLite v2.10
|
||||
* 支持6种运行模式:
|
||||
* 检测+分类+识别
|
||||
* 检测+识别
|
||||
* 分类+识别
|
||||
* 检测
|
||||
* 识别
|
||||
* 分类
|
||||
|
||||
## 3. 快速使用
|
||||
|
||||
### 3.1 环境准备
|
||||
1. 在本地环境安装好 Android Studio 工具,详细安装方法请见[Android Stuido 官网](https://developer.android.com/studio)。
|
||||
2. 准备一部 Android 手机,并开启 USB 调试模式。开启方法: `手机设置 -> 查找开发者选项 -> 打开开发者选项和 USB 调试模式`
|
||||
|
||||
**注意**:如果您的 Android Studio 尚未配置 NDK ,请根据 Android Studio 用户指南中的[安装及配置 NDK 和 CMake ](https://developer.android.com/studio/projects/install-ndk)内容,预先配置好 NDK 。您可以选择最新的 NDK 版本,或者使用 Paddle Lite 预测库版本一样的 NDK
|
||||
|
||||
### 3.2 导入项目
|
||||
|
||||
### 3. 导入项目
|
||||
点击 File->New->Import Project..., 然后跟着Android Studio的引导导入
|
||||
导入完成后呈现如下界面
|
||||
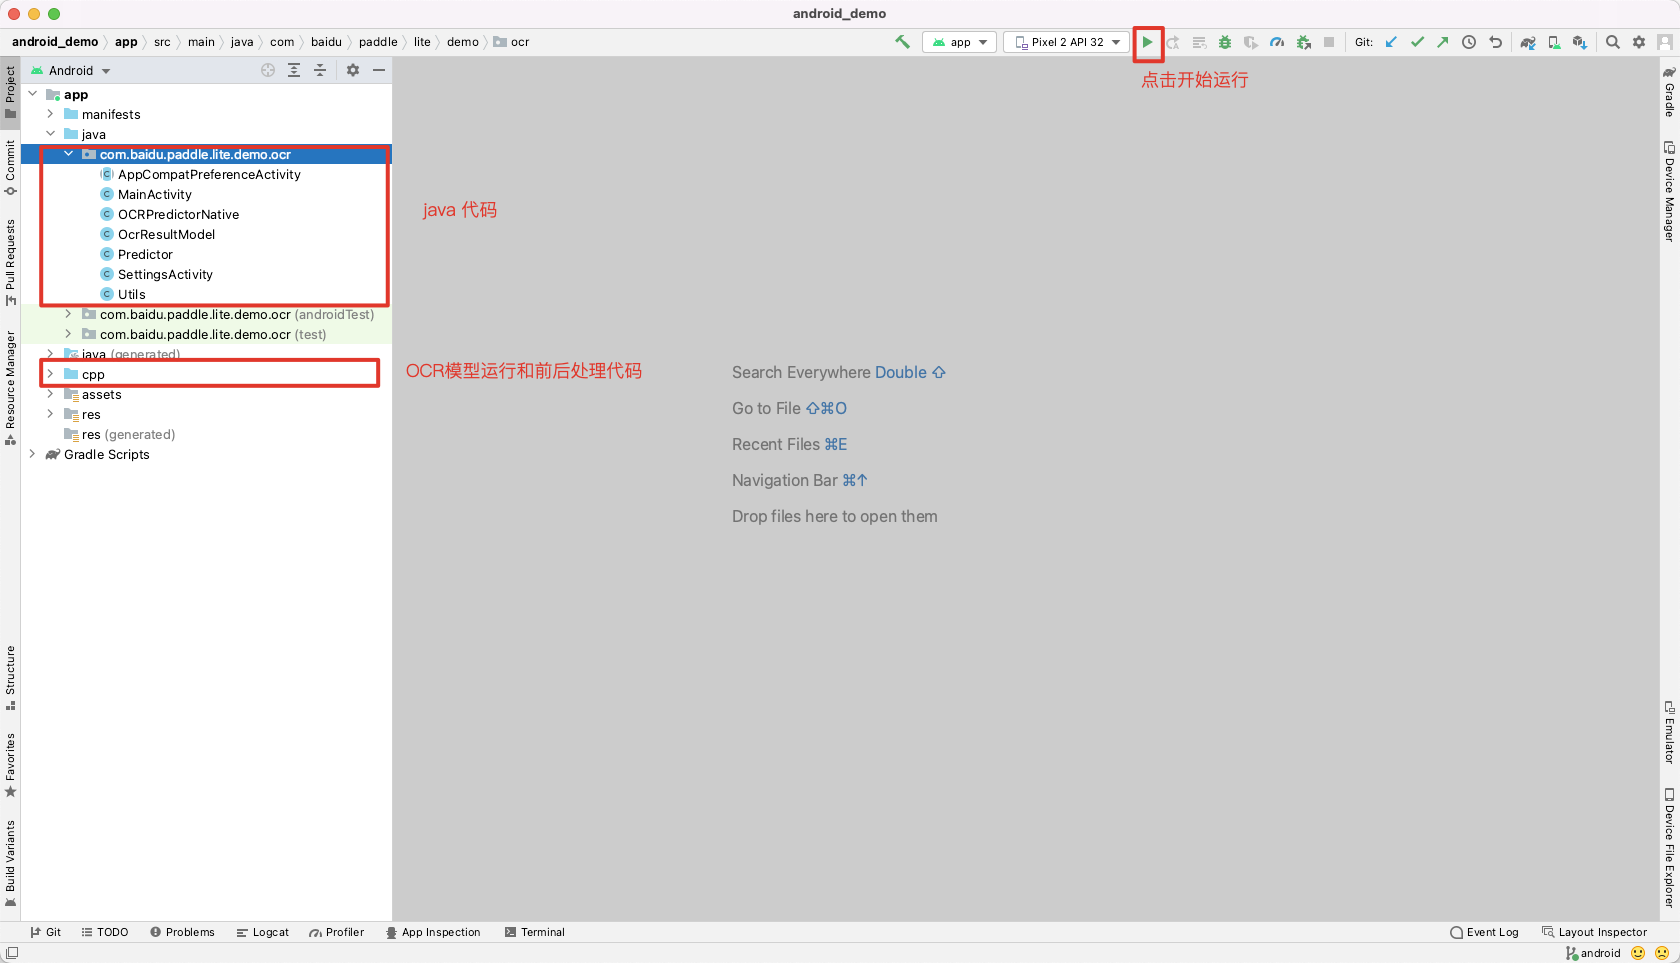
|
||||
|
||||
### 3.3 运行demo
|
||||
将手机连接上电脑后,点击Android Studio工具栏中的运行按钮即可运行demo。在此过程中,手机会弹出"允许从 USB 安装软件权限"的弹窗,点击允许即可。
|
||||
|
||||
软件安转到手机上后会在手机主屏最后一页看到如下app
|
||||
<div align="left">
|
||||
<img src="https://paddleocr.bj.bcebos.com/PP-OCRv2/lite/imgs/install_finish.jpeg" width="400">
|
||||
</div>
|
||||
|
||||
点击app图标即可启动app,启动后app主页如下
|
||||
|
||||
<div align="left">
|
||||
<img src="https://paddleocr.bj.bcebos.com/PP-OCRv2/lite/imgs/main_page.jpg" width="400">
|
||||
</div>
|
||||
|
||||
app主页中有四个按钮,一个下拉列表和一个菜单按钮,他们的功能分别为
|
||||
|
||||
* 运行模型:按照已选择的模式,运行对应的模型组合
|
||||
* 拍照识别:唤起手机相机拍照并获取拍照的图像,拍照完成后需要点击运行模型进行识别
|
||||
* 选取图片:唤起手机相册拍照选择图像,选择完成后需要点击运行模型进行识别
|
||||
* 清空绘图:清空当前显示图像上绘制的文本框,以便进行下一次识别(每次识别使用的图像都是当前显示的图像)
|
||||
* 下拉列表:进行运行模式的选择,目前包含6种运行模式,默认模式为**检测+分类+识别**详细说明见下一节。
|
||||
* 菜单按钮:点击后会进入菜单界面,进行模型和内置图像有关设置
|
||||
|
||||
点击运行模型后,会按照所选择的模式运行对应的模型,**检测+分类+识别**模式下运行的模型结果如下所示:
|
||||
|
||||
<img src="https://paddleocr.bj.bcebos.com/PP-OCRv2/lite/imgs/run_det_cls_rec.jpg" width="400">
|
||||
|
||||
模型运行完成后,模型和运行状态显示区`STATUS`字段显示了当前模型的运行状态,这里显示为`run model successed`表明模型运行成功。
|
||||
|
||||
模型的运行结果显示在运行结果显示区,显示格式为
|
||||
```text
|
||||
序号:Det:(x1,y1)(x2,y2)(x3,y3)(x4,y4) Rec: 识别文本,识别置信度 Cls:分类类别,分类分时
|
||||
```
|
||||
|
||||
### 3.4 运行模式
|
||||
|
||||
PaddleOCR demo共提供了6种运行模式,如下图
|
||||
<div align="left">
|
||||
<img src="https://paddleocr.bj.bcebos.com/PP-OCRv2/lite/imgs/select_mode.jpg" width="400">
|
||||
</div>
|
||||
|
||||
每种模式的运行结果如下表所示
|
||||
|
||||
| 检测+分类+识别 | 检测+识别 | 分类+识别 |
|
||||
|------------------------------------------------------------------------------------------------|--------------------------------------------------------------------------------------------|--------------------------------------------------------------------------------------------|
|
||||
| <img src="https://paddleocr.bj.bcebos.com/PP-OCRv2/lite/imgs/run_det_cls_rec.jpg" width="400"> | <img src="https://paddleocr.bj.bcebos.com/PP-OCRv2/lite/imgs/run_det_rec.jpg" width="400"> | <img src="https://paddleocr.bj.bcebos.com/PP-OCRv2/lite/imgs/run_cls_rec.jpg" width="400"> |
|
||||
|
||||
|
||||
# 获得更多支持
|
||||
前往[端计算模型生成平台EasyEdge](https://ai.baidu.com/easyedge/app/open_source_demo?referrerUrl=paddlelite),获得更多开发支持:
|
||||
| 检测 | 识别 | 分类 |
|
||||
|----------------------------------------------------------------------------------------|----------------------------------------------------------------------------------------|----------------------------------------------------------------------------------------|
|
||||
| <img src="https://paddleocr.bj.bcebos.com/PP-OCRv2/lite/imgs/run_det.jpg" width="400"> | <img src="https://paddleocr.bj.bcebos.com/PP-OCRv2/lite/imgs/run_rec.jpg" width="400"> | <img src="https://paddleocr.bj.bcebos.com/PP-OCRv2/lite/imgs/run_cls.jpg" width="400"> |
|
||||
|
||||
- Demo APP:可使用手机扫码安装,方便手机端快速体验文字识别
|
||||
- SDK:模型被封装为适配不同芯片硬件和操作系统SDK,包括完善的接口,方便进行二次开发
|
||||
### 3.5 设置
|
||||
|
||||
设置界面如下
|
||||
|
||||
<div align="left">
|
||||
<img src="https://paddleocr.bj.bcebos.com/PP-OCRv2/lite/imgs/settings.jpg" width="400">
|
||||
</div>
|
||||
|
||||
在设置界面可以进行如下几项设定:
|
||||
1. 普通设置
|
||||
* Enable custom settings: 选中状态下才能更改设置
|
||||
* Model Path: 所运行的模型地址,使用默认值就好
|
||||
* Label Path: 识别模型的字典
|
||||
* Image Path: 进行识别的内置图像名
|
||||
2. 模型运行态设置,此项设置更改后返回主界面时,会自动重新加载模型
|
||||
* CPU Thread Num: 模型运行使用的CPU核心数量
|
||||
* CPU Power Mode: 模型运行模式,大小核设定
|
||||
3. 输入设置
|
||||
* det long size: DB模型预处理时图像的长边长度,超过此长度resize到该值,短边进行等比例缩放,小于此长度不进行处理。
|
||||
4. 输出设置
|
||||
* Score Threshold: DB模型后处理box的阈值,低于此阈值的box进行过滤,不显示。
|
||||
|
||||
## 4 更多支持
|
||||
1. 实时识别,更新预测库可参考 https://github.com/PaddlePaddle/Paddle-Lite-Demo/tree/develop/ocr/android/app/cxx/ppocr_demo
|
||||
2. 更多Paddle-Lite相关问题可前往[Paddle-Lite](https://github.com/PaddlePaddle/Paddle-Lite) ,获得更多开发支持
|
||||
|
||||
@@ -8,8 +8,8 @@ android {
|
||||
applicationId "com.baidu.paddle.lite.demo.ocr"
|
||||
minSdkVersion 23
|
||||
targetSdkVersion 29
|
||||
versionCode 1
|
||||
versionName "1.0"
|
||||
versionCode 2
|
||||
versionName "2.0"
|
||||
testInstrumentationRunner "android.support.test.runner.AndroidJUnitRunner"
|
||||
externalNativeBuild {
|
||||
cmake {
|
||||
@@ -17,11 +17,6 @@ android {
|
||||
arguments '-DANDROID_PLATFORM=android-23', '-DANDROID_STL=c++_shared' ,"-DANDROID_ARM_NEON=TRUE"
|
||||
}
|
||||
}
|
||||
ndk {
|
||||
// abiFilters "arm64-v8a", "armeabi-v7a"
|
||||
abiFilters "arm64-v8a", "armeabi-v7a"
|
||||
ldLibs "jnigraphics"
|
||||
}
|
||||
}
|
||||
buildTypes {
|
||||
release {
|
||||
@@ -48,7 +43,7 @@ dependencies {
|
||||
|
||||
def archives = [
|
||||
[
|
||||
'src' : 'https://paddleocr.bj.bcebos.com/dygraph_v2.0/lite/paddle_lite_libs_v2_9_0.tar.gz',
|
||||
'src' : 'https://paddleocr.bj.bcebos.com/libs/paddle_lite_libs_v2_10.tar.gz',
|
||||
'dest': 'PaddleLite'
|
||||
],
|
||||
[
|
||||
@@ -56,7 +51,7 @@ def archives = [
|
||||
'dest': 'OpenCV'
|
||||
],
|
||||
[
|
||||
'src' : 'https://paddleocr.bj.bcebos.com/dygraph_v2.0/lite/ocr_v2_for_cpu.tar.gz',
|
||||
'src' : 'https://paddleocr.bj.bcebos.com/PP-OCRv2/lite/ch_PP-OCRv2.tar.gz',
|
||||
'dest' : 'src/main/assets/models'
|
||||
],
|
||||
[
|
||||
|
||||
@@ -14,7 +14,6 @@
|
||||
android:roundIcon="@mipmap/ic_launcher_round"
|
||||
android:supportsRtl="true"
|
||||
android:theme="@style/AppTheme">
|
||||
<!-- to test MiniActivity, change this to com.baidu.paddle.lite.demo.ocr.MiniActivity -->
|
||||
<activity android:name="com.baidu.paddle.lite.demo.ocr.MainActivity">
|
||||
<intent-filter>
|
||||
<action android:name="android.intent.action.MAIN"/>
|
||||
|
||||

|
Before Width: | Height: | Size: 62 KiB After Width: | Height: | Size: 62 KiB |

|
Before Width: | Height: | Size: 63 KiB After Width: | Height: | Size: 63 KiB |

|
Before Width: | Height: | Size: 171 KiB After Width: | Height: | Size: 171 KiB |

|
Before Width: | Height: | Size: 61 KiB After Width: | Height: | Size: 61 KiB |

|
After Width: | Height: | Size: 6.2 KiB |

|
After Width: | Height: | Size: 6.6 KiB |

|
After Width: | Height: | Size: 7.8 KiB |

|
After Width: | Height: | Size: 8.1 KiB |
@@ -13,7 +13,7 @@ static paddle::lite_api::PowerMode str_to_cpu_mode(const std::string &cpu_mode);
|
||||
extern "C" JNIEXPORT jlong JNICALL
|
||||
Java_com_baidu_paddle_lite_demo_ocr_OCRPredictorNative_init(
|
||||
JNIEnv *env, jobject thiz, jstring j_det_model_path,
|
||||
jstring j_rec_model_path, jstring j_cls_model_path, jint j_thread_num,
|
||||
jstring j_rec_model_path, jstring j_cls_model_path, jint j_use_opencl, jint j_thread_num,
|
||||
jstring j_cpu_mode) {
|
||||
std::string det_model_path = jstring_to_cpp_string(env, j_det_model_path);
|
||||
std::string rec_model_path = jstring_to_cpp_string(env, j_rec_model_path);
|
||||
@@ -21,6 +21,7 @@ Java_com_baidu_paddle_lite_demo_ocr_OCRPredictorNative_init(
|
||||
int thread_num = j_thread_num;
|
||||
std::string cpu_mode = jstring_to_cpp_string(env, j_cpu_mode);
|
||||
ppredictor::OCR_Config conf;
|
||||
conf.use_opencl = j_use_opencl;
|
||||
conf.thread_num = thread_num;
|
||||
conf.mode = str_to_cpu_mode(cpu_mode);
|
||||
ppredictor::OCR_PPredictor *orc_predictor =
|
||||
@@ -57,32 +58,31 @@ str_to_cpu_mode(const std::string &cpu_mode) {
|
||||
|
||||
extern "C" JNIEXPORT jfloatArray JNICALL
|
||||
Java_com_baidu_paddle_lite_demo_ocr_OCRPredictorNative_forward(
|
||||
JNIEnv *env, jobject thiz, jlong java_pointer, jfloatArray buf,
|
||||
jfloatArray ddims, jobject original_image) {
|
||||
JNIEnv *env, jobject thiz, jlong java_pointer, jobject original_image,jint j_max_size_len, jint j_run_det, jint j_run_cls, jint j_run_rec) {
|
||||
LOGI("begin to run native forward");
|
||||
if (java_pointer == 0) {
|
||||
LOGE("JAVA pointer is NULL");
|
||||
return cpp_array_to_jfloatarray(env, nullptr, 0);
|
||||
}
|
||||
|
||||
cv::Mat origin = bitmap_to_cv_mat(env, original_image);
|
||||
if (origin.size == 0) {
|
||||
LOGE("origin bitmap cannot convert to CV Mat");
|
||||
return cpp_array_to_jfloatarray(env, nullptr, 0);
|
||||
}
|
||||
|
||||
int max_size_len = j_max_size_len;
|
||||
int run_det = j_run_det;
|
||||
int run_cls = j_run_cls;
|
||||
int run_rec = j_run_rec;
|
||||
|
||||
ppredictor::OCR_PPredictor *ppredictor =
|
||||
(ppredictor::OCR_PPredictor *)java_pointer;
|
||||
std::vector<float> dims_float_arr = jfloatarray_to_float_vector(env, ddims);
|
||||
std::vector<int64_t> dims_arr;
|
||||
dims_arr.resize(dims_float_arr.size());
|
||||
std::copy(dims_float_arr.cbegin(), dims_float_arr.cend(), dims_arr.begin());
|
||||
|
||||
// 这里值有点大,就不调用jfloatarray_to_float_vector了
|
||||
int64_t buf_len = (int64_t)env->GetArrayLength(buf);
|
||||
jfloat *buf_data = env->GetFloatArrayElements(buf, JNI_FALSE);
|
||||
float *data = (jfloat *)buf_data;
|
||||
std::vector<ppredictor::OCRPredictResult> results =
|
||||
ppredictor->infer_ocr(dims_arr, data, buf_len, NET_OCR, origin);
|
||||
ppredictor->infer_ocr(origin, max_size_len, run_det, run_cls, run_rec);
|
||||
LOGI("infer_ocr finished with boxes %ld", results.size());
|
||||
|
||||
// 这里将std::vector<ppredictor::OCRPredictResult> 序列化成
|
||||
// float数组,传输到java层再反序列化
|
||||
std::vector<float> float_arr;
|
||||
@@ -90,13 +90,18 @@ Java_com_baidu_paddle_lite_demo_ocr_OCRPredictorNative_forward(
|
||||
float_arr.push_back(r.points.size());
|
||||
float_arr.push_back(r.word_index.size());
|
||||
float_arr.push_back(r.score);
|
||||
// add det point
|
||||
for (const std::vector<int> &point : r.points) {
|
||||
float_arr.push_back(point.at(0));
|
||||
float_arr.push_back(point.at(1));
|
||||
}
|
||||
// add rec word idx
|
||||
for (int index : r.word_index) {
|
||||
float_arr.push_back(index);
|
||||
}
|
||||
// add cls result
|
||||
float_arr.push_back(r.cls_label);
|
||||
float_arr.push_back(r.cls_score);
|
||||
}
|
||||
return cpp_array_to_jfloatarray(env, float_arr.data(), float_arr.size());
|
||||
}
|
||||
|
||||
@@ -17,15 +17,15 @@ int OCR_PPredictor::init(const std::string &det_model_content,
|
||||
const std::string &rec_model_content,
|
||||
const std::string &cls_model_content) {
|
||||
_det_predictor = std::unique_ptr<PPredictor>(
|
||||
new PPredictor{_config.thread_num, NET_OCR, _config.mode});
|
||||
new PPredictor{_config.use_opencl,_config.thread_num, NET_OCR, _config.mode});
|
||||
_det_predictor->init_nb(det_model_content);
|
||||
|
||||
_rec_predictor = std::unique_ptr<PPredictor>(
|
||||
new PPredictor{_config.thread_num, NET_OCR_INTERNAL, _config.mode});
|
||||
new PPredictor{_config.use_opencl,_config.thread_num, NET_OCR_INTERNAL, _config.mode});
|
||||
_rec_predictor->init_nb(rec_model_content);
|
||||
|
||||
_cls_predictor = std::unique_ptr<PPredictor>(
|
||||
new PPredictor{_config.thread_num, NET_OCR_INTERNAL, _config.mode});
|
||||
new PPredictor{_config.use_opencl,_config.thread_num, NET_OCR_INTERNAL, _config.mode});
|
||||
_cls_predictor->init_nb(cls_model_content);
|
||||
return RETURN_OK;
|
||||
}
|
||||
@@ -34,15 +34,16 @@ int OCR_PPredictor::init_from_file(const std::string &det_model_path,
|
||||
const std::string &rec_model_path,
|
||||
const std::string &cls_model_path) {
|
||||
_det_predictor = std::unique_ptr<PPredictor>(
|
||||
new PPredictor{_config.thread_num, NET_OCR, _config.mode});
|
||||
new PPredictor{_config.use_opencl, _config.thread_num, NET_OCR, _config.mode});
|
||||
_det_predictor->init_from_file(det_model_path);
|
||||
|
||||
|
||||
_rec_predictor = std::unique_ptr<PPredictor>(
|
||||
new PPredictor{_config.thread_num, NET_OCR_INTERNAL, _config.mode});
|
||||
new PPredictor{_config.use_opencl,_config.thread_num, NET_OCR_INTERNAL, _config.mode});
|
||||
_rec_predictor->init_from_file(rec_model_path);
|
||||
|
||||
_cls_predictor = std::unique_ptr<PPredictor>(
|
||||
new PPredictor{_config.thread_num, NET_OCR_INTERNAL, _config.mode});
|
||||
new PPredictor{_config.use_opencl,_config.thread_num, NET_OCR_INTERNAL, _config.mode});
|
||||
_cls_predictor->init_from_file(cls_model_path);
|
||||
return RETURN_OK;
|
||||
}
|
||||
@@ -77,90 +78,173 @@ visual_img(const std::vector<std::vector<std::vector<int>>> &filter_boxes,
|
||||
}
|
||||
|
||||
std::vector<OCRPredictResult>
|
||||
OCR_PPredictor::infer_ocr(const std::vector<int64_t> &dims,
|
||||
const float *input_data, int input_len, int net_flag,
|
||||
cv::Mat &origin) {
|
||||
PredictorInput input = _det_predictor->get_first_input();
|
||||
input.set_dims(dims);
|
||||
input.set_data(input_data, input_len);
|
||||
std::vector<PredictorOutput> results = _det_predictor->infer();
|
||||
PredictorOutput &res = results.at(0);
|
||||
std::vector<std::vector<std::vector<int>>> filtered_box = calc_filtered_boxes(
|
||||
res.get_float_data(), res.get_size(), (int)dims[2], (int)dims[3], origin);
|
||||
LOGI("Filter_box size %ld", filtered_box.size());
|
||||
return infer_rec(filtered_box, origin);
|
||||
}
|
||||
|
||||
std::vector<OCRPredictResult> OCR_PPredictor::infer_rec(
|
||||
const std::vector<std::vector<std::vector<int>>> &boxes,
|
||||
const cv::Mat &origin_img) {
|
||||
std::vector<float> mean = {0.5f, 0.5f, 0.5f};
|
||||
std::vector<float> scale = {1 / 0.5f, 1 / 0.5f, 1 / 0.5f};
|
||||
std::vector<int64_t> dims = {1, 3, 0, 0};
|
||||
OCR_PPredictor::infer_ocr(cv::Mat &origin,int max_size_len, int run_det, int run_cls, int run_rec) {
|
||||
LOGI("ocr cpp start *****************");
|
||||
LOGI("ocr cpp det: %d, cls: %d, rec: %d", run_det, run_cls, run_rec);
|
||||
std::vector<OCRPredictResult> ocr_results;
|
||||
|
||||
PredictorInput input = _rec_predictor->get_first_input();
|
||||
for (auto bp = boxes.crbegin(); bp != boxes.crend(); ++bp) {
|
||||
const std::vector<std::vector<int>> &box = *bp;
|
||||
cv::Mat crop_img = get_rotate_crop_image(origin_img, box);
|
||||
crop_img = infer_cls(crop_img);
|
||||
|
||||
float wh_ratio = float(crop_img.cols) / float(crop_img.rows);
|
||||
cv::Mat input_image = crnn_resize_img(crop_img, wh_ratio);
|
||||
input_image.convertTo(input_image, CV_32FC3, 1 / 255.0f);
|
||||
const float *dimg = reinterpret_cast<const float *>(input_image.data);
|
||||
int input_size = input_image.rows * input_image.cols;
|
||||
|
||||
dims[2] = input_image.rows;
|
||||
dims[3] = input_image.cols;
|
||||
input.set_dims(dims);
|
||||
|
||||
neon_mean_scale(dimg, input.get_mutable_float_data(), input_size, mean,
|
||||
scale);
|
||||
|
||||
std::vector<PredictorOutput> results = _rec_predictor->infer();
|
||||
const float *predict_batch = results.at(0).get_float_data();
|
||||
const std::vector<int64_t> predict_shape = results.at(0).get_shape();
|
||||
|
||||
OCRPredictResult res;
|
||||
|
||||
// ctc decode
|
||||
int argmax_idx;
|
||||
int last_index = 0;
|
||||
float score = 0.f;
|
||||
int count = 0;
|
||||
float max_value = 0.0f;
|
||||
|
||||
for (int n = 0; n < predict_shape[1]; n++) {
|
||||
argmax_idx = int(argmax(&predict_batch[n * predict_shape[2]],
|
||||
&predict_batch[(n + 1) * predict_shape[2]]));
|
||||
max_value =
|
||||
float(*std::max_element(&predict_batch[n * predict_shape[2]],
|
||||
&predict_batch[(n + 1) * predict_shape[2]]));
|
||||
if (argmax_idx > 0 && (!(n > 0 && argmax_idx == last_index))) {
|
||||
score += max_value;
|
||||
count += 1;
|
||||
res.word_index.push_back(argmax_idx);
|
||||
}
|
||||
last_index = argmax_idx;
|
||||
}
|
||||
score /= count;
|
||||
if (res.word_index.empty()) {
|
||||
continue;
|
||||
}
|
||||
res.score = score;
|
||||
res.points = box;
|
||||
ocr_results.emplace_back(std::move(res));
|
||||
if(run_det){
|
||||
infer_det(origin, max_size_len, ocr_results);
|
||||
}
|
||||
LOGI("ocr_results finished %lu", ocr_results.size());
|
||||
if(run_rec){
|
||||
if(ocr_results.size()==0){
|
||||
OCRPredictResult res;
|
||||
ocr_results.emplace_back(std::move(res));
|
||||
}
|
||||
for(int i = 0; i < ocr_results.size();i++) {
|
||||
infer_rec(origin, run_cls, ocr_results[i]);
|
||||
}
|
||||
}else if(run_cls){
|
||||
ClsPredictResult cls_res = infer_cls(origin);
|
||||
OCRPredictResult res;
|
||||
res.cls_score = cls_res.cls_score;
|
||||
res.cls_label = cls_res.cls_label;
|
||||
ocr_results.push_back(res);
|
||||
}
|
||||
|
||||
LOGI("ocr cpp end *****************");
|
||||
return ocr_results;
|
||||
}
|
||||
|
||||
cv::Mat OCR_PPredictor::infer_cls(const cv::Mat &img, float thresh) {
|
||||
cv::Mat DetResizeImg(const cv::Mat img, int max_size_len,
|
||||
std::vector<float> &ratio_hw) {
|
||||
int w = img.cols;
|
||||
int h = img.rows;
|
||||
|
||||
float ratio = 1.f;
|
||||
int max_wh = w >= h ? w : h;
|
||||
if (max_wh > max_size_len) {
|
||||
if (h > w) {
|
||||
ratio = static_cast<float>(max_size_len) / static_cast<float>(h);
|
||||
} else {
|
||||
ratio = static_cast<float>(max_size_len) / static_cast<float>(w);
|
||||
}
|
||||
}
|
||||
|
||||
int resize_h = static_cast<int>(float(h) * ratio);
|
||||
int resize_w = static_cast<int>(float(w) * ratio);
|
||||
if (resize_h % 32 == 0)
|
||||
resize_h = resize_h;
|
||||
else if (resize_h / 32 < 1 + 1e-5)
|
||||
resize_h = 32;
|
||||
else
|
||||
resize_h = (resize_h / 32 - 1) * 32;
|
||||
|
||||
if (resize_w % 32 == 0)
|
||||
resize_w = resize_w;
|
||||
else if (resize_w / 32 < 1 + 1e-5)
|
||||
resize_w = 32;
|
||||
else
|
||||
resize_w = (resize_w / 32 - 1) * 32;
|
||||
|
||||
cv::Mat resize_img;
|
||||
cv::resize(img, resize_img, cv::Size(resize_w, resize_h));
|
||||
|
||||
ratio_hw.push_back(static_cast<float>(resize_h) / static_cast<float>(h));
|
||||
ratio_hw.push_back(static_cast<float>(resize_w) / static_cast<float>(w));
|
||||
return resize_img;
|
||||
}
|
||||
|
||||
void OCR_PPredictor::infer_det(cv::Mat &origin, int max_size_len, std::vector<OCRPredictResult> &ocr_results) {
|
||||
std::vector<float> mean = {0.485f, 0.456f, 0.406f};
|
||||
std::vector<float> scale = {1 / 0.229f, 1 / 0.224f, 1 / 0.225f};
|
||||
|
||||
PredictorInput input = _det_predictor->get_first_input();
|
||||
|
||||
std::vector<float> ratio_hw;
|
||||
cv::Mat input_image = DetResizeImg(origin, max_size_len, ratio_hw);
|
||||
input_image.convertTo(input_image, CV_32FC3, 1 / 255.0f);
|
||||
const float *dimg = reinterpret_cast<const float *>(input_image.data);
|
||||
int input_size = input_image.rows * input_image.cols;
|
||||
|
||||
input.set_dims({1, 3, input_image.rows, input_image.cols});
|
||||
|
||||
neon_mean_scale(dimg, input.get_mutable_float_data(), input_size, mean,
|
||||
scale);
|
||||
LOGI("ocr cpp det shape %d,%d", input_image.rows,input_image.cols);
|
||||
std::vector<PredictorOutput> results = _det_predictor->infer();
|
||||
PredictorOutput &res = results.at(0);
|
||||
std::vector<std::vector<std::vector<int>>> filtered_box = calc_filtered_boxes(
|
||||
res.get_float_data(), res.get_size(), input_image.rows, input_image.cols, origin);
|
||||
LOGI("ocr cpp det Filter_box size %ld", filtered_box.size());
|
||||
|
||||
for(int i = 0;i<filtered_box.size();i++){
|
||||
LOGI("ocr cpp box %d,%d,%d,%d,%d,%d,%d,%d", filtered_box[i][0][0],filtered_box[i][0][1], filtered_box[i][1][0],filtered_box[i][1][1], filtered_box[i][2][0],filtered_box[i][2][1], filtered_box[i][3][0],filtered_box[i][3][1]);
|
||||
OCRPredictResult res;
|
||||
res.points = filtered_box[i];
|
||||
ocr_results.push_back(res);
|
||||
}
|
||||
}
|
||||
|
||||
void OCR_PPredictor::infer_rec(const cv::Mat &origin_img, int run_cls, OCRPredictResult& ocr_result) {
|
||||
std::vector<float> mean = {0.5f, 0.5f, 0.5f};
|
||||
std::vector<float> scale = {1 / 0.5f, 1 / 0.5f, 1 / 0.5f};
|
||||
std::vector<int64_t> dims = {1, 3, 0, 0};
|
||||
|
||||
PredictorInput input = _rec_predictor->get_first_input();
|
||||
|
||||
const std::vector<std::vector<int>> &box = ocr_result.points;
|
||||
cv::Mat crop_img;
|
||||
if(box.size()>0){
|
||||
crop_img = get_rotate_crop_image(origin_img, box);
|
||||
}
|
||||
else{
|
||||
crop_img = origin_img;
|
||||
}
|
||||
|
||||
if(run_cls){
|
||||
ClsPredictResult cls_res = infer_cls(crop_img);
|
||||
crop_img = cls_res.img;
|
||||
ocr_result.cls_score = cls_res.cls_score;
|
||||
ocr_result.cls_label = cls_res.cls_label;
|
||||
}
|
||||
|
||||
|
||||
float wh_ratio = float(crop_img.cols) / float(crop_img.rows);
|
||||
cv::Mat input_image = crnn_resize_img(crop_img, wh_ratio);
|
||||
input_image.convertTo(input_image, CV_32FC3, 1 / 255.0f);
|
||||
const float *dimg = reinterpret_cast<const float *>(input_image.data);
|
||||
int input_size = input_image.rows * input_image.cols;
|
||||
|
||||
dims[2] = input_image.rows;
|
||||
dims[3] = input_image.cols;
|
||||
input.set_dims(dims);
|
||||
|
||||
neon_mean_scale(dimg, input.get_mutable_float_data(), input_size, mean,
|
||||
scale);
|
||||
|
||||
std::vector<PredictorOutput> results = _rec_predictor->infer();
|
||||
const float *predict_batch = results.at(0).get_float_data();
|
||||
const std::vector<int64_t> predict_shape = results.at(0).get_shape();
|
||||
|
||||
// ctc decode
|
||||
int argmax_idx;
|
||||
int last_index = 0;
|
||||
float score = 0.f;
|
||||
int count = 0;
|
||||
float max_value = 0.0f;
|
||||
|
||||
for (int n = 0; n < predict_shape[1]; n++) {
|
||||
argmax_idx = int(argmax(&predict_batch[n * predict_shape[2]],
|
||||
&predict_batch[(n + 1) * predict_shape[2]]));
|
||||
max_value =
|
||||
float(*std::max_element(&predict_batch[n * predict_shape[2]],
|
||||
&predict_batch[(n + 1) * predict_shape[2]]));
|
||||
if (argmax_idx > 0 && (!(n > 0 && argmax_idx == last_index))) {
|
||||
score += max_value;
|
||||
count += 1;
|
||||
ocr_result.word_index.push_back(argmax_idx);
|
||||
}
|
||||
last_index = argmax_idx;
|
||||
}
|
||||
score /= count;
|
||||
ocr_result.score = score;
|
||||
LOGI("ocr cpp rec word size %ld", count);
|
||||
}
|
||||
|
||||
ClsPredictResult OCR_PPredictor::infer_cls(const cv::Mat &img, float thresh) {
|
||||
std::vector<float> mean = {0.5f, 0.5f, 0.5f};
|
||||
std::vector<float> scale = {1 / 0.5f, 1 / 0.5f, 1 / 0.5f};
|
||||
std::vector<int64_t> dims = {1, 3, 0, 0};
|
||||
std::vector<OCRPredictResult> ocr_results;
|
||||
|
||||
PredictorInput input = _cls_predictor->get_first_input();
|
||||
|
||||
@@ -182,7 +266,7 @@ cv::Mat OCR_PPredictor::infer_cls(const cv::Mat &img, float thresh) {
|
||||
float score = 0;
|
||||
int label = 0;
|
||||
for (int64_t i = 0; i < results.at(0).get_size(); i++) {
|
||||
LOGI("output scores [%f]", scores[i]);
|
||||
LOGI("ocr cpp cls output scores [%f]", scores[i]);
|
||||
if (scores[i] > score) {
|
||||
score = scores[i];
|
||||
label = i;
|
||||
@@ -193,7 +277,12 @@ cv::Mat OCR_PPredictor::infer_cls(const cv::Mat &img, float thresh) {
|
||||
if (label % 2 == 1 && score > thresh) {
|
||||
cv::rotate(srcimg, srcimg, 1);
|
||||
}
|
||||
return srcimg;
|
||||
ClsPredictResult res;
|
||||
res.cls_label = label;
|
||||
res.cls_score = score;
|
||||
res.img = srcimg;
|
||||
LOGI("ocr cpp cls word cls %ld, %f", label, score);
|
||||
return res;
|
||||
}
|
||||
|
||||
std::vector<std::vector<std::vector<int>>>
|
||||
|
||||
@@ -15,7 +15,8 @@ namespace ppredictor {
|
||||
* Config
|
||||
*/
|
||||
struct OCR_Config {
|
||||
int thread_num = 4; // Thread num
|
||||
int use_opencl = 0;
|
||||
int thread_num = 4; // Thread num
|
||||
paddle::lite_api::PowerMode mode =
|
||||
paddle::lite_api::LITE_POWER_HIGH; // PaddleLite Mode
|
||||
};
|
||||
@@ -27,8 +28,15 @@ struct OCRPredictResult {
|
||||
std::vector<int> word_index;
|
||||
std::vector<std::vector<int>> points;
|
||||
float score;
|
||||
float cls_score;
|
||||
int cls_label=-1;
|
||||
};
|
||||
|
||||
struct ClsPredictResult {
|
||||
float cls_score;
|
||||
int cls_label=-1;
|
||||
cv::Mat img;
|
||||
};
|
||||
/**
|
||||
* OCR there are 2 models
|
||||
* 1. First model(det),select polygones to show where are the texts
|
||||
@@ -62,8 +70,7 @@ public:
|
||||
* @return
|
||||
*/
|
||||
virtual std::vector<OCRPredictResult>
|
||||
infer_ocr(const std::vector<int64_t> &dims, const float *input_data,
|
||||
int input_len, int net_flag, cv::Mat &origin);
|
||||
infer_ocr(cv::Mat &origin, int max_size_len, int run_det, int run_cls, int run_rec);
|
||||
|
||||
virtual NET_TYPE get_net_flag() const;
|
||||
|
||||
@@ -80,25 +87,26 @@ private:
|
||||
calc_filtered_boxes(const float *pred, int pred_size, int output_height,
|
||||
int output_width, const cv::Mat &origin);
|
||||
|
||||
void
|
||||
infer_det(cv::Mat &origin, int max_side_len, std::vector<OCRPredictResult>& ocr_results);
|
||||
/**
|
||||
* infer for second model
|
||||
* infer for rec model
|
||||
*
|
||||
* @param boxes
|
||||
* @param origin
|
||||
* @return
|
||||
*/
|
||||
std::vector<OCRPredictResult>
|
||||
infer_rec(const std::vector<std::vector<std::vector<int>>> &boxes,
|
||||
const cv::Mat &origin);
|
||||
void
|
||||
infer_rec(const cv::Mat &origin, int run_cls, OCRPredictResult& ocr_result);
|
||||
|
||||
/**
|
||||
/**
|
||||
* infer for cls model
|
||||
*
|
||||
* @param boxes
|
||||
* @param origin
|
||||
* @return
|
||||
*/
|
||||
cv::Mat infer_cls(const cv::Mat &origin, float thresh = 0.9);
|
||||
ClsPredictResult infer_cls(const cv::Mat &origin, float thresh = 0.9);
|
||||
|
||||
/**
|
||||
* Postprocess or sencod model to extract text
|
||||
|
||||
@@ -2,9 +2,9 @@
|
||||
#include "common.h"
|
||||
|
||||
namespace ppredictor {
|
||||
PPredictor::PPredictor(int thread_num, int net_flag,
|
||||
PPredictor::PPredictor(int use_opencl, int thread_num, int net_flag,
|
||||
paddle::lite_api::PowerMode mode)
|
||||
: _thread_num(thread_num), _net_flag(net_flag), _mode(mode) {}
|
||||
: _use_opencl(use_opencl), _thread_num(thread_num), _net_flag(net_flag), _mode(mode) {}
|
||||
|
||||
int PPredictor::init_nb(const std::string &model_content) {
|
||||
paddle::lite_api::MobileConfig config;
|
||||
@@ -19,10 +19,40 @@ int PPredictor::init_from_file(const std::string &model_content) {
|
||||
}
|
||||
|
||||
template <typename ConfigT> int PPredictor::_init(ConfigT &config) {
|
||||
bool is_opencl_backend_valid = paddle::lite_api::IsOpenCLBackendValid(/*check_fp16_valid = false*/);
|
||||
if (is_opencl_backend_valid) {
|
||||
if (_use_opencl != 0) {
|
||||
// Make sure you have write permission of the binary path.
|
||||
// We strongly recommend each model has a unique binary name.
|
||||
const std::string bin_path = "/data/local/tmp/";
|
||||
const std::string bin_name = "lite_opencl_kernel.bin";
|
||||
config.set_opencl_binary_path_name(bin_path, bin_name);
|
||||
|
||||
// opencl tune option
|
||||
// CL_TUNE_NONE: 0
|
||||
// CL_TUNE_RAPID: 1
|
||||
// CL_TUNE_NORMAL: 2
|
||||
// CL_TUNE_EXHAUSTIVE: 3
|
||||
const std::string tuned_path = "/data/local/tmp/";
|
||||
const std::string tuned_name = "lite_opencl_tuned.bin";
|
||||
config.set_opencl_tune(paddle::lite_api::CL_TUNE_NORMAL, tuned_path, tuned_name);
|
||||
|
||||
// opencl precision option
|
||||
// CL_PRECISION_AUTO: 0, first fp16 if valid, default
|
||||
// CL_PRECISION_FP32: 1, force fp32
|
||||
// CL_PRECISION_FP16: 2, force fp16
|
||||
config.set_opencl_precision(paddle::lite_api::CL_PRECISION_FP32);
|
||||
LOGI("ocr cpp device: running on gpu.");
|
||||
}
|
||||
} else {
|
||||
LOGI("ocr cpp device: running on cpu.");
|
||||
// you can give backup cpu nb model instead
|
||||
// config.set_model_from_file(cpu_nb_model_dir);
|
||||
}
|
||||
config.set_threads(_thread_num);
|
||||
config.set_power_mode(_mode);
|
||||
_predictor = paddle::lite_api::CreatePaddlePredictor(config);
|
||||
LOGI("paddle instance created");
|
||||
LOGI("ocr cpp paddle instance created");
|
||||
return RETURN_OK;
|
||||
}
|
||||
|
||||
@@ -43,18 +73,18 @@ std::vector<PredictorInput> PPredictor::get_inputs(int num) {
|
||||
PredictorInput PPredictor::get_first_input() { return get_input(0); }
|
||||
|
||||
std::vector<PredictorOutput> PPredictor::infer() {
|
||||
LOGI("infer Run start %d", _net_flag);
|
||||
LOGI("ocr cpp infer Run start %d", _net_flag);
|
||||
std::vector<PredictorOutput> results;
|
||||
if (!_is_input_get) {
|
||||
return results;
|
||||
}
|
||||
_predictor->Run();
|
||||
LOGI("infer Run end");
|
||||
LOGI("ocr cpp infer Run end");
|
||||
|
||||
for (int i = 0; i < _predictor->GetOutputNames().size(); i++) {
|
||||
std::unique_ptr<const paddle::lite_api::Tensor> output_tensor =
|
||||
_predictor->GetOutput(i);
|
||||
LOGI("output tensor[%d] size %ld", i, product(output_tensor->shape()));
|
||||
LOGI("ocr cpp output tensor[%d] size %ld", i, product(output_tensor->shape()));
|
||||
PredictorOutput result{std::move(output_tensor), i, _net_flag};
|
||||
results.emplace_back(std::move(result));
|
||||
}
|
||||
|
||||
@@ -22,7 +22,7 @@ public:
|
||||
class PPredictor : public PPredictor_Interface {
|
||||
public:
|
||||
PPredictor(
|
||||
int thread_num, int net_flag = 0,
|
||||
int use_opencl, int thread_num, int net_flag = 0,
|
||||
paddle::lite_api::PowerMode mode = paddle::lite_api::LITE_POWER_HIGH);
|
||||
|
||||
virtual ~PPredictor() {}
|
||||
@@ -54,6 +54,7 @@ protected:
|
||||
template <typename ConfigT> int _init(ConfigT &config);
|
||||
|
||||
private:
|
||||
int _use_opencl;
|
||||
int _thread_num;
|
||||
paddle::lite_api::PowerMode _mode;
|
||||
std::shared_ptr<paddle::lite_api::PaddlePredictor> _predictor;
|
||||
|
||||
@@ -13,6 +13,7 @@ import android.graphics.BitmapFactory;
|
||||
import android.graphics.drawable.BitmapDrawable;
|
||||
import android.media.ExifInterface;
|
||||
import android.content.res.AssetManager;
|
||||
import android.media.FaceDetector;
|
||||
import android.net.Uri;
|
||||
import android.os.Bundle;
|
||||
import android.os.Environment;
|
||||
@@ -27,7 +28,9 @@ import android.view.Menu;
|
||||
import android.view.MenuInflater;
|
||||
import android.view.MenuItem;
|
||||
import android.view.View;
|
||||
import android.widget.CheckBox;
|
||||
import android.widget.ImageView;
|
||||
import android.widget.Spinner;
|
||||
import android.widget.TextView;
|
||||
import android.widget.Toast;
|
||||
|
||||
@@ -68,23 +71,24 @@ public class MainActivity extends AppCompatActivity {
|
||||
protected ImageView ivInputImage;
|
||||
protected TextView tvOutputResult;
|
||||
protected TextView tvInferenceTime;
|
||||
protected CheckBox cbOpencl;
|
||||
protected Spinner spRunMode;
|
||||
|
||||
// Model settings of object detection
|
||||
// Model settings of ocr
|
||||
protected String modelPath = "";
|
||||
protected String labelPath = "";
|
||||
protected String imagePath = "";
|
||||
protected int cpuThreadNum = 1;
|
||||
protected String cpuPowerMode = "";
|
||||
protected String inputColorFormat = "";
|
||||
protected long[] inputShape = new long[]{};
|
||||
protected float[] inputMean = new float[]{};
|
||||
protected float[] inputStd = new float[]{};
|
||||
protected int detLongSize = 960;
|
||||
protected float scoreThreshold = 0.1f;
|
||||
private String currentPhotoPath;
|
||||
private AssetManager assetManager =null;
|
||||
private AssetManager assetManager = null;
|
||||
|
||||
protected Predictor predictor = new Predictor();
|
||||
|
||||
private Bitmap cur_predict_image = null;
|
||||
|
||||
@Override
|
||||
protected void onCreate(Bundle savedInstanceState) {
|
||||
super.onCreate(savedInstanceState);
|
||||
@@ -98,10 +102,12 @@ public class MainActivity extends AppCompatActivity {
|
||||
|
||||
// Setup the UI components
|
||||
tvInputSetting = findViewById(R.id.tv_input_setting);
|
||||
cbOpencl = findViewById(R.id.cb_opencl);
|
||||
tvStatus = findViewById(R.id.tv_model_img_status);
|
||||
ivInputImage = findViewById(R.id.iv_input_image);
|
||||
tvInferenceTime = findViewById(R.id.tv_inference_time);
|
||||
tvOutputResult = findViewById(R.id.tv_output_result);
|
||||
spRunMode = findViewById(R.id.sp_run_mode);
|
||||
tvInputSetting.setMovementMethod(ScrollingMovementMethod.getInstance());
|
||||
tvOutputResult.setMovementMethod(ScrollingMovementMethod.getInstance());
|
||||
|
||||
@@ -111,26 +117,26 @@ public class MainActivity extends AppCompatActivity {
|
||||
public void handleMessage(Message msg) {
|
||||
switch (msg.what) {
|
||||
case RESPONSE_LOAD_MODEL_SUCCESSED:
|
||||
if(pbLoadModel!=null && pbLoadModel.isShowing()){
|
||||
if (pbLoadModel != null && pbLoadModel.isShowing()) {
|
||||
pbLoadModel.dismiss();
|
||||
}
|
||||
onLoadModelSuccessed();
|
||||
break;
|
||||
case RESPONSE_LOAD_MODEL_FAILED:
|
||||
if(pbLoadModel!=null && pbLoadModel.isShowing()){
|
||||
if (pbLoadModel != null && pbLoadModel.isShowing()) {
|
||||
pbLoadModel.dismiss();
|
||||
}
|
||||
Toast.makeText(MainActivity.this, "Load model failed!", Toast.LENGTH_SHORT).show();
|
||||
onLoadModelFailed();
|
||||
break;
|
||||
case RESPONSE_RUN_MODEL_SUCCESSED:
|
||||
if(pbRunModel!=null && pbRunModel.isShowing()){
|
||||
if (pbRunModel != null && pbRunModel.isShowing()) {
|
||||
pbRunModel.dismiss();
|
||||
}
|
||||
onRunModelSuccessed();
|
||||
break;
|
||||
case RESPONSE_RUN_MODEL_FAILED:
|
||||
if(pbRunModel!=null && pbRunModel.isShowing()){
|
||||
if (pbRunModel != null && pbRunModel.isShowing()) {
|
||||
pbRunModel.dismiss();
|
||||
}
|
||||
Toast.makeText(MainActivity.this, "Run model failed!", Toast.LENGTH_SHORT).show();
|
||||
@@ -175,71 +181,47 @@ public class MainActivity extends AppCompatActivity {
|
||||
super.onResume();
|
||||
SharedPreferences sharedPreferences = PreferenceManager.getDefaultSharedPreferences(this);
|
||||
boolean settingsChanged = false;
|
||||
boolean model_settingsChanged = false;
|
||||
String model_path = sharedPreferences.getString(getString(R.string.MODEL_PATH_KEY),
|
||||
getString(R.string.MODEL_PATH_DEFAULT));
|
||||
String label_path = sharedPreferences.getString(getString(R.string.LABEL_PATH_KEY),
|
||||
getString(R.string.LABEL_PATH_DEFAULT));
|
||||
String image_path = sharedPreferences.getString(getString(R.string.IMAGE_PATH_KEY),
|
||||
getString(R.string.IMAGE_PATH_DEFAULT));
|
||||
settingsChanged |= !model_path.equalsIgnoreCase(modelPath);
|
||||
model_settingsChanged |= !model_path.equalsIgnoreCase(modelPath);
|
||||
settingsChanged |= !label_path.equalsIgnoreCase(labelPath);
|
||||
settingsChanged |= !image_path.equalsIgnoreCase(imagePath);
|
||||
int cpu_thread_num = Integer.parseInt(sharedPreferences.getString(getString(R.string.CPU_THREAD_NUM_KEY),
|
||||
getString(R.string.CPU_THREAD_NUM_DEFAULT)));
|
||||
settingsChanged |= cpu_thread_num != cpuThreadNum;
|
||||
model_settingsChanged |= cpu_thread_num != cpuThreadNum;
|
||||
String cpu_power_mode =
|
||||
sharedPreferences.getString(getString(R.string.CPU_POWER_MODE_KEY),
|
||||
getString(R.string.CPU_POWER_MODE_DEFAULT));
|
||||
settingsChanged |= !cpu_power_mode.equalsIgnoreCase(cpuPowerMode);
|
||||
String input_color_format =
|
||||
sharedPreferences.getString(getString(R.string.INPUT_COLOR_FORMAT_KEY),
|
||||
getString(R.string.INPUT_COLOR_FORMAT_DEFAULT));
|
||||
settingsChanged |= !input_color_format.equalsIgnoreCase(inputColorFormat);
|
||||
long[] input_shape =
|
||||
Utils.parseLongsFromString(sharedPreferences.getString(getString(R.string.INPUT_SHAPE_KEY),
|
||||
getString(R.string.INPUT_SHAPE_DEFAULT)), ",");
|
||||
float[] input_mean =
|
||||
Utils.parseFloatsFromString(sharedPreferences.getString(getString(R.string.INPUT_MEAN_KEY),
|
||||
getString(R.string.INPUT_MEAN_DEFAULT)), ",");
|
||||
float[] input_std =
|
||||
Utils.parseFloatsFromString(sharedPreferences.getString(getString(R.string.INPUT_STD_KEY)
|
||||
, getString(R.string.INPUT_STD_DEFAULT)), ",");
|
||||
settingsChanged |= input_shape.length != inputShape.length;
|
||||
settingsChanged |= input_mean.length != inputMean.length;
|
||||
settingsChanged |= input_std.length != inputStd.length;
|
||||
if (!settingsChanged) {
|
||||
for (int i = 0; i < input_shape.length; i++) {
|
||||
settingsChanged |= input_shape[i] != inputShape[i];
|
||||
}
|
||||
for (int i = 0; i < input_mean.length; i++) {
|
||||
settingsChanged |= input_mean[i] != inputMean[i];
|
||||
}
|
||||
for (int i = 0; i < input_std.length; i++) {
|
||||
settingsChanged |= input_std[i] != inputStd[i];
|
||||
}
|
||||
}
|
||||
model_settingsChanged |= !cpu_power_mode.equalsIgnoreCase(cpuPowerMode);
|
||||
|
||||
int det_long_size = Integer.parseInt(sharedPreferences.getString(getString(R.string.DET_LONG_SIZE_KEY),
|
||||
getString(R.string.DET_LONG_SIZE_DEFAULT)));
|
||||
settingsChanged |= det_long_size != detLongSize;
|
||||
float score_threshold =
|
||||
Float.parseFloat(sharedPreferences.getString(getString(R.string.SCORE_THRESHOLD_KEY),
|
||||
getString(R.string.SCORE_THRESHOLD_DEFAULT)));
|
||||
settingsChanged |= scoreThreshold != score_threshold;
|
||||
if (settingsChanged) {
|
||||
modelPath = model_path;
|
||||
labelPath = label_path;
|
||||
imagePath = image_path;
|
||||
detLongSize = det_long_size;
|
||||
scoreThreshold = score_threshold;
|
||||
set_img();
|
||||
}
|
||||
if (model_settingsChanged) {
|
||||
modelPath = model_path;
|
||||
cpuThreadNum = cpu_thread_num;
|
||||
cpuPowerMode = cpu_power_mode;
|
||||
inputColorFormat = input_color_format;
|
||||
inputShape = input_shape;
|
||||
inputMean = input_mean;
|
||||
inputStd = input_std;
|
||||
scoreThreshold = score_threshold;
|
||||
// Update UI
|
||||
tvInputSetting.setText("Model: " + modelPath.substring(modelPath.lastIndexOf("/") + 1) + "\n" + "CPU" +
|
||||
" Thread Num: " + Integer.toString(cpuThreadNum) + "\n" + "CPU Power Mode: " + cpuPowerMode);
|
||||
tvInputSetting.setText("Model: " + modelPath.substring(modelPath.lastIndexOf("/") + 1) + "\nOPENCL: " + cbOpencl.isChecked() + "\nCPU Thread Num: " + cpuThreadNum + "\nCPU Power Mode: " + cpuPowerMode);
|
||||
tvInputSetting.scrollTo(0, 0);
|
||||
// Reload model if configure has been changed
|
||||
// loadModel();
|
||||
set_img();
|
||||
loadModel();
|
||||
}
|
||||
}
|
||||
|
||||
@@ -254,20 +236,28 @@ public class MainActivity extends AppCompatActivity {
|
||||
}
|
||||
|
||||
public boolean onLoadModel() {
|
||||
return predictor.init(MainActivity.this, modelPath, labelPath, cpuThreadNum,
|
||||
if (predictor.isLoaded()) {
|
||||
predictor.releaseModel();
|
||||
}
|
||||
return predictor.init(MainActivity.this, modelPath, labelPath, cbOpencl.isChecked() ? 1 : 0, cpuThreadNum,
|
||||
cpuPowerMode,
|
||||
inputColorFormat,
|
||||
inputShape, inputMean,
|
||||
inputStd, scoreThreshold);
|
||||
detLongSize, scoreThreshold);
|
||||
}
|
||||
|
||||
public boolean onRunModel() {
|
||||
return predictor.isLoaded() && predictor.runModel();
|
||||
String run_mode = spRunMode.getSelectedItem().toString();
|
||||
int run_det = run_mode.contains("检测") ? 1 : 0;
|
||||
int run_cls = run_mode.contains("分类") ? 1 : 0;
|
||||
int run_rec = run_mode.contains("识别") ? 1 : 0;
|
||||
return predictor.isLoaded() && predictor.runModel(run_det, run_cls, run_rec);
|
||||
}
|
||||
|
||||
public void onLoadModelSuccessed() {
|
||||
// Load test image from path and run model
|
||||
tvInputSetting.setText("Model: " + modelPath.substring(modelPath.lastIndexOf("/") + 1) + "\nOPENCL: " + cbOpencl.isChecked() + "\nCPU Thread Num: " + cpuThreadNum + "\nCPU Power Mode: " + cpuPowerMode);
|
||||
tvInputSetting.scrollTo(0, 0);
|
||||
tvStatus.setText("STATUS: load model successed");
|
||||
|
||||
}
|
||||
|
||||
public void onLoadModelFailed() {
|
||||
@@ -290,20 +280,13 @@ public class MainActivity extends AppCompatActivity {
|
||||
tvStatus.setText("STATUS: run model failed");
|
||||
}
|
||||
|
||||
public void onImageChanged(Bitmap image) {
|
||||
// Rerun model if users pick test image from gallery or camera
|
||||
if (image != null && predictor.isLoaded()) {
|
||||
predictor.setInputImage(image);
|
||||
runModel();
|
||||
}
|
||||
}
|
||||
|
||||
public void set_img() {
|
||||
// Load test image from path and run model
|
||||
try {
|
||||
assetManager= getAssets();
|
||||
InputStream in=assetManager.open(imagePath);
|
||||
Bitmap bmp=BitmapFactory.decodeStream(in);
|
||||
assetManager = getAssets();
|
||||
InputStream in = assetManager.open(imagePath);
|
||||
Bitmap bmp = BitmapFactory.decodeStream(in);
|
||||
cur_predict_image = bmp;
|
||||
ivInputImage.setImageBitmap(bmp);
|
||||
} catch (IOException e) {
|
||||
Toast.makeText(MainActivity.this, "Load image failed!", Toast.LENGTH_SHORT).show();
|
||||
@@ -430,7 +413,7 @@ public class MainActivity extends AppCompatActivity {
|
||||
Cursor cursor = managedQuery(uri, proj, null, null, null);
|
||||
cursor.moveToFirst();
|
||||
if (image != null) {
|
||||
// onImageChanged(image);
|
||||
cur_predict_image = image;
|
||||
ivInputImage.setImageBitmap(image);
|
||||
}
|
||||
} catch (IOException e) {
|
||||
@@ -451,7 +434,7 @@ public class MainActivity extends AppCompatActivity {
|
||||
Bitmap image = BitmapFactory.decodeFile(currentPhotoPath);
|
||||
image = Utils.rotateBitmap(image, orientation);
|
||||
if (image != null) {
|
||||
// onImageChanged(image);
|
||||
cur_predict_image = image;
|
||||
ivInputImage.setImageBitmap(image);
|
||||
}
|
||||
} else {
|
||||
@@ -464,28 +447,28 @@ public class MainActivity extends AppCompatActivity {
|
||||
}
|
||||
}
|
||||
|
||||
public void btn_load_model_click(View view) {
|
||||
if (predictor.isLoaded()){
|
||||
tvStatus.setText("STATUS: model has been loaded");
|
||||
}else{
|
||||
tvStatus.setText("STATUS: load model ......");
|
||||
loadModel();
|
||||
}
|
||||
public void btn_reset_img_click(View view) {
|
||||
ivInputImage.setImageBitmap(cur_predict_image);
|
||||
}
|
||||
|
||||
public void cb_opencl_click(View view) {
|
||||
tvStatus.setText("STATUS: load model ......");
|
||||
loadModel();
|
||||
}
|
||||
|
||||
public void btn_run_model_click(View view) {
|
||||
Bitmap image =((BitmapDrawable)ivInputImage.getDrawable()).getBitmap();
|
||||
if(image == null) {
|
||||
Bitmap image = ((BitmapDrawable) ivInputImage.getDrawable()).getBitmap();
|
||||
if (image == null) {
|
||||
tvStatus.setText("STATUS: image is not exists");
|
||||
}
|
||||
else if (!predictor.isLoaded()){
|
||||
} else if (!predictor.isLoaded()) {
|
||||
tvStatus.setText("STATUS: model is not loaded");
|
||||
}else{
|
||||
} else {
|
||||
tvStatus.setText("STATUS: run model ...... ");
|
||||
predictor.setInputImage(image);
|
||||
runModel();
|
||||
}
|
||||
}
|
||||
|
||||
public void btn_choice_img_click(View view) {
|
||||
if (requestAllPermissions()) {
|
||||
openGallery();
|
||||
@@ -506,4 +489,32 @@ public class MainActivity extends AppCompatActivity {
|
||||
worker.quit();
|
||||
super.onDestroy();
|
||||
}
|
||||
|
||||
public int get_run_mode() {
|
||||
String run_mode = spRunMode.getSelectedItem().toString();
|
||||
int mode;
|
||||
switch (run_mode) {
|
||||
case "检测+分类+识别":
|
||||
mode = 1;
|
||||
break;
|
||||
case "检测+识别":
|
||||
mode = 2;
|
||||
break;
|
||||
case "识别+分类":
|
||||
mode = 3;
|
||||
break;
|
||||
case "检测":
|
||||
mode = 4;
|
||||
break;
|
||||
case "识别":
|
||||
mode = 5;
|
||||
break;
|
||||
case "分类":
|
||||
mode = 6;
|
||||
break;
|
||||
default:
|
||||
mode = 1;
|
||||
}
|
||||
return mode;
|
||||
}
|
||||
}
|
||||
|
||||
@@ -1,157 +0,0 @@
|
||||
package com.baidu.paddle.lite.demo.ocr;
|
||||
|
||||
import android.graphics.Bitmap;
|
||||
import android.graphics.BitmapFactory;
|
||||
import android.os.Build;
|
||||
import android.os.Bundle;
|
||||
import android.os.Handler;
|
||||
import android.os.HandlerThread;
|
||||
import android.os.Message;
|
||||
import android.util.Log;
|
||||
import android.view.View;
|
||||
import android.widget.Button;
|
||||
import android.widget.ImageView;
|
||||
import android.widget.TextView;
|
||||
import android.widget.Toast;
|
||||
|
||||
import androidx.appcompat.app.AppCompatActivity;
|
||||
|
||||
import java.io.IOException;
|
||||
import java.io.InputStream;
|
||||
|
||||
public class MiniActivity extends AppCompatActivity {
|
||||
|
||||
|
||||
public static final int REQUEST_LOAD_MODEL = 0;
|
||||
public static final int REQUEST_RUN_MODEL = 1;
|
||||
public static final int REQUEST_UNLOAD_MODEL = 2;
|
||||
public static final int RESPONSE_LOAD_MODEL_SUCCESSED = 0;
|
||||
public static final int RESPONSE_LOAD_MODEL_FAILED = 1;
|
||||
public static final int RESPONSE_RUN_MODEL_SUCCESSED = 2;
|
||||
public static final int RESPONSE_RUN_MODEL_FAILED = 3;
|
||||
|
||||
private static final String TAG = "MiniActivity";
|
||||
|
||||
protected Handler receiver = null; // Receive messages from worker thread
|
||||
protected Handler sender = null; // Send command to worker thread
|
||||
protected HandlerThread worker = null; // Worker thread to load&run model
|
||||
protected volatile Predictor predictor = null;
|
||||
|
||||
private String assetModelDirPath = "models/ocr_v2_for_cpu";
|
||||
private String assetlabelFilePath = "labels/ppocr_keys_v1.txt";
|
||||
|
||||
private Button button;
|
||||
private ImageView imageView; // image result
|
||||
private TextView textView; // text result
|
||||
|
||||
@Override
|
||||
protected void onCreate(Bundle savedInstanceState) {
|
||||
super.onCreate(savedInstanceState);
|
||||
setContentView(R.layout.activity_mini);
|
||||
|
||||
Log.i(TAG, "SHOW in Logcat");
|
||||
|
||||
// Prepare the worker thread for mode loading and inference
|
||||
worker = new HandlerThread("Predictor Worker");
|
||||
worker.start();
|
||||
sender = new Handler(worker.getLooper()) {
|
||||
public void handleMessage(Message msg) {
|
||||
switch (msg.what) {
|
||||
case REQUEST_LOAD_MODEL:
|
||||
// Load model and reload test image
|
||||
if (!onLoadModel()) {
|
||||
runOnUiThread(new Runnable() {
|
||||
@Override
|
||||
public void run() {
|
||||
Toast.makeText(MiniActivity.this, "Load model failed!", Toast.LENGTH_SHORT).show();
|
||||
}
|
||||
});
|
||||
}
|
||||
break;
|
||||
case REQUEST_RUN_MODEL:
|
||||
// Run model if model is loaded
|
||||
final boolean isSuccessed = onRunModel();
|
||||
runOnUiThread(new Runnable() {
|
||||
@Override
|
||||
public void run() {
|
||||
if (isSuccessed){
|
||||
onRunModelSuccessed();
|
||||
}else{
|
||||
Toast.makeText(MiniActivity.this, "Run model failed!", Toast.LENGTH_SHORT).show();
|
||||
}
|
||||
}
|
||||
});
|
||||
break;
|
||||
}
|
||||
}
|
||||
};
|
||||
sender.sendEmptyMessage(REQUEST_LOAD_MODEL); // corresponding to REQUEST_LOAD_MODEL, to call onLoadModel()
|
||||
|
||||
imageView = findViewById(R.id.imageView);
|
||||
textView = findViewById(R.id.sample_text);
|
||||
button = findViewById(R.id.button);
|
||||
button.setOnClickListener(new View.OnClickListener() {
|
||||
@Override
|
||||
public void onClick(View v) {
|
||||
sender.sendEmptyMessage(REQUEST_RUN_MODEL);
|
||||
}
|
||||
});
|
||||
|
||||
|
||||
}
|
||||
|
||||
@Override
|
||||
protected void onDestroy() {
|
||||
onUnloadModel();
|
||||
if (Build.VERSION.SDK_INT >= Build.VERSION_CODES.JELLY_BEAN_MR2) {
|
||||
worker.quitSafely();
|
||||
} else {
|
||||
worker.quit();
|
||||
}
|
||||
super.onDestroy();
|
||||
}
|
||||
|
||||
/**
|
||||
* call in onCreate, model init
|
||||
*
|
||||
* @return
|
||||
*/
|
||||
private boolean onLoadModel() {
|
||||
if (predictor == null) {
|
||||
predictor = new Predictor();
|
||||
}
|
||||
return predictor.init(this, assetModelDirPath, assetlabelFilePath);
|
||||
}
|
||||
|
||||
/**
|
||||
* init engine
|
||||
* call in onCreate
|
||||
*
|
||||
* @return
|
||||
*/
|
||||
private boolean onRunModel() {
|
||||
try {
|
||||
String assetImagePath = "images/0.jpg";
|
||||
InputStream imageStream = getAssets().open(assetImagePath);
|
||||
Bitmap image = BitmapFactory.decodeStream(imageStream);
|
||||
// Input is Bitmap
|
||||
predictor.setInputImage(image);
|
||||
return predictor.isLoaded() && predictor.runModel();
|
||||
} catch (IOException e) {
|
||||
e.printStackTrace();
|
||||
return false;
|
||||
}
|
||||
}
|
||||
|
||||
private void onRunModelSuccessed() {
|
||||
Log.i(TAG, "onRunModelSuccessed");
|
||||
textView.setText(predictor.outputResult);
|
||||
imageView.setImageBitmap(predictor.outputImage);
|
||||
}
|
||||
|
||||
private void onUnloadModel() {
|
||||
if (predictor != null) {
|
||||
predictor.releaseModel();
|
||||
}
|
||||
}
|
||||
}
|
||||
@@ -29,22 +29,22 @@ public class OCRPredictorNative {
|
||||
public OCRPredictorNative(Config config) {
|
||||
this.config = config;
|
||||
loadLibrary();
|
||||
nativePointer = init(config.detModelFilename, config.recModelFilename,config.clsModelFilename,
|
||||
nativePointer = init(config.detModelFilename, config.recModelFilename, config.clsModelFilename, config.useOpencl,
|
||||
config.cpuThreadNum, config.cpuPower);
|
||||
Log.i("OCRPredictorNative", "load success " + nativePointer);
|
||||
|
||||
}
|
||||
|
||||
|
||||
public ArrayList<OcrResultModel> runImage(float[] inputData, int width, int height, int channels, Bitmap originalImage) {
|
||||
Log.i("OCRPredictorNative", "begin to run image " + inputData.length + " " + width + " " + height);
|
||||
float[] dims = new float[]{1, channels, height, width};
|
||||
float[] rawResults = forward(nativePointer, inputData, dims, originalImage);
|
||||
public ArrayList<OcrResultModel> runImage(Bitmap originalImage, int max_size_len, int run_det, int run_cls, int run_rec) {
|
||||
Log.i("OCRPredictorNative", "begin to run image ");
|
||||
float[] rawResults = forward(nativePointer, originalImage, max_size_len, run_det, run_cls, run_rec);
|
||||
ArrayList<OcrResultModel> results = postprocess(rawResults);
|
||||
return results;
|
||||
}
|
||||
|
||||
public static class Config {
|
||||
public int useOpencl;
|
||||
public int cpuThreadNum;
|
||||
public String cpuPower;
|
||||
public String detModelFilename;
|
||||
@@ -53,16 +53,16 @@ public class OCRPredictorNative {
|
||||
|
||||
}
|
||||
|
||||
public void destory(){
|
||||
public void destory() {
|
||||
if (nativePointer > 0) {
|
||||
release(nativePointer);
|
||||
nativePointer = 0;
|
||||
}
|
||||
}
|
||||
|
||||
protected native long init(String detModelPath, String recModelPath,String clsModelPath, int threadNum, String cpuMode);
|
||||
protected native long init(String detModelPath, String recModelPath, String clsModelPath, int useOpencl, int threadNum, String cpuMode);
|
||||
|
||||
protected native float[] forward(long pointer, float[] buf, float[] ddims, Bitmap originalImage);
|
||||
protected native float[] forward(long pointer, Bitmap originalImage,int max_size_len, int run_det, int run_cls, int run_rec);
|
||||
|
||||
protected native void release(long pointer);
|
||||
|
||||
@@ -73,9 +73,9 @@ public class OCRPredictorNative {
|
||||
while (begin < raw.length) {
|
||||
int point_num = Math.round(raw[begin]);
|
||||
int word_num = Math.round(raw[begin + 1]);
|
||||
OcrResultModel model = parse(raw, begin + 2, point_num, word_num);
|
||||
begin += 2 + 1 + point_num * 2 + word_num;
|
||||
results.add(model);
|
||||
OcrResultModel res = parse(raw, begin + 2, point_num, word_num);
|
||||
begin += 2 + 1 + point_num * 2 + word_num + 2;
|
||||
results.add(res);
|
||||
}
|
||||
|
||||
return results;
|
||||
@@ -83,19 +83,22 @@ public class OCRPredictorNative {
|
||||
|
||||
private OcrResultModel parse(float[] raw, int begin, int pointNum, int wordNum) {
|
||||
int current = begin;
|
||||
OcrResultModel model = new OcrResultModel();
|
||||
model.setConfidence(raw[current]);
|
||||
OcrResultModel res = new OcrResultModel();
|
||||
res.setConfidence(raw[current]);
|
||||
current++;
|
||||
for (int i = 0; i < pointNum; i++) {
|
||||
model.addPoints(Math.round(raw[current + i * 2]), Math.round(raw[current + i * 2 + 1]));
|
||||
res.addPoints(Math.round(raw[current + i * 2]), Math.round(raw[current + i * 2 + 1]));
|
||||
}
|
||||
current += (pointNum * 2);
|
||||
for (int i = 0; i < wordNum; i++) {
|
||||
int index = Math.round(raw[current + i]);
|
||||
model.addWordIndex(index);
|
||||
res.addWordIndex(index);
|
||||
}
|
||||
current += wordNum;
|
||||
res.setClsIdx(raw[current]);
|
||||
res.setClsConfidence(raw[current + 1]);
|
||||
Log.i("OCRPredictorNative", "word finished " + wordNum);
|
||||
return model;
|
||||
return res;
|
||||
}
|
||||
|
||||
|
||||
|
||||
@@ -10,6 +10,9 @@ public class OcrResultModel {
|
||||
private List<Integer> wordIndex;
|
||||
private String label;
|
||||
private float confidence;
|
||||
private float cls_idx;
|
||||
private String cls_label;
|
||||
private float cls_confidence;
|
||||
|
||||
public OcrResultModel() {
|
||||
super();
|
||||
@@ -49,4 +52,28 @@ public class OcrResultModel {
|
||||
public void setConfidence(float confidence) {
|
||||
this.confidence = confidence;
|
||||
}
|
||||
|
||||
public float getClsIdx() {
|
||||
return cls_idx;
|
||||
}
|
||||
|
||||
public void setClsIdx(float idx) {
|
||||
this.cls_idx = idx;
|
||||
}
|
||||
|
||||
public String getClsLabel() {
|
||||
return cls_label;
|
||||
}
|
||||
|
||||
public void setClsLabel(String label) {
|
||||
this.cls_label = label;
|
||||
}
|
||||
|
||||
public float getClsConfidence() {
|
||||
return cls_confidence;
|
||||
}
|
||||
|
||||
public void setClsConfidence(float confidence) {
|
||||
this.cls_confidence = confidence;
|
||||
}
|
||||
}
|
||||
|
||||
@@ -31,23 +31,19 @@ public class Predictor {
|
||||
protected float inferenceTime = 0;
|
||||
// Only for object detection
|
||||
protected Vector<String> wordLabels = new Vector<String>();
|
||||
protected String inputColorFormat = "BGR";
|
||||
protected long[] inputShape = new long[]{1, 3, 960};
|
||||
protected float[] inputMean = new float[]{0.485f, 0.456f, 0.406f};
|
||||
protected float[] inputStd = new float[]{1.0f / 0.229f, 1.0f / 0.224f, 1.0f / 0.225f};
|
||||
protected int detLongSize = 960;
|
||||
protected float scoreThreshold = 0.1f;
|
||||
protected Bitmap inputImage = null;
|
||||
protected Bitmap outputImage = null;
|
||||
protected volatile String outputResult = "";
|
||||
protected float preprocessTime = 0;
|
||||
protected float postprocessTime = 0;
|
||||
|
||||
|
||||
public Predictor() {
|
||||
}
|
||||
|
||||
public boolean init(Context appCtx, String modelPath, String labelPath) {
|
||||
isLoaded = loadModel(appCtx, modelPath, cpuThreadNum, cpuPowerMode);
|
||||
public boolean init(Context appCtx, String modelPath, String labelPath, int useOpencl, int cpuThreadNum, String cpuPowerMode) {
|
||||
isLoaded = loadModel(appCtx, modelPath, useOpencl, cpuThreadNum, cpuPowerMode);
|
||||
if (!isLoaded) {
|
||||
return false;
|
||||
}
|
||||
@@ -56,49 +52,18 @@ public class Predictor {
|
||||
}
|
||||
|
||||
|
||||
public boolean init(Context appCtx, String modelPath, String labelPath, int cpuThreadNum, String cpuPowerMode,
|
||||
String inputColorFormat,
|
||||
long[] inputShape, float[] inputMean,
|
||||
float[] inputStd, float scoreThreshold) {
|
||||
if (inputShape.length != 3) {
|
||||
Log.e(TAG, "Size of input shape should be: 3");
|
||||
return false;
|
||||
}
|
||||
if (inputMean.length != inputShape[1]) {
|
||||
Log.e(TAG, "Size of input mean should be: " + Long.toString(inputShape[1]));
|
||||
return false;
|
||||
}
|
||||
if (inputStd.length != inputShape[1]) {
|
||||
Log.e(TAG, "Size of input std should be: " + Long.toString(inputShape[1]));
|
||||
return false;
|
||||
}
|
||||
if (inputShape[0] != 1) {
|
||||
Log.e(TAG, "Only one batch is supported in the image classification demo, you can use any batch size in " +
|
||||
"your Apps!");
|
||||
return false;
|
||||
}
|
||||
if (inputShape[1] != 1 && inputShape[1] != 3) {
|
||||
Log.e(TAG, "Only one/three channels are supported in the image classification demo, you can use any " +
|
||||
"channel size in your Apps!");
|
||||
return false;
|
||||
}
|
||||
if (!inputColorFormat.equalsIgnoreCase("BGR")) {
|
||||
Log.e(TAG, "Only BGR color format is supported.");
|
||||
return false;
|
||||
}
|
||||
boolean isLoaded = init(appCtx, modelPath, labelPath);
|
||||
public boolean init(Context appCtx, String modelPath, String labelPath, int useOpencl, int cpuThreadNum, String cpuPowerMode,
|
||||
int detLongSize, float scoreThreshold) {
|
||||
boolean isLoaded = init(appCtx, modelPath, labelPath, useOpencl, cpuThreadNum, cpuPowerMode);
|
||||
if (!isLoaded) {
|
||||
return false;
|
||||
}
|
||||
this.inputColorFormat = inputColorFormat;
|
||||
this.inputShape = inputShape;
|
||||
this.inputMean = inputMean;
|
||||
this.inputStd = inputStd;
|
||||
this.detLongSize = detLongSize;
|
||||
this.scoreThreshold = scoreThreshold;
|
||||
return true;
|
||||
}
|
||||
|
||||
protected boolean loadModel(Context appCtx, String modelPath, int cpuThreadNum, String cpuPowerMode) {
|
||||
protected boolean loadModel(Context appCtx, String modelPath, int useOpencl, int cpuThreadNum, String cpuPowerMode) {
|
||||
// Release model if exists
|
||||
releaseModel();
|
||||
|
||||
@@ -118,12 +83,13 @@ public class Predictor {
|
||||
}
|
||||
|
||||
OCRPredictorNative.Config config = new OCRPredictorNative.Config();
|
||||
config.useOpencl = useOpencl;
|
||||
config.cpuThreadNum = cpuThreadNum;
|
||||
config.detModelFilename = realPath + File.separator + "ch_ppocr_mobile_v2.0_det_opt.nb";
|
||||
config.recModelFilename = realPath + File.separator + "ch_ppocr_mobile_v2.0_rec_opt.nb";
|
||||
config.clsModelFilename = realPath + File.separator + "ch_ppocr_mobile_v2.0_cls_opt.nb";
|
||||
Log.e("Predictor", "model path" + config.detModelFilename + " ; " + config.recModelFilename + ";" + config.clsModelFilename);
|
||||
config.cpuPower = cpuPowerMode;
|
||||
config.detModelFilename = realPath + File.separator + "det_db.nb";
|
||||
config.recModelFilename = realPath + File.separator + "rec_crnn.nb";
|
||||
config.clsModelFilename = realPath + File.separator + "cls.nb";
|
||||
Log.i("Predictor", "model path" + config.detModelFilename + " ; " + config.recModelFilename + ";" + config.clsModelFilename);
|
||||
paddlePredictor = new OCRPredictorNative(config);
|
||||
|
||||
this.cpuThreadNum = cpuThreadNum;
|
||||
@@ -170,82 +136,29 @@ public class Predictor {
|
||||
}
|
||||
|
||||
|
||||
public boolean runModel() {
|
||||
public boolean runModel(int run_det, int run_cls, int run_rec) {
|
||||
if (inputImage == null || !isLoaded()) {
|
||||
return false;
|
||||
}
|
||||
|
||||
// Pre-process image, and feed input tensor with pre-processed data
|
||||
|
||||
Bitmap scaleImage = Utils.resizeWithStep(inputImage, Long.valueOf(inputShape[2]).intValue(), 32);
|
||||
|
||||
Date start = new Date();
|
||||
int channels = (int) inputShape[1];
|
||||
int width = scaleImage.getWidth();
|
||||
int height = scaleImage.getHeight();
|
||||
float[] inputData = new float[channels * width * height];
|
||||
if (channels == 3) {
|
||||
int[] channelIdx = null;
|
||||
if (inputColorFormat.equalsIgnoreCase("RGB")) {
|
||||
channelIdx = new int[]{0, 1, 2};
|
||||
} else if (inputColorFormat.equalsIgnoreCase("BGR")) {
|
||||
channelIdx = new int[]{2, 1, 0};
|
||||
} else {
|
||||
Log.i(TAG, "Unknown color format " + inputColorFormat + ", only RGB and BGR color format is " +
|
||||
"supported!");
|
||||
return false;
|
||||
}
|
||||
|
||||
int[] channelStride = new int[]{width * height, width * height * 2};
|
||||
int[] pixels=new int[width*height];
|
||||
scaleImage.getPixels(pixels,0,scaleImage.getWidth(),0,0,scaleImage.getWidth(),scaleImage.getHeight());
|
||||
for (int i = 0; i < pixels.length; i++) {
|
||||
int color = pixels[i];
|
||||
float[] rgb = new float[]{(float) red(color) / 255.0f, (float) green(color) / 255.0f,
|
||||
(float) blue(color) / 255.0f};
|
||||
inputData[i] = (rgb[channelIdx[0]] - inputMean[0]) / inputStd[0];
|
||||
inputData[i + channelStride[0]] = (rgb[channelIdx[1]] - inputMean[1]) / inputStd[1];
|
||||
inputData[i+ channelStride[1]] = (rgb[channelIdx[2]] - inputMean[2]) / inputStd[2];
|
||||
}
|
||||
} else if (channels == 1) {
|
||||
int[] pixels=new int[width*height];
|
||||
scaleImage.getPixels(pixels,0,scaleImage.getWidth(),0,0,scaleImage.getWidth(),scaleImage.getHeight());
|
||||
for (int i = 0; i < pixels.length; i++) {
|
||||
int color = pixels[i];
|
||||
float gray = (float) (red(color) + green(color) + blue(color)) / 3.0f / 255.0f;
|
||||
inputData[i] = (gray - inputMean[0]) / inputStd[0];
|
||||
}
|
||||
} else {
|
||||
Log.i(TAG, "Unsupported channel size " + Integer.toString(channels) + ", only channel 1 and 3 is " +
|
||||
"supported!");
|
||||
return false;
|
||||
}
|
||||
float[] pixels = inputData;
|
||||
Log.i(TAG, "pixels " + pixels[0] + " " + pixels[1] + " " + pixels[2] + " " + pixels[3]
|
||||
+ " " + pixels[pixels.length / 2] + " " + pixels[pixels.length / 2 + 1] + " " + pixels[pixels.length - 2] + " " + pixels[pixels.length - 1]);
|
||||
Date end = new Date();
|
||||
preprocessTime = (float) (end.getTime() - start.getTime());
|
||||
|
||||
// Warm up
|
||||
for (int i = 0; i < warmupIterNum; i++) {
|
||||
paddlePredictor.runImage(inputData, width, height, channels, inputImage);
|
||||
paddlePredictor.runImage(inputImage, detLongSize, run_det, run_cls, run_rec);
|
||||
}
|
||||
warmupIterNum = 0; // do not need warm
|
||||
// Run inference
|
||||
start = new Date();
|
||||
ArrayList<OcrResultModel> results = paddlePredictor.runImage(inputData, width, height, channels, inputImage);
|
||||
end = new Date();
|
||||
Date start = new Date();
|
||||
ArrayList<OcrResultModel> results = paddlePredictor.runImage(inputImage, detLongSize, run_det, run_cls, run_rec);
|
||||
Date end = new Date();
|
||||
inferenceTime = (end.getTime() - start.getTime()) / (float) inferIterNum;
|
||||
|
||||
results = postprocess(results);
|
||||
Log.i(TAG, "[stat] Preprocess Time: " + preprocessTime
|
||||
+ " ; Inference Time: " + inferenceTime + " ;Box Size " + results.size());
|
||||
Log.i(TAG, "[stat] Inference Time: " + inferenceTime + " ;Box Size " + results.size());
|
||||
drawResults(results);
|
||||
|
||||
return true;
|
||||
}
|
||||
|
||||
|
||||
public boolean isLoaded() {
|
||||
return paddlePredictor != null && isLoaded;
|
||||
}
|
||||
@@ -282,10 +195,6 @@ public class Predictor {
|
||||
return outputResult;
|
||||
}
|
||||
|
||||
public float preprocessTime() {
|
||||
return preprocessTime;
|
||||
}
|
||||
|
||||
public float postprocessTime() {
|
||||
return postprocessTime;
|
||||
}
|
||||
@@ -310,6 +219,7 @@ public class Predictor {
|
||||
}
|
||||
}
|
||||
r.setLabel(word.toString());
|
||||
r.setClsLabel(r.getClsIdx() == 1 ? "180" : "0");
|
||||
}
|
||||
return results;
|
||||
}
|
||||
@@ -319,14 +229,22 @@ public class Predictor {
|
||||
for (int i = 0; i < results.size(); i++) {
|
||||
OcrResultModel result = results.get(i);
|
||||
StringBuilder sb = new StringBuilder("");
|
||||
sb.append(result.getLabel());
|
||||
sb.append(" ").append(result.getConfidence());
|
||||
sb.append("; Points: ");
|
||||
for (Point p : result.getPoints()) {
|
||||
sb.append("(").append(p.x).append(",").append(p.y).append(") ");
|
||||
if(result.getPoints().size()>0){
|
||||
sb.append("Det: ");
|
||||
for (Point p : result.getPoints()) {
|
||||
sb.append("(").append(p.x).append(",").append(p.y).append(") ");
|
||||
}
|
||||
}
|
||||
if(result.getLabel().length() > 0){
|
||||
sb.append("\n Rec: ").append(result.getLabel());
|
||||
sb.append(",").append(result.getConfidence());
|
||||
}
|
||||
if(result.getClsIdx()!=-1){
|
||||
sb.append(" Cls: ").append(result.getClsLabel());
|
||||
sb.append(",").append(result.getClsConfidence());
|
||||
}
|
||||
Log.i(TAG, sb.toString()); // show LOG in Logcat panel
|
||||
outputResultSb.append(i + 1).append(": ").append(result.getLabel()).append("\n");
|
||||
outputResultSb.append(i + 1).append(": ").append(sb.toString()).append("\n");
|
||||
}
|
||||
outputResult = outputResultSb.toString();
|
||||
outputImage = inputImage;
|
||||
@@ -344,6 +262,9 @@ public class Predictor {
|
||||
for (OcrResultModel result : results) {
|
||||
Path path = new Path();
|
||||
List<Point> points = result.getPoints();
|
||||
if(points.size()==0){
|
||||
continue;
|
||||
}
|
||||
path.moveTo(points.get(0).x, points.get(0).y);
|
||||
for (int i = points.size() - 1; i >= 0; i--) {
|
||||
Point p = points.get(i);
|
||||
|
||||
@@ -20,16 +20,13 @@ public class SettingsActivity extends AppCompatPreferenceActivity implements Sha
|
||||
ListPreference etImagePath = null;
|
||||
ListPreference lpCPUThreadNum = null;
|
||||
ListPreference lpCPUPowerMode = null;
|
||||
ListPreference lpInputColorFormat = null;
|
||||
EditTextPreference etInputShape = null;
|
||||
EditTextPreference etInputMean = null;
|
||||
EditTextPreference etInputStd = null;
|
||||
EditTextPreference etDetLongSize = null;
|
||||
EditTextPreference etScoreThreshold = null;
|
||||
|
||||
List<String> preInstalledModelPaths = null;
|
||||
List<String> preInstalledLabelPaths = null;
|
||||
List<String> preInstalledImagePaths = null;
|
||||
List<String> preInstalledInputShapes = null;
|
||||
List<String> preInstalledDetLongSizes = null;
|
||||
List<String> preInstalledCPUThreadNums = null;
|
||||
List<String> preInstalledCPUPowerModes = null;
|
||||
List<String> preInstalledInputColorFormats = null;
|
||||
@@ -50,7 +47,7 @@ public class SettingsActivity extends AppCompatPreferenceActivity implements Sha
|
||||
preInstalledModelPaths = new ArrayList<String>();
|
||||
preInstalledLabelPaths = new ArrayList<String>();
|
||||
preInstalledImagePaths = new ArrayList<String>();
|
||||
preInstalledInputShapes = new ArrayList<String>();
|
||||
preInstalledDetLongSizes = new ArrayList<String>();
|
||||
preInstalledCPUThreadNums = new ArrayList<String>();
|
||||
preInstalledCPUPowerModes = new ArrayList<String>();
|
||||
preInstalledInputColorFormats = new ArrayList<String>();
|
||||
@@ -63,10 +60,7 @@ public class SettingsActivity extends AppCompatPreferenceActivity implements Sha
|
||||
preInstalledImagePaths.add(getString(R.string.IMAGE_PATH_DEFAULT));
|
||||
preInstalledCPUThreadNums.add(getString(R.string.CPU_THREAD_NUM_DEFAULT));
|
||||
preInstalledCPUPowerModes.add(getString(R.string.CPU_POWER_MODE_DEFAULT));
|
||||
preInstalledInputColorFormats.add(getString(R.string.INPUT_COLOR_FORMAT_DEFAULT));
|
||||
preInstalledInputShapes.add(getString(R.string.INPUT_SHAPE_DEFAULT));
|
||||
preInstalledInputMeans.add(getString(R.string.INPUT_MEAN_DEFAULT));
|
||||
preInstalledInputStds.add(getString(R.string.INPUT_STD_DEFAULT));
|
||||
preInstalledDetLongSizes.add(getString(R.string.DET_LONG_SIZE_DEFAULT));
|
||||
preInstalledScoreThresholds.add(getString(R.string.SCORE_THRESHOLD_DEFAULT));
|
||||
|
||||
// Setup UI components
|
||||
@@ -89,11 +83,7 @@ public class SettingsActivity extends AppCompatPreferenceActivity implements Sha
|
||||
(ListPreference) findPreference(getString(R.string.CPU_THREAD_NUM_KEY));
|
||||
lpCPUPowerMode =
|
||||
(ListPreference) findPreference(getString(R.string.CPU_POWER_MODE_KEY));
|
||||
lpInputColorFormat =
|
||||
(ListPreference) findPreference(getString(R.string.INPUT_COLOR_FORMAT_KEY));
|
||||
etInputShape = (EditTextPreference) findPreference(getString(R.string.INPUT_SHAPE_KEY));
|
||||
etInputMean = (EditTextPreference) findPreference(getString(R.string.INPUT_MEAN_KEY));
|
||||
etInputStd = (EditTextPreference) findPreference(getString(R.string.INPUT_STD_KEY));
|
||||
etDetLongSize = (EditTextPreference) findPreference(getString(R.string.DET_LONG_SIZE_KEY));
|
||||
etScoreThreshold = (EditTextPreference) findPreference(getString(R.string.SCORE_THRESHOLD_KEY));
|
||||
}
|
||||
|
||||
@@ -112,11 +102,7 @@ public class SettingsActivity extends AppCompatPreferenceActivity implements Sha
|
||||
editor.putString(getString(R.string.IMAGE_PATH_KEY), preInstalledImagePaths.get(modelIdx));
|
||||
editor.putString(getString(R.string.CPU_THREAD_NUM_KEY), preInstalledCPUThreadNums.get(modelIdx));
|
||||
editor.putString(getString(R.string.CPU_POWER_MODE_KEY), preInstalledCPUPowerModes.get(modelIdx));
|
||||
editor.putString(getString(R.string.INPUT_COLOR_FORMAT_KEY),
|
||||
preInstalledInputColorFormats.get(modelIdx));
|
||||
editor.putString(getString(R.string.INPUT_SHAPE_KEY), preInstalledInputShapes.get(modelIdx));
|
||||
editor.putString(getString(R.string.INPUT_MEAN_KEY), preInstalledInputMeans.get(modelIdx));
|
||||
editor.putString(getString(R.string.INPUT_STD_KEY), preInstalledInputStds.get(modelIdx));
|
||||
editor.putString(getString(R.string.DET_LONG_SIZE_KEY), preInstalledDetLongSizes.get(modelIdx));
|
||||
editor.putString(getString(R.string.SCORE_THRESHOLD_KEY),
|
||||
preInstalledScoreThresholds.get(modelIdx));
|
||||
editor.apply();
|
||||
@@ -129,10 +115,7 @@ public class SettingsActivity extends AppCompatPreferenceActivity implements Sha
|
||||
etImagePath.setEnabled(enableCustomSettings);
|
||||
lpCPUThreadNum.setEnabled(enableCustomSettings);
|
||||
lpCPUPowerMode.setEnabled(enableCustomSettings);
|
||||
lpInputColorFormat.setEnabled(enableCustomSettings);
|
||||
etInputShape.setEnabled(enableCustomSettings);
|
||||
etInputMean.setEnabled(enableCustomSettings);
|
||||
etInputStd.setEnabled(enableCustomSettings);
|
||||
etDetLongSize.setEnabled(enableCustomSettings);
|
||||
etScoreThreshold.setEnabled(enableCustomSettings);
|
||||
modelPath = sharedPreferences.getString(getString(R.string.MODEL_PATH_KEY),
|
||||
getString(R.string.MODEL_PATH_DEFAULT));
|
||||
@@ -144,14 +127,8 @@ public class SettingsActivity extends AppCompatPreferenceActivity implements Sha
|
||||
getString(R.string.CPU_THREAD_NUM_DEFAULT));
|
||||
String cpuPowerMode = sharedPreferences.getString(getString(R.string.CPU_POWER_MODE_KEY),
|
||||
getString(R.string.CPU_POWER_MODE_DEFAULT));
|
||||
String inputColorFormat = sharedPreferences.getString(getString(R.string.INPUT_COLOR_FORMAT_KEY),
|
||||
getString(R.string.INPUT_COLOR_FORMAT_DEFAULT));
|
||||
String inputShape = sharedPreferences.getString(getString(R.string.INPUT_SHAPE_KEY),
|
||||
getString(R.string.INPUT_SHAPE_DEFAULT));
|
||||
String inputMean = sharedPreferences.getString(getString(R.string.INPUT_MEAN_KEY),
|
||||
getString(R.string.INPUT_MEAN_DEFAULT));
|
||||
String inputStd = sharedPreferences.getString(getString(R.string.INPUT_STD_KEY),
|
||||
getString(R.string.INPUT_STD_DEFAULT));
|
||||
String detLongSize = sharedPreferences.getString(getString(R.string.DET_LONG_SIZE_KEY),
|
||||
getString(R.string.DET_LONG_SIZE_DEFAULT));
|
||||
String scoreThreshold = sharedPreferences.getString(getString(R.string.SCORE_THRESHOLD_KEY),
|
||||
getString(R.string.SCORE_THRESHOLD_DEFAULT));
|
||||
etModelPath.setSummary(modelPath);
|
||||
@@ -164,14 +141,8 @@ public class SettingsActivity extends AppCompatPreferenceActivity implements Sha
|
||||
lpCPUThreadNum.setSummary(cpuThreadNum);
|
||||
lpCPUPowerMode.setValue(cpuPowerMode);
|
||||
lpCPUPowerMode.setSummary(cpuPowerMode);
|
||||
lpInputColorFormat.setValue(inputColorFormat);
|
||||
lpInputColorFormat.setSummary(inputColorFormat);
|
||||
etInputShape.setSummary(inputShape);
|
||||
etInputShape.setText(inputShape);
|
||||
etInputMean.setSummary(inputMean);
|
||||
etInputMean.setText(inputMean);
|
||||
etInputStd.setSummary(inputStd);
|
||||
etInputStd.setText(inputStd);
|
||||
etDetLongSize.setSummary(detLongSize);
|
||||
etDetLongSize.setText(detLongSize);
|
||||
etScoreThreshold.setText(scoreThreshold);
|
||||
etScoreThreshold.setSummary(scoreThreshold);
|
||||
}
|
||||
|
||||
@@ -23,13 +23,7 @@
|
||||
android:layout_height="wrap_content"
|
||||
android:orientation="horizontal">
|
||||
|
||||
<Button
|
||||
android:id="@+id/btn_load_model"
|
||||
android:layout_width="0dp"
|
||||
android:layout_height="wrap_content"
|
||||
android:layout_weight="1"
|
||||
android:onClick="btn_load_model_click"
|
||||
android:text="加载模型" />
|
||||
|
||||
<Button
|
||||
android:id="@+id/btn_run_model"
|
||||
android:layout_width="0dp"
|
||||
@@ -52,7 +46,45 @@
|
||||
android:onClick="btn_choice_img_click"
|
||||
android:text="选取图片" />
|
||||
|
||||
<Button
|
||||
android:id="@+id/btn_reset_img"
|
||||
android:layout_width="0dp"
|
||||
android:layout_height="wrap_content"
|
||||
android:layout_weight="1"
|
||||
android:onClick="btn_reset_img_click"
|
||||
android:text="清空绘图" />
|
||||
|
||||
</LinearLayout>
|
||||
<LinearLayout
|
||||
android:id="@+id/run_mode_layout"
|
||||
android:layout_width="fill_parent"
|
||||
android:layout_height="wrap_content"
|
||||
android:orientation="horizontal">
|
||||
|
||||
<CheckBox
|
||||
android:id="@+id/cb_opencl"
|
||||
android:layout_width="0dp"
|
||||
android:layout_weight="1"
|
||||
android:layout_height="wrap_content"
|
||||
android:text="开启OPENCL"
|
||||
android:onClick="cb_opencl_click"
|
||||
android:visibility="gone"/>
|
||||
<TextView
|
||||
android:layout_width="0dp"
|
||||
android:layout_weight="0.5"
|
||||
android:layout_height="wrap_content"
|
||||
android:text="运行模式:"/>
|
||||
|
||||
<Spinner
|
||||
android:id="@+id/sp_run_mode"
|
||||
android:layout_width="0dp"
|
||||
android:layout_weight="1.5"
|
||||
android:layout_height="wrap_content"
|
||||
android:entries="@array/run_Model"
|
||||
/>
|
||||
|
||||
</LinearLayout>
|
||||
|
||||
<TextView
|
||||
android:id="@+id/tv_input_setting"
|
||||
android:layout_width="wrap_content"
|
||||
@@ -60,7 +92,7 @@
|
||||
android:scrollbars="vertical"
|
||||
android:layout_marginLeft="12dp"
|
||||
android:layout_marginRight="12dp"
|
||||
android:layout_marginTop="10dp"
|
||||
android:layout_marginTop="5dp"
|
||||
android:layout_marginBottom="5dp"
|
||||
android:lineSpacingExtra="4dp"
|
||||
android:singleLine="false"
|
||||
|
||||
@@ -1,46 +0,0 @@
|
||||
<?xml version="1.0" encoding="utf-8"?>
|
||||
<!-- for MiniActivity Use Only -->
|
||||
<androidx.constraintlayout.widget.ConstraintLayout xmlns:android="http://schemas.android.com/apk/res/android"
|
||||
xmlns:app="http://schemas.android.com/apk/res-auto"
|
||||
xmlns:tools="http://schemas.android.com/tools"
|
||||
android:layout_width="match_parent"
|
||||
android:layout_height="match_parent"
|
||||
app:layout_constraintLeft_toLeftOf="parent"
|
||||
app:layout_constraintLeft_toRightOf="parent"
|
||||
tools:context=".MainActivity">
|
||||
|
||||
<TextView
|
||||
android:id="@+id/sample_text"
|
||||
android:layout_width="0dp"
|
||||
android:layout_height="wrap_content"
|
||||
android:text="Hello World!"
|
||||
app:layout_constraintLeft_toLeftOf="parent"
|
||||
app:layout_constraintRight_toRightOf="parent"
|
||||
app:layout_constraintTop_toBottomOf="@id/imageView"
|
||||
android:scrollbars="vertical"
|
||||
/>
|
||||
|
||||
<ImageView
|
||||
android:id="@+id/imageView"
|
||||
android:layout_width="wrap_content"
|
||||
android:layout_height="wrap_content"
|
||||
android:paddingTop="20dp"
|
||||
android:paddingBottom="20dp"
|
||||
app:layout_constraintBottom_toTopOf="@id/imageView"
|
||||
app:layout_constraintLeft_toLeftOf="parent"
|
||||
app:layout_constraintRight_toRightOf="parent"
|
||||
app:layout_constraintTop_toTopOf="parent"
|
||||
tools:srcCompat="@tools:sample/avatars" />
|
||||
|
||||
<Button
|
||||
android:id="@+id/button"
|
||||
android:layout_width="wrap_content"
|
||||
android:layout_height="wrap_content"
|
||||
android:layout_marginBottom="4dp"
|
||||
android:text="Button"
|
||||
app:layout_constraintBottom_toBottomOf="parent"
|
||||
app:layout_constraintLeft_toLeftOf="parent"
|
||||
app:layout_constraintRight_toRightOf="parent"
|
||||
tools:layout_editor_absoluteX="161dp" />
|
||||
|
||||
</androidx.constraintlayout.widget.ConstraintLayout>
|
||||
@@ -1,16 +1,24 @@
|
||||
<?xml version="1.0" encoding="utf-8"?>
|
||||
<resources>
|
||||
<string-array name="image_name_entries">
|
||||
<item>0.jpg</item>
|
||||
<item>90.jpg</item>
|
||||
<item>180.jpg</item>
|
||||
<item>270.jpg</item>
|
||||
<item>det_0.jpg</item>
|
||||
<item>det_90.jpg</item>
|
||||
<item>det_180.jpg</item>
|
||||
<item>det_270.jpg</item>
|
||||
<item>rec_0.jpg</item>
|
||||
<item>rec_0_180.jpg</item>
|
||||
<item>rec_1.jpg</item>
|
||||
<item>rec_1_180.jpg</item>
|
||||
</string-array>
|
||||
<string-array name="image_name_values">
|
||||
<item>images/0.jpg</item>
|
||||
<item>images/90.jpg</item>
|
||||
<item>images/180.jpg</item>
|
||||
<item>images/270.jpg</item>
|
||||
<item>images/det_0.jpg</item>
|
||||
<item>images/det_90.jpg</item>
|
||||
<item>images/det_180.jpg</item>
|
||||
<item>images/det_270.jpg</item>
|
||||
<item>images/rec_0.jpg</item>
|
||||
<item>images/rec_0_180.jpg</item>
|
||||
<item>images/rec_1.jpg</item>
|
||||
<item>images/rec_1_180.jpg</item>
|
||||
</string-array>
|
||||
<string-array name="cpu_thread_num_entries">
|
||||
<item>1 threads</item>
|
||||
@@ -48,4 +56,12 @@
|
||||
<item>BGR</item>
|
||||
<item>RGB</item>
|
||||
</string-array>
|
||||
<string-array name="run_Model">
|
||||
<item>检测+分类+识别</item>
|
||||
<item>检测+识别</item>
|
||||
<item>分类+识别</item>
|
||||
<item>检测</item>
|
||||
<item>识别</item>
|
||||
<item>分类</item>
|
||||
</string-array>
|
||||
</resources>
|
||||
@@ -1,5 +1,5 @@
|
||||
<resources>
|
||||
<string name="app_name">OCR Chinese</string>
|
||||
<string name="app_name">PaddleOCR</string>
|
||||
<string name="CHOOSE_PRE_INSTALLED_MODEL_KEY">CHOOSE_PRE_INSTALLED_MODEL_KEY</string>
|
||||
<string name="ENABLE_CUSTOM_SETTINGS_KEY">ENABLE_CUSTOM_SETTINGS_KEY</string>
|
||||
<string name="MODEL_PATH_KEY">MODEL_PATH_KEY</string>
|
||||
@@ -7,20 +7,14 @@
|
||||
<string name="IMAGE_PATH_KEY">IMAGE_PATH_KEY</string>
|
||||
<string name="CPU_THREAD_NUM_KEY">CPU_THREAD_NUM_KEY</string>
|
||||
<string name="CPU_POWER_MODE_KEY">CPU_POWER_MODE_KEY</string>
|
||||
<string name="INPUT_COLOR_FORMAT_KEY">INPUT_COLOR_FORMAT_KEY</string>
|
||||
<string name="INPUT_SHAPE_KEY">INPUT_SHAPE_KEY</string>
|
||||
<string name="INPUT_MEAN_KEY">INPUT_MEAN_KEY</string>
|
||||
<string name="INPUT_STD_KEY">INPUT_STD_KEY</string>
|
||||
<string name="DET_LONG_SIZE_KEY">DET_LONG_SIZE_KEY</string>
|
||||
<string name="SCORE_THRESHOLD_KEY">SCORE_THRESHOLD_KEY</string>
|
||||
<string name="MODEL_PATH_DEFAULT">models/ocr_v2_for_cpu</string>
|
||||
<string name="MODEL_PATH_DEFAULT">models/ch_PP-OCRv2</string>
|
||||
<string name="LABEL_PATH_DEFAULT">labels/ppocr_keys_v1.txt</string>
|
||||
<string name="IMAGE_PATH_DEFAULT">images/0.jpg</string>
|
||||
<string name="IMAGE_PATH_DEFAULT">images/det_0.jpg</string>
|
||||
<string name="CPU_THREAD_NUM_DEFAULT">4</string>
|
||||
<string name="CPU_POWER_MODE_DEFAULT">LITE_POWER_HIGH</string>
|
||||
<string name="INPUT_COLOR_FORMAT_DEFAULT">BGR</string>
|
||||
<string name="INPUT_SHAPE_DEFAULT">1,3,960</string>
|
||||
<string name="INPUT_MEAN_DEFAULT">0.485, 0.456, 0.406</string>
|
||||
<string name="INPUT_STD_DEFAULT">0.229,0.224,0.225</string>
|
||||
<string name="DET_LONG_SIZE_DEFAULT">960</string>
|
||||
<string name="SCORE_THRESHOLD_DEFAULT">0.1</string>
|
||||
</resources>
|
||||
|
||||
|
||||
@@ -47,26 +47,10 @@
|
||||
android:entryValues="@array/cpu_power_mode_values"/>
|
||||
</PreferenceCategory>
|
||||
<PreferenceCategory android:title="Input Settings">
|
||||
<ListPreference
|
||||
android:defaultValue="@string/INPUT_COLOR_FORMAT_DEFAULT"
|
||||
android:key="@string/INPUT_COLOR_FORMAT_KEY"
|
||||
android:negativeButtonText="@null"
|
||||
android:positiveButtonText="@null"
|
||||
android:title="Input Color Format: BGR or RGB"
|
||||
android:entries="@array/input_color_format_entries"
|
||||
android:entryValues="@array/input_color_format_values"/>
|
||||
<EditTextPreference
|
||||
android:key="@string/INPUT_SHAPE_KEY"
|
||||
android:defaultValue="@string/INPUT_SHAPE_DEFAULT"
|
||||
android:title="Input Shape: (1,1,max_width_height) or (1,3,max_width_height)" />
|
||||
<EditTextPreference
|
||||
android:key="@string/INPUT_MEAN_KEY"
|
||||
android:defaultValue="@string/INPUT_MEAN_DEFAULT"
|
||||
android:title="Input Mean: (channel/255-mean)/std" />
|
||||
<EditTextPreference
|
||||
android:key="@string/INPUT_STD_KEY"
|
||||
android:defaultValue="@string/INPUT_STD_DEFAULT"
|
||||
android:title="Input Std: (channel/255-mean)/std" />
|
||||
android:key="@string/DET_LONG_SIZE_KEY"
|
||||
android:defaultValue="@string/DET_LONG_SIZE_DEFAULT"
|
||||
android:title="det long size" />
|
||||
</PreferenceCategory>
|
||||
<PreferenceCategory android:title="Output Settings">
|
||||
<EditTextPreference
|
||||
|
||||
@@ -45,8 +45,9 @@ public:
|
||||
const double &det_db_thresh,
|
||||
const double &det_db_box_thresh,
|
||||
const double &det_db_unclip_ratio,
|
||||
const bool &use_polygon_score, const bool &visualize,
|
||||
const bool &use_tensorrt, const std::string &precision) {
|
||||
const bool &use_polygon_score, const bool &use_dilation,
|
||||
const bool &visualize, const bool &use_tensorrt,
|
||||
const std::string &precision) {
|
||||
this->use_gpu_ = use_gpu;
|
||||
this->gpu_id_ = gpu_id;
|
||||
this->gpu_mem_ = gpu_mem;
|
||||
@@ -59,6 +60,7 @@ public:
|
||||
this->det_db_box_thresh_ = det_db_box_thresh;
|
||||
this->det_db_unclip_ratio_ = det_db_unclip_ratio;
|
||||
this->use_polygon_score_ = use_polygon_score;
|
||||
this->use_dilation_ = use_dilation;
|
||||
|
||||
this->visualize_ = visualize;
|
||||
this->use_tensorrt_ = use_tensorrt;
|
||||
@@ -71,7 +73,8 @@ public:
|
||||
void LoadModel(const std::string &model_dir);
|
||||
|
||||
// Run predictor
|
||||
void Run(cv::Mat &img, std::vector<std::vector<std::vector<int>>> &boxes, std::vector<double> *times);
|
||||
void Run(cv::Mat &img, std::vector<std::vector<std::vector<int>>> &boxes,
|
||||
std::vector<double> *times);
|
||||
|
||||
private:
|
||||
std::shared_ptr<Predictor> predictor_;
|
||||
@@ -88,6 +91,7 @@ private:
|
||||
double det_db_box_thresh_ = 0.5;
|
||||
double det_db_unclip_ratio_ = 2.0;
|
||||
bool use_polygon_score_ = false;
|
||||
bool use_dilation_ = false;
|
||||
|
||||
bool visualize_ = true;
|
||||
bool use_tensorrt_ = false;
|
||||
|
||||
@@ -4,16 +4,20 @@
|
||||
C++在性能计算上优于python,因此,在大多数CPU、GPU部署场景,多采用C++的部署方式,本节将介绍如何在Linux\Windows (CPU\GPU)环境下配置C++环境并完成
|
||||
PaddleOCR模型部署。
|
||||
|
||||
* [1. 准备环境](#1)
|
||||
+ [1.0 运行准备](#10)
|
||||
+ [1.1 编译opencv库](#11)
|
||||
+ [1.2 下载或者编译Paddle预测库](#12)
|
||||
- [1.2.1 直接下载安装](#121)
|
||||
- [1.2.2 预测库源码编译](#122)
|
||||
* [2 开始运行](#2)
|
||||
+ [2.1 将模型导出为inference model](#21)
|
||||
+ [2.2 编译PaddleOCR C++预测demo](#22)
|
||||
+ [2.3运行demo](#23)
|
||||
- [服务器端C++预测](#服务器端c预测)
|
||||
- [1. 准备环境](#1-准备环境)
|
||||
- [1.0 运行准备](#10-运行准备)
|
||||
- [1.1 编译opencv库](#11-编译opencv库)
|
||||
- [1.2 下载或者编译Paddle预测库](#12-下载或者编译paddle预测库)
|
||||
- [1.2.1 直接下载安装](#121-直接下载安装)
|
||||
- [1.2.2 预测库源码编译](#122-预测库源码编译)
|
||||
- [2 开始运行](#2-开始运行)
|
||||
- [2.1 将模型导出为inference model](#21-将模型导出为inference-model)
|
||||
- [2.2 编译PaddleOCR C++预测demo](#22-编译paddleocr-c预测demo)
|
||||
- [2.3 运行demo](#23-运行demo)
|
||||
- [1. 只调用检测:](#1-只调用检测)
|
||||
- [2. 只调用识别:](#2-只调用识别)
|
||||
- [3. 调用串联:](#3-调用串联)
|
||||
|
||||
<a name="1"></a>
|
||||
|
||||
@@ -103,7 +107,7 @@ opencv3/
|
||||
|
||||
#### 1.2.1 直接下载安装
|
||||
|
||||
* [Paddle预测库官网](https://paddle-inference.readthedocs.io/en/latest/user_guides/download_lib.html) 上提供了不同cuda版本的Linux预测库,可以在官网查看并选择合适的预测库版本(*建议选择paddle版本>=2.0.1版本的预测库* )。
|
||||
* [Paddle预测库官网](https://paddleinference.paddlepaddle.org.cn/user_guides/download_lib.html#linux) 上提供了不同cuda版本的Linux预测库,可以在官网查看并选择合适的预测库版本(*建议选择paddle版本>=2.0.1版本的预测库* )。
|
||||
|
||||
* 下载之后使用下面的方法解压。
|
||||
|
||||
@@ -249,7 +253,7 @@ CUDNN_LIB_DIR=/your_cudnn_lib_dir
|
||||
|gpu_id|int|0|GPU id,使用GPU时有效|
|
||||
|gpu_mem|int|4000|申请的GPU内存|
|
||||
|cpu_math_library_num_threads|int|10|CPU预测时的线程数,在机器核数充足的情况下,该值越大,预测速度越快|
|
||||
|use_mkldnn|bool|true|是否使用mkldnn库|
|
||||
|enable_mkldnn|bool|true|是否使用mkldnn库|
|
||||
|
||||
- 检测模型相关
|
||||
|
||||
|
||||
@@ -78,7 +78,7 @@ opencv3/
|
||||
|
||||
#### 1.2.1 Direct download and installation
|
||||
|
||||
[Paddle inference library official website](https://paddle-inference.readthedocs.io/en/latest/user_guides/download_lib.html). You can review and select the appropriate version of the inference library on the official website.
|
||||
[Paddle inference library official website](https://paddleinference.paddlepaddle.org.cn/user_guides/download_lib.html#linux). You can review and select the appropriate version of the inference library on the official website.
|
||||
|
||||
|
||||
* After downloading, use the following command to extract files.
|
||||
@@ -231,7 +231,7 @@ More parameters are as follows,
|
||||
|gpu_id|int|0|GPU id when use_gpu is true|
|
||||
|gpu_mem|int|4000|GPU memory requested|
|
||||
|cpu_math_library_num_threads|int|10|Number of threads when using CPU inference. When machine cores is enough, the large the value, the faster the inference speed|
|
||||
|use_mkldnn|bool|true|Whether to use mkdlnn library|
|
||||
|enable_mkldnn|bool|true|Whether to use mkdlnn library|
|
||||
|
||||
- Detection related parameters
|
||||
|
||||
|
||||
@@ -28,14 +28,14 @@
|
||||
#include <numeric>
|
||||
|
||||
#include <glog/logging.h>
|
||||
#include <include/ocr_det.h>
|
||||
#include <include/ocr_cls.h>
|
||||
#include <include/ocr_det.h>
|
||||
#include <include/ocr_rec.h>
|
||||
#include <include/utility.h>
|
||||
#include <sys/stat.h>
|
||||
|
||||
#include <gflags/gflags.h>
|
||||
#include "auto_log/autolog.h"
|
||||
#include <gflags/gflags.h>
|
||||
|
||||
DEFINE_bool(use_gpu, false, "Infering with GPU or CPU.");
|
||||
DEFINE_int32(gpu_id, 0, "Device id of GPU to execute.");
|
||||
@@ -51,9 +51,10 @@ DEFINE_string(image_dir, "", "Dir of input image.");
|
||||
DEFINE_string(det_model_dir, "", "Path of det inference model.");
|
||||
DEFINE_int32(max_side_len, 960, "max_side_len of input image.");
|
||||
DEFINE_double(det_db_thresh, 0.3, "Threshold of det_db_thresh.");
|
||||
DEFINE_double(det_db_box_thresh, 0.5, "Threshold of det_db_box_thresh.");
|
||||
DEFINE_double(det_db_unclip_ratio, 1.6, "Threshold of det_db_unclip_ratio.");
|
||||
DEFINE_double(det_db_box_thresh, 0.6, "Threshold of det_db_box_thresh.");
|
||||
DEFINE_double(det_db_unclip_ratio, 1.5, "Threshold of det_db_unclip_ratio.");
|
||||
DEFINE_bool(use_polygon_score, false, "Whether use polygon score.");
|
||||
DEFINE_bool(use_dilation, false, "Whether use the dilation on output map.");
|
||||
DEFINE_bool(visualize, true, "Whether show the detection results.");
|
||||
// classification related
|
||||
DEFINE_bool(use_angle_cls, false, "Whether use use_angle_cls.");
|
||||
@@ -62,281 +63,260 @@ DEFINE_double(cls_thresh, 0.9, "Threshold of cls_thresh.");
|
||||
// recognition related
|
||||
DEFINE_string(rec_model_dir, "", "Path of rec inference model.");
|
||||
DEFINE_int32(rec_batch_num, 6, "rec_batch_num.");
|
||||
DEFINE_string(char_list_file, "../../ppocr/utils/ppocr_keys_v1.txt", "Path of dictionary.");
|
||||
|
||||
DEFINE_string(char_list_file, "../../ppocr/utils/ppocr_keys_v1.txt",
|
||||
"Path of dictionary.");
|
||||
|
||||
using namespace std;
|
||||
using namespace cv;
|
||||
using namespace PaddleOCR;
|
||||
|
||||
|
||||
static bool PathExists(const std::string& path){
|
||||
static bool PathExists(const std::string &path) {
|
||||
#ifdef _WIN32
|
||||
struct _stat buffer;
|
||||
return (_stat(path.c_str(), &buffer) == 0);
|
||||
#else
|
||||
struct stat buffer;
|
||||
return (stat(path.c_str(), &buffer) == 0);
|
||||
#endif // !_WIN32
|
||||
#endif // !_WIN32
|
||||
}
|
||||
|
||||
|
||||
int main_det(std::vector<cv::String> cv_all_img_names) {
|
||||
std::vector<double> time_info = {0, 0, 0};
|
||||
DBDetector det(FLAGS_det_model_dir, FLAGS_use_gpu, FLAGS_gpu_id,
|
||||
FLAGS_gpu_mem, FLAGS_cpu_threads,
|
||||
FLAGS_enable_mkldnn, FLAGS_max_side_len, FLAGS_det_db_thresh,
|
||||
FLAGS_det_db_box_thresh, FLAGS_det_db_unclip_ratio,
|
||||
FLAGS_use_polygon_score, FLAGS_visualize,
|
||||
FLAGS_use_tensorrt, FLAGS_precision);
|
||||
|
||||
for (int i = 0; i < cv_all_img_names.size(); ++i) {
|
||||
// LOG(INFO) << "The predict img: " << cv_all_img_names[i];
|
||||
std::vector<double> time_info = {0, 0, 0};
|
||||
DBDetector det(FLAGS_det_model_dir, FLAGS_use_gpu, FLAGS_gpu_id,
|
||||
FLAGS_gpu_mem, FLAGS_cpu_threads, FLAGS_enable_mkldnn,
|
||||
FLAGS_max_side_len, FLAGS_det_db_thresh,
|
||||
FLAGS_det_db_box_thresh, FLAGS_det_db_unclip_ratio,
|
||||
FLAGS_use_polygon_score, FLAGS_use_dilation, FLAGS_visualize,
|
||||
FLAGS_use_tensorrt, FLAGS_precision);
|
||||
|
||||
cv::Mat srcimg = cv::imread(cv_all_img_names[i], cv::IMREAD_COLOR);
|
||||
if (!srcimg.data) {
|
||||
std::cerr << "[ERROR] image read failed! image path: " << cv_all_img_names[i] << endl;
|
||||
exit(1);
|
||||
}
|
||||
std::vector<std::vector<std::vector<int>>> boxes;
|
||||
std::vector<double> det_times;
|
||||
for (int i = 0; i < cv_all_img_names.size(); ++i) {
|
||||
// LOG(INFO) << "The predict img: " << cv_all_img_names[i];
|
||||
|
||||
det.Run(srcimg, boxes, &det_times);
|
||||
|
||||
time_info[0] += det_times[0];
|
||||
time_info[1] += det_times[1];
|
||||
time_info[2] += det_times[2];
|
||||
|
||||
if (FLAGS_benchmark) {
|
||||
cout << cv_all_img_names[i] << '\t';
|
||||
for (int n = 0; n < boxes.size(); n++) {
|
||||
for (int m = 0; m < boxes[n].size(); m++) {
|
||||
cout << boxes[n][m][0] << ' ' << boxes[n][m][1] << ' ';
|
||||
}
|
||||
}
|
||||
cout << endl;
|
||||
}
|
||||
cv::Mat srcimg = cv::imread(cv_all_img_names[i], cv::IMREAD_COLOR);
|
||||
if (!srcimg.data) {
|
||||
std::cerr << "[ERROR] image read failed! image path: "
|
||||
<< cv_all_img_names[i] << endl;
|
||||
exit(1);
|
||||
}
|
||||
|
||||
std::vector<std::vector<std::vector<int>>> boxes;
|
||||
std::vector<double> det_times;
|
||||
|
||||
det.Run(srcimg, boxes, &det_times);
|
||||
|
||||
time_info[0] += det_times[0];
|
||||
time_info[1] += det_times[1];
|
||||
time_info[2] += det_times[2];
|
||||
|
||||
if (FLAGS_benchmark) {
|
||||
AutoLogger autolog("ocr_det",
|
||||
FLAGS_use_gpu,
|
||||
FLAGS_use_tensorrt,
|
||||
FLAGS_enable_mkldnn,
|
||||
FLAGS_cpu_threads,
|
||||
1,
|
||||
"dynamic",
|
||||
FLAGS_precision,
|
||||
time_info,
|
||||
cv_all_img_names.size());
|
||||
autolog.report();
|
||||
cout << cv_all_img_names[i] << '\t';
|
||||
for (int n = 0; n < boxes.size(); n++) {
|
||||
for (int m = 0; m < boxes[n].size(); m++) {
|
||||
cout << boxes[n][m][0] << ' ' << boxes[n][m][1] << ' ';
|
||||
}
|
||||
}
|
||||
cout << endl;
|
||||
}
|
||||
return 0;
|
||||
}
|
||||
}
|
||||
|
||||
if (FLAGS_benchmark) {
|
||||
AutoLogger autolog("ocr_det", FLAGS_use_gpu, FLAGS_use_tensorrt,
|
||||
FLAGS_enable_mkldnn, FLAGS_cpu_threads, 1, "dynamic",
|
||||
FLAGS_precision, time_info, cv_all_img_names.size());
|
||||
autolog.report();
|
||||
}
|
||||
return 0;
|
||||
}
|
||||
|
||||
int main_rec(std::vector<cv::String> cv_all_img_names) {
|
||||
std::vector<double> time_info = {0, 0, 0};
|
||||
|
||||
std::string char_list_file = FLAGS_char_list_file;
|
||||
if (FLAGS_benchmark)
|
||||
char_list_file = FLAGS_char_list_file.substr(6);
|
||||
cout << "label file: " << char_list_file << endl;
|
||||
|
||||
CRNNRecognizer rec(FLAGS_rec_model_dir, FLAGS_use_gpu, FLAGS_gpu_id,
|
||||
FLAGS_gpu_mem, FLAGS_cpu_threads,
|
||||
FLAGS_enable_mkldnn, char_list_file,
|
||||
FLAGS_use_tensorrt, FLAGS_precision, FLAGS_rec_batch_num);
|
||||
std::vector<double> time_info = {0, 0, 0};
|
||||
|
||||
std::vector<cv::Mat> img_list;
|
||||
for (int i = 0; i < cv_all_img_names.size(); ++i) {
|
||||
LOG(INFO) << "The predict img: " << cv_all_img_names[i];
|
||||
std::string char_list_file = FLAGS_char_list_file;
|
||||
if (FLAGS_benchmark)
|
||||
char_list_file = FLAGS_char_list_file.substr(6);
|
||||
cout << "label file: " << char_list_file << endl;
|
||||
|
||||
cv::Mat srcimg = cv::imread(cv_all_img_names[i], cv::IMREAD_COLOR);
|
||||
if (!srcimg.data) {
|
||||
std::cerr << "[ERROR] image read failed! image path: " << cv_all_img_names[i] << endl;
|
||||
exit(1);
|
||||
}
|
||||
img_list.push_back(srcimg);
|
||||
CRNNRecognizer rec(FLAGS_rec_model_dir, FLAGS_use_gpu, FLAGS_gpu_id,
|
||||
FLAGS_gpu_mem, FLAGS_cpu_threads, FLAGS_enable_mkldnn,
|
||||
char_list_file, FLAGS_use_tensorrt, FLAGS_precision,
|
||||
FLAGS_rec_batch_num);
|
||||
|
||||
std::vector<cv::Mat> img_list;
|
||||
for (int i = 0; i < cv_all_img_names.size(); ++i) {
|
||||
LOG(INFO) << "The predict img: " << cv_all_img_names[i];
|
||||
|
||||
cv::Mat srcimg = cv::imread(cv_all_img_names[i], cv::IMREAD_COLOR);
|
||||
if (!srcimg.data) {
|
||||
std::cerr << "[ERROR] image read failed! image path: "
|
||||
<< cv_all_img_names[i] << endl;
|
||||
exit(1);
|
||||
}
|
||||
std::vector<double> rec_times;
|
||||
rec.Run(img_list, &rec_times);
|
||||
time_info[0] += rec_times[0];
|
||||
time_info[1] += rec_times[1];
|
||||
time_info[2] += rec_times[2];
|
||||
|
||||
if (FLAGS_benchmark) {
|
||||
AutoLogger autolog("ocr_rec",
|
||||
FLAGS_use_gpu,
|
||||
FLAGS_use_tensorrt,
|
||||
FLAGS_enable_mkldnn,
|
||||
FLAGS_cpu_threads,
|
||||
FLAGS_rec_batch_num,
|
||||
"dynamic",
|
||||
FLAGS_precision,
|
||||
time_info,
|
||||
cv_all_img_names.size());
|
||||
autolog.report();
|
||||
}
|
||||
return 0;
|
||||
img_list.push_back(srcimg);
|
||||
}
|
||||
std::vector<double> rec_times;
|
||||
rec.Run(img_list, &rec_times);
|
||||
time_info[0] += rec_times[0];
|
||||
time_info[1] += rec_times[1];
|
||||
time_info[2] += rec_times[2];
|
||||
|
||||
if (FLAGS_benchmark) {
|
||||
AutoLogger autolog("ocr_rec", FLAGS_use_gpu, FLAGS_use_tensorrt,
|
||||
FLAGS_enable_mkldnn, FLAGS_cpu_threads,
|
||||
FLAGS_rec_batch_num, "dynamic", FLAGS_precision,
|
||||
time_info, cv_all_img_names.size());
|
||||
autolog.report();
|
||||
}
|
||||
return 0;
|
||||
}
|
||||
|
||||
|
||||
int main_system(std::vector<cv::String> cv_all_img_names) {
|
||||
std::vector<double> time_info_det = {0, 0, 0};
|
||||
std::vector<double> time_info_rec = {0, 0, 0};
|
||||
std::vector<double> time_info_det = {0, 0, 0};
|
||||
std::vector<double> time_info_rec = {0, 0, 0};
|
||||
|
||||
DBDetector det(FLAGS_det_model_dir, FLAGS_use_gpu, FLAGS_gpu_id,
|
||||
FLAGS_gpu_mem, FLAGS_cpu_threads,
|
||||
FLAGS_enable_mkldnn, FLAGS_max_side_len, FLAGS_det_db_thresh,
|
||||
FLAGS_det_db_box_thresh, FLAGS_det_db_unclip_ratio,
|
||||
FLAGS_use_polygon_score, FLAGS_visualize,
|
||||
FLAGS_use_tensorrt, FLAGS_precision);
|
||||
DBDetector det(FLAGS_det_model_dir, FLAGS_use_gpu, FLAGS_gpu_id,
|
||||
FLAGS_gpu_mem, FLAGS_cpu_threads, FLAGS_enable_mkldnn,
|
||||
FLAGS_max_side_len, FLAGS_det_db_thresh,
|
||||
FLAGS_det_db_box_thresh, FLAGS_det_db_unclip_ratio,
|
||||
FLAGS_use_polygon_score, FLAGS_use_dilation, FLAGS_visualize,
|
||||
FLAGS_use_tensorrt, FLAGS_precision);
|
||||
|
||||
Classifier *cls = nullptr;
|
||||
if (FLAGS_use_angle_cls) {
|
||||
cls = new Classifier(FLAGS_cls_model_dir, FLAGS_use_gpu, FLAGS_gpu_id,
|
||||
FLAGS_gpu_mem, FLAGS_cpu_threads,
|
||||
FLAGS_enable_mkldnn, FLAGS_cls_thresh,
|
||||
FLAGS_use_tensorrt, FLAGS_precision);
|
||||
Classifier *cls = nullptr;
|
||||
if (FLAGS_use_angle_cls) {
|
||||
cls = new Classifier(FLAGS_cls_model_dir, FLAGS_use_gpu, FLAGS_gpu_id,
|
||||
FLAGS_gpu_mem, FLAGS_cpu_threads, FLAGS_enable_mkldnn,
|
||||
FLAGS_cls_thresh, FLAGS_use_tensorrt, FLAGS_precision);
|
||||
}
|
||||
|
||||
std::string char_list_file = FLAGS_char_list_file;
|
||||
if (FLAGS_benchmark)
|
||||
char_list_file = FLAGS_char_list_file.substr(6);
|
||||
cout << "label file: " << char_list_file << endl;
|
||||
|
||||
CRNNRecognizer rec(FLAGS_rec_model_dir, FLAGS_use_gpu, FLAGS_gpu_id,
|
||||
FLAGS_gpu_mem, FLAGS_cpu_threads, FLAGS_enable_mkldnn,
|
||||
char_list_file, FLAGS_use_tensorrt, FLAGS_precision,
|
||||
FLAGS_rec_batch_num);
|
||||
|
||||
for (int i = 0; i < cv_all_img_names.size(); ++i) {
|
||||
LOG(INFO) << "The predict img: " << cv_all_img_names[i];
|
||||
|
||||
cv::Mat srcimg = cv::imread(cv_all_img_names[i], cv::IMREAD_COLOR);
|
||||
if (!srcimg.data) {
|
||||
std::cerr << "[ERROR] image read failed! image path: "
|
||||
<< cv_all_img_names[i] << endl;
|
||||
exit(1);
|
||||
}
|
||||
std::vector<std::vector<std::vector<int>>> boxes;
|
||||
std::vector<double> det_times;
|
||||
std::vector<double> rec_times;
|
||||
|
||||
det.Run(srcimg, boxes, &det_times);
|
||||
time_info_det[0] += det_times[0];
|
||||
time_info_det[1] += det_times[1];
|
||||
time_info_det[2] += det_times[2];
|
||||
|
||||
std::vector<cv::Mat> img_list;
|
||||
for (int j = 0; j < boxes.size(); j++) {
|
||||
cv::Mat crop_img;
|
||||
crop_img = Utility::GetRotateCropImage(srcimg, boxes[j]);
|
||||
if (cls != nullptr) {
|
||||
crop_img = cls->Run(crop_img);
|
||||
}
|
||||
img_list.push_back(crop_img);
|
||||
}
|
||||
|
||||
std::string char_list_file = FLAGS_char_list_file;
|
||||
if (FLAGS_benchmark)
|
||||
char_list_file = FLAGS_char_list_file.substr(6);
|
||||
cout << "label file: " << char_list_file << endl;
|
||||
|
||||
CRNNRecognizer rec(FLAGS_rec_model_dir, FLAGS_use_gpu, FLAGS_gpu_id,
|
||||
FLAGS_gpu_mem, FLAGS_cpu_threads,
|
||||
FLAGS_enable_mkldnn, char_list_file,
|
||||
FLAGS_use_tensorrt, FLAGS_precision, FLAGS_rec_batch_num);
|
||||
rec.Run(img_list, &rec_times);
|
||||
time_info_rec[0] += rec_times[0];
|
||||
time_info_rec[1] += rec_times[1];
|
||||
time_info_rec[2] += rec_times[2];
|
||||
}
|
||||
|
||||
for (int i = 0; i < cv_all_img_names.size(); ++i) {
|
||||
LOG(INFO) << "The predict img: " << cv_all_img_names[i];
|
||||
|
||||
cv::Mat srcimg = cv::imread(cv_all_img_names[i], cv::IMREAD_COLOR);
|
||||
if (!srcimg.data) {
|
||||
std::cerr << "[ERROR] image read failed! image path: " << cv_all_img_names[i] << endl;
|
||||
exit(1);
|
||||
}
|
||||
std::vector<std::vector<std::vector<int>>> boxes;
|
||||
std::vector<double> det_times;
|
||||
std::vector<double> rec_times;
|
||||
|
||||
det.Run(srcimg, boxes, &det_times);
|
||||
time_info_det[0] += det_times[0];
|
||||
time_info_det[1] += det_times[1];
|
||||
time_info_det[2] += det_times[2];
|
||||
|
||||
std::vector<cv::Mat> img_list;
|
||||
for (int j = 0; j < boxes.size(); j++) {
|
||||
cv::Mat crop_img;
|
||||
crop_img = Utility::GetRotateCropImage(srcimg, boxes[j]);
|
||||
if (cls != nullptr) {
|
||||
crop_img = cls->Run(crop_img);
|
||||
}
|
||||
img_list.push_back(crop_img);
|
||||
}
|
||||
|
||||
rec.Run(img_list, &rec_times);
|
||||
time_info_rec[0] += rec_times[0];
|
||||
time_info_rec[1] += rec_times[1];
|
||||
time_info_rec[2] += rec_times[2];
|
||||
}
|
||||
|
||||
if (FLAGS_benchmark) {
|
||||
AutoLogger autolog_det("ocr_det",
|
||||
FLAGS_use_gpu,
|
||||
FLAGS_use_tensorrt,
|
||||
FLAGS_enable_mkldnn,
|
||||
FLAGS_cpu_threads,
|
||||
1,
|
||||
"dynamic",
|
||||
FLAGS_precision,
|
||||
time_info_det,
|
||||
cv_all_img_names.size());
|
||||
AutoLogger autolog_rec("ocr_rec",
|
||||
FLAGS_use_gpu,
|
||||
FLAGS_use_tensorrt,
|
||||
FLAGS_enable_mkldnn,
|
||||
FLAGS_cpu_threads,
|
||||
FLAGS_rec_batch_num,
|
||||
"dynamic",
|
||||
FLAGS_precision,
|
||||
time_info_rec,
|
||||
cv_all_img_names.size());
|
||||
autolog_det.report();
|
||||
std::cout << endl;
|
||||
autolog_rec.report();
|
||||
}
|
||||
return 0;
|
||||
if (FLAGS_benchmark) {
|
||||
AutoLogger autolog_det("ocr_det", FLAGS_use_gpu, FLAGS_use_tensorrt,
|
||||
FLAGS_enable_mkldnn, FLAGS_cpu_threads, 1, "dynamic",
|
||||
FLAGS_precision, time_info_det,
|
||||
cv_all_img_names.size());
|
||||
AutoLogger autolog_rec("ocr_rec", FLAGS_use_gpu, FLAGS_use_tensorrt,
|
||||
FLAGS_enable_mkldnn, FLAGS_cpu_threads,
|
||||
FLAGS_rec_batch_num, "dynamic", FLAGS_precision,
|
||||
time_info_rec, cv_all_img_names.size());
|
||||
autolog_det.report();
|
||||
std::cout << endl;
|
||||
autolog_rec.report();
|
||||
}
|
||||
return 0;
|
||||
}
|
||||
|
||||
|
||||
void check_params(char* mode) {
|
||||
if (strcmp(mode, "det")==0) {
|
||||
if (FLAGS_det_model_dir.empty() || FLAGS_image_dir.empty()) {
|
||||
std::cout << "Usage[det]: ./ppocr --det_model_dir=/PATH/TO/DET_INFERENCE_MODEL/ "
|
||||
<< "--image_dir=/PATH/TO/INPUT/IMAGE/" << std::endl;
|
||||
exit(1);
|
||||
}
|
||||
void check_params(char *mode) {
|
||||
if (strcmp(mode, "det") == 0) {
|
||||
if (FLAGS_det_model_dir.empty() || FLAGS_image_dir.empty()) {
|
||||
std::cout << "Usage[det]: ./ppocr "
|
||||
"--det_model_dir=/PATH/TO/DET_INFERENCE_MODEL/ "
|
||||
<< "--image_dir=/PATH/TO/INPUT/IMAGE/" << std::endl;
|
||||
exit(1);
|
||||
}
|
||||
if (strcmp(mode, "rec")==0) {
|
||||
if (FLAGS_rec_model_dir.empty() || FLAGS_image_dir.empty()) {
|
||||
std::cout << "Usage[rec]: ./ppocr --rec_model_dir=/PATH/TO/REC_INFERENCE_MODEL/ "
|
||||
<< "--image_dir=/PATH/TO/INPUT/IMAGE/" << std::endl;
|
||||
exit(1);
|
||||
}
|
||||
}
|
||||
if (strcmp(mode, "rec") == 0) {
|
||||
if (FLAGS_rec_model_dir.empty() || FLAGS_image_dir.empty()) {
|
||||
std::cout << "Usage[rec]: ./ppocr "
|
||||
"--rec_model_dir=/PATH/TO/REC_INFERENCE_MODEL/ "
|
||||
<< "--image_dir=/PATH/TO/INPUT/IMAGE/" << std::endl;
|
||||
exit(1);
|
||||
}
|
||||
if (strcmp(mode, "system")==0) {
|
||||
if ((FLAGS_det_model_dir.empty() || FLAGS_rec_model_dir.empty() || FLAGS_image_dir.empty()) ||
|
||||
(FLAGS_use_angle_cls && FLAGS_cls_model_dir.empty())) {
|
||||
std::cout << "Usage[system without angle cls]: ./ppocr --det_model_dir=/PATH/TO/DET_INFERENCE_MODEL/ "
|
||||
<< "--rec_model_dir=/PATH/TO/REC_INFERENCE_MODEL/ "
|
||||
<< "--image_dir=/PATH/TO/INPUT/IMAGE/" << std::endl;
|
||||
std::cout << "Usage[system with angle cls]: ./ppocr --det_model_dir=/PATH/TO/DET_INFERENCE_MODEL/ "
|
||||
<< "--use_angle_cls=true "
|
||||
<< "--cls_model_dir=/PATH/TO/CLS_INFERENCE_MODEL/ "
|
||||
<< "--rec_model_dir=/PATH/TO/REC_INFERENCE_MODEL/ "
|
||||
<< "--image_dir=/PATH/TO/INPUT/IMAGE/" << std::endl;
|
||||
exit(1);
|
||||
}
|
||||
}
|
||||
if (FLAGS_precision != "fp32" && FLAGS_precision != "fp16" && FLAGS_precision != "int8") {
|
||||
cout << "precison should be 'fp32'(default), 'fp16' or 'int8'. " << endl;
|
||||
exit(1);
|
||||
}
|
||||
if (strcmp(mode, "system") == 0) {
|
||||
if ((FLAGS_det_model_dir.empty() || FLAGS_rec_model_dir.empty() ||
|
||||
FLAGS_image_dir.empty()) ||
|
||||
(FLAGS_use_angle_cls && FLAGS_cls_model_dir.empty())) {
|
||||
std::cout << "Usage[system without angle cls]: ./ppocr "
|
||||
"--det_model_dir=/PATH/TO/DET_INFERENCE_MODEL/ "
|
||||
<< "--rec_model_dir=/PATH/TO/REC_INFERENCE_MODEL/ "
|
||||
<< "--image_dir=/PATH/TO/INPUT/IMAGE/" << std::endl;
|
||||
std::cout << "Usage[system with angle cls]: ./ppocr "
|
||||
"--det_model_dir=/PATH/TO/DET_INFERENCE_MODEL/ "
|
||||
<< "--use_angle_cls=true "
|
||||
<< "--cls_model_dir=/PATH/TO/CLS_INFERENCE_MODEL/ "
|
||||
<< "--rec_model_dir=/PATH/TO/REC_INFERENCE_MODEL/ "
|
||||
<< "--image_dir=/PATH/TO/INPUT/IMAGE/" << std::endl;
|
||||
exit(1);
|
||||
}
|
||||
}
|
||||
if (FLAGS_precision != "fp32" && FLAGS_precision != "fp16" &&
|
||||
FLAGS_precision != "int8") {
|
||||
cout << "precison should be 'fp32'(default), 'fp16' or 'int8'. " << endl;
|
||||
exit(1);
|
||||
}
|
||||
}
|
||||
|
||||
|
||||
int main(int argc, char **argv) {
|
||||
if (argc<=1 || (strcmp(argv[1], "det")!=0 && strcmp(argv[1], "rec")!=0 && strcmp(argv[1], "system")!=0)) {
|
||||
std::cout << "Please choose one mode of [det, rec, system] !" << std::endl;
|
||||
return -1;
|
||||
}
|
||||
std::cout << "mode: " << argv[1] << endl;
|
||||
if (argc <= 1 ||
|
||||
(strcmp(argv[1], "det") != 0 && strcmp(argv[1], "rec") != 0 &&
|
||||
strcmp(argv[1], "system") != 0)) {
|
||||
std::cout << "Please choose one mode of [det, rec, system] !" << std::endl;
|
||||
return -1;
|
||||
}
|
||||
std::cout << "mode: " << argv[1] << endl;
|
||||
|
||||
// Parsing command-line
|
||||
google::ParseCommandLineFlags(&argc, &argv, true);
|
||||
check_params(argv[1]);
|
||||
|
||||
if (!PathExists(FLAGS_image_dir)) {
|
||||
std::cerr << "[ERROR] image path not exist! image_dir: " << FLAGS_image_dir << endl;
|
||||
exit(1);
|
||||
}
|
||||
|
||||
std::vector<cv::String> cv_all_img_names;
|
||||
cv::glob(FLAGS_image_dir, cv_all_img_names);
|
||||
std::cout << "total images num: " << cv_all_img_names.size() << endl;
|
||||
|
||||
if (strcmp(argv[1], "det")==0) {
|
||||
return main_det(cv_all_img_names);
|
||||
}
|
||||
if (strcmp(argv[1], "rec")==0) {
|
||||
return main_rec(cv_all_img_names);
|
||||
}
|
||||
if (strcmp(argv[1], "system")==0) {
|
||||
return main_system(cv_all_img_names);
|
||||
}
|
||||
// Parsing command-line
|
||||
google::ParseCommandLineFlags(&argc, &argv, true);
|
||||
check_params(argv[1]);
|
||||
|
||||
if (!PathExists(FLAGS_image_dir)) {
|
||||
std::cerr << "[ERROR] image path not exist! image_dir: " << FLAGS_image_dir
|
||||
<< endl;
|
||||
exit(1);
|
||||
}
|
||||
|
||||
std::vector<cv::String> cv_all_img_names;
|
||||
cv::glob(FLAGS_image_dir, cv_all_img_names);
|
||||
std::cout << "total images num: " << cv_all_img_names.size() << endl;
|
||||
|
||||
if (strcmp(argv[1], "det") == 0) {
|
||||
return main_det(cv_all_img_names);
|
||||
}
|
||||
if (strcmp(argv[1], "rec") == 0) {
|
||||
return main_rec(cv_all_img_names);
|
||||
}
|
||||
if (strcmp(argv[1], "system") == 0) {
|
||||
return main_system(cv_all_img_names);
|
||||
}
|
||||
}
|
||||
|
||||
@@ -14,7 +14,6 @@
|
||||
|
||||
#include <include/ocr_det.h>
|
||||
|
||||
|
||||
namespace PaddleOCR {
|
||||
|
||||
void DBDetector::LoadModel(const std::string &model_dir) {
|
||||
@@ -30,13 +29,10 @@ void DBDetector::LoadModel(const std::string &model_dir) {
|
||||
if (this->precision_ == "fp16") {
|
||||
precision = paddle_infer::Config::Precision::kHalf;
|
||||
}
|
||||
if (this->precision_ == "int8") {
|
||||
if (this->precision_ == "int8") {
|
||||
precision = paddle_infer::Config::Precision::kInt8;
|
||||
}
|
||||
config.EnableTensorRtEngine(
|
||||
1 << 20, 10, 3,
|
||||
precision,
|
||||
false, false);
|
||||
}
|
||||
config.EnableTensorRtEngine(1 << 20, 10, 3, precision, false, false);
|
||||
std::map<std::string, std::vector<int>> min_input_shape = {
|
||||
{"x", {1, 3, 50, 50}},
|
||||
{"conv2d_92.tmp_0", {1, 96, 20, 20}},
|
||||
@@ -105,7 +101,7 @@ void DBDetector::Run(cv::Mat &img,
|
||||
cv::Mat srcimg;
|
||||
cv::Mat resize_img;
|
||||
img.copyTo(srcimg);
|
||||
|
||||
|
||||
auto preprocess_start = std::chrono::steady_clock::now();
|
||||
this->resize_op_.Run(img, resize_img, this->max_side_len_, ratio_h, ratio_w,
|
||||
this->use_tensorrt_);
|
||||
@@ -116,16 +112,16 @@ void DBDetector::Run(cv::Mat &img,
|
||||
std::vector<float> input(1 * 3 * resize_img.rows * resize_img.cols, 0.0f);
|
||||
this->permute_op_.Run(&resize_img, input.data());
|
||||
auto preprocess_end = std::chrono::steady_clock::now();
|
||||
|
||||
|
||||
// Inference.
|
||||
auto input_names = this->predictor_->GetInputNames();
|
||||
auto input_t = this->predictor_->GetInputHandle(input_names[0]);
|
||||
input_t->Reshape({1, 3, resize_img.rows, resize_img.cols});
|
||||
auto inference_start = std::chrono::steady_clock::now();
|
||||
input_t->CopyFromCpu(input.data());
|
||||
|
||||
|
||||
this->predictor_->Run();
|
||||
|
||||
|
||||
std::vector<float> out_data;
|
||||
auto output_names = this->predictor_->GetOutputNames();
|
||||
auto output_t = this->predictor_->GetOutputHandle(output_names[0]);
|
||||
@@ -136,7 +132,7 @@ void DBDetector::Run(cv::Mat &img,
|
||||
out_data.resize(out_num);
|
||||
output_t->CopyToCpu(out_data.data());
|
||||
auto inference_end = std::chrono::steady_clock::now();
|
||||
|
||||
|
||||
auto postprocess_start = std::chrono::steady_clock::now();
|
||||
int n2 = output_shape[2];
|
||||
int n3 = output_shape[3];
|
||||
@@ -157,24 +153,29 @@ void DBDetector::Run(cv::Mat &img,
|
||||
const double maxvalue = 255;
|
||||
cv::Mat bit_map;
|
||||
cv::threshold(cbuf_map, bit_map, threshold, maxvalue, cv::THRESH_BINARY);
|
||||
cv::Mat dilation_map;
|
||||
cv::Mat dila_ele = cv::getStructuringElement(cv::MORPH_RECT, cv::Size(2, 2));
|
||||
cv::dilate(bit_map, dilation_map, dila_ele);
|
||||
if (this->use_dilation_) {
|
||||
cv::Mat dila_ele =
|
||||
cv::getStructuringElement(cv::MORPH_RECT, cv::Size(2, 2));
|
||||
cv::dilate(bit_map, bit_map, dila_ele);
|
||||
}
|
||||
|
||||
boxes = post_processor_.BoxesFromBitmap(
|
||||
pred_map, dilation_map, this->det_db_box_thresh_,
|
||||
this->det_db_unclip_ratio_, this->use_polygon_score_);
|
||||
pred_map, bit_map, this->det_db_box_thresh_, this->det_db_unclip_ratio_,
|
||||
this->use_polygon_score_);
|
||||
|
||||
boxes = post_processor_.FilterTagDetRes(boxes, ratio_h, ratio_w, srcimg);
|
||||
auto postprocess_end = std::chrono::steady_clock::now();
|
||||
std::cout << "Detected boxes num: " << boxes.size() << endl;
|
||||
|
||||
std::chrono::duration<float> preprocess_diff = preprocess_end - preprocess_start;
|
||||
std::chrono::duration<float> preprocess_diff =
|
||||
preprocess_end - preprocess_start;
|
||||
times->push_back(double(preprocess_diff.count() * 1000));
|
||||
std::chrono::duration<float> inference_diff = inference_end - inference_start;
|
||||
times->push_back(double(inference_diff.count() * 1000));
|
||||
std::chrono::duration<float> postprocess_diff = postprocess_end - postprocess_start;
|
||||
std::chrono::duration<float> postprocess_diff =
|
||||
postprocess_end - postprocess_start;
|
||||
times->push_back(double(postprocess_diff.count() * 1000));
|
||||
|
||||
|
||||
//// visualization
|
||||
if (this->visualize_) {
|
||||
Utility::VisualizeBboxes(srcimg, boxes);
|
||||
|
||||
@@ -15,108 +15,115 @@
|
||||
#include <include/ocr_rec.h>
|
||||
|
||||
namespace PaddleOCR {
|
||||
|
||||
void CRNNRecognizer::Run(std::vector<cv::Mat> img_list, std::vector<double> *times) {
|
||||
std::chrono::duration<float> preprocess_diff = std::chrono::steady_clock::now() - std::chrono::steady_clock::now();
|
||||
std::chrono::duration<float> inference_diff = std::chrono::steady_clock::now() - std::chrono::steady_clock::now();
|
||||
std::chrono::duration<float> postprocess_diff = std::chrono::steady_clock::now() - std::chrono::steady_clock::now();
|
||||
|
||||
int img_num = img_list.size();
|
||||
std::vector<float> width_list;
|
||||
for (int i = 0; i < img_num; i++) {
|
||||
width_list.push_back(float(img_list[i].cols) / img_list[i].rows);
|
||||
void CRNNRecognizer::Run(std::vector<cv::Mat> img_list,
|
||||
std::vector<double> *times) {
|
||||
std::chrono::duration<float> preprocess_diff =
|
||||
std::chrono::steady_clock::now() - std::chrono::steady_clock::now();
|
||||
std::chrono::duration<float> inference_diff =
|
||||
std::chrono::steady_clock::now() - std::chrono::steady_clock::now();
|
||||
std::chrono::duration<float> postprocess_diff =
|
||||
std::chrono::steady_clock::now() - std::chrono::steady_clock::now();
|
||||
|
||||
int img_num = img_list.size();
|
||||
std::vector<float> width_list;
|
||||
for (int i = 0; i < img_num; i++) {
|
||||
width_list.push_back(float(img_list[i].cols) / img_list[i].rows);
|
||||
}
|
||||
std::vector<int> indices = Utility::argsort(width_list);
|
||||
|
||||
for (int beg_img_no = 0; beg_img_no < img_num;
|
||||
beg_img_no += this->rec_batch_num_) {
|
||||
auto preprocess_start = std::chrono::steady_clock::now();
|
||||
int end_img_no = min(img_num, beg_img_no + this->rec_batch_num_);
|
||||
float max_wh_ratio = 0;
|
||||
for (int ino = beg_img_no; ino < end_img_no; ino++) {
|
||||
int h = img_list[indices[ino]].rows;
|
||||
int w = img_list[indices[ino]].cols;
|
||||
float wh_ratio = w * 1.0 / h;
|
||||
max_wh_ratio = max(max_wh_ratio, wh_ratio);
|
||||
}
|
||||
std::vector<int> indices = Utility::argsort(width_list);
|
||||
|
||||
for (int beg_img_no = 0; beg_img_no < img_num; beg_img_no += this->rec_batch_num_) {
|
||||
auto preprocess_start = std::chrono::steady_clock::now();
|
||||
int end_img_no = min(img_num, beg_img_no + this->rec_batch_num_);
|
||||
float max_wh_ratio = 0;
|
||||
for (int ino = beg_img_no; ino < end_img_no; ino ++) {
|
||||
int h = img_list[indices[ino]].rows;
|
||||
int w = img_list[indices[ino]].cols;
|
||||
float wh_ratio = w * 1.0 / h;
|
||||
max_wh_ratio = max(max_wh_ratio, wh_ratio);
|
||||
}
|
||||
std::vector<cv::Mat> norm_img_batch;
|
||||
for (int ino = beg_img_no; ino < end_img_no; ino ++) {
|
||||
cv::Mat srcimg;
|
||||
img_list[indices[ino]].copyTo(srcimg);
|
||||
cv::Mat resize_img;
|
||||
this->resize_op_.Run(srcimg, resize_img, max_wh_ratio, this->use_tensorrt_);
|
||||
this->normalize_op_.Run(&resize_img, this->mean_, this->scale_, this->is_scale_);
|
||||
norm_img_batch.push_back(resize_img);
|
||||
}
|
||||
|
||||
int batch_width = int(ceilf(32 * max_wh_ratio)) - 1;
|
||||
std::vector<float> input(this->rec_batch_num_ * 3 * 32 * batch_width, 0.0f);
|
||||
this->permute_op_.Run(norm_img_batch, input.data());
|
||||
auto preprocess_end = std::chrono::steady_clock::now();
|
||||
preprocess_diff += preprocess_end - preprocess_start;
|
||||
|
||||
// Inference.
|
||||
auto input_names = this->predictor_->GetInputNames();
|
||||
auto input_t = this->predictor_->GetInputHandle(input_names[0]);
|
||||
input_t->Reshape({this->rec_batch_num_, 3, 32, batch_width});
|
||||
auto inference_start = std::chrono::steady_clock::now();
|
||||
input_t->CopyFromCpu(input.data());
|
||||
this->predictor_->Run();
|
||||
|
||||
std::vector<float> predict_batch;
|
||||
auto output_names = this->predictor_->GetOutputNames();
|
||||
auto output_t = this->predictor_->GetOutputHandle(output_names[0]);
|
||||
auto predict_shape = output_t->shape();
|
||||
|
||||
int out_num = std::accumulate(predict_shape.begin(), predict_shape.end(), 1,
|
||||
std::multiplies<int>());
|
||||
predict_batch.resize(out_num);
|
||||
|
||||
output_t->CopyToCpu(predict_batch.data());
|
||||
auto inference_end = std::chrono::steady_clock::now();
|
||||
inference_diff += inference_end - inference_start;
|
||||
|
||||
// ctc decode
|
||||
auto postprocess_start = std::chrono::steady_clock::now();
|
||||
for (int m = 0; m < predict_shape[0]; m++) {
|
||||
std::vector<std::string> str_res;
|
||||
int argmax_idx;
|
||||
int last_index = 0;
|
||||
float score = 0.f;
|
||||
int count = 0;
|
||||
float max_value = 0.0f;
|
||||
|
||||
for (int n = 0; n < predict_shape[1]; n++) {
|
||||
argmax_idx =
|
||||
int(Utility::argmax(&predict_batch[(m * predict_shape[1] + n) * predict_shape[2]],
|
||||
&predict_batch[(m * predict_shape[1] + n + 1) * predict_shape[2]]));
|
||||
max_value =
|
||||
float(*std::max_element(&predict_batch[(m * predict_shape[1] + n) * predict_shape[2]],
|
||||
&predict_batch[(m * predict_shape[1] + n + 1) * predict_shape[2]]));
|
||||
|
||||
if (argmax_idx > 0 && (!(n > 0 && argmax_idx == last_index))) {
|
||||
score += max_value;
|
||||
count += 1;
|
||||
str_res.push_back(label_list_[argmax_idx]);
|
||||
}
|
||||
last_index = argmax_idx;
|
||||
}
|
||||
score /= count;
|
||||
if (isnan(score))
|
||||
continue;
|
||||
for (int i = 0; i < str_res.size(); i++) {
|
||||
std::cout << str_res[i];
|
||||
}
|
||||
std::cout << "\tscore: " << score << std::endl;
|
||||
}
|
||||
auto postprocess_end = std::chrono::steady_clock::now();
|
||||
postprocess_diff += postprocess_end - postprocess_start;
|
||||
int batch_width = 0;
|
||||
std::vector<cv::Mat> norm_img_batch;
|
||||
for (int ino = beg_img_no; ino < end_img_no; ino++) {
|
||||
cv::Mat srcimg;
|
||||
img_list[indices[ino]].copyTo(srcimg);
|
||||
cv::Mat resize_img;
|
||||
this->resize_op_.Run(srcimg, resize_img, max_wh_ratio,
|
||||
this->use_tensorrt_);
|
||||
this->normalize_op_.Run(&resize_img, this->mean_, this->scale_,
|
||||
this->is_scale_);
|
||||
norm_img_batch.push_back(resize_img);
|
||||
batch_width = max(resize_img.cols, batch_width);
|
||||
}
|
||||
times->push_back(double(preprocess_diff.count() * 1000));
|
||||
times->push_back(double(inference_diff.count() * 1000));
|
||||
times->push_back(double(postprocess_diff.count() * 1000));
|
||||
|
||||
std::vector<float> input(this->rec_batch_num_ * 3 * 32 * batch_width, 0.0f);
|
||||
this->permute_op_.Run(norm_img_batch, input.data());
|
||||
auto preprocess_end = std::chrono::steady_clock::now();
|
||||
preprocess_diff += preprocess_end - preprocess_start;
|
||||
|
||||
// Inference.
|
||||
auto input_names = this->predictor_->GetInputNames();
|
||||
auto input_t = this->predictor_->GetInputHandle(input_names[0]);
|
||||
input_t->Reshape({this->rec_batch_num_, 3, 32, batch_width});
|
||||
auto inference_start = std::chrono::steady_clock::now();
|
||||
input_t->CopyFromCpu(input.data());
|
||||
this->predictor_->Run();
|
||||
|
||||
std::vector<float> predict_batch;
|
||||
auto output_names = this->predictor_->GetOutputNames();
|
||||
auto output_t = this->predictor_->GetOutputHandle(output_names[0]);
|
||||
auto predict_shape = output_t->shape();
|
||||
|
||||
int out_num = std::accumulate(predict_shape.begin(), predict_shape.end(), 1,
|
||||
std::multiplies<int>());
|
||||
predict_batch.resize(out_num);
|
||||
|
||||
output_t->CopyToCpu(predict_batch.data());
|
||||
auto inference_end = std::chrono::steady_clock::now();
|
||||
inference_diff += inference_end - inference_start;
|
||||
|
||||
// ctc decode
|
||||
auto postprocess_start = std::chrono::steady_clock::now();
|
||||
for (int m = 0; m < predict_shape[0]; m++) {
|
||||
std::vector<std::string> str_res;
|
||||
int argmax_idx;
|
||||
int last_index = 0;
|
||||
float score = 0.f;
|
||||
int count = 0;
|
||||
float max_value = 0.0f;
|
||||
|
||||
for (int n = 0; n < predict_shape[1]; n++) {
|
||||
argmax_idx = int(Utility::argmax(
|
||||
&predict_batch[(m * predict_shape[1] + n) * predict_shape[2]],
|
||||
&predict_batch[(m * predict_shape[1] + n + 1) * predict_shape[2]]));
|
||||
max_value = float(*std::max_element(
|
||||
&predict_batch[(m * predict_shape[1] + n) * predict_shape[2]],
|
||||
&predict_batch[(m * predict_shape[1] + n + 1) * predict_shape[2]]));
|
||||
|
||||
if (argmax_idx > 0 && (!(n > 0 && argmax_idx == last_index))) {
|
||||
score += max_value;
|
||||
count += 1;
|
||||
str_res.push_back(label_list_[argmax_idx]);
|
||||
}
|
||||
last_index = argmax_idx;
|
||||
}
|
||||
score /= count;
|
||||
if (isnan(score))
|
||||
continue;
|
||||
for (int i = 0; i < str_res.size(); i++) {
|
||||
std::cout << str_res[i];
|
||||
}
|
||||
std::cout << "\tscore: " << score << std::endl;
|
||||
}
|
||||
auto postprocess_end = std::chrono::steady_clock::now();
|
||||
postprocess_diff += postprocess_end - postprocess_start;
|
||||
}
|
||||
times->push_back(double(preprocess_diff.count() * 1000));
|
||||
times->push_back(double(inference_diff.count() * 1000));
|
||||
times->push_back(double(postprocess_diff.count() * 1000));
|
||||
}
|
||||
|
||||
|
||||
void CRNNRecognizer::LoadModel(const std::string &model_dir) {
|
||||
// AnalysisConfig config;
|
||||
paddle_infer::Config config;
|
||||
@@ -130,23 +137,17 @@ void CRNNRecognizer::LoadModel(const std::string &model_dir) {
|
||||
if (this->precision_ == "fp16") {
|
||||
precision = paddle_infer::Config::Precision::kHalf;
|
||||
}
|
||||
if (this->precision_ == "int8") {
|
||||
if (this->precision_ == "int8") {
|
||||
precision = paddle_infer::Config::Precision::kInt8;
|
||||
}
|
||||
config.EnableTensorRtEngine(
|
||||
1 << 20, 10, 3,
|
||||
precision,
|
||||
false, false);
|
||||
}
|
||||
config.EnableTensorRtEngine(1 << 20, 10, 3, precision, false, false);
|
||||
|
||||
std::map<std::string, std::vector<int>> min_input_shape = {
|
||||
{"x", {1, 3, 32, 10}},
|
||||
{"lstm_0.tmp_0", {10, 1, 96}}};
|
||||
{"x", {1, 3, 32, 10}}, {"lstm_0.tmp_0", {10, 1, 96}}};
|
||||
std::map<std::string, std::vector<int>> max_input_shape = {
|
||||
{"x", {1, 3, 32, 2000}},
|
||||
{"lstm_0.tmp_0", {1000, 1, 96}}};
|
||||
{"x", {1, 3, 32, 2000}}, {"lstm_0.tmp_0", {1000, 1, 96}}};
|
||||
std::map<std::string, std::vector<int>> opt_input_shape = {
|
||||
{"x", {1, 3, 32, 320}},
|
||||
{"lstm_0.tmp_0", {25, 1, 96}}};
|
||||
{"x", {1, 3, 32, 320}}, {"lstm_0.tmp_0", {25, 1, 96}}};
|
||||
|
||||
config.SetTRTDynamicShapeInfo(min_input_shape, max_input_shape,
|
||||
opt_input_shape);
|
||||
@@ -168,7 +169,7 @@ void CRNNRecognizer::LoadModel(const std::string &model_dir) {
|
||||
config.SwitchIrOptim(true);
|
||||
|
||||
config.EnableMemoryOptim();
|
||||
// config.DisableGlogInfo();
|
||||
// config.DisableGlogInfo();
|
||||
|
||||
this->predictor_ = CreatePredictor(config);
|
||||
}
|
||||
|
||||
@@ -1,3 +1,14 @@
|
||||
- [端侧部署](#端侧部署)
|
||||
- [1. 准备环境](#1-准备环境)
|
||||
- [运行准备](#运行准备)
|
||||
- [1.1 准备交叉编译环境](#11-准备交叉编译环境)
|
||||
- [1.2 准备预测库](#12-准备预测库)
|
||||
- [2 开始运行](#2-开始运行)
|
||||
- [2.1 模型优化](#21-模型优化)
|
||||
- [2.2 与手机联调](#22-与手机联调)
|
||||
- [注意:](#注意)
|
||||
- [FAQ](#faq)
|
||||
|
||||
# 端侧部署
|
||||
|
||||
本教程将介绍基于[Paddle Lite](https://github.com/PaddlePaddle/Paddle-Lite) 在移动端部署PaddleOCR超轻量中文检测、识别模型的详细步骤。
|
||||
@@ -26,17 +37,17 @@ Paddle Lite是飞桨轻量化推理引擎,为手机、IOT端提供高效推理
|
||||
|
||||
| 平台 | 预测库下载链接 |
|
||||
|---|---|
|
||||
|Android|[arm7](https://github.com/PaddlePaddle/Paddle-Lite/releases/download/v2.9/inference_lite_lib.android.armv7.gcc.c++_shared.with_extra.with_cv.tar.gz) / [arm8](https://github.com/PaddlePaddle/Paddle-Lite/releases/download/v2.9/inference_lite_lib.android.armv8.gcc.c++_shared.with_extra.with_cv.tar.gz)|
|
||||
|IOS|[arm7](https://github.com/PaddlePaddle/Paddle-Lite/releases/download/v2.9/inference_lite_lib.ios.armv7.with_cv.with_extra.with_log.tiny_publish.tar.gz) / [arm8](https://github.com/PaddlePaddle/Paddle-Lite/releases/download/v2.9/inference_lite_lib.ios.armv8.with_cv.with_extra.with_log.tiny_publish.tar.gz)|
|
||||
|Android|[arm7](https://github.com/PaddlePaddle/Paddle-Lite/releases/download/v2.10/inference_lite_lib.android.armv7.gcc.c++_shared.with_extra.with_cv.tar.gz) / [arm8](https://github.com/PaddlePaddle/Paddle-Lite/releases/download/v2.10/inference_lite_lib.android.armv8.gcc.c++_shared.with_extra.with_cv.tar.gz)|
|
||||
|IOS|[arm7](https://github.com/PaddlePaddle/Paddle-Lite/releases/download/v2.10/inference_lite_lib.ios.armv7.with_cv.with_extra.with_log.tiny_publish.tar.gz) / [arm8](https://github.com/PaddlePaddle/Paddle-Lite/releases/download/v2.10/inference_lite_lib.ios.armv8.with_cv.with_extra.with_log.tiny_publish.tar.gz)|
|
||||
|
||||
注:1. 上述预测库为PaddleLite 2.9分支编译得到,有关PaddleLite 2.9 详细信息可参考 [链接](https://github.com/PaddlePaddle/Paddle-Lite/releases/tag/v2.9) 。
|
||||
注:1. 上述预测库为PaddleLite 2.10分支编译得到,有关PaddleLite 2.10 详细信息可参考 [链接](https://github.com/PaddlePaddle/Paddle-Lite/releases/tag/v2.10) 。
|
||||
|
||||
- 2. [推荐]编译Paddle-Lite得到预测库,Paddle-Lite的编译方式如下:
|
||||
```
|
||||
git clone https://github.com/PaddlePaddle/Paddle-Lite.git
|
||||
cd Paddle-Lite
|
||||
# 切换到Paddle-Lite release/v2.9 稳定分支
|
||||
git checkout release/v2.9
|
||||
# 切换到Paddle-Lite release/v2.10 稳定分支
|
||||
git checkout release/v2.10
|
||||
./lite/tools/build_android.sh --arch=armv8 --with_cv=ON --with_extra=ON
|
||||
```
|
||||
|
||||
@@ -85,8 +96,8 @@ Paddle-Lite 提供了多种策略来自动优化原始的模型,其中包括
|
||||
|
||||
|模型版本|模型简介|模型大小|检测模型|文本方向分类模型|识别模型|Paddle-Lite版本|
|
||||
|---|---|---|---|---|---|---|
|
||||
|V2.0|超轻量中文OCR 移动端模型|7.8M|[下载地址](https://paddleocr.bj.bcebos.com/dygraph_v2.0/lite/ch_ppocr_mobile_v2.0_det_opt.nb)|[下载地址](https://paddleocr.bj.bcebos.com/dygraph_v2.0/lite/ch_ppocr_mobile_v2.0_cls_opt.nb)|[下载地址](https://paddleocr.bj.bcebos.com/dygraph_v2.0/lite/ch_ppocr_mobile_v2.0_rec_opt.nb)|v2.9|
|
||||
|V2.0(slim)|超轻量中文OCR 移动端模型|3.3M|[下载地址](https://paddleocr.bj.bcebos.com/dygraph_v2.0/lite/ch_ppocr_mobile_v2.0_det_slim_opt.nb)|[下载地址](https://paddleocr.bj.bcebos.com/dygraph_v2.0/lite/ch_ppocr_mobile_v2.0_cls_slim_opt.nb)|[下载地址](https://paddleocr.bj.bcebos.com/dygraph_v2.0/lite/ch_ppocr_mobile_v2.0_rec_slim_opt.nb)|v2.9|
|
||||
|PP-OCRv2|蒸馏版超轻量中文OCR移动端模型|11M|[下载地址](https://paddleocr.bj.bcebos.com/PP-OCRv2/lite/ch_PP-OCRv2_det_infer_opt.nb)|[下载地址](https://paddleocr.bj.bcebos.com/PP-OCRv2/lite/ch_ppocr_mobile_v2.0_cls_infer_opt.nb)|[下载地址](https://paddleocr.bj.bcebos.com/PP-OCRv2/lite/ch_PP-OCRv2_rec_infer_opt.nb)|v2.10|
|
||||
|PP-OCRv2(slim)|蒸馏版超轻量中文OCR移动端模型|4.6M|[下载地址](https://paddleocr.bj.bcebos.com/PP-OCRv2/lite/ch_PP-OCRv2_det_slim_opt.nb)|[下载地址](https://paddleocr.bj.bcebos.com/PP-OCRv2/lite/ch_ppocr_mobile_v2.0_cls_slim_opt.nb)|[下载地址](https://paddleocr.bj.bcebos.com/PP-OCRv2/lite/ch_PP-OCRv2_rec_slim_opt.nb)|v2.10|
|
||||
|
||||
如果直接使用上述表格中的模型进行部署,可略过下述步骤,直接阅读 [2.2节](#2.2与手机联调)。
|
||||
|
||||
@@ -97,7 +108,7 @@ Paddle-Lite 提供了多种策略来自动优化原始的模型,其中包括
|
||||
# 如果准备环境时已经clone了Paddle-Lite,则不用重新clone Paddle-Lite
|
||||
git clone https://github.com/PaddlePaddle/Paddle-Lite.git
|
||||
cd Paddle-Lite
|
||||
git checkout release/v2.9
|
||||
git checkout release/v2.10
|
||||
# 启动编译
|
||||
./lite/tools/build.sh build_optimize_tool
|
||||
```
|
||||
@@ -123,15 +134,15 @@ cd build.opt/lite/api/
|
||||
下面以PaddleOCR的超轻量中文模型为例,介绍使用编译好的opt文件完成inference模型到Paddle-Lite优化模型的转换。
|
||||
|
||||
```
|
||||
# 【推荐】 下载PaddleOCR V2.0版本的中英文 inference模型
|
||||
wget https://paddleocr.bj.bcebos.com/dygraph_v2.0/slim/ch_ppocr_mobile_v2.0_det_slim_infer.tar && tar xf ch_ppocr_mobile_v2.0_det_slim_infer.tar
|
||||
wget https://paddleocr.bj.bcebos.com/dygraph_v2.0/slim/ch_ppocr_mobile_v2.0_rec_slim_infer.tar && tar xf ch_ppocr_mobile_v2.0_rec_slim_infer.tar
|
||||
# 【推荐】 下载 PP-OCRv2版本的中英文 inference模型
|
||||
wget https://paddleocr.bj.bcebos.com/PP-OCRv2/chinese/ch_PP-OCRv2_det_slim_quant_infer.tar && tar xf ch_PP-OCRv2_det_slim_quant_infer.tar
|
||||
wget https://paddleocr.bj.bcebos.com/PP-OCRv2/chinese/ch_PP-OCRv2_rec_slim_quant_infer.tar && tar xf ch_PP-OCRv2_rec_slim_quant_infer.tar
|
||||
wget https://paddleocr.bj.bcebos.com/dygraph_v2.0/slim/ch_ppocr_mobile_v2.0_cls_slim_infer.tar && tar xf ch_ppocr_mobile_v2.0_cls_slim_infer.tar
|
||||
# 转换V2.0检测模型
|
||||
./opt --model_file=./ch_ppocr_mobile_v2.0_det_slim_infer/inference.pdmodel --param_file=./ch_ppocr_mobile_v2.0_det_slim_infer/inference.pdiparams --optimize_out=./ch_ppocr_mobile_v2.0_det_slim_opt --valid_targets=arm --optimize_out_type=naive_buffer
|
||||
# 转换V2.0识别模型
|
||||
./opt --model_file=./ch_ppocr_mobile_v2.0_rec_slim_infer/inference.pdmodel --param_file=./ch_ppocr_mobile_v2.0_rec_slim_infer/inference.pdiparams --optimize_out=./ch_ppocr_mobile_v2.0_rec_slim_opt --valid_targets=arm --optimize_out_type=naive_buffer
|
||||
# 转换V2.0方向分类器模型
|
||||
# 转换检测模型
|
||||
./opt --model_file=./ch_PP-OCRv2_det_slim_quant_infer/inference.pdmodel --param_file=./ch_PP-OCRv2_det_slim_quant_infer/inference.pdiparams --optimize_out=./ch_PP-OCRv2_det_slim_opt --valid_targets=arm --optimize_out_type=naive_buffer
|
||||
# 转换识别模型
|
||||
./opt --model_file=./ch_PP-OCRv2_rec_slim_quant_infer/inference.pdmodel --param_file=./ch_PP-OCRv2_rec_slim_quant_infer/inference.pdiparams --optimize_out=./ch_PP-OCRv2_rec_slim_opt --valid_targets=arm --optimize_out_type=naive_buffer
|
||||
# 转换方向分类器模型
|
||||
./opt --model_file=./ch_ppocr_mobile_v2.0_cls_slim_infer/inference.pdmodel --param_file=./ch_ppocr_mobile_v2.0_cls_slim_infer/inference.pdiparams --optimize_out=./ch_ppocr_mobile_v2.0_cls_slim_opt --valid_targets=arm --optimize_out_type=naive_buffer
|
||||
|
||||
```
|
||||
@@ -186,15 +197,15 @@ wget https://paddleocr.bj.bcebos.com/dygraph_v2.0/slim/ch_ppocr_mobile_v2.0_cls
|
||||
```
|
||||
|
||||
准备测试图像,以`PaddleOCR/doc/imgs/11.jpg`为例,将测试的图像复制到`demo/cxx/ocr/debug/`文件夹下。
|
||||
准备lite opt工具优化后的模型文件,比如使用`ch_ppocr_mobile_v2.0_det_slim_opt.nb,ch_ppocr_mobile_v2.0_rec_slim_opt.nb, ch_ppocr_mobile_v2.0_cls_slim_opt.nb`,模型文件放置在`demo/cxx/ocr/debug/`文件夹下。
|
||||
准备lite opt工具优化后的模型文件,比如使用`ch_PP-OCRv2_det_slim_opt.ch_PP-OCRv2_rec_slim_rec.nb, ch_ppocr_mobile_v2.0_cls_slim_opt.nb`,模型文件放置在`demo/cxx/ocr/debug/`文件夹下。
|
||||
|
||||
执行完成后,ocr文件夹下将有如下文件格式:
|
||||
|
||||
```
|
||||
demo/cxx/ocr/
|
||||
|-- debug/
|
||||
| |--ch_ppocr_mobile_v2.0_det_slim_opt.nb 优化后的检测模型文件
|
||||
| |--ch_ppocr_mobile_v2.0_rec_slim_opt.nb 优化后的识别模型文件
|
||||
| |--ch_PP-OCRv2_det_slim_opt.nb 优化后的检测模型文件
|
||||
| |--ch_PP-OCRv2_rec_slim_opt.nb 优化后的识别模型文件
|
||||
| |--ch_ppocr_mobile_v2.0_cls_slim_opt.nb 优化后的文字方向分类器模型文件
|
||||
| |--11.jpg 待测试图像
|
||||
| |--ppocr_keys_v1.txt 中文字典文件
|
||||
@@ -250,7 +261,7 @@ use_direction_classify 0 # 是否使用方向分类器,0表示不使用,1
|
||||
export LD_LIBRARY_PATH=${PWD}:$LD_LIBRARY_PATH
|
||||
# 开始使用,ocr_db_crnn可执行文件的使用方式为:
|
||||
# ./ocr_db_crnn 检测模型文件 方向分类器模型文件 识别模型文件 测试图像路径 字典文件路径
|
||||
./ocr_db_crnn ch_ppocr_mobile_v2.0_det_slim_opt.nb ch_ppocr_mobile_v2.0_rec_slim_opt.nb ch_ppocr_mobile_v2.0_cls_slim_opt.nb ./11.jpg ppocr_keys_v1.txt
|
||||
./ocr_db_crnn ch_PP-OCRv2_det_slim_opt.nb ch_PP-OCRv2_rec_slim_opt.nb ch_ppocr_mobile_v2.0_cls_slim_opt.nb ./11.jpg ppocr_keys_v1.txt
|
||||
```
|
||||
|
||||
如果对代码做了修改,则需要重新编译并push到手机上。
|
||||
|
||||
@@ -1,3 +1,14 @@
|
||||
- [Tutorial of PaddleOCR Mobile deployment](#tutorial-of-paddleocr-mobile-deployment)
|
||||
- [1. Preparation](#1-preparation)
|
||||
- [Preparation environment](#preparation-environment)
|
||||
- [1.1 Prepare the cross-compilation environment](#11-prepare-the-cross-compilation-environment)
|
||||
- [1.2 Prepare Paddle-Lite library](#12-prepare-paddle-lite-library)
|
||||
- [2 Run](#2-run)
|
||||
- [2.1 Inference Model Optimization](#21-inference-model-optimization)
|
||||
- [2.2 Run optimized model on Phone](#22-run-optimized-model-on-phone)
|
||||
- [注意:](#注意)
|
||||
- [FAQ](#faq)
|
||||
|
||||
# Tutorial of PaddleOCR Mobile deployment
|
||||
|
||||
This tutorial will introduce how to use [Paddle Lite](https://github.com/PaddlePaddle/Paddle-Lite) to deploy PaddleOCR ultra-lightweight Chinese and English detection models on mobile phones.
|
||||
@@ -28,17 +39,17 @@ There are two ways to obtain the Paddle-Lite library:
|
||||
|
||||
| Platform | Paddle-Lite library download link |
|
||||
|---|---|
|
||||
|Android|[arm7](https://github.com/PaddlePaddle/Paddle-Lite/releases/download/v2.9/inference_lite_lib.android.armv7.gcc.c++_shared.with_extra.with_cv.tar.gz) / [arm8](https://github.com/PaddlePaddle/Paddle-Lite/releases/download/v2.9/inference_lite_lib.android.armv8.gcc.c++_shared.with_extra.with_cv.tar.gz)|
|
||||
|IOS|[arm7](https://github.com/PaddlePaddle/Paddle-Lite/releases/download/v2.9/inference_lite_lib.ios.armv7.with_cv.with_extra.with_log.tiny_publish.tar.gz) / [arm8](https://github.com/PaddlePaddle/Paddle-Lite/releases/download/v2.9/inference_lite_lib.ios.armv8.with_cv.with_extra.with_log.tiny_publish.tar.gz)|
|
||||
|Android|[arm7](https://github.com/PaddlePaddle/Paddle-Lite/releases/download/v2.10/inference_lite_lib.android.armv7.gcc.c++_shared.with_extra.with_cv.tar.gz) / [arm8](https://github.com/PaddlePaddle/Paddle-Lite/releases/download/v2.10/inference_lite_lib.android.armv8.gcc.c++_shared.with_extra.with_cv.tar.gz)|
|
||||
|IOS|[arm7](https://github.com/PaddlePaddle/Paddle-Lite/releases/download/v2.10/inference_lite_lib.ios.armv7.with_cv.with_extra.with_log.tiny_publish.tar.gz) / [arm8](https://github.com/PaddlePaddle/Paddle-Lite/releases/download/v2.10/inference_lite_lib.ios.armv8.with_cv.with_extra.with_log.tiny_publish.tar.gz)|
|
||||
|
||||
Note: 1. The above Paddle-Lite library is compiled from the Paddle-Lite 2.9 branch. For more information about Paddle-Lite 2.9, please refer to [link](https://github.com/PaddlePaddle/Paddle-Lite/releases/tag/v2.9).
|
||||
Note: 1. The above Paddle-Lite library is compiled from the Paddle-Lite 2.10 branch. For more information about Paddle-Lite 2.10, please refer to [link](https://github.com/PaddlePaddle/Paddle-Lite/releases/tag/v2.10).
|
||||
|
||||
- 2. [Recommended] Compile Paddle-Lite to get the prediction library. The compilation method of Paddle-Lite is as follows:
|
||||
```
|
||||
git clone https://github.com/PaddlePaddle/Paddle-Lite.git
|
||||
cd Paddle-Lite
|
||||
# Switch to Paddle-Lite release/v2.8 stable branch
|
||||
git checkout release/v2.8
|
||||
# Switch to Paddle-Lite release/v2.10 stable branch
|
||||
git checkout release/v2.10
|
||||
./lite/tools/build_android.sh --arch=armv8 --with_cv=ON --with_extra=ON
|
||||
```
|
||||
|
||||
@@ -87,10 +98,10 @@ The following table also provides a series of models that can be deployed on mob
|
||||
|
||||
|Version|Introduction|Model size|Detection model|Text Direction model|Recognition model|Paddle-Lite branch|
|
||||
|---|---|---|---|---|---|---|
|
||||
|V2.0|extra-lightweight chinese OCR optimized model|7.8M|[download link](https://paddleocr.bj.bcebos.com/dygraph_v2.0/lite/ch_ppocr_mobile_v2.0_det_opt.nb)|[download link](https://paddleocr.bj.bcebos.com/dygraph_v2.0/lite/ch_ppocr_mobile_v2.0_cls_opt.nb)|[download link](https://paddleocr.bj.bcebos.com/dygraph_v2.0/lite/ch_ppocr_mobile_v2.0_rec_opt.nb)|v2.9|
|
||||
|V2.0(slim)|extra-lightweight chinese OCR optimized model|3.3M|[download link](https://paddleocr.bj.bcebos.com/dygraph_v2.0/lite/ch_ppocr_mobile_v2.0_det_slim_opt.nb)|[download link](https://paddleocr.bj.bcebos.com/dygraph_v2.0/lite/ch_ppocr_mobile_v2.0_cls_slim_opt.nb)|[download link](https://paddleocr.bj.bcebos.com/dygraph_v2.0/lite/ch_ppocr_mobile_v2.0_rec_slim_opt.nb)|v2.9|
|
||||
|PP-OCRv2|extra-lightweight chinese OCR optimized model|11M|[download link](https://paddleocr.bj.bcebos.com/PP-OCRv2/lite/ch_PP-OCRv2_det_infer_opt.nb)|[download link](https://paddleocr.bj.bcebos.com/PP-OCRv2/lite/ch_ppocr_mobile_v2.0_cls_infer_opt.nb)|[download link](https://paddleocr.bj.bcebos.com/PP-OCRv2/lite/ch_PP-OCRv2_rec_infer_opt.nb)|v2.10|
|
||||
|PP-OCRv2(slim)|extra-lightweight chinese OCR optimized model|4.6M|[download link](https://paddleocr.bj.bcebos.com/PP-OCRv2/lite/ch_PP-OCRv2_det_slim_opt.nb)|[download link](https://paddleocr.bj.bcebos.com/PP-OCRv2/lite/ch_ppocr_mobile_v2.0_cls_slim_opt.nb)|[download link](https://paddleocr.bj.bcebos.com/PP-OCRv2/lite/ch_PP-OCRv2_rec_slim_opt.nb)|v2.10|
|
||||
|
||||
If you directly use the model in the above table for deployment, you can skip the following steps and directly read [Section 2.2](#2.2 Run optimized model on Phone).
|
||||
If you directly use the model in the above table for deployment, you can skip the following steps and directly read [Section 2.2](#2.2-Run-optimized-model-on-Phone).
|
||||
|
||||
If the model to be deployed is not in the above table, you need to follow the steps below to obtain the optimized model.
|
||||
|
||||
@@ -98,7 +109,7 @@ The `opt` tool can be obtained by compiling Paddle Lite.
|
||||
```
|
||||
git clone https://github.com/PaddlePaddle/Paddle-Lite.git
|
||||
cd Paddle-Lite
|
||||
git checkout release/v2.9
|
||||
git checkout release/v2.10
|
||||
./lite/tools/build.sh build_optimize_tool
|
||||
```
|
||||
|
||||
@@ -124,22 +135,22 @@ cd build.opt/lite/api/
|
||||
The following takes the ultra-lightweight Chinese model of PaddleOCR as an example to introduce the use of the compiled opt file to complete the conversion of the inference model to the Paddle-Lite optimized model
|
||||
|
||||
```
|
||||
# [Recommendation] Download the Chinese and English inference model of PaddleOCR V2.0
|
||||
wget https://paddleocr.bj.bcebos.com/dygraph_v2.0/slim/ch_ppocr_mobile_v2.0_det_slim_infer.tar && tar xf ch_ppocr_mobile_v2.0_det_slim_infer.tar
|
||||
wget https://paddleocr.bj.bcebos.com/dygraph_v2.0/slim/ch_ppocr_mobile_v2.0_rec_slim_infer.tar && tar xf ch_ppocr_mobile_v2.0_rec_slim_infer.tar
|
||||
# 【[Recommendation] Download the Chinese and English inference model of PP-OCRv2
|
||||
wget https://paddleocr.bj.bcebos.com/PP-OCRv2/chinese/ch_PP-OCRv2_det_slim_quant_infer.tar && tar xf ch_PP-OCRv2_det_slim_quant_infer.tar
|
||||
wget https://paddleocr.bj.bcebos.com/PP-OCRv2/chinese/ch_PP-OCRv2_rec_slim_quant_infer.tar && tar xf ch_PP-OCRv2_rec_slim_quant_infer.tar
|
||||
wget https://paddleocr.bj.bcebos.com/dygraph_v2.0/slim/ch_ppocr_mobile_v2.0_cls_slim_infer.tar && tar xf ch_ppocr_mobile_v2.0_cls_slim_infer.tar
|
||||
# Convert V2.0 detection model
|
||||
./opt --model_file=./ch_ppocr_mobile_v2.0_det_slim_infer/inference.pdmodel --param_file=./ch_ppocr_mobile_v2.0_det_slim_infer/inference.pdiparams --optimize_out=./ch_ppocr_mobile_v2.0_det_slim_opt --valid_targets=arm --optimize_out_type=naive_buffer
|
||||
# Convert V2.0 recognition model
|
||||
./opt --model_file=./ch_ppocr_mobile_v2.0_rec_slim_infer/inference.pdmodel --param_file=./ch_ppocr_mobile_v2.0_rec_slim_infer/inference.pdiparams --optimize_out=./ch_ppocr_mobile_v2.0_rec_slim_opt --valid_targets=arm --optimize_out_type=naive_buffer
|
||||
# Convert V2.0 angle classifier model
|
||||
# Convert detection model
|
||||
./opt --model_file=./ch_PP-OCRv2_det_slim_quant_infer/inference.pdmodel --param_file=./ch_PP-OCRv2_det_slim_quant_infer/inference.pdiparams --optimize_out=./ch_PP-OCRv2_det_slim_opt --valid_targets=arm --optimize_out_type=naive_buffer
|
||||
# Convert recognition model
|
||||
./opt --model_file=./ch_PP-OCRv2_rec_slim_quant_infer/inference.pdmodel --param_file=./ch_PP-OCRv2_rec_slim_quant_infer/inference.pdiparams --optimize_out=./ch_PP-OCRv2_rec_slim_opt --valid_targets=arm --optimize_out_type=naive_buffer
|
||||
# Convert angle classifier model
|
||||
./opt --model_file=./ch_ppocr_mobile_v2.0_cls_slim_infer/inference.pdmodel --param_file=./ch_ppocr_mobile_v2.0_cls_slim_infer/inference.pdiparams --optimize_out=./ch_ppocr_mobile_v2.0_cls_slim_opt --valid_targets=arm --optimize_out_type=naive_buffer
|
||||
|
||||
```
|
||||
|
||||
After the conversion is successful, there will be more files ending with `.nb` in the inference model directory, which is the successfully converted model file.
|
||||
|
||||
<a name="2.2 Run optimized model on Phone"></a>
|
||||
<a name="2.2-Run-optimized-model-on-Phone"></a>
|
||||
### 2.2 Run optimized model on Phone
|
||||
|
||||
Some preparatory work is required first.
|
||||
@@ -194,8 +205,8 @@ The structure of the OCR demo is as follows after the above command is executed:
|
||||
```
|
||||
demo/cxx/ocr/
|
||||
|-- debug/
|
||||
| |--ch_ppocr_mobile_v2.0_det_slim_opt.nb Detection model
|
||||
| |--ch_ppocr_mobile_v2.0_rec_slim_opt.nb Recognition model
|
||||
| |--ch_PP-OCRv2_det_slim_opt.nb Detection model
|
||||
| |--ch_PP-OCRv2_rec_slim_opt.nb Recognition model
|
||||
| |--ch_ppocr_mobile_v2.0_cls_slim_opt.nb Text direction classification model
|
||||
| |--11.jpg Image for OCR
|
||||
| |--ppocr_keys_v1.txt Dictionary file
|
||||
@@ -249,7 +260,7 @@ After the above steps are completed, you can use adb to push the file to the pho
|
||||
export LD_LIBRARY_PATH=${PWD}:$LD_LIBRARY_PATH
|
||||
# The use of ocr_db_crnn is:
|
||||
# ./ocr_db_crnn Detection model file Orientation classifier model file Recognition model file Test image path Dictionary file path
|
||||
./ocr_db_crnn ch_ppocr_mobile_v2.0_det_opt.nb ch_ppocr_mobile_v2.0_rec_opt.nb ch_ppocr_mobile_v2.0_cls_opt.nb ./11.jpg ppocr_keys_v1.txt
|
||||
./ocr_db_crnn ch_PP-OCRv2_det_slim_opt.nb ch_PP-OCRv2_rec_slim_opt.nb ch_ppocr_mobile_v2.0_cls_opt.nb ./11.jpg ppocr_keys_v1.txt
|
||||
```
|
||||
|
||||
If you modify the code, you need to recompile and push to the phone.
|
||||
|
||||

|
After Width: | Height: | Size: 206 KiB |

|
After Width: | Height: | Size: 206 KiB |
@@ -1,10 +1,19 @@
|
||||
# paddle2onnx 模型转化与预测
|
||||
|
||||
本章节介绍 PaddleOCR 模型如何转化为 ONNX 模型,并基于 ONNX 引擎预测。
|
||||
本章节介绍 PaddleOCR 模型如何转化为 ONNX 模型,并基于 ONNXRuntime 引擎预测。
|
||||
|
||||
## 1. 环境准备
|
||||
|
||||
需要准备 Paddle2ONNX 模型转化环境,和 ONNX 模型预测环境
|
||||
需要准备 PaddleOCR、Paddle2ONNX 模型转化环境,和 ONNXRuntime 预测环境
|
||||
|
||||
### PaddleOCR
|
||||
|
||||
克隆PaddleOCR的仓库,使用release/2.4分支,并进行安装,由于PaddleOCR仓库比较大,git clone速度比较慢,所以本教程已下载
|
||||
|
||||
```
|
||||
git clone -b release/2.4 https://github.com/PaddlePaddle/PaddleOCR.git
|
||||
cd PaddleOCR && python3.7 setup.py install
|
||||
```
|
||||
|
||||
### Paddle2ONNX
|
||||
|
||||
@@ -16,7 +25,7 @@ Paddle2ONNX 支持将 PaddlePaddle 模型格式转化到 ONNX 模型格式,算
|
||||
python3.7 -m pip install paddle2onnx
|
||||
```
|
||||
|
||||
- 安装 ONNX
|
||||
- 安装 ONNXRuntime
|
||||
```
|
||||
# 建议安装 1.9.0 版本,可根据环境更换版本号
|
||||
python3.7 -m pip install onnxruntime==1.9.0
|
||||
@@ -30,11 +39,17 @@ python3.7 -m pip install onnxruntime==1.9.0
|
||||
有两种方式获取Paddle静态图模型:在 [model_list](../../doc/doc_ch/models_list.md) 中下载PaddleOCR提供的预测模型;
|
||||
参考[模型导出说明](../../doc/doc_ch/inference.md#训练模型转inference模型)把训练好的权重转为 inference_model。
|
||||
|
||||
以 ppocr 检测模型为例:
|
||||
以 ppocr 中文检测、识别、分类模型为例:
|
||||
|
||||
```
|
||||
wget -nc -P ./inference https://paddleocr.bj.bcebos.com/dygraph_v2.0/ch/ch_ppocr_mobile_v2.0_det_infer.tar
|
||||
cd ./inference && tar xf ch_ppocr_mobile_v2.0_det_infer.tar && cd ..
|
||||
wget -nc -P ./inference https://paddleocr.bj.bcebos.com/PP-OCRv2/chinese/ch_PP-OCRv2_det_infer.tar
|
||||
cd ./inference && tar xf ch_PP-OCRv2_det_infer.tar && cd ..
|
||||
|
||||
wget -nc -P ./inference https://paddleocr.bj.bcebos.com/PP-OCRv2/chinese/ch_PP-OCRv2_rec_infer.tar
|
||||
cd ./inference && tar xf ch_PP-OCRv2_rec_infer.tar && cd ..
|
||||
|
||||
wget -nc -P ./inference https://paddleocr.bj.bcebos.com/dygraph_v2.0/ch/ch_ppocr_mobile_v2.0_cls_infer.tar
|
||||
cd ./inference && tar xf ch_ppocr_mobile_v2.0_cls_infer.tar && cd ..
|
||||
```
|
||||
|
||||
- 模型转换
|
||||
@@ -42,35 +57,160 @@ cd ./inference && tar xf ch_ppocr_mobile_v2.0_det_infer.tar && cd ..
|
||||
使用 Paddle2ONNX 将Paddle静态图模型转换为ONNX模型格式:
|
||||
|
||||
```
|
||||
paddle2onnx --model_dir=./inference/ch_ppocr_mobile_v2.0_det_infer/ \
|
||||
--model_filename=inference.pdmodel \
|
||||
--params_filename=inference.pdiparams \
|
||||
--save_file=./inference/det_mobile_onnx/model.onnx \
|
||||
--opset_version=10 \
|
||||
--input_shape_dict="{'x': [-1, 3, -1, -1]}" \
|
||||
--enable_onnx_checker=True
|
||||
paddle2onnx --model_dir ./inference/ch_PP-OCRv2_det_infer \
|
||||
--model_filename inference.pdmodel \
|
||||
--params_filename inference.pdiparams \
|
||||
--save_file ./inference/det_onnx/model.onnx \
|
||||
--opset_version 10 \
|
||||
--input_shape_dict="{'x':[-1,3,-1,-1]}" \
|
||||
--enable_onnx_checker True
|
||||
|
||||
paddle2onnx --model_dir ./inference/ch_PP-OCRv2_rec_infer \
|
||||
--model_filename inference.pdmodel \
|
||||
--params_filename inference.pdiparams \
|
||||
--save_file ./inference/rec_onnx/model.onnx \
|
||||
--opset_version 10 \
|
||||
--input_shape_dict="{'x':[-1,3,-1,-1]}" \
|
||||
--enable_onnx_checker True
|
||||
|
||||
paddle2onnx --model_dir ./inference/ch_ppocr_mobile_v2.0_cls_infer \
|
||||
--model_filename ch_ppocr_mobile_v2.0_cls_infer/inference.pdmodel \
|
||||
--params_filename ch_ppocr_mobile_v2.0_cls_infer/inference.pdiparams \
|
||||
--save_file ./inferencecls_onnx/model.onnx \
|
||||
--opset_version 10 \
|
||||
--input_shape_dict="{'x':[-1,3,-1,-1]}" \
|
||||
--enable_onnx_checker True
|
||||
```
|
||||
|
||||
执行完毕后,ONNX 模型会被保存在 `./inference/det_mobile_onnx/` 路径下
|
||||
执行完毕后,ONNX 模型会被分别保存在 `./inference/det_onnx/`,`./inference/rec_onnx/`,`./inference/cls_onnx/`路径下
|
||||
|
||||
* 注意:对于OCR模型,转化过程中必须采用动态shape的形式,即加入选项--input_shape_dict="{'x': [-1, 3, -1, -1]}",否则预测结果可能与直接使用Paddle预测有细微不同。
|
||||
另外,以下几个模型暂不支持转换为 ONNX 模型:
|
||||
NRTR、SAR、RARE、SRN
|
||||
|
||||
## 3. onnx 预测
|
||||
## 3. 推理预测
|
||||
|
||||
以检测模型为例,使用 ONNX 预测可执行如下命令:
|
||||
以中文OCR模型为例,使用 ONNXRuntime 预测可执行如下命令:
|
||||
|
||||
```
|
||||
python3.7 ../../tools/infer/predict_det.py --use_gpu=False --use_onnx=True \
|
||||
--det_model_dir=./inference/det_mobile_onnx/model.onnx \
|
||||
--image_dir=../../doc/imgs/1.jpg
|
||||
python3.7 tools/infer/predict_system.py --use_gpu=False --use_onnx=True \
|
||||
--det_model_dir=./inference/det_onnx/model.onnx \
|
||||
--rec_model_dir=./inference/rec_onnx/model.onnx \
|
||||
--cls_model_dir=./inference/cls_onnx/model.onnx \
|
||||
--image_dir=./deploy/lite/imgs/lite_demo.png
|
||||
```
|
||||
|
||||
执行命令后在终端会打印出预测的检测框坐标,并在 `./inference_results/` 下保存可视化结果。
|
||||
以中文OCR模型为例,使用 Paddle Inference 预测可执行如下命令:
|
||||
|
||||
```
|
||||
root INFO: 1.jpg [[[291, 295], [334, 292], [348, 844], [305, 847]], [[344, 296], [379, 294], [387, 669], [353, 671]]]
|
||||
The predict time of ../../doc/imgs/1.jpg: 0.06162881851196289
|
||||
The visualized image saved in ./inference_results/det_res_1.jpg
|
||||
python3.7 tools/infer/predict_system.py --use_gpu=False \
|
||||
--cls_model_dir=./inference/ch_ppocr_mobile_v2.0_cls_infer \
|
||||
--rec_model_dir=./inference/ch_PP-OCRv2_rec_infer \
|
||||
--det_model_dir=./inference/ch_PP-OCRv2_det_infer \
|
||||
--image_dir=./deploy/lite/imgs/lite_demo.png
|
||||
```
|
||||
|
||||
|
||||
执行命令后在终端会打印出预测的识别信息,并在 `./inference_results/` 下保存可视化结果。
|
||||
|
||||
ONNXRuntime 执行效果:
|
||||
|
||||
<div align="center">
|
||||
<img src="./images/lite_demo_onnx.png" width=800">
|
||||
</div>
|
||||
|
||||
Paddle Inference 执行效果:
|
||||
|
||||
<div align="center">
|
||||
<img src="./images/lite_demo_paddle.png" width=800">
|
||||
</div>
|
||||
|
||||
|
||||
使用 ONNXRuntime 预测,终端输出:
|
||||
```
|
||||
[2022/02/22 17:48:27] root DEBUG: dt_boxes num : 38, elapse : 0.043187856674194336
|
||||
[2022/02/22 17:48:27] root DEBUG: rec_res num : 38, elapse : 0.592170000076294
|
||||
[2022/02/22 17:48:27] root DEBUG: 0 Predict time of ./deploy/lite/imgs/lite_demo.png: 0.642s
|
||||
[2022/02/22 17:48:27] root DEBUG: The, 0.984
|
||||
[2022/02/22 17:48:27] root DEBUG: visualized, 0.882
|
||||
[2022/02/22 17:48:27] root DEBUG: etect18片, 0.720
|
||||
[2022/02/22 17:48:27] root DEBUG: image saved in./vis.jpg, 0.947
|
||||
[2022/02/22 17:48:27] root DEBUG: 纯臻营养护发素0.993604, 0.996
|
||||
[2022/02/22 17:48:27] root DEBUG: 产品信息/参数, 0.922
|
||||
[2022/02/22 17:48:27] root DEBUG: 0.992728, 0.914
|
||||
[2022/02/22 17:48:27] root DEBUG: (45元/每公斤,100公斤起订), 0.926
|
||||
[2022/02/22 17:48:27] root DEBUG: 0.97417, 0.977
|
||||
[2022/02/22 17:48:27] root DEBUG: 每瓶22元,1000瓶起订)0.993976, 0.962
|
||||
[2022/02/22 17:48:27] root DEBUG: 【品牌】:代加工方式/0EMODM, 0.945
|
||||
[2022/02/22 17:48:27] root DEBUG: 0.985133, 0.980
|
||||
[2022/02/22 17:48:27] root DEBUG: 【品名】:纯臻营养护发素, 0.921
|
||||
[2022/02/22 17:48:27] root DEBUG: 0.995007, 0.883
|
||||
[2022/02/22 17:48:27] root DEBUG: 【产品编号】:YM-X-30110.96899, 0.955
|
||||
[2022/02/22 17:48:27] root DEBUG: 【净含量】:220ml, 0.943
|
||||
[2022/02/22 17:48:27] root DEBUG: Q.996577, 0.932
|
||||
[2022/02/22 17:48:27] root DEBUG: 【适用人群】:适合所有肤质, 0.913
|
||||
[2022/02/22 17:48:27] root DEBUG: 0.995842, 0.969
|
||||
[2022/02/22 17:48:27] root DEBUG: 【主要成分】:鲸蜡硬脂醇、燕麦B-葡聚, 0.883
|
||||
[2022/02/22 17:48:27] root DEBUG: 0.961928, 0.964
|
||||
[2022/02/22 17:48:27] root DEBUG: 10, 0.812
|
||||
[2022/02/22 17:48:27] root DEBUG: 糖、椰油酰胺丙基甜菜碱、泛醒, 0.866
|
||||
[2022/02/22 17:48:27] root DEBUG: 0.925898, 0.943
|
||||
[2022/02/22 17:48:27] root DEBUG: (成品包材), 0.974
|
||||
[2022/02/22 17:48:27] root DEBUG: 0.972573, 0.961
|
||||
[2022/02/22 17:48:27] root DEBUG: 【主要功能】:可紧致头发磷层,从而达到, 0.936
|
||||
[2022/02/22 17:48:27] root DEBUG: 0.994448, 0.952
|
||||
[2022/02/22 17:48:27] root DEBUG: 13, 0.998
|
||||
[2022/02/22 17:48:27] root DEBUG: 即时持久改善头发光泽的效果,给干燥的头, 0.994
|
||||
[2022/02/22 17:48:27] root DEBUG: 0.990198, 0.975
|
||||
[2022/02/22 17:48:27] root DEBUG: 14, 0.977
|
||||
[2022/02/22 17:48:27] root DEBUG: 发足够的滋养, 0.991
|
||||
[2022/02/22 17:48:27] root DEBUG: 0.997668, 0.918
|
||||
[2022/02/22 17:48:27] root DEBUG: 花费了0.457335秒, 0.901
|
||||
[2022/02/22 17:48:27] root DEBUG: The visualized image saved in ./inference_results/lite_demo.png
|
||||
[2022/02/22 17:48:27] root INFO: The predict total time is 0.7003889083862305
|
||||
```
|
||||
|
||||
使用 Paddle Inference 预测,终端输出:
|
||||
|
||||
```
|
||||
[2022/02/22 17:47:25] root DEBUG: dt_boxes num : 38, elapse : 0.11791276931762695
|
||||
[2022/02/22 17:47:27] root DEBUG: rec_res num : 38, elapse : 2.6206860542297363
|
||||
[2022/02/22 17:47:27] root DEBUG: 0 Predict time of ./deploy/lite/imgs/lite_demo.png: 2.746s
|
||||
[2022/02/22 17:47:27] root DEBUG: The, 0.984
|
||||
[2022/02/22 17:47:27] root DEBUG: visualized, 0.882
|
||||
[2022/02/22 17:47:27] root DEBUG: etect18片, 0.720
|
||||
[2022/02/22 17:47:27] root DEBUG: image saved in./vis.jpg, 0.947
|
||||
[2022/02/22 17:47:27] root DEBUG: 纯臻营养护发素0.993604, 0.996
|
||||
[2022/02/22 17:47:27] root DEBUG: 产品信息/参数, 0.922
|
||||
[2022/02/22 17:47:27] root DEBUG: 0.992728, 0.914
|
||||
[2022/02/22 17:47:27] root DEBUG: (45元/每公斤,100公斤起订), 0.926
|
||||
[2022/02/22 17:47:27] root DEBUG: 0.97417, 0.977
|
||||
[2022/02/22 17:47:27] root DEBUG: 每瓶22元,1000瓶起订)0.993976, 0.962
|
||||
[2022/02/22 17:47:27] root DEBUG: 【品牌】:代加工方式/0EMODM, 0.945
|
||||
[2022/02/22 17:47:27] root DEBUG: 0.985133, 0.980
|
||||
[2022/02/22 17:47:27] root DEBUG: 【品名】:纯臻营养护发素, 0.921
|
||||
[2022/02/22 17:47:27] root DEBUG: 0.995007, 0.883
|
||||
[2022/02/22 17:47:27] root DEBUG: 【产品编号】:YM-X-30110.96899, 0.955
|
||||
[2022/02/22 17:47:27] root DEBUG: 【净含量】:220ml, 0.943
|
||||
[2022/02/22 17:47:27] root DEBUG: Q.996577, 0.932
|
||||
[2022/02/22 17:47:27] root DEBUG: 【适用人群】:适合所有肤质, 0.913
|
||||
[2022/02/22 17:47:27] root DEBUG: 0.995842, 0.969
|
||||
[2022/02/22 17:47:27] root DEBUG: 【主要成分】:鲸蜡硬脂醇、燕麦B-葡聚, 0.883
|
||||
[2022/02/22 17:47:27] root DEBUG: 0.961928, 0.964
|
||||
[2022/02/22 17:47:27] root DEBUG: 10, 0.812
|
||||
[2022/02/22 17:47:27] root DEBUG: 糖、椰油酰胺丙基甜菜碱、泛醒, 0.866
|
||||
[2022/02/22 17:47:27] root DEBUG: 0.925898, 0.943
|
||||
[2022/02/22 17:47:27] root DEBUG: (成品包材), 0.974
|
||||
[2022/02/22 17:47:27] root DEBUG: 0.972573, 0.961
|
||||
[2022/02/22 17:47:27] root DEBUG: 【主要功能】:可紧致头发磷层,从而达到, 0.936
|
||||
[2022/02/22 17:47:27] root DEBUG: 0.994448, 0.952
|
||||
[2022/02/22 17:47:27] root DEBUG: 13, 0.998
|
||||
[2022/02/22 17:47:27] root DEBUG: 即时持久改善头发光泽的效果,给干燥的头, 0.994
|
||||
[2022/02/22 17:47:27] root DEBUG: 0.990198, 0.975
|
||||
[2022/02/22 17:47:27] root DEBUG: 14, 0.977
|
||||
[2022/02/22 17:47:27] root DEBUG: 发足够的滋养, 0.991
|
||||
[2022/02/22 17:47:27] root DEBUG: 0.997668, 0.918
|
||||
[2022/02/22 17:47:27] root DEBUG: 花费了0.457335秒, 0.901
|
||||
[2022/02/22 17:47:27] root DEBUG: The visualized image saved in ./inference_results/lite_demo.png
|
||||
[2022/02/22 17:47:27] root INFO: The predict total time is 2.8338775634765625
|
||||
```
|
||||
|
||||
@@ -34,35 +34,26 @@ The introduction and tutorial of Paddle Serving service deployment framework ref
|
||||
PaddleOCR operating environment and Paddle Serving operating environment are needed.
|
||||
|
||||
1. Please prepare PaddleOCR operating environment reference [link](../../doc/doc_ch/installation.md).
|
||||
Download the corresponding paddle whl package according to the environment, it is recommended to install version 2.0.1.
|
||||
Download the corresponding paddlepaddle whl package according to the environment, it is recommended to install version 2.2.2.
|
||||
|
||||
|
||||
2. The steps of PaddleServing operating environment prepare are as follows:
|
||||
|
||||
Install serving which used to start the service
|
||||
```
|
||||
pip3 install paddle-serving-server==0.6.1 # for CPU
|
||||
pip3 install paddle-serving-server-gpu==0.6.1 # for GPU
|
||||
# Other GPU environments need to confirm the environment and then choose to execute the following commands
|
||||
pip3 install paddle-serving-server-gpu==0.6.1.post101 # GPU with CUDA10.1 + TensorRT6
|
||||
pip3 install paddle-serving-server-gpu==0.6.1.post11 # GPU with CUDA11 + TensorRT7
|
||||
```
|
||||
|
||||
3. Install the client to send requests to the service
|
||||
|
||||
```bash
|
||||
# 安装serving,用于启动服务
|
||||
# Install serving which used to start the service
|
||||
wget https://paddle-serving.bj.bcebos.com/test-dev/whl/paddle_serving_server_gpu-0.7.0.post102-py3-none-any.whl
|
||||
pip3 install paddle_serving_server_gpu-0.7.0.post102-py3-none-any.whl
|
||||
# 如果是cuda10.1环境,可以使用下面的命令安装paddle-serving-server
|
||||
|
||||
# Install paddle-serving-server for cuda10.1
|
||||
# wget https://paddle-serving.bj.bcebos.com/test-dev/whl/paddle_serving_server_gpu-0.7.0.post101-py3-none-any.whl
|
||||
# pip3 install paddle_serving_server_gpu-0.7.0.post101-py3-none-any.whl
|
||||
|
||||
# 安装client,用于向服务发送请求
|
||||
# Install serving which used to start the service
|
||||
wget https://paddle-serving.bj.bcebos.com/test-dev/whl/paddle_serving_client-0.7.0-cp37-none-any.whl
|
||||
pip3 install paddle_serving_client-0.7.0-cp37-none-any.whl
|
||||
|
||||
# 安装serving-app
|
||||
# Install serving-app
|
||||
wget https://paddle-serving.bj.bcebos.com/test-dev/whl/paddle_serving_app-0.7.0-py3-none-any.whl
|
||||
pip3 install paddle_serving_app-0.7.0-py3-none-any.whl
|
||||
```
|
||||
@@ -87,27 +78,27 @@ Then, you can use installed paddle_serving_client tool to convert inference mode
|
||||
python3 -m paddle_serving_client.convert --dirname ./ch_PP-OCRv2_det_infer/ \
|
||||
--model_filename inference.pdmodel \
|
||||
--params_filename inference.pdiparams \
|
||||
--serving_server ./ppocrv2_det_serving/ \
|
||||
--serving_client ./ppocrv2_det_client/
|
||||
--serving_server ./ppocr_det_mobile_2.0_serving/ \
|
||||
--serving_client ./ppocr_det_mobile_2.0_client/
|
||||
|
||||
# Recognition model conversion
|
||||
python3 -m paddle_serving_client.convert --dirname ./ch_PP-OCRv2_rec_infer/ \
|
||||
--model_filename inference.pdmodel \
|
||||
--params_filename inference.pdiparams \
|
||||
--serving_server ./ppocrv2_rec_serving/ \
|
||||
--serving_client ./ppocrv2_rec_client/
|
||||
--serving_server ./ppocr_rec_mobile_2.0_serving/ \
|
||||
--serving_client ./ppocr_rec_mobile_2.0_client/
|
||||
|
||||
```
|
||||
|
||||
After the detection model is converted, there will be additional folders of `ppocr_det_mobile_2.0_serving` and `ppocr_det_mobile_2.0_client` in the current folder, with the following format:
|
||||
```
|
||||
|- ppocrv2_det_serving/
|
||||
|- ppocr_det_mobile_2.0_serving/
|
||||
|- __model__
|
||||
|- __params__
|
||||
|- serving_server_conf.prototxt
|
||||
|- serving_server_conf.stream.prototxt
|
||||
|
||||
|- ppocrv2_det_client
|
||||
|- ppocr_det_mobile_2.0_client
|
||||
|- serving_client_conf.prototxt
|
||||
|- serving_client_conf.stream.prototxt
|
||||
|
||||
|
||||
@@ -31,7 +31,7 @@ PaddleOCR提供2种服务部署方式:
|
||||
需要准备PaddleOCR的运行环境和Paddle Serving的运行环境。
|
||||
|
||||
- 准备PaddleOCR的运行环境[链接](../../doc/doc_ch/installation.md)
|
||||
根据环境下载对应的paddle whl包,推荐安装2.0.1版本
|
||||
根据环境下载对应的paddlepaddle whl包,推荐安装2.2.2版本
|
||||
|
||||
- 准备PaddleServing的运行环境,步骤如下
|
||||
|
||||
@@ -75,26 +75,26 @@ wget https://paddleocr.bj.bcebos.com/PP-OCRv2/chinese/ch_PP-OCRv2_rec_infer.tar
|
||||
python3 -m paddle_serving_client.convert --dirname ./ch_PP-OCRv2_det_infer/ \
|
||||
--model_filename inference.pdmodel \
|
||||
--params_filename inference.pdiparams \
|
||||
--serving_server ./ppocrv2_det_serving/ \
|
||||
--serving_client ./ppocrv2_det_client/
|
||||
--serving_server ./ppocr_det_mobile_2.0_serving/ \
|
||||
--serving_client ./ppocr_det_mobile_2.0_client/
|
||||
|
||||
# 转换识别模型
|
||||
python3 -m paddle_serving_client.convert --dirname ./ch_PP-OCRv2_rec_infer/ \
|
||||
--model_filename inference.pdmodel \
|
||||
--params_filename inference.pdiparams \
|
||||
--serving_server ./ppocrv2_rec_serving/ \
|
||||
--serving_client ./ppocrv2_rec_client/
|
||||
--serving_server ./ppocr_rec_mobile_2.0_serving/ \
|
||||
--serving_client ./ppocr_rec_mobile_2.0_client/
|
||||
```
|
||||
|
||||
检测模型转换完成后,会在当前文件夹多出`ppocrv2_det_serving` 和`ppocrv2_det_client`的文件夹,具备如下格式:
|
||||
检测模型转换完成后,会在当前文件夹多出`ppocr_det_mobile_2.0_serving` 和`ppocr_det_mobile_2.0_client`的文件夹,具备如下格式:
|
||||
```
|
||||
|- ppocrv2_det_serving/
|
||||
|- ppocr_det_mobile_2.0_serving/
|
||||
|- __model__
|
||||
|- __params__
|
||||
|- serving_server_conf.prototxt
|
||||
|- serving_server_conf.stream.prototxt
|
||||
|
||||
|- ppocrv2_det_client
|
||||
|- ppocr_det_mobile_2.0_client
|
||||
|- serving_client_conf.prototxt
|
||||
|- serving_client_conf.stream.prototxt
|
||||
|
||||
|
||||
@@ -34,7 +34,7 @@ op:
|
||||
client_type: local_predictor
|
||||
|
||||
#det模型路径
|
||||
model_config: ./ppocrv2_det_serving
|
||||
model_config: ./ppocr_det_mobile_2.0_serving
|
||||
|
||||
#Fetch结果列表,以client_config中fetch_var的alias_name为准
|
||||
fetch_list: ["save_infer_model/scale_0.tmp_1"]
|
||||
@@ -60,7 +60,7 @@ op:
|
||||
client_type: local_predictor
|
||||
|
||||
#rec模型路径
|
||||
model_config: ./ppocrv2_rec_serving
|
||||
model_config: ./ppocr_rec_mobile_2.0_serving
|
||||
|
||||
#Fetch结果列表,以client_config中fetch_var的alias_name为准
|
||||
fetch_list: ["save_infer_model/scale_0.tmp_1"]
|
||||
|
||||
@@ -433,3 +433,54 @@ class OCRReader(object):
|
||||
text = self.label_ops.decode(
|
||||
preds_idx, preds_prob, is_remove_duplicate=True)
|
||||
return text
|
||||
|
||||
from argparse import ArgumentParser,RawDescriptionHelpFormatter
|
||||
import yaml
|
||||
class ArgsParser(ArgumentParser):
|
||||
def __init__(self):
|
||||
super(ArgsParser, self).__init__(
|
||||
formatter_class=RawDescriptionHelpFormatter)
|
||||
self.add_argument("-c", "--config", help="configuration file to use")
|
||||
self.add_argument(
|
||||
"-o", "--opt", nargs='+', help="set configuration options")
|
||||
|
||||
def parse_args(self, argv=None):
|
||||
args = super(ArgsParser, self).parse_args(argv)
|
||||
assert args.config is not None, \
|
||||
"Please specify --config=configure_file_path."
|
||||
args.conf_dict = self._parse_opt(args.opt, args.config)
|
||||
print("args config:", args.conf_dict)
|
||||
return args
|
||||
|
||||
def _parse_helper(self, v):
|
||||
if v.isnumeric():
|
||||
if "." in v:
|
||||
v = float(v)
|
||||
else:
|
||||
v = int(v)
|
||||
elif v == "True" or v == "False":
|
||||
v = (v == "True")
|
||||
return v
|
||||
|
||||
def _parse_opt(self, opts, conf_path):
|
||||
f = open(conf_path)
|
||||
config = yaml.load(f, Loader=yaml.Loader)
|
||||
if not opts:
|
||||
return config
|
||||
for s in opts:
|
||||
s = s.strip()
|
||||
k, v = s.split('=')
|
||||
v = self._parse_helper(v)
|
||||
print(k,v, type(v))
|
||||
cur = config
|
||||
parent = cur
|
||||
for kk in k.split("."):
|
||||
if kk not in cur:
|
||||
cur[kk] = {}
|
||||
parent = cur
|
||||
cur = cur[kk]
|
||||
else:
|
||||
parent = cur
|
||||
cur = cur[kk]
|
||||
parent[k.split(".")[-1]] = v
|
||||
return config
|
||||
@@ -18,7 +18,7 @@ import numpy as np
|
||||
import cv2
|
||||
import base64
|
||||
# from paddle_serving_app.reader import OCRReader
|
||||
from ocr_reader import OCRReader, DetResizeForTest
|
||||
from ocr_reader import OCRReader, DetResizeForTest, ArgsParser
|
||||
from paddle_serving_app.reader import Sequential, ResizeByFactor
|
||||
from paddle_serving_app.reader import Div, Normalize, Transpose
|
||||
from paddle_serving_app.reader import DBPostProcess, FilterBoxes, GetRotateCropImage, SortedBoxes
|
||||
@@ -73,5 +73,6 @@ class OcrService(WebService):
|
||||
|
||||
|
||||
uci_service = OcrService(name="ocr")
|
||||
uci_service.prepare_pipeline_config("config.yml")
|
||||
FLAGS = ArgsParser().parse_args()
|
||||
uci_service.prepare_pipeline_config(yml_dict=FLAGS.conf_dict)
|
||||
uci_service.run_service()
|
||||
|
||||
@@ -18,7 +18,7 @@ import numpy as np
|
||||
import cv2
|
||||
import base64
|
||||
# from paddle_serving_app.reader import OCRReader
|
||||
from ocr_reader import OCRReader, DetResizeForTest
|
||||
from ocr_reader import OCRReader, DetResizeForTest, ArgsParser
|
||||
from paddle_serving_app.reader import Sequential, ResizeByFactor
|
||||
from paddle_serving_app.reader import Div, Normalize, Transpose
|
||||
|
||||
@@ -82,5 +82,6 @@ class OcrService(WebService):
|
||||
|
||||
|
||||
uci_service = OcrService(name="ocr")
|
||||
uci_service.prepare_pipeline_config("config.yml")
|
||||
FLAGS = ArgsParser().parse_args()
|
||||
uci_service.prepare_pipeline_config(yml_dict=FLAGS.conf_dict)
|
||||
uci_service.run_service()
|
||||
|
||||
@@ -349,7 +349,7 @@ A:PaddleOCR已完成Windows和Mac系统适配,运行时注意两点:
|
||||
|
||||
#### Q:训练文字识别模型,真实数据有30w,合成数据有500w,需要做样本均衡吗?
|
||||
|
||||
A:需要,一般需要保证一个batch中真实数据样本和合成数据样本的比例是1:1~1:3左右效果比较理想。如果合成数据过大,会过拟合到合成数据,预测效果往往不佳。还有一种启发性的尝试是可以先用大量合成数据训练一个base模型,然后再用真实数据微调,在一些简单场景效果也是会有提升的。
|
||||
A:需要,一般需要保证一个batch中真实数据样本和合成数据样本的比例是5:1~10:1左右效果比较理想。如果合成数据过大,会过拟合到合成数据,预测效果往往不佳。还有一种启发性的尝试是可以先用大量合成数据训练一个base模型,然后再用真实数据微调,在一些简单场景效果也是会有提升的。
|
||||
|
||||
#### Q: 当训练数据量少时,如何获取更多的数据?
|
||||
|
||||
|
||||
@@ -1,11 +1,11 @@
|
||||
# 两阶段算法
|
||||
|
||||
- [两阶段算法](#-----)
|
||||
* [1. 算法介绍](#1)
|
||||
+ [1.1 文本检测算法](#11)
|
||||
+ [1.2 文本识别算法](#12)
|
||||
* [2. 模型训练](#2)
|
||||
* [3. 模型推理](#3)
|
||||
- [两阶段算法](#两阶段算法)
|
||||
- [1. 算法介绍](#1-算法介绍)
|
||||
- [1.1 文本检测算法](#11-文本检测算法)
|
||||
- [1.2 文本识别算法](#12-文本识别算法)
|
||||
- [2. 模型训练](#2-模型训练)
|
||||
- [3. 模型推理](#3-模型推理)
|
||||
|
||||
<a name="1"></a>
|
||||
|
||||
@@ -21,6 +21,7 @@ PaddleOCR开源的文本检测算法列表:
|
||||
- [x] EAST([paper](https://arxiv.org/abs/1704.03155))[1]
|
||||
- [x] SAST([paper](https://arxiv.org/abs/1908.05498))[4]
|
||||
- [x] PSENet([paper](https://arxiv.org/abs/1903.12473v2))
|
||||
- [x] FCENet([paper](https://arxiv.org/abs/2104.10442))
|
||||
|
||||
在ICDAR2015文本检测公开数据集上,算法效果如下:
|
||||
|模型|骨干网络|precision|recall|Hmean|下载链接|
|
||||
@@ -39,6 +40,12 @@ PaddleOCR开源的文本检测算法列表:
|
||||
| --- | --- | --- | --- | --- | --- |
|
||||
|SAST|ResNet50_vd|89.63%|78.44%|83.66%|[训练模型](https://paddleocr.bj.bcebos.com/dygraph_v2.0/en/det_r50_vd_sast_totaltext_v2.0_train.tar)|
|
||||
|
||||
在CTW1500文本检测公开数据集上,算法效果如下:
|
||||
|
||||
|模型|骨干网络|precision|recall|Hmean|下载链接|
|
||||
| --- | --- | --- | --- | --- | --- |
|
||||
|FCE|ResNet50_dcn|88.39%|82.18%|85.27%|[训练模型](https://paddleocr.bj.bcebos.com/contribution/det_r50_dcn_fce_ctw_v2.0_train.tar)|
|
||||
|
||||
**说明:** SAST模型训练额外加入了icdar2013、icdar2017、COCO-Text、ArT等公开数据集进行调优。PaddleOCR用到的经过整理格式的英文公开数据集下载:
|
||||
* [百度云地址](https://pan.baidu.com/s/12cPnZcVuV1zn5DOd4mqjVw) (提取码: 2bpi)
|
||||
* [Google Drive下载地址](https://drive.google.com/drive/folders/1ll2-XEVyCQLpJjawLDiRlvo_i4BqHCJe?usp=sharing)
|
||||
|
||||
@@ -10,6 +10,7 @@
|
||||
* [2.1 启动训练](#21-----)
|
||||
* [2.2 断点训练](#22-----)
|
||||
* [2.3 更换Backbone 训练](#23---backbone---)
|
||||
* [2.4 知识蒸馏训练](#24---distill---)
|
||||
- [3. 模型评估与预测](#3--------)
|
||||
* [3.1 指标评估](#31-----)
|
||||
* [3.2 测试检测效果](#32-------)
|
||||
@@ -182,6 +183,15 @@ args1: args1
|
||||
|
||||
**注意**:如果要更换网络的其他模块,可以参考[文档](./add_new_algorithm.md)。
|
||||
|
||||
|
||||
<a name="24---distill---"></a>
|
||||
|
||||
## 2.4 知识蒸馏训练
|
||||
|
||||
PaddleOCR支持了基于知识蒸馏的检测模型训练过程,更多内容可以参考[知识蒸馏说明文档](./knowledge_distillation.md)。
|
||||
|
||||
|
||||
|
||||
<a name="3--------"></a>
|
||||
# 3. 模型评估与预测
|
||||
|
||||
|
||||
@@ -6,13 +6,14 @@
|
||||
> 3. 本文档提供的是PPOCR自研模型列表,更多基于公开数据集的算法介绍与预训练模型可以参考:[算法概览文档](./algorithm_overview.md)。
|
||||
|
||||
|
||||
- [1. 文本检测模型](#文本检测模型)
|
||||
- [2. 文本识别模型](#文本识别模型)
|
||||
- [2.1 中文识别模型](#中文识别模型)
|
||||
- [2.2 英文识别模型](#英文识别模型)
|
||||
- [2.3 多语言识别模型](#多语言识别模型)
|
||||
- [3. 文本方向分类模型](#文本方向分类模型)
|
||||
- [4. Paddle-Lite 模型](#Paddle-Lite模型)
|
||||
- [PP-OCR系列模型列表(V2.1,2021年9月6日更新)](#pp-ocr系列模型列表v212021年9月6日更新)
|
||||
- [1. 文本检测模型](#1-文本检测模型)
|
||||
- [2. 文本识别模型](#2-文本识别模型)
|
||||
- [2.1 中文识别模型](#21-中文识别模型)
|
||||
- [2.2 英文识别模型](#22-英文识别模型)
|
||||
- [2.3 多语言识别模型(更多语言持续更新中...)](#23-多语言识别模型更多语言持续更新中)
|
||||
- [3. 文本方向分类模型](#3-文本方向分类模型)
|
||||
- [4. Paddle-Lite 模型](#4-paddle-lite-模型)
|
||||
|
||||
PaddleOCR提供的可下载模型包括`推理模型`、`训练模型`、`预训练模型`、`slim模型`,模型区别说明如下:
|
||||
|
||||
@@ -100,6 +101,8 @@ PaddleOCR提供的可下载模型包括`推理模型`、`训练模型`、`预训
|
||||
|
||||
|模型版本|模型简介|模型大小|检测模型|文本方向分类模型|识别模型|Paddle-Lite版本|
|
||||
|---|---|---|---|---|---|---|
|
||||
|PP-OCRv2|蒸馏版超轻量中文OCR移动端模型|11M|[下载地址](https://paddleocr.bj.bcebos.com/PP-OCRv2/lite/ch_PP-OCRv2_det_infer_opt.nb)|[下载地址](https://paddleocr.bj.bcebos.com/PP-OCRv2/lite/ch_ppocr_mobile_v2.0_cls_infer_opt.nb)|[下载地址](https://paddleocr.bj.bcebos.com/PP-OCRv2/lite/ch_PP-OCRv2_rec_infer_opt.nb)|v2.10|
|
||||
|PP-OCRv2(slim)|蒸馏版超轻量中文OCR移动端模型|4.6M|[下载地址](https://paddleocr.bj.bcebos.com/PP-OCRv2/lite/ch_PP-OCRv2_det_slim_opt.nb)|[下载地址](https://paddleocr.bj.bcebos.com/PP-OCRv2/lite/ch_ppocr_mobile_v2.0_cls_slim_opt.nb)|[下载地址](https://paddleocr.bj.bcebos.com/PP-OCRv2/lite/ch_PP-OCRv2_rec_slim_opt.nb)|v2.10|
|
||||
|PP-OCRv2|蒸馏版超轻量中文OCR移动端模型|11M|[下载地址](https://paddleocr.bj.bcebos.com/PP-OCRv2/chinese/ch_PP-OCRv2_det_infer_opt.nb)|[下载地址](https://paddleocr.bj.bcebos.com/dygraph_v2.0/lite/ch_ppocr_mobile_v2.0_cls_opt.nb)|[下载地址](https://paddleocr.bj.bcebos.com/PP-OCRv2/chinese/ch_PP-OCRv2_rec_infer_opt.nb)|v2.9|
|
||||
|PP-OCRv2(slim)|蒸馏版超轻量中文OCR移动端模型|4.9M|[下载地址](https://paddleocr.bj.bcebos.com/PP-OCRv2/chinese/ch_PP-OCRv2_det_slim_opt.nb)|[下载地址](https://paddleocr.bj.bcebos.com/dygraph_v2.0/lite/ch_ppocr_mobile_v2.0_cls_slim_opt.nb)|[下载地址](https://paddleocr.bj.bcebos.com/PP-OCRv2/chinese/ch_PP-OCRv2_rec_slim_opt.nb)|v2.9|
|
||||
|V2.0|ppocr_v2.0超轻量中文OCR移动端模型|7.8M|[下载地址](https://paddleocr.bj.bcebos.com/dygraph_v2.0/lite/ch_ppocr_mobile_v2.0_det_opt.nb)|[下载地址](https://paddleocr.bj.bcebos.com/dygraph_v2.0/lite/ch_ppocr_mobile_v2.0_cls_opt.nb)|[下载地址](https://paddleocr.bj.bcebos.com/dygraph_v2.0/lite/ch_ppocr_mobile_v2.0_rec_opt.nb)|v2.9|
|
||||
|
||||
@@ -1,15 +1,12 @@
|
||||
# PaddleOCR快速开始
|
||||
|
||||
|
||||
- [PaddleOCR快速开始](#paddleocr)
|
||||
|
||||
+ [1. 安装PaddleOCR whl包](#1)
|
||||
* [2. 便捷使用](#2)
|
||||
+ [2.1 命令行使用](#21)
|
||||
- [1. 安装PaddleOCR whl包](#1)
|
||||
- [2. 便捷使用](#2)
|
||||
- [2.1 命令行使用](#21)
|
||||
- [2.1.1 中英文模型](#211)
|
||||
- [2.1.2 多语言模型](#212)
|
||||
- [2.1.3 版面分析](#213)
|
||||
+ [2.2 Python脚本使用](#22)
|
||||
- [2.2 Python脚本使用](#22)
|
||||
- [2.2.1 中英文与多语言使用](#221)
|
||||
- [2.2.2 版面分析](#222)
|
||||
|
||||
|
||||
@@ -11,6 +11,7 @@
|
||||
- [2.1 数据增强](#数据增强)
|
||||
- [2.2 通用模型训练](#通用模型训练)
|
||||
- [2.3 多语言模型训练](#多语言模型训练)
|
||||
- [2.4 知识蒸馏训练](#知识蒸馏训练)
|
||||
- [3 评估](#评估)
|
||||
- [4 预测](#预测)
|
||||
- [5 转Inference模型测试](#Inference)
|
||||
@@ -368,6 +369,13 @@ Eval:
|
||||
label_file_list: ["./train_data/french_val.txt"]
|
||||
...
|
||||
```
|
||||
|
||||
<a name="知识蒸馏训练"></a>
|
||||
|
||||
### 2.4 知识蒸馏训练
|
||||
|
||||
PaddleOCR支持了基于知识蒸馏的文本识别模型训练过程,更多内容可以参考[知识蒸馏说明文档](./knowledge_distillation.md)。
|
||||
|
||||
<a name="评估"></a>
|
||||
## 3 评估
|
||||
|
||||
|
||||
@@ -9,6 +9,7 @@ This section uses the icdar2015 dataset as an example to introduce the training,
|
||||
* [2.1 Start Training](#21-start-training)
|
||||
* [2.2 Load Trained Model and Continue Training](#22-load-trained-model-and-continue-training)
|
||||
* [2.3 Training with New Backbone](#23-training-with-new-backbone)
|
||||
* [2.4 Training with knowledge distillation](#24)
|
||||
- [3. Evaluation and Test](#3-evaluation-and-test)
|
||||
* [3.1 Evaluation](#31-evaluation)
|
||||
* [3.2 Test](#32-test)
|
||||
@@ -174,6 +175,11 @@ After adding the four-part modules of the network, you only need to configure th
|
||||
|
||||
**NOTE**: More details about replace Backbone and other mudule can be found in [doc](add_new_algorithm_en.md).
|
||||
|
||||
|
||||
### 2.4 Training with knowledge distillation
|
||||
|
||||
Knowledge distillation is supported in PaddleOCR for text detection training process. For more details, please refer to [doc](./knowledge_distillation_en.md).
|
||||
|
||||
## 3. Evaluation and Test
|
||||
|
||||
### 3.1 Evaluation
|
||||
|
||||
@@ -94,6 +94,8 @@ For more supported languages, please refer to : [Multi-language model](./multi_l
|
||||
## 4. Paddle-Lite Model
|
||||
|Version|Introduction|Model size|Detection model|Text Direction model|Recognition model|Paddle-Lite branch|
|
||||
|---|---|---|---|---|---|---|
|
||||
|PP-OCRv2|extra-lightweight chinese OCR optimized model|11M|[download link](https://paddleocr.bj.bcebos.com/PP-OCRv2/lite/ch_PP-OCRv2_det_infer_opt.nb)|[download link](https://paddleocr.bj.bcebos.com/PP-OCRv2/lite/ch_ppocr_mobile_v2.0_cls_infer_opt.nb)|[download link](https://paddleocr.bj.bcebos.com/PP-OCRv2/lite/ch_PP-OCRv2_rec_infer_opt.nb)|v2.10|
|
||||
|PP-OCRv2(slim)|extra-lightweight chinese OCR optimized model|4.6M|[download link](https://paddleocr.bj.bcebos.com/PP-OCRv2/lite/ch_PP-OCRv2_det_slim_opt.nb)|[download link](https://paddleocr.bj.bcebos.com/PP-OCRv2/lite/ch_ppocr_mobile_v2.0_cls_slim_opt.nb)|[download link](https://paddleocr.bj.bcebos.com/PP-OCRv2/lite/ch_PP-OCRv2_rec_slim_opt.nb)|v2.10|
|
||||
|PP-OCRv2|extra-lightweight chinese OCR optimized model|11M|[download link](https://paddleocr.bj.bcebos.com/PP-OCRv2/chinese/ch_PP-OCRv2_det_infer_opt.nb)|[download link](https://paddleocr.bj.bcebos.com/dygraph_v2.0/lite/ch_ppocr_mobile_v2.0_cls_opt.nb)|[download link](https://paddleocr.bj.bcebos.com/PP-OCRv2/chinese/ch_PP-OCRv2_rec_infer_opt.nb)|v2.9|
|
||||
|PP-OCRv2(slim)|extra-lightweight chinese OCR optimized model|4.9M|[download link](https://paddleocr.bj.bcebos.com/PP-OCRv2/chinese/ch_PP-OCRv2_det_slim_opt.nb)|[download link](https://paddleocr.bj.bcebos.com/dygraph_v2.0/lite/ch_ppocr_mobile_v2.0_cls_slim_opt.nb)|[download link](https://paddleocr.bj.bcebos.com/PP-OCRv2/chinese/ch_PP-OCRv2_rec_slim_opt.nb)|v2.9|
|
||||
|V2.0|ppocr_v2.0 extra-lightweight chinese OCR optimized model|7.8M|[download link](https://paddleocr.bj.bcebos.com/dygraph_v2.0/lite/ch_ppocr_mobile_v2.0_det_opt.nb)|[download link](https://paddleocr.bj.bcebos.com/dygraph_v2.0/lite/ch_ppocr_mobile_v2.0_cls_opt.nb)|[download link](https://paddleocr.bj.bcebos.com/dygraph_v2.0/lite/ch_ppocr_mobile_v2.0_rec_opt.nb)|v2.9|
|
||||
|
||||
@@ -1,8 +1,6 @@
|
||||
|
||||
# PaddleOCR Quick Start
|
||||
|
||||
[PaddleOCR Quick Start](#paddleocr-quick-start)
|
||||
|
||||
+ [1. Install PaddleOCR Whl Package](#1-install-paddleocr-whl-package)
|
||||
* [2. Easy-to-Use](#2-easy-to-use)
|
||||
+ [2.1 Use by Command Line](#21-use-by-command-line)
|
||||
|
||||
@@ -10,6 +10,7 @@
|
||||
- [2.1 Data Augmentation](#Data_Augmentation)
|
||||
- [2.2 General Training](#Training)
|
||||
- [2.3 Multi-language Training](#Multi_language)
|
||||
- [2.4 Training with Knowledge Distillation](#kd)
|
||||
|
||||
- [3. Evaluation](#EVALUATION)
|
||||
|
||||
@@ -361,6 +362,12 @@ Eval:
|
||||
...
|
||||
```
|
||||
|
||||
<a name="kd"></a>
|
||||
|
||||
### 2.4 Training with Knowledge Distillation
|
||||
|
||||
Knowledge distillation is supported in PaddleOCR for text recognition training process. For more details, please refer to [doc](./knowledge_distillation_en.md).
|
||||
|
||||
<a name="EVALUATION"></a>
|
||||
|
||||
## 3. Evalution
|
||||
|
||||
@@ -22,7 +22,8 @@ from .make_shrink_map import MakeShrinkMap
|
||||
from .random_crop_data import EastRandomCropData, RandomCropImgMask
|
||||
from .make_pse_gt import MakePseGt
|
||||
|
||||
from .rec_img_aug import RecAug, RecResizeImg, ClsResizeImg, SRNRecResizeImg, NRTRRecResizeImg, SARRecResizeImg
|
||||
from .rec_img_aug import RecAug, RecResizeImg, ClsResizeImg, \
|
||||
SRNRecResizeImg, NRTRRecResizeImg, SARRecResizeImg, PRENResizeImg
|
||||
from .randaugment import RandAugment
|
||||
from .copy_paste import CopyPaste
|
||||
from .ColorJitter import ColorJitter
|
||||
@@ -36,6 +37,9 @@ from .gen_table_mask import *
|
||||
|
||||
from .vqa import *
|
||||
|
||||
from .fce_aug import *
|
||||
from .fce_targets import FCENetTargets
|
||||
|
||||
|
||||
def transform(data, ops=None):
|
||||
""" transform """
|
||||
|
||||
@@ -0,0 +1,564 @@
|
||||
# copyright (c) 2022 PaddlePaddle Authors. All Rights Reserve.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
"""
|
||||
This code is refer from:
|
||||
https://github.com/open-mmlab/mmocr/blob/main/mmocr/datasets/pipelines/transforms.py
|
||||
"""
|
||||
import numpy as np
|
||||
from PIL import Image, ImageDraw
|
||||
import cv2
|
||||
from shapely.geometry import Polygon
|
||||
import math
|
||||
from ppocr.utils.poly_nms import poly_intersection
|
||||
|
||||
|
||||
class RandomScaling:
|
||||
def __init__(self, size=800, scale=(3. / 4, 5. / 2), **kwargs):
|
||||
"""Random scale the image while keeping aspect.
|
||||
|
||||
Args:
|
||||
size (int) : Base size before scaling.
|
||||
scale (tuple(float)) : The range of scaling.
|
||||
"""
|
||||
assert isinstance(size, int)
|
||||
assert isinstance(scale, float) or isinstance(scale, tuple)
|
||||
self.size = size
|
||||
self.scale = scale if isinstance(scale, tuple) \
|
||||
else (1 - scale, 1 + scale)
|
||||
|
||||
def __call__(self, data):
|
||||
image = data['image']
|
||||
text_polys = data['polys']
|
||||
h, w, _ = image.shape
|
||||
|
||||
aspect_ratio = np.random.uniform(min(self.scale), max(self.scale))
|
||||
scales = self.size * 1.0 / max(h, w) * aspect_ratio
|
||||
scales = np.array([scales, scales])
|
||||
out_size = (int(h * scales[1]), int(w * scales[0]))
|
||||
image = cv2.resize(image, out_size[::-1])
|
||||
|
||||
data['image'] = image
|
||||
text_polys[:, :, 0::2] = text_polys[:, :, 0::2] * scales[1]
|
||||
text_polys[:, :, 1::2] = text_polys[:, :, 1::2] * scales[0]
|
||||
data['polys'] = text_polys
|
||||
|
||||
return data
|
||||
|
||||
|
||||
class RandomCropFlip:
|
||||
def __init__(self,
|
||||
pad_ratio=0.1,
|
||||
crop_ratio=0.5,
|
||||
iter_num=1,
|
||||
min_area_ratio=0.2,
|
||||
**kwargs):
|
||||
"""Random crop and flip a patch of the image.
|
||||
|
||||
Args:
|
||||
crop_ratio (float): The ratio of cropping.
|
||||
iter_num (int): Number of operations.
|
||||
min_area_ratio (float): Minimal area ratio between cropped patch
|
||||
and original image.
|
||||
"""
|
||||
assert isinstance(crop_ratio, float)
|
||||
assert isinstance(iter_num, int)
|
||||
assert isinstance(min_area_ratio, float)
|
||||
|
||||
self.pad_ratio = pad_ratio
|
||||
self.epsilon = 1e-2
|
||||
self.crop_ratio = crop_ratio
|
||||
self.iter_num = iter_num
|
||||
self.min_area_ratio = min_area_ratio
|
||||
|
||||
def __call__(self, results):
|
||||
for i in range(self.iter_num):
|
||||
results = self.random_crop_flip(results)
|
||||
|
||||
return results
|
||||
|
||||
def random_crop_flip(self, results):
|
||||
image = results['image']
|
||||
polygons = results['polys']
|
||||
ignore_tags = results['ignore_tags']
|
||||
if len(polygons) == 0:
|
||||
return results
|
||||
|
||||
if np.random.random() >= self.crop_ratio:
|
||||
return results
|
||||
|
||||
h, w, _ = image.shape
|
||||
area = h * w
|
||||
pad_h = int(h * self.pad_ratio)
|
||||
pad_w = int(w * self.pad_ratio)
|
||||
h_axis, w_axis = self.generate_crop_target(image, polygons, pad_h,
|
||||
pad_w)
|
||||
if len(h_axis) == 0 or len(w_axis) == 0:
|
||||
return results
|
||||
|
||||
attempt = 0
|
||||
while attempt < 50:
|
||||
attempt += 1
|
||||
polys_keep = []
|
||||
polys_new = []
|
||||
ignore_tags_keep = []
|
||||
ignore_tags_new = []
|
||||
xx = np.random.choice(w_axis, size=2)
|
||||
xmin = np.min(xx) - pad_w
|
||||
xmax = np.max(xx) - pad_w
|
||||
xmin = np.clip(xmin, 0, w - 1)
|
||||
xmax = np.clip(xmax, 0, w - 1)
|
||||
yy = np.random.choice(h_axis, size=2)
|
||||
ymin = np.min(yy) - pad_h
|
||||
ymax = np.max(yy) - pad_h
|
||||
ymin = np.clip(ymin, 0, h - 1)
|
||||
ymax = np.clip(ymax, 0, h - 1)
|
||||
if (xmax - xmin) * (ymax - ymin) < area * self.min_area_ratio:
|
||||
# area too small
|
||||
continue
|
||||
|
||||
pts = np.stack([[xmin, xmax, xmax, xmin],
|
||||
[ymin, ymin, ymax, ymax]]).T.astype(np.int32)
|
||||
pp = Polygon(pts)
|
||||
fail_flag = False
|
||||
for polygon, ignore_tag in zip(polygons, ignore_tags):
|
||||
ppi = Polygon(polygon.reshape(-1, 2))
|
||||
ppiou, _ = poly_intersection(ppi, pp, buffer=0)
|
||||
if np.abs(ppiou - float(ppi.area)) > self.epsilon and \
|
||||
np.abs(ppiou) > self.epsilon:
|
||||
fail_flag = True
|
||||
break
|
||||
elif np.abs(ppiou - float(ppi.area)) < self.epsilon:
|
||||
polys_new.append(polygon)
|
||||
ignore_tags_new.append(ignore_tag)
|
||||
else:
|
||||
polys_keep.append(polygon)
|
||||
ignore_tags_keep.append(ignore_tag)
|
||||
|
||||
if fail_flag:
|
||||
continue
|
||||
else:
|
||||
break
|
||||
|
||||
cropped = image[ymin:ymax, xmin:xmax, :]
|
||||
select_type = np.random.randint(3)
|
||||
if select_type == 0:
|
||||
img = np.ascontiguousarray(cropped[:, ::-1])
|
||||
elif select_type == 1:
|
||||
img = np.ascontiguousarray(cropped[::-1, :])
|
||||
else:
|
||||
img = np.ascontiguousarray(cropped[::-1, ::-1])
|
||||
image[ymin:ymax, xmin:xmax, :] = img
|
||||
results['img'] = image
|
||||
|
||||
if len(polys_new) != 0:
|
||||
height, width, _ = cropped.shape
|
||||
if select_type == 0:
|
||||
for idx, polygon in enumerate(polys_new):
|
||||
poly = polygon.reshape(-1, 2)
|
||||
poly[:, 0] = width - poly[:, 0] + 2 * xmin
|
||||
polys_new[idx] = poly
|
||||
elif select_type == 1:
|
||||
for idx, polygon in enumerate(polys_new):
|
||||
poly = polygon.reshape(-1, 2)
|
||||
poly[:, 1] = height - poly[:, 1] + 2 * ymin
|
||||
polys_new[idx] = poly
|
||||
else:
|
||||
for idx, polygon in enumerate(polys_new):
|
||||
poly = polygon.reshape(-1, 2)
|
||||
poly[:, 0] = width - poly[:, 0] + 2 * xmin
|
||||
poly[:, 1] = height - poly[:, 1] + 2 * ymin
|
||||
polys_new[idx] = poly
|
||||
polygons = polys_keep + polys_new
|
||||
ignore_tags = ignore_tags_keep + ignore_tags_new
|
||||
results['polys'] = np.array(polygons)
|
||||
results['ignore_tags'] = ignore_tags
|
||||
|
||||
return results
|
||||
|
||||
def generate_crop_target(self, image, all_polys, pad_h, pad_w):
|
||||
"""Generate crop target and make sure not to crop the polygon
|
||||
instances.
|
||||
|
||||
Args:
|
||||
image (ndarray): The image waited to be crop.
|
||||
all_polys (list[list[ndarray]]): All polygons including ground
|
||||
truth polygons and ground truth ignored polygons.
|
||||
pad_h (int): Padding length of height.
|
||||
pad_w (int): Padding length of width.
|
||||
Returns:
|
||||
h_axis (ndarray): Vertical cropping range.
|
||||
w_axis (ndarray): Horizontal cropping range.
|
||||
"""
|
||||
h, w, _ = image.shape
|
||||
h_array = np.zeros((h + pad_h * 2), dtype=np.int32)
|
||||
w_array = np.zeros((w + pad_w * 2), dtype=np.int32)
|
||||
|
||||
text_polys = []
|
||||
for polygon in all_polys:
|
||||
rect = cv2.minAreaRect(polygon.astype(np.int32).reshape(-1, 2))
|
||||
box = cv2.boxPoints(rect)
|
||||
box = np.int0(box)
|
||||
text_polys.append([box[0], box[1], box[2], box[3]])
|
||||
|
||||
polys = np.array(text_polys, dtype=np.int32)
|
||||
for poly in polys:
|
||||
poly = np.round(poly, decimals=0).astype(np.int32)
|
||||
minx = np.min(poly[:, 0])
|
||||
maxx = np.max(poly[:, 0])
|
||||
w_array[minx + pad_w:maxx + pad_w] = 1
|
||||
miny = np.min(poly[:, 1])
|
||||
maxy = np.max(poly[:, 1])
|
||||
h_array[miny + pad_h:maxy + pad_h] = 1
|
||||
|
||||
h_axis = np.where(h_array == 0)[0]
|
||||
w_axis = np.where(w_array == 0)[0]
|
||||
return h_axis, w_axis
|
||||
|
||||
|
||||
class RandomCropPolyInstances:
|
||||
"""Randomly crop images and make sure to contain at least one intact
|
||||
instance."""
|
||||
|
||||
def __init__(self, crop_ratio=5.0 / 8.0, min_side_ratio=0.4, **kwargs):
|
||||
super().__init__()
|
||||
self.crop_ratio = crop_ratio
|
||||
self.min_side_ratio = min_side_ratio
|
||||
|
||||
def sample_valid_start_end(self, valid_array, min_len, max_start, min_end):
|
||||
|
||||
assert isinstance(min_len, int)
|
||||
assert len(valid_array) > min_len
|
||||
|
||||
start_array = valid_array.copy()
|
||||
max_start = min(len(start_array) - min_len, max_start)
|
||||
start_array[max_start:] = 0
|
||||
start_array[0] = 1
|
||||
diff_array = np.hstack([0, start_array]) - np.hstack([start_array, 0])
|
||||
region_starts = np.where(diff_array < 0)[0]
|
||||
region_ends = np.where(diff_array > 0)[0]
|
||||
region_ind = np.random.randint(0, len(region_starts))
|
||||
start = np.random.randint(region_starts[region_ind],
|
||||
region_ends[region_ind])
|
||||
|
||||
end_array = valid_array.copy()
|
||||
min_end = max(start + min_len, min_end)
|
||||
end_array[:min_end] = 0
|
||||
end_array[-1] = 1
|
||||
diff_array = np.hstack([0, end_array]) - np.hstack([end_array, 0])
|
||||
region_starts = np.where(diff_array < 0)[0]
|
||||
region_ends = np.where(diff_array > 0)[0]
|
||||
region_ind = np.random.randint(0, len(region_starts))
|
||||
end = np.random.randint(region_starts[region_ind],
|
||||
region_ends[region_ind])
|
||||
return start, end
|
||||
|
||||
def sample_crop_box(self, img_size, results):
|
||||
"""Generate crop box and make sure not to crop the polygon instances.
|
||||
|
||||
Args:
|
||||
img_size (tuple(int)): The image size (h, w).
|
||||
results (dict): The results dict.
|
||||
"""
|
||||
|
||||
assert isinstance(img_size, tuple)
|
||||
h, w = img_size[:2]
|
||||
|
||||
key_masks = results['polys']
|
||||
|
||||
x_valid_array = np.ones(w, dtype=np.int32)
|
||||
y_valid_array = np.ones(h, dtype=np.int32)
|
||||
|
||||
selected_mask = key_masks[np.random.randint(0, len(key_masks))]
|
||||
selected_mask = selected_mask.reshape((-1, 2)).astype(np.int32)
|
||||
max_x_start = max(np.min(selected_mask[:, 0]) - 2, 0)
|
||||
min_x_end = min(np.max(selected_mask[:, 0]) + 3, w - 1)
|
||||
max_y_start = max(np.min(selected_mask[:, 1]) - 2, 0)
|
||||
min_y_end = min(np.max(selected_mask[:, 1]) + 3, h - 1)
|
||||
|
||||
for mask in key_masks:
|
||||
mask = mask.reshape((-1, 2)).astype(np.int32)
|
||||
clip_x = np.clip(mask[:, 0], 0, w - 1)
|
||||
clip_y = np.clip(mask[:, 1], 0, h - 1)
|
||||
min_x, max_x = np.min(clip_x), np.max(clip_x)
|
||||
min_y, max_y = np.min(clip_y), np.max(clip_y)
|
||||
|
||||
x_valid_array[min_x - 2:max_x + 3] = 0
|
||||
y_valid_array[min_y - 2:max_y + 3] = 0
|
||||
|
||||
min_w = int(w * self.min_side_ratio)
|
||||
min_h = int(h * self.min_side_ratio)
|
||||
|
||||
x1, x2 = self.sample_valid_start_end(x_valid_array, min_w, max_x_start,
|
||||
min_x_end)
|
||||
y1, y2 = self.sample_valid_start_end(y_valid_array, min_h, max_y_start,
|
||||
min_y_end)
|
||||
|
||||
return np.array([x1, y1, x2, y2])
|
||||
|
||||
def crop_img(self, img, bbox):
|
||||
assert img.ndim == 3
|
||||
h, w, _ = img.shape
|
||||
assert 0 <= bbox[1] < bbox[3] <= h
|
||||
assert 0 <= bbox[0] < bbox[2] <= w
|
||||
return img[bbox[1]:bbox[3], bbox[0]:bbox[2]]
|
||||
|
||||
def __call__(self, results):
|
||||
image = results['image']
|
||||
polygons = results['polys']
|
||||
ignore_tags = results['ignore_tags']
|
||||
if len(polygons) < 1:
|
||||
return results
|
||||
|
||||
if np.random.random_sample() < self.crop_ratio:
|
||||
|
||||
crop_box = self.sample_crop_box(image.shape, results)
|
||||
img = self.crop_img(image, crop_box)
|
||||
results['image'] = img
|
||||
# crop and filter masks
|
||||
x1, y1, x2, y2 = crop_box
|
||||
w = max(x2 - x1, 1)
|
||||
h = max(y2 - y1, 1)
|
||||
polygons[:, :, 0::2] = polygons[:, :, 0::2] - x1
|
||||
polygons[:, :, 1::2] = polygons[:, :, 1::2] - y1
|
||||
|
||||
valid_masks_list = []
|
||||
valid_tags_list = []
|
||||
for ind, polygon in enumerate(polygons):
|
||||
if (polygon[:, ::2] > -4).all() and (
|
||||
polygon[:, ::2] < w + 4).all() and (
|
||||
polygon[:, 1::2] > -4).all() and (
|
||||
polygon[:, 1::2] < h + 4).all():
|
||||
polygon[:, ::2] = np.clip(polygon[:, ::2], 0, w)
|
||||
polygon[:, 1::2] = np.clip(polygon[:, 1::2], 0, h)
|
||||
valid_masks_list.append(polygon)
|
||||
valid_tags_list.append(ignore_tags[ind])
|
||||
|
||||
results['polys'] = np.array(valid_masks_list)
|
||||
results['ignore_tags'] = valid_tags_list
|
||||
|
||||
return results
|
||||
|
||||
def __repr__(self):
|
||||
repr_str = self.__class__.__name__
|
||||
return repr_str
|
||||
|
||||
|
||||
class RandomRotatePolyInstances:
|
||||
def __init__(self,
|
||||
rotate_ratio=0.5,
|
||||
max_angle=10,
|
||||
pad_with_fixed_color=False,
|
||||
pad_value=(0, 0, 0),
|
||||
**kwargs):
|
||||
"""Randomly rotate images and polygon masks.
|
||||
|
||||
Args:
|
||||
rotate_ratio (float): The ratio of samples to operate rotation.
|
||||
max_angle (int): The maximum rotation angle.
|
||||
pad_with_fixed_color (bool): The flag for whether to pad rotated
|
||||
image with fixed value. If set to False, the rotated image will
|
||||
be padded onto cropped image.
|
||||
pad_value (tuple(int)): The color value for padding rotated image.
|
||||
"""
|
||||
self.rotate_ratio = rotate_ratio
|
||||
self.max_angle = max_angle
|
||||
self.pad_with_fixed_color = pad_with_fixed_color
|
||||
self.pad_value = pad_value
|
||||
|
||||
def rotate(self, center, points, theta, center_shift=(0, 0)):
|
||||
# rotate points.
|
||||
(center_x, center_y) = center
|
||||
center_y = -center_y
|
||||
x, y = points[:, ::2], points[:, 1::2]
|
||||
y = -y
|
||||
|
||||
theta = theta / 180 * math.pi
|
||||
cos = math.cos(theta)
|
||||
sin = math.sin(theta)
|
||||
|
||||
x = (x - center_x)
|
||||
y = (y - center_y)
|
||||
|
||||
_x = center_x + x * cos - y * sin + center_shift[0]
|
||||
_y = -(center_y + x * sin + y * cos) + center_shift[1]
|
||||
|
||||
points[:, ::2], points[:, 1::2] = _x, _y
|
||||
return points
|
||||
|
||||
def cal_canvas_size(self, ori_size, degree):
|
||||
assert isinstance(ori_size, tuple)
|
||||
angle = degree * math.pi / 180.0
|
||||
h, w = ori_size[:2]
|
||||
|
||||
cos = math.cos(angle)
|
||||
sin = math.sin(angle)
|
||||
canvas_h = int(w * math.fabs(sin) + h * math.fabs(cos))
|
||||
canvas_w = int(w * math.fabs(cos) + h * math.fabs(sin))
|
||||
|
||||
canvas_size = (canvas_h, canvas_w)
|
||||
return canvas_size
|
||||
|
||||
def sample_angle(self, max_angle):
|
||||
angle = np.random.random_sample() * 2 * max_angle - max_angle
|
||||
return angle
|
||||
|
||||
def rotate_img(self, img, angle, canvas_size):
|
||||
h, w = img.shape[:2]
|
||||
rotation_matrix = cv2.getRotationMatrix2D((w / 2, h / 2), angle, 1)
|
||||
rotation_matrix[0, 2] += int((canvas_size[1] - w) / 2)
|
||||
rotation_matrix[1, 2] += int((canvas_size[0] - h) / 2)
|
||||
|
||||
if self.pad_with_fixed_color:
|
||||
target_img = cv2.warpAffine(
|
||||
img,
|
||||
rotation_matrix, (canvas_size[1], canvas_size[0]),
|
||||
flags=cv2.INTER_NEAREST,
|
||||
borderValue=self.pad_value)
|
||||
else:
|
||||
mask = np.zeros_like(img)
|
||||
(h_ind, w_ind) = (np.random.randint(0, h * 7 // 8),
|
||||
np.random.randint(0, w * 7 // 8))
|
||||
img_cut = img[h_ind:(h_ind + h // 9), w_ind:(w_ind + w // 9)]
|
||||
img_cut = cv2.resize(img_cut, (canvas_size[1], canvas_size[0]))
|
||||
|
||||
mask = cv2.warpAffine(
|
||||
mask,
|
||||
rotation_matrix, (canvas_size[1], canvas_size[0]),
|
||||
borderValue=[1, 1, 1])
|
||||
target_img = cv2.warpAffine(
|
||||
img,
|
||||
rotation_matrix, (canvas_size[1], canvas_size[0]),
|
||||
borderValue=[0, 0, 0])
|
||||
target_img = target_img + img_cut * mask
|
||||
|
||||
return target_img
|
||||
|
||||
def __call__(self, results):
|
||||
if np.random.random_sample() < self.rotate_ratio:
|
||||
image = results['image']
|
||||
polygons = results['polys']
|
||||
h, w = image.shape[:2]
|
||||
|
||||
angle = self.sample_angle(self.max_angle)
|
||||
canvas_size = self.cal_canvas_size((h, w), angle)
|
||||
center_shift = (int((canvas_size[1] - w) / 2), int(
|
||||
(canvas_size[0] - h) / 2))
|
||||
image = self.rotate_img(image, angle, canvas_size)
|
||||
results['image'] = image
|
||||
# rotate polygons
|
||||
rotated_masks = []
|
||||
for mask in polygons:
|
||||
rotated_mask = self.rotate((w / 2, h / 2), mask, angle,
|
||||
center_shift)
|
||||
rotated_masks.append(rotated_mask)
|
||||
results['polys'] = np.array(rotated_masks)
|
||||
|
||||
return results
|
||||
|
||||
def __repr__(self):
|
||||
repr_str = self.__class__.__name__
|
||||
return repr_str
|
||||
|
||||
|
||||
class SquareResizePad:
|
||||
def __init__(self,
|
||||
target_size,
|
||||
pad_ratio=0.6,
|
||||
pad_with_fixed_color=False,
|
||||
pad_value=(0, 0, 0),
|
||||
**kwargs):
|
||||
"""Resize or pad images to be square shape.
|
||||
|
||||
Args:
|
||||
target_size (int): The target size of square shaped image.
|
||||
pad_with_fixed_color (bool): The flag for whether to pad rotated
|
||||
image with fixed value. If set to False, the rescales image will
|
||||
be padded onto cropped image.
|
||||
pad_value (tuple(int)): The color value for padding rotated image.
|
||||
"""
|
||||
assert isinstance(target_size, int)
|
||||
assert isinstance(pad_ratio, float)
|
||||
assert isinstance(pad_with_fixed_color, bool)
|
||||
assert isinstance(pad_value, tuple)
|
||||
|
||||
self.target_size = target_size
|
||||
self.pad_ratio = pad_ratio
|
||||
self.pad_with_fixed_color = pad_with_fixed_color
|
||||
self.pad_value = pad_value
|
||||
|
||||
def resize_img(self, img, keep_ratio=True):
|
||||
h, w, _ = img.shape
|
||||
if keep_ratio:
|
||||
t_h = self.target_size if h >= w else int(h * self.target_size / w)
|
||||
t_w = self.target_size if h <= w else int(w * self.target_size / h)
|
||||
else:
|
||||
t_h = t_w = self.target_size
|
||||
img = cv2.resize(img, (t_w, t_h))
|
||||
return img, (t_h, t_w)
|
||||
|
||||
def square_pad(self, img):
|
||||
h, w = img.shape[:2]
|
||||
if h == w:
|
||||
return img, (0, 0)
|
||||
pad_size = max(h, w)
|
||||
if self.pad_with_fixed_color:
|
||||
expand_img = np.ones((pad_size, pad_size, 3), dtype=np.uint8)
|
||||
expand_img[:] = self.pad_value
|
||||
else:
|
||||
(h_ind, w_ind) = (np.random.randint(0, h * 7 // 8),
|
||||
np.random.randint(0, w * 7 // 8))
|
||||
img_cut = img[h_ind:(h_ind + h // 9), w_ind:(w_ind + w // 9)]
|
||||
expand_img = cv2.resize(img_cut, (pad_size, pad_size))
|
||||
if h > w:
|
||||
y0, x0 = 0, (h - w) // 2
|
||||
else:
|
||||
y0, x0 = (w - h) // 2, 0
|
||||
expand_img[y0:y0 + h, x0:x0 + w] = img
|
||||
offset = (x0, y0)
|
||||
|
||||
return expand_img, offset
|
||||
|
||||
def square_pad_mask(self, points, offset):
|
||||
x0, y0 = offset
|
||||
pad_points = points.copy()
|
||||
pad_points[::2] = pad_points[::2] + x0
|
||||
pad_points[1::2] = pad_points[1::2] + y0
|
||||
return pad_points
|
||||
|
||||
def __call__(self, results):
|
||||
image = results['image']
|
||||
polygons = results['polys']
|
||||
h, w = image.shape[:2]
|
||||
|
||||
if np.random.random_sample() < self.pad_ratio:
|
||||
image, out_size = self.resize_img(image, keep_ratio=True)
|
||||
image, offset = self.square_pad(image)
|
||||
else:
|
||||
image, out_size = self.resize_img(image, keep_ratio=False)
|
||||
offset = (0, 0)
|
||||
results['image'] = image
|
||||
try:
|
||||
polygons[:, :, 0::2] = polygons[:, :, 0::2] * out_size[
|
||||
1] / w + offset[0]
|
||||
polygons[:, :, 1::2] = polygons[:, :, 1::2] * out_size[
|
||||
0] / h + offset[1]
|
||||
except:
|
||||
pass
|
||||
results['polys'] = polygons
|
||||
|
||||
return results
|
||||
|
||||
def __repr__(self):
|
||||
repr_str = self.__class__.__name__
|
||||
return repr_str
|
||||
@@ -0,0 +1,658 @@
|
||||
# copyright (c) 2022 PaddlePaddle Authors. All Rights Reserve.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
"""
|
||||
This code is refer from:
|
||||
https://github.com/open-mmlab/mmocr/blob/main/mmocr/datasets/pipelines/textdet_targets/fcenet_targets.py
|
||||
"""
|
||||
|
||||
import cv2
|
||||
import numpy as np
|
||||
from numpy.fft import fft
|
||||
from numpy.linalg import norm
|
||||
import sys
|
||||
|
||||
|
||||
class FCENetTargets:
|
||||
"""Generate the ground truth targets of FCENet: Fourier Contour Embedding
|
||||
for Arbitrary-Shaped Text Detection.
|
||||
|
||||
[https://arxiv.org/abs/2104.10442]
|
||||
|
||||
Args:
|
||||
fourier_degree (int): The maximum Fourier transform degree k.
|
||||
resample_step (float): The step size for resampling the text center
|
||||
line (TCL). It's better not to exceed half of the minimum width.
|
||||
center_region_shrink_ratio (float): The shrink ratio of text center
|
||||
region.
|
||||
level_size_divisors (tuple(int)): The downsample ratio on each level.
|
||||
level_proportion_range (tuple(tuple(int))): The range of text sizes
|
||||
assigned to each level.
|
||||
"""
|
||||
|
||||
def __init__(self,
|
||||
fourier_degree=5,
|
||||
resample_step=4.0,
|
||||
center_region_shrink_ratio=0.3,
|
||||
level_size_divisors=(8, 16, 32),
|
||||
level_proportion_range=((0, 0.25), (0.2, 0.65), (0.55, 1.0)),
|
||||
orientation_thr=2.0,
|
||||
**kwargs):
|
||||
|
||||
super().__init__()
|
||||
assert isinstance(level_size_divisors, tuple)
|
||||
assert isinstance(level_proportion_range, tuple)
|
||||
assert len(level_size_divisors) == len(level_proportion_range)
|
||||
self.fourier_degree = fourier_degree
|
||||
self.resample_step = resample_step
|
||||
self.center_region_shrink_ratio = center_region_shrink_ratio
|
||||
self.level_size_divisors = level_size_divisors
|
||||
self.level_proportion_range = level_proportion_range
|
||||
|
||||
self.orientation_thr = orientation_thr
|
||||
|
||||
def vector_angle(self, vec1, vec2):
|
||||
if vec1.ndim > 1:
|
||||
unit_vec1 = vec1 / (norm(vec1, axis=-1) + 1e-8).reshape((-1, 1))
|
||||
else:
|
||||
unit_vec1 = vec1 / (norm(vec1, axis=-1) + 1e-8)
|
||||
if vec2.ndim > 1:
|
||||
unit_vec2 = vec2 / (norm(vec2, axis=-1) + 1e-8).reshape((-1, 1))
|
||||
else:
|
||||
unit_vec2 = vec2 / (norm(vec2, axis=-1) + 1e-8)
|
||||
return np.arccos(
|
||||
np.clip(
|
||||
np.sum(unit_vec1 * unit_vec2, axis=-1), -1.0, 1.0))
|
||||
|
||||
def resample_line(self, line, n):
|
||||
"""Resample n points on a line.
|
||||
|
||||
Args:
|
||||
line (ndarray): The points composing a line.
|
||||
n (int): The resampled points number.
|
||||
|
||||
Returns:
|
||||
resampled_line (ndarray): The points composing the resampled line.
|
||||
"""
|
||||
|
||||
assert line.ndim == 2
|
||||
assert line.shape[0] >= 2
|
||||
assert line.shape[1] == 2
|
||||
assert isinstance(n, int)
|
||||
assert n > 0
|
||||
|
||||
length_list = [
|
||||
norm(line[i + 1] - line[i]) for i in range(len(line) - 1)
|
||||
]
|
||||
total_length = sum(length_list)
|
||||
length_cumsum = np.cumsum([0.0] + length_list)
|
||||
delta_length = total_length / (float(n) + 1e-8)
|
||||
|
||||
current_edge_ind = 0
|
||||
resampled_line = [line[0]]
|
||||
|
||||
for i in range(1, n):
|
||||
current_line_len = i * delta_length
|
||||
|
||||
while current_line_len >= length_cumsum[current_edge_ind + 1]:
|
||||
current_edge_ind += 1
|
||||
current_edge_end_shift = current_line_len - length_cumsum[
|
||||
current_edge_ind]
|
||||
end_shift_ratio = current_edge_end_shift / length_list[
|
||||
current_edge_ind]
|
||||
current_point = line[current_edge_ind] + (line[current_edge_ind + 1]
|
||||
- line[current_edge_ind]
|
||||
) * end_shift_ratio
|
||||
resampled_line.append(current_point)
|
||||
|
||||
resampled_line.append(line[-1])
|
||||
resampled_line = np.array(resampled_line)
|
||||
|
||||
return resampled_line
|
||||
|
||||
def reorder_poly_edge(self, points):
|
||||
"""Get the respective points composing head edge, tail edge, top
|
||||
sideline and bottom sideline.
|
||||
|
||||
Args:
|
||||
points (ndarray): The points composing a text polygon.
|
||||
|
||||
Returns:
|
||||
head_edge (ndarray): The two points composing the head edge of text
|
||||
polygon.
|
||||
tail_edge (ndarray): The two points composing the tail edge of text
|
||||
polygon.
|
||||
top_sideline (ndarray): The points composing top curved sideline of
|
||||
text polygon.
|
||||
bot_sideline (ndarray): The points composing bottom curved sideline
|
||||
of text polygon.
|
||||
"""
|
||||
|
||||
assert points.ndim == 2
|
||||
assert points.shape[0] >= 4
|
||||
assert points.shape[1] == 2
|
||||
|
||||
head_inds, tail_inds = self.find_head_tail(points, self.orientation_thr)
|
||||
head_edge, tail_edge = points[head_inds], points[tail_inds]
|
||||
|
||||
pad_points = np.vstack([points, points])
|
||||
if tail_inds[1] < 1:
|
||||
tail_inds[1] = len(points)
|
||||
sideline1 = pad_points[head_inds[1]:tail_inds[1]]
|
||||
sideline2 = pad_points[tail_inds[1]:(head_inds[1] + len(points))]
|
||||
sideline_mean_shift = np.mean(
|
||||
sideline1, axis=0) - np.mean(
|
||||
sideline2, axis=0)
|
||||
|
||||
if sideline_mean_shift[1] > 0:
|
||||
top_sideline, bot_sideline = sideline2, sideline1
|
||||
else:
|
||||
top_sideline, bot_sideline = sideline1, sideline2
|
||||
|
||||
return head_edge, tail_edge, top_sideline, bot_sideline
|
||||
|
||||
def find_head_tail(self, points, orientation_thr):
|
||||
"""Find the head edge and tail edge of a text polygon.
|
||||
|
||||
Args:
|
||||
points (ndarray): The points composing a text polygon.
|
||||
orientation_thr (float): The threshold for distinguishing between
|
||||
head edge and tail edge among the horizontal and vertical edges
|
||||
of a quadrangle.
|
||||
|
||||
Returns:
|
||||
head_inds (list): The indexes of two points composing head edge.
|
||||
tail_inds (list): The indexes of two points composing tail edge.
|
||||
"""
|
||||
|
||||
assert points.ndim == 2
|
||||
assert points.shape[0] >= 4
|
||||
assert points.shape[1] == 2
|
||||
assert isinstance(orientation_thr, float)
|
||||
|
||||
if len(points) > 4:
|
||||
pad_points = np.vstack([points, points[0]])
|
||||
edge_vec = pad_points[1:] - pad_points[:-1]
|
||||
|
||||
theta_sum = []
|
||||
adjacent_vec_theta = []
|
||||
for i, edge_vec1 in enumerate(edge_vec):
|
||||
adjacent_ind = [x % len(edge_vec) for x in [i - 1, i + 1]]
|
||||
adjacent_edge_vec = edge_vec[adjacent_ind]
|
||||
temp_theta_sum = np.sum(
|
||||
self.vector_angle(edge_vec1, adjacent_edge_vec))
|
||||
temp_adjacent_theta = self.vector_angle(adjacent_edge_vec[0],
|
||||
adjacent_edge_vec[1])
|
||||
theta_sum.append(temp_theta_sum)
|
||||
adjacent_vec_theta.append(temp_adjacent_theta)
|
||||
theta_sum_score = np.array(theta_sum) / np.pi
|
||||
adjacent_theta_score = np.array(adjacent_vec_theta) / np.pi
|
||||
poly_center = np.mean(points, axis=0)
|
||||
edge_dist = np.maximum(
|
||||
norm(
|
||||
pad_points[1:] - poly_center, axis=-1),
|
||||
norm(
|
||||
pad_points[:-1] - poly_center, axis=-1))
|
||||
dist_score = edge_dist / np.max(edge_dist)
|
||||
position_score = np.zeros(len(edge_vec))
|
||||
score = 0.5 * theta_sum_score + 0.15 * adjacent_theta_score
|
||||
score += 0.35 * dist_score
|
||||
if len(points) % 2 == 0:
|
||||
position_score[(len(score) // 2 - 1)] += 1
|
||||
position_score[-1] += 1
|
||||
score += 0.1 * position_score
|
||||
pad_score = np.concatenate([score, score])
|
||||
score_matrix = np.zeros((len(score), len(score) - 3))
|
||||
x = np.arange(len(score) - 3) / float(len(score) - 4)
|
||||
gaussian = 1. / (np.sqrt(2. * np.pi) * 0.5) * np.exp(-np.power(
|
||||
(x - 0.5) / 0.5, 2.) / 2)
|
||||
gaussian = gaussian / np.max(gaussian)
|
||||
for i in range(len(score)):
|
||||
score_matrix[i, :] = score[i] + pad_score[(i + 2):(i + len(
|
||||
score) - 1)] * gaussian * 0.3
|
||||
|
||||
head_start, tail_increment = np.unravel_index(score_matrix.argmax(),
|
||||
score_matrix.shape)
|
||||
tail_start = (head_start + tail_increment + 2) % len(points)
|
||||
head_end = (head_start + 1) % len(points)
|
||||
tail_end = (tail_start + 1) % len(points)
|
||||
|
||||
if head_end > tail_end:
|
||||
head_start, tail_start = tail_start, head_start
|
||||
head_end, tail_end = tail_end, head_end
|
||||
head_inds = [head_start, head_end]
|
||||
tail_inds = [tail_start, tail_end]
|
||||
else:
|
||||
if self.vector_slope(points[1] - points[0]) + self.vector_slope(
|
||||
points[3] - points[2]) < self.vector_slope(points[
|
||||
2] - points[1]) + self.vector_slope(points[0] - points[
|
||||
3]):
|
||||
horizontal_edge_inds = [[0, 1], [2, 3]]
|
||||
vertical_edge_inds = [[3, 0], [1, 2]]
|
||||
else:
|
||||
horizontal_edge_inds = [[3, 0], [1, 2]]
|
||||
vertical_edge_inds = [[0, 1], [2, 3]]
|
||||
|
||||
vertical_len_sum = norm(points[vertical_edge_inds[0][0]] - points[
|
||||
vertical_edge_inds[0][1]]) + norm(points[vertical_edge_inds[1][
|
||||
0]] - points[vertical_edge_inds[1][1]])
|
||||
horizontal_len_sum = norm(points[horizontal_edge_inds[0][
|
||||
0]] - points[horizontal_edge_inds[0][1]]) + norm(points[
|
||||
horizontal_edge_inds[1][0]] - points[horizontal_edge_inds[1]
|
||||
[1]])
|
||||
|
||||
if vertical_len_sum > horizontal_len_sum * orientation_thr:
|
||||
head_inds = horizontal_edge_inds[0]
|
||||
tail_inds = horizontal_edge_inds[1]
|
||||
else:
|
||||
head_inds = vertical_edge_inds[0]
|
||||
tail_inds = vertical_edge_inds[1]
|
||||
|
||||
return head_inds, tail_inds
|
||||
|
||||
def resample_sidelines(self, sideline1, sideline2, resample_step):
|
||||
"""Resample two sidelines to be of the same points number according to
|
||||
step size.
|
||||
|
||||
Args:
|
||||
sideline1 (ndarray): The points composing a sideline of a text
|
||||
polygon.
|
||||
sideline2 (ndarray): The points composing another sideline of a
|
||||
text polygon.
|
||||
resample_step (float): The resampled step size.
|
||||
|
||||
Returns:
|
||||
resampled_line1 (ndarray): The resampled line 1.
|
||||
resampled_line2 (ndarray): The resampled line 2.
|
||||
"""
|
||||
|
||||
assert sideline1.ndim == sideline2.ndim == 2
|
||||
assert sideline1.shape[1] == sideline2.shape[1] == 2
|
||||
assert sideline1.shape[0] >= 2
|
||||
assert sideline2.shape[0] >= 2
|
||||
assert isinstance(resample_step, float)
|
||||
|
||||
length1 = sum([
|
||||
norm(sideline1[i + 1] - sideline1[i])
|
||||
for i in range(len(sideline1) - 1)
|
||||
])
|
||||
length2 = sum([
|
||||
norm(sideline2[i + 1] - sideline2[i])
|
||||
for i in range(len(sideline2) - 1)
|
||||
])
|
||||
|
||||
total_length = (length1 + length2) / 2
|
||||
resample_point_num = max(int(float(total_length) / resample_step), 1)
|
||||
|
||||
resampled_line1 = self.resample_line(sideline1, resample_point_num)
|
||||
resampled_line2 = self.resample_line(sideline2, resample_point_num)
|
||||
|
||||
return resampled_line1, resampled_line2
|
||||
|
||||
def generate_center_region_mask(self, img_size, text_polys):
|
||||
"""Generate text center region mask.
|
||||
|
||||
Args:
|
||||
img_size (tuple): The image size of (height, width).
|
||||
text_polys (list[list[ndarray]]): The list of text polygons.
|
||||
|
||||
Returns:
|
||||
center_region_mask (ndarray): The text center region mask.
|
||||
"""
|
||||
|
||||
assert isinstance(img_size, tuple)
|
||||
# assert check_argument.is_2dlist(text_polys)
|
||||
|
||||
h, w = img_size
|
||||
|
||||
center_region_mask = np.zeros((h, w), np.uint8)
|
||||
|
||||
center_region_boxes = []
|
||||
for poly in text_polys:
|
||||
# assert len(poly) == 1
|
||||
polygon_points = poly.reshape(-1, 2)
|
||||
_, _, top_line, bot_line = self.reorder_poly_edge(polygon_points)
|
||||
resampled_top_line, resampled_bot_line = self.resample_sidelines(
|
||||
top_line, bot_line, self.resample_step)
|
||||
resampled_bot_line = resampled_bot_line[::-1]
|
||||
center_line = (resampled_top_line + resampled_bot_line) / 2
|
||||
|
||||
line_head_shrink_len = norm(resampled_top_line[0] -
|
||||
resampled_bot_line[0]) / 4.0
|
||||
line_tail_shrink_len = norm(resampled_top_line[-1] -
|
||||
resampled_bot_line[-1]) / 4.0
|
||||
head_shrink_num = int(line_head_shrink_len // self.resample_step)
|
||||
tail_shrink_num = int(line_tail_shrink_len // self.resample_step)
|
||||
if len(center_line) > head_shrink_num + tail_shrink_num + 2:
|
||||
center_line = center_line[head_shrink_num:len(center_line) -
|
||||
tail_shrink_num]
|
||||
resampled_top_line = resampled_top_line[head_shrink_num:len(
|
||||
resampled_top_line) - tail_shrink_num]
|
||||
resampled_bot_line = resampled_bot_line[head_shrink_num:len(
|
||||
resampled_bot_line) - tail_shrink_num]
|
||||
|
||||
for i in range(0, len(center_line) - 1):
|
||||
tl = center_line[i] + (resampled_top_line[i] - center_line[i]
|
||||
) * self.center_region_shrink_ratio
|
||||
tr = center_line[i + 1] + (resampled_top_line[i + 1] -
|
||||
center_line[i + 1]
|
||||
) * self.center_region_shrink_ratio
|
||||
br = center_line[i + 1] + (resampled_bot_line[i + 1] -
|
||||
center_line[i + 1]
|
||||
) * self.center_region_shrink_ratio
|
||||
bl = center_line[i] + (resampled_bot_line[i] - center_line[i]
|
||||
) * self.center_region_shrink_ratio
|
||||
current_center_box = np.vstack([tl, tr, br,
|
||||
bl]).astype(np.int32)
|
||||
center_region_boxes.append(current_center_box)
|
||||
|
||||
cv2.fillPoly(center_region_mask, center_region_boxes, 1)
|
||||
return center_region_mask
|
||||
|
||||
def resample_polygon(self, polygon, n=400):
|
||||
"""Resample one polygon with n points on its boundary.
|
||||
|
||||
Args:
|
||||
polygon (list[float]): The input polygon.
|
||||
n (int): The number of resampled points.
|
||||
Returns:
|
||||
resampled_polygon (list[float]): The resampled polygon.
|
||||
"""
|
||||
length = []
|
||||
|
||||
for i in range(len(polygon)):
|
||||
p1 = polygon[i]
|
||||
if i == len(polygon) - 1:
|
||||
p2 = polygon[0]
|
||||
else:
|
||||
p2 = polygon[i + 1]
|
||||
length.append(((p1[0] - p2[0])**2 + (p1[1] - p2[1])**2)**0.5)
|
||||
|
||||
total_length = sum(length)
|
||||
n_on_each_line = (np.array(length) / (total_length + 1e-8)) * n
|
||||
n_on_each_line = n_on_each_line.astype(np.int32)
|
||||
new_polygon = []
|
||||
|
||||
for i in range(len(polygon)):
|
||||
num = n_on_each_line[i]
|
||||
p1 = polygon[i]
|
||||
if i == len(polygon) - 1:
|
||||
p2 = polygon[0]
|
||||
else:
|
||||
p2 = polygon[i + 1]
|
||||
|
||||
if num == 0:
|
||||
continue
|
||||
|
||||
dxdy = (p2 - p1) / num
|
||||
for j in range(num):
|
||||
point = p1 + dxdy * j
|
||||
new_polygon.append(point)
|
||||
|
||||
return np.array(new_polygon)
|
||||
|
||||
def normalize_polygon(self, polygon):
|
||||
"""Normalize one polygon so that its start point is at right most.
|
||||
|
||||
Args:
|
||||
polygon (list[float]): The origin polygon.
|
||||
Returns:
|
||||
new_polygon (lost[float]): The polygon with start point at right.
|
||||
"""
|
||||
temp_polygon = polygon - polygon.mean(axis=0)
|
||||
x = np.abs(temp_polygon[:, 0])
|
||||
y = temp_polygon[:, 1]
|
||||
index_x = np.argsort(x)
|
||||
index_y = np.argmin(y[index_x[:8]])
|
||||
index = index_x[index_y]
|
||||
new_polygon = np.concatenate([polygon[index:], polygon[:index]])
|
||||
return new_polygon
|
||||
|
||||
def poly2fourier(self, polygon, fourier_degree):
|
||||
"""Perform Fourier transformation to generate Fourier coefficients ck
|
||||
from polygon.
|
||||
|
||||
Args:
|
||||
polygon (ndarray): An input polygon.
|
||||
fourier_degree (int): The maximum Fourier degree K.
|
||||
Returns:
|
||||
c (ndarray(complex)): Fourier coefficients.
|
||||
"""
|
||||
points = polygon[:, 0] + polygon[:, 1] * 1j
|
||||
c_fft = fft(points) / len(points)
|
||||
c = np.hstack((c_fft[-fourier_degree:], c_fft[:fourier_degree + 1]))
|
||||
return c
|
||||
|
||||
def clockwise(self, c, fourier_degree):
|
||||
"""Make sure the polygon reconstructed from Fourier coefficients c in
|
||||
the clockwise direction.
|
||||
|
||||
Args:
|
||||
polygon (list[float]): The origin polygon.
|
||||
Returns:
|
||||
new_polygon (lost[float]): The polygon in clockwise point order.
|
||||
"""
|
||||
if np.abs(c[fourier_degree + 1]) > np.abs(c[fourier_degree - 1]):
|
||||
return c
|
||||
elif np.abs(c[fourier_degree + 1]) < np.abs(c[fourier_degree - 1]):
|
||||
return c[::-1]
|
||||
else:
|
||||
if np.abs(c[fourier_degree + 2]) > np.abs(c[fourier_degree - 2]):
|
||||
return c
|
||||
else:
|
||||
return c[::-1]
|
||||
|
||||
def cal_fourier_signature(self, polygon, fourier_degree):
|
||||
"""Calculate Fourier signature from input polygon.
|
||||
|
||||
Args:
|
||||
polygon (ndarray): The input polygon.
|
||||
fourier_degree (int): The maximum Fourier degree K.
|
||||
Returns:
|
||||
fourier_signature (ndarray): An array shaped (2k+1, 2) containing
|
||||
real part and image part of 2k+1 Fourier coefficients.
|
||||
"""
|
||||
resampled_polygon = self.resample_polygon(polygon)
|
||||
resampled_polygon = self.normalize_polygon(resampled_polygon)
|
||||
|
||||
fourier_coeff = self.poly2fourier(resampled_polygon, fourier_degree)
|
||||
fourier_coeff = self.clockwise(fourier_coeff, fourier_degree)
|
||||
|
||||
real_part = np.real(fourier_coeff).reshape((-1, 1))
|
||||
image_part = np.imag(fourier_coeff).reshape((-1, 1))
|
||||
fourier_signature = np.hstack([real_part, image_part])
|
||||
|
||||
return fourier_signature
|
||||
|
||||
def generate_fourier_maps(self, img_size, text_polys):
|
||||
"""Generate Fourier coefficient maps.
|
||||
|
||||
Args:
|
||||
img_size (tuple): The image size of (height, width).
|
||||
text_polys (list[list[ndarray]]): The list of text polygons.
|
||||
|
||||
Returns:
|
||||
fourier_real_map (ndarray): The Fourier coefficient real part maps.
|
||||
fourier_image_map (ndarray): The Fourier coefficient image part
|
||||
maps.
|
||||
"""
|
||||
|
||||
assert isinstance(img_size, tuple)
|
||||
|
||||
h, w = img_size
|
||||
k = self.fourier_degree
|
||||
real_map = np.zeros((k * 2 + 1, h, w), dtype=np.float32)
|
||||
imag_map = np.zeros((k * 2 + 1, h, w), dtype=np.float32)
|
||||
|
||||
for poly in text_polys:
|
||||
mask = np.zeros((h, w), dtype=np.uint8)
|
||||
polygon = np.array(poly).reshape((1, -1, 2))
|
||||
cv2.fillPoly(mask, polygon.astype(np.int32), 1)
|
||||
fourier_coeff = self.cal_fourier_signature(polygon[0], k)
|
||||
for i in range(-k, k + 1):
|
||||
if i != 0:
|
||||
real_map[i + k, :, :] = mask * fourier_coeff[i + k, 0] + (
|
||||
1 - mask) * real_map[i + k, :, :]
|
||||
imag_map[i + k, :, :] = mask * fourier_coeff[i + k, 1] + (
|
||||
1 - mask) * imag_map[i + k, :, :]
|
||||
else:
|
||||
yx = np.argwhere(mask > 0.5)
|
||||
k_ind = np.ones((len(yx)), dtype=np.int64) * k
|
||||
y, x = yx[:, 0], yx[:, 1]
|
||||
real_map[k_ind, y, x] = fourier_coeff[k, 0] - x
|
||||
imag_map[k_ind, y, x] = fourier_coeff[k, 1] - y
|
||||
|
||||
return real_map, imag_map
|
||||
|
||||
def generate_text_region_mask(self, img_size, text_polys):
|
||||
"""Generate text center region mask and geometry attribute maps.
|
||||
|
||||
Args:
|
||||
img_size (tuple): The image size (height, width).
|
||||
text_polys (list[list[ndarray]]): The list of text polygons.
|
||||
|
||||
Returns:
|
||||
text_region_mask (ndarray): The text region mask.
|
||||
"""
|
||||
|
||||
assert isinstance(img_size, tuple)
|
||||
|
||||
h, w = img_size
|
||||
text_region_mask = np.zeros((h, w), dtype=np.uint8)
|
||||
|
||||
for poly in text_polys:
|
||||
polygon = np.array(poly, dtype=np.int32).reshape((1, -1, 2))
|
||||
cv2.fillPoly(text_region_mask, polygon, 1)
|
||||
|
||||
return text_region_mask
|
||||
|
||||
def generate_effective_mask(self, mask_size: tuple, polygons_ignore):
|
||||
"""Generate effective mask by setting the ineffective regions to 0 and
|
||||
effective regions to 1.
|
||||
|
||||
Args:
|
||||
mask_size (tuple): The mask size.
|
||||
polygons_ignore (list[[ndarray]]: The list of ignored text
|
||||
polygons.
|
||||
|
||||
Returns:
|
||||
mask (ndarray): The effective mask of (height, width).
|
||||
"""
|
||||
|
||||
mask = np.ones(mask_size, dtype=np.uint8)
|
||||
|
||||
for poly in polygons_ignore:
|
||||
instance = poly.reshape(-1, 2).astype(np.int32).reshape(1, -1, 2)
|
||||
cv2.fillPoly(mask, instance, 0)
|
||||
|
||||
return mask
|
||||
|
||||
def generate_level_targets(self, img_size, text_polys, ignore_polys):
|
||||
"""Generate ground truth target on each level.
|
||||
|
||||
Args:
|
||||
img_size (list[int]): Shape of input image.
|
||||
text_polys (list[list[ndarray]]): A list of ground truth polygons.
|
||||
ignore_polys (list[list[ndarray]]): A list of ignored polygons.
|
||||
Returns:
|
||||
level_maps (list(ndarray)): A list of ground target on each level.
|
||||
"""
|
||||
h, w = img_size
|
||||
lv_size_divs = self.level_size_divisors
|
||||
lv_proportion_range = self.level_proportion_range
|
||||
lv_text_polys = [[] for i in range(len(lv_size_divs))]
|
||||
lv_ignore_polys = [[] for i in range(len(lv_size_divs))]
|
||||
level_maps = []
|
||||
for poly in text_polys:
|
||||
polygon = np.array(poly, dtype=np.int).reshape((1, -1, 2))
|
||||
_, _, box_w, box_h = cv2.boundingRect(polygon)
|
||||
proportion = max(box_h, box_w) / (h + 1e-8)
|
||||
|
||||
for ind, proportion_range in enumerate(lv_proportion_range):
|
||||
if proportion_range[0] < proportion < proportion_range[1]:
|
||||
lv_text_polys[ind].append(poly / lv_size_divs[ind])
|
||||
|
||||
for ignore_poly in ignore_polys:
|
||||
polygon = np.array(ignore_poly, dtype=np.int).reshape((1, -1, 2))
|
||||
_, _, box_w, box_h = cv2.boundingRect(polygon)
|
||||
proportion = max(box_h, box_w) / (h + 1e-8)
|
||||
|
||||
for ind, proportion_range in enumerate(lv_proportion_range):
|
||||
if proportion_range[0] < proportion < proportion_range[1]:
|
||||
lv_ignore_polys[ind].append(ignore_poly / lv_size_divs[ind])
|
||||
|
||||
for ind, size_divisor in enumerate(lv_size_divs):
|
||||
current_level_maps = []
|
||||
level_img_size = (h // size_divisor, w // size_divisor)
|
||||
|
||||
text_region = self.generate_text_region_mask(
|
||||
level_img_size, lv_text_polys[ind])[None]
|
||||
current_level_maps.append(text_region)
|
||||
|
||||
center_region = self.generate_center_region_mask(
|
||||
level_img_size, lv_text_polys[ind])[None]
|
||||
current_level_maps.append(center_region)
|
||||
|
||||
effective_mask = self.generate_effective_mask(
|
||||
level_img_size, lv_ignore_polys[ind])[None]
|
||||
current_level_maps.append(effective_mask)
|
||||
|
||||
fourier_real_map, fourier_image_maps = self.generate_fourier_maps(
|
||||
level_img_size, lv_text_polys[ind])
|
||||
current_level_maps.append(fourier_real_map)
|
||||
current_level_maps.append(fourier_image_maps)
|
||||
|
||||
level_maps.append(np.concatenate(current_level_maps))
|
||||
|
||||
return level_maps
|
||||
|
||||
def generate_targets(self, results):
|
||||
"""Generate the ground truth targets for FCENet.
|
||||
|
||||
Args:
|
||||
results (dict): The input result dictionary.
|
||||
|
||||
Returns:
|
||||
results (dict): The output result dictionary.
|
||||
"""
|
||||
|
||||
assert isinstance(results, dict)
|
||||
image = results['image']
|
||||
polygons = results['polys']
|
||||
ignore_tags = results['ignore_tags']
|
||||
h, w, _ = image.shape
|
||||
|
||||
polygon_masks = []
|
||||
polygon_masks_ignore = []
|
||||
for tag, polygon in zip(ignore_tags, polygons):
|
||||
if tag is True:
|
||||
polygon_masks_ignore.append(polygon)
|
||||
else:
|
||||
polygon_masks.append(polygon)
|
||||
|
||||
level_maps = self.generate_level_targets((h, w), polygon_masks,
|
||||
polygon_masks_ignore)
|
||||
|
||||
mapping = {
|
||||
'p3_maps': level_maps[0],
|
||||
'p4_maps': level_maps[1],
|
||||
'p5_maps': level_maps[2]
|
||||
}
|
||||
for key, value in mapping.items():
|
||||
results[key] = value
|
||||
|
||||
return results
|
||||
|
||||
def __call__(self, results):
|
||||
results = self.generate_targets(results)
|
||||
return results
|
||||
@@ -785,6 +785,53 @@ class SARLabelEncode(BaseRecLabelEncode):
|
||||
return [self.padding_idx]
|
||||
|
||||
|
||||
class PRENLabelEncode(BaseRecLabelEncode):
|
||||
def __init__(self,
|
||||
max_text_length,
|
||||
character_dict_path,
|
||||
use_space_char=False,
|
||||
**kwargs):
|
||||
super(PRENLabelEncode, self).__init__(
|
||||
max_text_length, character_dict_path, use_space_char)
|
||||
|
||||
def add_special_char(self, dict_character):
|
||||
padding_str = '<PAD>' # 0
|
||||
end_str = '<EOS>' # 1
|
||||
unknown_str = '<UNK>' # 2
|
||||
|
||||
dict_character = [padding_str, end_str, unknown_str] + dict_character
|
||||
self.padding_idx = 0
|
||||
self.end_idx = 1
|
||||
self.unknown_idx = 2
|
||||
|
||||
return dict_character
|
||||
|
||||
def encode(self, text):
|
||||
if len(text) == 0 or len(text) >= self.max_text_len:
|
||||
return None
|
||||
if self.lower:
|
||||
text = text.lower()
|
||||
text_list = []
|
||||
for char in text:
|
||||
if char not in self.dict:
|
||||
text_list.append(self.unknown_idx)
|
||||
else:
|
||||
text_list.append(self.dict[char])
|
||||
text_list.append(self.end_idx)
|
||||
if len(text_list) < self.max_text_len:
|
||||
text_list += [self.padding_idx] * (
|
||||
self.max_text_len - len(text_list))
|
||||
return text_list
|
||||
|
||||
def __call__(self, data):
|
||||
text = data['label']
|
||||
encoded_text = self.encode(text)
|
||||
if encoded_text is None:
|
||||
return None
|
||||
data['label'] = np.array(encoded_text)
|
||||
return data
|
||||
|
||||
|
||||
class VQATokenLabelEncode(object):
|
||||
"""
|
||||
Label encode for NLP VQA methods
|
||||
|
||||
@@ -23,14 +23,20 @@ import sys
|
||||
import six
|
||||
import cv2
|
||||
import numpy as np
|
||||
import math
|
||||
|
||||
|
||||
class DecodeImage(object):
|
||||
""" decode image """
|
||||
|
||||
def __init__(self, img_mode='RGB', channel_first=False, **kwargs):
|
||||
def __init__(self,
|
||||
img_mode='RGB',
|
||||
channel_first=False,
|
||||
ignore_orientation=False,
|
||||
**kwargs):
|
||||
self.img_mode = img_mode
|
||||
self.channel_first = channel_first
|
||||
self.ignore_orientation = ignore_orientation
|
||||
|
||||
def __call__(self, data):
|
||||
img = data['image']
|
||||
@@ -41,7 +47,11 @@ class DecodeImage(object):
|
||||
assert type(img) is bytes and len(
|
||||
img) > 0, "invalid input 'img' in DecodeImage"
|
||||
img = np.frombuffer(img, dtype='uint8')
|
||||
img = cv2.imdecode(img, 1)
|
||||
if self.ignore_orientation:
|
||||
img = cv2.imdecode(img, cv2.IMREAD_IGNORE_ORIENTATION |
|
||||
cv2.IMREAD_COLOR)
|
||||
else:
|
||||
img = cv2.imdecode(img, 1)
|
||||
if img is None:
|
||||
return None
|
||||
if self.img_mode == 'GRAY':
|
||||
@@ -156,6 +166,44 @@ class KeepKeys(object):
|
||||
return data_list
|
||||
|
||||
|
||||
class Pad(object):
|
||||
def __init__(self, size=None, size_div=32, **kwargs):
|
||||
if size is not None and not isinstance(size, (int, list, tuple)):
|
||||
raise TypeError("Type of target_size is invalid. Now is {}".format(
|
||||
type(size)))
|
||||
if isinstance(size, int):
|
||||
size = [size, size]
|
||||
self.size = size
|
||||
self.size_div = size_div
|
||||
|
||||
def __call__(self, data):
|
||||
|
||||
img = data['image']
|
||||
img_h, img_w = img.shape[0], img.shape[1]
|
||||
if self.size:
|
||||
resize_h2, resize_w2 = self.size
|
||||
assert (
|
||||
img_h < resize_h2 and img_w < resize_w2
|
||||
), '(h, w) of target size should be greater than (img_h, img_w)'
|
||||
else:
|
||||
resize_h2 = max(
|
||||
int(math.ceil(img.shape[0] / self.size_div) * self.size_div),
|
||||
self.size_div)
|
||||
resize_w2 = max(
|
||||
int(math.ceil(img.shape[1] / self.size_div) * self.size_div),
|
||||
self.size_div)
|
||||
img = cv2.copyMakeBorder(
|
||||
img,
|
||||
0,
|
||||
resize_h2 - img_h,
|
||||
0,
|
||||
resize_w2 - img_w,
|
||||
cv2.BORDER_CONSTANT,
|
||||
value=0)
|
||||
data['image'] = img
|
||||
return data
|
||||
|
||||
|
||||
class Resize(object):
|
||||
def __init__(self, size=(640, 640), **kwargs):
|
||||
self.size = size
|
||||
|
||||
@@ -141,6 +141,25 @@ class SARRecResizeImg(object):
|
||||
return data
|
||||
|
||||
|
||||
class PRENResizeImg(object):
|
||||
def __init__(self, image_shape, **kwargs):
|
||||
"""
|
||||
Accroding to original paper's realization, it's a hard resize method here.
|
||||
So maybe you should optimize it to fit for your task better.
|
||||
"""
|
||||
self.dst_h, self.dst_w = image_shape
|
||||
|
||||
def __call__(self, data):
|
||||
img = data['image']
|
||||
resized_img = cv2.resize(
|
||||
img, (self.dst_w, self.dst_h), interpolation=cv2.INTER_LINEAR)
|
||||
resized_img = resized_img.transpose((2, 0, 1)) / 255
|
||||
resized_img -= 0.5
|
||||
resized_img /= 0.5
|
||||
data['image'] = resized_img.astype(np.float32)
|
||||
return data
|
||||
|
||||
|
||||
def resize_norm_img_sar(img, image_shape, width_downsample_ratio=0.25):
|
||||
imgC, imgH, imgW_min, imgW_max = image_shape
|
||||
h = img.shape[0]
|
||||
|
||||
@@ -13,6 +13,7 @@
|
||||
# limitations under the License.
|
||||
import numpy as np
|
||||
import os
|
||||
import json
|
||||
import random
|
||||
import traceback
|
||||
from paddle.io import Dataset
|
||||
|
||||
@@ -24,6 +24,7 @@ from .det_db_loss import DBLoss
|
||||
from .det_east_loss import EASTLoss
|
||||
from .det_sast_loss import SASTLoss
|
||||
from .det_pse_loss import PSELoss
|
||||
from .det_fce_loss import FCELoss
|
||||
|
||||
# rec loss
|
||||
from .rec_ctc_loss import CTCLoss
|
||||
@@ -32,6 +33,7 @@ from .rec_srn_loss import SRNLoss
|
||||
from .rec_nrtr_loss import NRTRLoss
|
||||
from .rec_sar_loss import SARLoss
|
||||
from .rec_aster_loss import AsterLoss
|
||||
from .rec_pren_loss import PRENLoss
|
||||
|
||||
# cls loss
|
||||
from .cls_loss import ClsLoss
|
||||
@@ -55,10 +57,10 @@ from .vqa_token_layoutlm_loss import VQASerTokenLayoutLMLoss
|
||||
|
||||
def build_loss(config):
|
||||
support_dict = [
|
||||
'DBLoss', 'PSELoss', 'EASTLoss', 'SASTLoss', 'CTCLoss', 'ClsLoss',
|
||||
'AttentionLoss', 'SRNLoss', 'PGLoss', 'CombinedLoss', 'NRTRLoss',
|
||||
'TableAttentionLoss', 'SARLoss', 'AsterLoss', 'SDMGRLoss',
|
||||
'VQASerTokenLayoutLMLoss', 'LossFromOutput'
|
||||
'DBLoss', 'PSELoss', 'EASTLoss', 'SASTLoss', 'FCELoss', 'CTCLoss',
|
||||
'ClsLoss', 'AttentionLoss', 'SRNLoss', 'PGLoss', 'CombinedLoss',
|
||||
'NRTRLoss', 'TableAttentionLoss', 'SARLoss', 'AsterLoss', 'SDMGRLoss',
|
||||
'VQASerTokenLayoutLMLoss', 'LossFromOutput', 'PRENLoss'
|
||||
]
|
||||
config = copy.deepcopy(config)
|
||||
module_name = config.pop('name')
|
||||
|
||||
@@ -95,9 +95,15 @@ class DMLLoss(nn.Layer):
|
||||
self.act = None
|
||||
|
||||
self.use_log = use_log
|
||||
|
||||
self.jskl_loss = KLJSLoss(mode="js")
|
||||
|
||||
def _kldiv(self, x, target):
|
||||
eps = 1.0e-10
|
||||
loss = target * (paddle.log(target + eps) - x)
|
||||
# batch mean loss
|
||||
loss = paddle.sum(loss) / loss.shape[0]
|
||||
return loss
|
||||
|
||||
def forward(self, out1, out2):
|
||||
if self.act is not None:
|
||||
out1 = self.act(out1)
|
||||
@@ -106,9 +112,8 @@ class DMLLoss(nn.Layer):
|
||||
# for recognition distillation, log is needed for feature map
|
||||
log_out1 = paddle.log(out1)
|
||||
log_out2 = paddle.log(out2)
|
||||
loss = (F.kl_div(
|
||||
log_out1, out2, reduction='batchmean') + F.kl_div(
|
||||
log_out2, out1, reduction='batchmean')) / 2.0
|
||||
loss = (
|
||||
self._kldiv(log_out1, out2) + self._kldiv(log_out2, out1)) / 2.0
|
||||
else:
|
||||
# for detection distillation log is not needed
|
||||
loss = self.jskl_loss(out1, out2)
|
||||
|
||||
@@ -0,0 +1,227 @@
|
||||
# copyright (c) 2022 PaddlePaddle Authors. All Rights Reserve.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
"""
|
||||
This code is refer from:
|
||||
https://github.com/open-mmlab/mmocr/blob/main/mmocr/models/textdet/losses/fce_loss.py
|
||||
"""
|
||||
|
||||
import numpy as np
|
||||
from paddle import nn
|
||||
import paddle
|
||||
import paddle.nn.functional as F
|
||||
from functools import partial
|
||||
|
||||
|
||||
def multi_apply(func, *args, **kwargs):
|
||||
pfunc = partial(func, **kwargs) if kwargs else func
|
||||
map_results = map(pfunc, *args)
|
||||
return tuple(map(list, zip(*map_results)))
|
||||
|
||||
|
||||
class FCELoss(nn.Layer):
|
||||
"""The class for implementing FCENet loss
|
||||
FCENet(CVPR2021): Fourier Contour Embedding for Arbitrary-shaped
|
||||
Text Detection
|
||||
|
||||
[https://arxiv.org/abs/2104.10442]
|
||||
|
||||
Args:
|
||||
fourier_degree (int) : The maximum Fourier transform degree k.
|
||||
num_sample (int) : The sampling points number of regression
|
||||
loss. If it is too small, fcenet tends to be overfitting.
|
||||
ohem_ratio (float): the negative/positive ratio in OHEM.
|
||||
"""
|
||||
|
||||
def __init__(self, fourier_degree, num_sample, ohem_ratio=3.):
|
||||
super().__init__()
|
||||
self.fourier_degree = fourier_degree
|
||||
self.num_sample = num_sample
|
||||
self.ohem_ratio = ohem_ratio
|
||||
|
||||
def forward(self, preds, labels):
|
||||
assert isinstance(preds, dict)
|
||||
preds = preds['levels']
|
||||
|
||||
p3_maps, p4_maps, p5_maps = labels[1:]
|
||||
assert p3_maps[0].shape[0] == 4 * self.fourier_degree + 5,\
|
||||
'fourier degree not equal in FCEhead and FCEtarget'
|
||||
|
||||
# to tensor
|
||||
gts = [p3_maps, p4_maps, p5_maps]
|
||||
for idx, maps in enumerate(gts):
|
||||
gts[idx] = paddle.to_tensor(np.stack(maps))
|
||||
|
||||
losses = multi_apply(self.forward_single, preds, gts)
|
||||
|
||||
loss_tr = paddle.to_tensor(0.).astype('float32')
|
||||
loss_tcl = paddle.to_tensor(0.).astype('float32')
|
||||
loss_reg_x = paddle.to_tensor(0.).astype('float32')
|
||||
loss_reg_y = paddle.to_tensor(0.).astype('float32')
|
||||
loss_all = paddle.to_tensor(0.).astype('float32')
|
||||
|
||||
for idx, loss in enumerate(losses):
|
||||
loss_all += sum(loss)
|
||||
if idx == 0:
|
||||
loss_tr += sum(loss)
|
||||
elif idx == 1:
|
||||
loss_tcl += sum(loss)
|
||||
elif idx == 2:
|
||||
loss_reg_x += sum(loss)
|
||||
else:
|
||||
loss_reg_y += sum(loss)
|
||||
|
||||
results = dict(
|
||||
loss=loss_all,
|
||||
loss_text=loss_tr,
|
||||
loss_center=loss_tcl,
|
||||
loss_reg_x=loss_reg_x,
|
||||
loss_reg_y=loss_reg_y, )
|
||||
return results
|
||||
|
||||
def forward_single(self, pred, gt):
|
||||
cls_pred = paddle.transpose(pred[0], (0, 2, 3, 1))
|
||||
reg_pred = paddle.transpose(pred[1], (0, 2, 3, 1))
|
||||
gt = paddle.transpose(gt, (0, 2, 3, 1))
|
||||
|
||||
k = 2 * self.fourier_degree + 1
|
||||
tr_pred = paddle.reshape(cls_pred[:, :, :, :2], (-1, 2))
|
||||
tcl_pred = paddle.reshape(cls_pred[:, :, :, 2:], (-1, 2))
|
||||
x_pred = paddle.reshape(reg_pred[:, :, :, 0:k], (-1, k))
|
||||
y_pred = paddle.reshape(reg_pred[:, :, :, k:2 * k], (-1, k))
|
||||
|
||||
tr_mask = gt[:, :, :, :1].reshape([-1])
|
||||
tcl_mask = gt[:, :, :, 1:2].reshape([-1])
|
||||
train_mask = gt[:, :, :, 2:3].reshape([-1])
|
||||
x_map = paddle.reshape(gt[:, :, :, 3:3 + k], (-1, k))
|
||||
y_map = paddle.reshape(gt[:, :, :, 3 + k:], (-1, k))
|
||||
|
||||
tr_train_mask = (train_mask * tr_mask).astype('bool')
|
||||
tr_train_mask2 = paddle.concat(
|
||||
[tr_train_mask.unsqueeze(1), tr_train_mask.unsqueeze(1)], axis=1)
|
||||
# tr loss
|
||||
loss_tr = self.ohem(tr_pred, tr_mask, train_mask)
|
||||
# tcl loss
|
||||
loss_tcl = paddle.to_tensor(0.).astype('float32')
|
||||
tr_neg_mask = tr_train_mask.logical_not()
|
||||
tr_neg_mask2 = paddle.concat(
|
||||
[tr_neg_mask.unsqueeze(1), tr_neg_mask.unsqueeze(1)], axis=1)
|
||||
if tr_train_mask.sum().item() > 0:
|
||||
loss_tcl_pos = F.cross_entropy(
|
||||
tcl_pred.masked_select(tr_train_mask2).reshape([-1, 2]),
|
||||
tcl_mask.masked_select(tr_train_mask).astype('int64'))
|
||||
loss_tcl_neg = F.cross_entropy(
|
||||
tcl_pred.masked_select(tr_neg_mask2).reshape([-1, 2]),
|
||||
tcl_mask.masked_select(tr_neg_mask).astype('int64'))
|
||||
loss_tcl = loss_tcl_pos + 0.5 * loss_tcl_neg
|
||||
|
||||
# regression loss
|
||||
loss_reg_x = paddle.to_tensor(0.).astype('float32')
|
||||
loss_reg_y = paddle.to_tensor(0.).astype('float32')
|
||||
if tr_train_mask.sum().item() > 0:
|
||||
weight = (tr_mask.masked_select(tr_train_mask.astype('bool'))
|
||||
.astype('float32') + tcl_mask.masked_select(
|
||||
tr_train_mask.astype('bool')).astype('float32')) / 2
|
||||
weight = weight.reshape([-1, 1])
|
||||
|
||||
ft_x, ft_y = self.fourier2poly(x_map, y_map)
|
||||
ft_x_pre, ft_y_pre = self.fourier2poly(x_pred, y_pred)
|
||||
|
||||
dim = ft_x.shape[1]
|
||||
|
||||
tr_train_mask3 = paddle.concat(
|
||||
[tr_train_mask.unsqueeze(1) for i in range(dim)], axis=1)
|
||||
|
||||
loss_reg_x = paddle.mean(weight * F.smooth_l1_loss(
|
||||
ft_x_pre.masked_select(tr_train_mask3).reshape([-1, dim]),
|
||||
ft_x.masked_select(tr_train_mask3).reshape([-1, dim]),
|
||||
reduction='none'))
|
||||
loss_reg_y = paddle.mean(weight * F.smooth_l1_loss(
|
||||
ft_y_pre.masked_select(tr_train_mask3).reshape([-1, dim]),
|
||||
ft_y.masked_select(tr_train_mask3).reshape([-1, dim]),
|
||||
reduction='none'))
|
||||
|
||||
return loss_tr, loss_tcl, loss_reg_x, loss_reg_y
|
||||
|
||||
def ohem(self, predict, target, train_mask):
|
||||
|
||||
pos = (target * train_mask).astype('bool')
|
||||
neg = ((1 - target) * train_mask).astype('bool')
|
||||
|
||||
pos2 = paddle.concat([pos.unsqueeze(1), pos.unsqueeze(1)], axis=1)
|
||||
neg2 = paddle.concat([neg.unsqueeze(1), neg.unsqueeze(1)], axis=1)
|
||||
|
||||
n_pos = pos.astype('float32').sum()
|
||||
|
||||
if n_pos.item() > 0:
|
||||
loss_pos = F.cross_entropy(
|
||||
predict.masked_select(pos2).reshape([-1, 2]),
|
||||
target.masked_select(pos).astype('int64'),
|
||||
reduction='sum')
|
||||
loss_neg = F.cross_entropy(
|
||||
predict.masked_select(neg2).reshape([-1, 2]),
|
||||
target.masked_select(neg).astype('int64'),
|
||||
reduction='none')
|
||||
n_neg = min(
|
||||
int(neg.astype('float32').sum().item()),
|
||||
int(self.ohem_ratio * n_pos.astype('float32')))
|
||||
else:
|
||||
loss_pos = paddle.to_tensor(0.)
|
||||
loss_neg = F.cross_entropy(
|
||||
predict.masked_select(neg2).reshape([-1, 2]),
|
||||
target.masked_select(neg).astype('int64'),
|
||||
reduction='none')
|
||||
n_neg = 100
|
||||
if len(loss_neg) > n_neg:
|
||||
loss_neg, _ = paddle.topk(loss_neg, n_neg)
|
||||
|
||||
return (loss_pos + loss_neg.sum()) / (n_pos + n_neg).astype('float32')
|
||||
|
||||
def fourier2poly(self, real_maps, imag_maps):
|
||||
"""Transform Fourier coefficient maps to polygon maps.
|
||||
|
||||
Args:
|
||||
real_maps (tensor): A map composed of the real parts of the
|
||||
Fourier coefficients, whose shape is (-1, 2k+1)
|
||||
imag_maps (tensor):A map composed of the imag parts of the
|
||||
Fourier coefficients, whose shape is (-1, 2k+1)
|
||||
|
||||
Returns
|
||||
x_maps (tensor): A map composed of the x value of the polygon
|
||||
represented by n sample points (xn, yn), whose shape is (-1, n)
|
||||
y_maps (tensor): A map composed of the y value of the polygon
|
||||
represented by n sample points (xn, yn), whose shape is (-1, n)
|
||||
"""
|
||||
|
||||
k_vect = paddle.arange(
|
||||
-self.fourier_degree, self.fourier_degree + 1,
|
||||
dtype='float32').reshape([-1, 1])
|
||||
i_vect = paddle.arange(
|
||||
0, self.num_sample, dtype='float32').reshape([1, -1])
|
||||
|
||||
transform_matrix = 2 * np.pi / self.num_sample * paddle.matmul(k_vect,
|
||||
i_vect)
|
||||
|
||||
x1 = paddle.einsum('ak, kn-> an', real_maps,
|
||||
paddle.cos(transform_matrix))
|
||||
x2 = paddle.einsum('ak, kn-> an', imag_maps,
|
||||
paddle.sin(transform_matrix))
|
||||
y1 = paddle.einsum('ak, kn-> an', real_maps,
|
||||
paddle.sin(transform_matrix))
|
||||
y2 = paddle.einsum('ak, kn-> an', imag_maps,
|
||||
paddle.cos(transform_matrix))
|
||||
|
||||
x_maps = x1 - x2
|
||||
y_maps = y1 + y2
|
||||
|
||||
return x_maps, y_maps
|
||||
@@ -0,0 +1,30 @@
|
||||
# copyright (c) 2022 PaddlePaddle Authors. All Rights Reserve.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
from __future__ import absolute_import
|
||||
from __future__ import division
|
||||
from __future__ import print_function
|
||||
|
||||
from paddle import nn
|
||||
|
||||
|
||||
class PRENLoss(nn.Layer):
|
||||
def __init__(self, **kwargs):
|
||||
super(PRENLoss, self).__init__()
|
||||
# note: 0 is padding idx
|
||||
self.loss_func = nn.CrossEntropyLoss(reduction='mean', ignore_index=0)
|
||||
|
||||
def forward(self, predicts, batch):
|
||||
loss = self.loss_func(predicts, batch[1].astype('int64'))
|
||||
return {'loss': loss}
|
||||
@@ -21,7 +21,7 @@ import copy
|
||||
|
||||
__all__ = ["build_metric"]
|
||||
|
||||
from .det_metric import DetMetric
|
||||
from .det_metric import DetMetric, DetFCEMetric
|
||||
from .rec_metric import RecMetric
|
||||
from .cls_metric import ClsMetric
|
||||
from .e2e_metric import E2EMetric
|
||||
@@ -34,7 +34,7 @@ from .vqa_token_re_metric import VQAReTokenMetric
|
||||
|
||||
def build_metric(config):
|
||||
support_dict = [
|
||||
"DetMetric", "RecMetric", "ClsMetric", "E2EMetric",
|
||||
"DetMetric", "DetFCEMetric", "RecMetric", "ClsMetric", "E2EMetric",
|
||||
"DistillationMetric", "TableMetric", 'KIEMetric', 'VQASerTokenMetric',
|
||||
'VQAReTokenMetric'
|
||||
]
|
||||
|
||||
@@ -16,7 +16,7 @@ from __future__ import absolute_import
|
||||
from __future__ import division
|
||||
from __future__ import print_function
|
||||
|
||||
__all__ = ['DetMetric']
|
||||
__all__ = ['DetMetric', 'DetFCEMetric']
|
||||
|
||||
from .eval_det_iou import DetectionIoUEvaluator
|
||||
|
||||
@@ -55,7 +55,6 @@ class DetMetric(object):
|
||||
result = self.evaluator.evaluate_image(gt_info_list, det_info_list)
|
||||
self.results.append(result)
|
||||
|
||||
|
||||
def get_metric(self):
|
||||
"""
|
||||
return metrics {
|
||||
@@ -71,3 +70,85 @@ class DetMetric(object):
|
||||
|
||||
def reset(self):
|
||||
self.results = [] # clear results
|
||||
|
||||
|
||||
class DetFCEMetric(object):
|
||||
def __init__(self, main_indicator='hmean', **kwargs):
|
||||
self.evaluator = DetectionIoUEvaluator()
|
||||
self.main_indicator = main_indicator
|
||||
self.reset()
|
||||
|
||||
def __call__(self, preds, batch, **kwargs):
|
||||
'''
|
||||
batch: a list produced by dataloaders.
|
||||
image: np.ndarray of shape (N, C, H, W).
|
||||
ratio_list: np.ndarray of shape(N,2)
|
||||
polygons: np.ndarray of shape (N, K, 4, 2), the polygons of objective regions.
|
||||
ignore_tags: np.ndarray of shape (N, K), indicates whether a region is ignorable or not.
|
||||
preds: a list of dict produced by post process
|
||||
points: np.ndarray of shape (N, K, 4, 2), the polygons of objective regions.
|
||||
'''
|
||||
gt_polyons_batch = batch[2]
|
||||
ignore_tags_batch = batch[3]
|
||||
|
||||
for pred, gt_polyons, ignore_tags in zip(preds, gt_polyons_batch,
|
||||
ignore_tags_batch):
|
||||
# prepare gt
|
||||
gt_info_list = [{
|
||||
'points': gt_polyon,
|
||||
'text': '',
|
||||
'ignore': ignore_tag
|
||||
} for gt_polyon, ignore_tag in zip(gt_polyons, ignore_tags)]
|
||||
# prepare det
|
||||
det_info_list = [{
|
||||
'points': det_polyon,
|
||||
'text': '',
|
||||
'score': score
|
||||
} for det_polyon, score in zip(pred['points'], pred['scores'])]
|
||||
|
||||
for score_thr in self.results.keys():
|
||||
det_info_list_thr = [
|
||||
det_info for det_info in det_info_list
|
||||
if det_info['score'] >= score_thr
|
||||
]
|
||||
result = self.evaluator.evaluate_image(gt_info_list,
|
||||
det_info_list_thr)
|
||||
self.results[score_thr].append(result)
|
||||
|
||||
def get_metric(self):
|
||||
"""
|
||||
return metrics {'heman':0,
|
||||
'thr 0.3':'precision: 0 recall: 0 hmean: 0',
|
||||
'thr 0.4':'precision: 0 recall: 0 hmean: 0',
|
||||
'thr 0.5':'precision: 0 recall: 0 hmean: 0',
|
||||
'thr 0.6':'precision: 0 recall: 0 hmean: 0',
|
||||
'thr 0.7':'precision: 0 recall: 0 hmean: 0',
|
||||
'thr 0.8':'precision: 0 recall: 0 hmean: 0',
|
||||
'thr 0.9':'precision: 0 recall: 0 hmean: 0',
|
||||
}
|
||||
"""
|
||||
metircs = {}
|
||||
hmean = 0
|
||||
for score_thr in self.results.keys():
|
||||
metirc = self.evaluator.combine_results(self.results[score_thr])
|
||||
# for key, value in metirc.items():
|
||||
# metircs['{}_{}'.format(key, score_thr)] = value
|
||||
metirc_str = 'precision:{:.5f} recall:{:.5f} hmean:{:.5f}'.format(
|
||||
metirc['precision'], metirc['recall'], metirc['hmean'])
|
||||
metircs['thr {}'.format(score_thr)] = metirc_str
|
||||
hmean = max(hmean, metirc['hmean'])
|
||||
metircs['hmean'] = hmean
|
||||
|
||||
self.reset()
|
||||
return metircs
|
||||
|
||||
def reset(self):
|
||||
self.results = {
|
||||
0.3: [],
|
||||
0.4: [],
|
||||
0.5: [],
|
||||
0.6: [],
|
||||
0.7: [],
|
||||
0.8: [],
|
||||
0.9: []
|
||||
} # clear results
|
||||
|
||||
@@ -30,9 +30,10 @@ def build_backbone(config, model_type):
|
||||
from .rec_resnet_31 import ResNet31
|
||||
from .rec_resnet_aster import ResNet_ASTER
|
||||
from .rec_micronet import MicroNet
|
||||
from .rec_efficientb3_pren import EfficientNetb3_PREN
|
||||
support_dict = [
|
||||
'MobileNetV1Enhance', 'MobileNetV3', 'ResNet', 'ResNetFPN', 'MTB',
|
||||
"ResNet31", "ResNet_ASTER", 'MicroNet'
|
||||
"ResNet31", "ResNet_ASTER", 'MicroNet', 'EfficientNetb3_PREN'
|
||||
]
|
||||
elif model_type == "e2e":
|
||||
from .e2e_resnet_vd_pg import ResNet
|
||||
|
||||
@@ -21,9 +21,82 @@ from paddle import ParamAttr
|
||||
import paddle.nn as nn
|
||||
import paddle.nn.functional as F
|
||||
|
||||
from paddle.vision.ops import DeformConv2D
|
||||
from paddle.regularizer import L2Decay
|
||||
from paddle.nn.initializer import Normal, Constant, XavierUniform
|
||||
|
||||
__all__ = ["ResNet"]
|
||||
|
||||
|
||||
class DeformableConvV2(nn.Layer):
|
||||
def __init__(self,
|
||||
in_channels,
|
||||
out_channels,
|
||||
kernel_size,
|
||||
stride=1,
|
||||
padding=0,
|
||||
dilation=1,
|
||||
groups=1,
|
||||
weight_attr=None,
|
||||
bias_attr=None,
|
||||
lr_scale=1,
|
||||
regularizer=None,
|
||||
skip_quant=False,
|
||||
dcn_bias_regularizer=L2Decay(0.),
|
||||
dcn_bias_lr_scale=2.):
|
||||
super(DeformableConvV2, self).__init__()
|
||||
self.offset_channel = 2 * kernel_size**2 * groups
|
||||
self.mask_channel = kernel_size**2 * groups
|
||||
|
||||
if bias_attr:
|
||||
# in FCOS-DCN head, specifically need learning_rate and regularizer
|
||||
dcn_bias_attr = ParamAttr(
|
||||
initializer=Constant(value=0),
|
||||
regularizer=dcn_bias_regularizer,
|
||||
learning_rate=dcn_bias_lr_scale)
|
||||
else:
|
||||
# in ResNet backbone, do not need bias
|
||||
dcn_bias_attr = False
|
||||
self.conv_dcn = DeformConv2D(
|
||||
in_channels,
|
||||
out_channels,
|
||||
kernel_size,
|
||||
stride=stride,
|
||||
padding=(kernel_size - 1) // 2 * dilation,
|
||||
dilation=dilation,
|
||||
deformable_groups=groups,
|
||||
weight_attr=weight_attr,
|
||||
bias_attr=dcn_bias_attr)
|
||||
|
||||
if lr_scale == 1 and regularizer is None:
|
||||
offset_bias_attr = ParamAttr(initializer=Constant(0.))
|
||||
else:
|
||||
offset_bias_attr = ParamAttr(
|
||||
initializer=Constant(0.),
|
||||
learning_rate=lr_scale,
|
||||
regularizer=regularizer)
|
||||
self.conv_offset = nn.Conv2D(
|
||||
in_channels,
|
||||
groups * 3 * kernel_size**2,
|
||||
kernel_size,
|
||||
stride=stride,
|
||||
padding=(kernel_size - 1) // 2,
|
||||
weight_attr=ParamAttr(initializer=Constant(0.0)),
|
||||
bias_attr=offset_bias_attr)
|
||||
if skip_quant:
|
||||
self.conv_offset.skip_quant = True
|
||||
|
||||
def forward(self, x):
|
||||
offset_mask = self.conv_offset(x)
|
||||
offset, mask = paddle.split(
|
||||
offset_mask,
|
||||
num_or_sections=[self.offset_channel, self.mask_channel],
|
||||
axis=1)
|
||||
mask = F.sigmoid(mask)
|
||||
y = self.conv_dcn(x, offset, mask=mask)
|
||||
return y
|
||||
|
||||
|
||||
class ConvBNLayer(nn.Layer):
|
||||
def __init__(self,
|
||||
in_channels,
|
||||
@@ -32,20 +105,31 @@ class ConvBNLayer(nn.Layer):
|
||||
stride=1,
|
||||
groups=1,
|
||||
is_vd_mode=False,
|
||||
act=None):
|
||||
act=None,
|
||||
is_dcn=False):
|
||||
super(ConvBNLayer, self).__init__()
|
||||
|
||||
self.is_vd_mode = is_vd_mode
|
||||
self._pool2d_avg = nn.AvgPool2D(
|
||||
kernel_size=2, stride=2, padding=0, ceil_mode=True)
|
||||
self._conv = nn.Conv2D(
|
||||
in_channels=in_channels,
|
||||
out_channels=out_channels,
|
||||
kernel_size=kernel_size,
|
||||
stride=stride,
|
||||
padding=(kernel_size - 1) // 2,
|
||||
groups=groups,
|
||||
bias_attr=False)
|
||||
if not is_dcn:
|
||||
self._conv = nn.Conv2D(
|
||||
in_channels=in_channels,
|
||||
out_channels=out_channels,
|
||||
kernel_size=kernel_size,
|
||||
stride=stride,
|
||||
padding=(kernel_size - 1) // 2,
|
||||
groups=groups,
|
||||
bias_attr=False)
|
||||
else:
|
||||
self._conv = DeformableConvV2(
|
||||
in_channels=in_channels,
|
||||
out_channels=out_channels,
|
||||
kernel_size=kernel_size,
|
||||
stride=stride,
|
||||
padding=(kernel_size - 1) // 2,
|
||||
groups=2, #groups,
|
||||
bias_attr=False)
|
||||
self._batch_norm = nn.BatchNorm(out_channels, act=act)
|
||||
|
||||
def forward(self, inputs):
|
||||
@@ -57,12 +141,14 @@ class ConvBNLayer(nn.Layer):
|
||||
|
||||
|
||||
class BottleneckBlock(nn.Layer):
|
||||
def __init__(self,
|
||||
in_channels,
|
||||
out_channels,
|
||||
stride,
|
||||
shortcut=True,
|
||||
if_first=False):
|
||||
def __init__(
|
||||
self,
|
||||
in_channels,
|
||||
out_channels,
|
||||
stride,
|
||||
shortcut=True,
|
||||
if_first=False,
|
||||
is_dcn=False, ):
|
||||
super(BottleneckBlock, self).__init__()
|
||||
|
||||
self.conv0 = ConvBNLayer(
|
||||
@@ -75,7 +161,8 @@ class BottleneckBlock(nn.Layer):
|
||||
out_channels=out_channels,
|
||||
kernel_size=3,
|
||||
stride=stride,
|
||||
act='relu')
|
||||
act='relu',
|
||||
is_dcn=is_dcn)
|
||||
self.conv2 = ConvBNLayer(
|
||||
in_channels=out_channels,
|
||||
out_channels=out_channels * 4,
|
||||
@@ -152,7 +239,12 @@ class BasicBlock(nn.Layer):
|
||||
|
||||
|
||||
class ResNet(nn.Layer):
|
||||
def __init__(self, in_channels=3, layers=50, **kwargs):
|
||||
def __init__(self,
|
||||
in_channels=3,
|
||||
layers=50,
|
||||
dcn_stage=None,
|
||||
out_indices=None,
|
||||
**kwargs):
|
||||
super(ResNet, self).__init__()
|
||||
|
||||
self.layers = layers
|
||||
@@ -175,6 +267,13 @@ class ResNet(nn.Layer):
|
||||
1024] if layers >= 50 else [64, 64, 128, 256]
|
||||
num_filters = [64, 128, 256, 512]
|
||||
|
||||
self.dcn_stage = dcn_stage if dcn_stage is not None else [
|
||||
False, False, False, False
|
||||
]
|
||||
self.out_indices = out_indices if out_indices is not None else [
|
||||
0, 1, 2, 3
|
||||
]
|
||||
|
||||
self.conv1_1 = ConvBNLayer(
|
||||
in_channels=in_channels,
|
||||
out_channels=32,
|
||||
@@ -201,6 +300,7 @@ class ResNet(nn.Layer):
|
||||
for block in range(len(depth)):
|
||||
block_list = []
|
||||
shortcut = False
|
||||
is_dcn = self.dcn_stage[block]
|
||||
for i in range(depth[block]):
|
||||
bottleneck_block = self.add_sublayer(
|
||||
'bb_%d_%d' % (block, i),
|
||||
@@ -210,15 +310,18 @@ class ResNet(nn.Layer):
|
||||
out_channels=num_filters[block],
|
||||
stride=2 if i == 0 and block != 0 else 1,
|
||||
shortcut=shortcut,
|
||||
if_first=block == i == 0))
|
||||
if_first=block == i == 0,
|
||||
is_dcn=is_dcn))
|
||||
shortcut = True
|
||||
block_list.append(bottleneck_block)
|
||||
self.out_channels.append(num_filters[block] * 4)
|
||||
if block in self.out_indices:
|
||||
self.out_channels.append(num_filters[block] * 4)
|
||||
self.stages.append(nn.Sequential(*block_list))
|
||||
else:
|
||||
for block in range(len(depth)):
|
||||
block_list = []
|
||||
shortcut = False
|
||||
# is_dcn = self.dcn_stage[block]
|
||||
for i in range(depth[block]):
|
||||
basic_block = self.add_sublayer(
|
||||
'bb_%d_%d' % (block, i),
|
||||
@@ -231,7 +334,8 @@ class ResNet(nn.Layer):
|
||||
if_first=block == i == 0))
|
||||
shortcut = True
|
||||
block_list.append(basic_block)
|
||||
self.out_channels.append(num_filters[block])
|
||||
if block in self.out_indices:
|
||||
self.out_channels.append(num_filters[block])
|
||||
self.stages.append(nn.Sequential(*block_list))
|
||||
|
||||
def forward(self, inputs):
|
||||
@@ -240,7 +344,8 @@ class ResNet(nn.Layer):
|
||||
y = self.conv1_3(y)
|
||||
y = self.pool2d_max(y)
|
||||
out = []
|
||||
for block in self.stages:
|
||||
for i, block in enumerate(self.stages):
|
||||
y = block(y)
|
||||
out.append(y)
|
||||
if i in self.out_indices:
|
||||
out.append(y)
|
||||
return out
|
||||
|
||||
@@ -0,0 +1,228 @@
|
||||
# copyright (c) 2022 PaddlePaddle Authors. All Rights Reserve.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
"""
|
||||
Code is refer from:
|
||||
https://github.com/RuijieJ/pren/blob/main/Nets/EfficientNet.py
|
||||
"""
|
||||
|
||||
from __future__ import absolute_import
|
||||
from __future__ import division
|
||||
from __future__ import print_function
|
||||
|
||||
import math
|
||||
from collections import namedtuple
|
||||
import paddle
|
||||
import paddle.nn as nn
|
||||
import paddle.nn.functional as F
|
||||
|
||||
__all__ = ['EfficientNetb3']
|
||||
|
||||
|
||||
class EffB3Params:
|
||||
@staticmethod
|
||||
def get_global_params():
|
||||
"""
|
||||
The fllowing are efficientnetb3's arch superparams, but to fit for scene
|
||||
text recognition task, the resolution(image_size) here is changed
|
||||
from 300 to 64.
|
||||
"""
|
||||
GlobalParams = namedtuple('GlobalParams', [
|
||||
'drop_connect_rate', 'width_coefficient', 'depth_coefficient',
|
||||
'depth_divisor', 'image_size'
|
||||
])
|
||||
global_params = GlobalParams(
|
||||
drop_connect_rate=0.3,
|
||||
width_coefficient=1.2,
|
||||
depth_coefficient=1.4,
|
||||
depth_divisor=8,
|
||||
image_size=64)
|
||||
return global_params
|
||||
|
||||
@staticmethod
|
||||
def get_block_params():
|
||||
BlockParams = namedtuple('BlockParams', [
|
||||
'kernel_size', 'num_repeat', 'input_filters', 'output_filters',
|
||||
'expand_ratio', 'id_skip', 'se_ratio', 'stride'
|
||||
])
|
||||
block_params = [
|
||||
BlockParams(3, 1, 32, 16, 1, True, 0.25, 1),
|
||||
BlockParams(3, 2, 16, 24, 6, True, 0.25, 2),
|
||||
BlockParams(5, 2, 24, 40, 6, True, 0.25, 2),
|
||||
BlockParams(3, 3, 40, 80, 6, True, 0.25, 2),
|
||||
BlockParams(5, 3, 80, 112, 6, True, 0.25, 1),
|
||||
BlockParams(5, 4, 112, 192, 6, True, 0.25, 2),
|
||||
BlockParams(3, 1, 192, 320, 6, True, 0.25, 1)
|
||||
]
|
||||
return block_params
|
||||
|
||||
|
||||
class EffUtils:
|
||||
@staticmethod
|
||||
def round_filters(filters, global_params):
|
||||
"""Calculate and round number of filters based on depth multiplier."""
|
||||
multiplier = global_params.width_coefficient
|
||||
if not multiplier:
|
||||
return filters
|
||||
divisor = global_params.depth_divisor
|
||||
filters *= multiplier
|
||||
new_filters = int(filters + divisor / 2) // divisor * divisor
|
||||
if new_filters < 0.9 * filters:
|
||||
new_filters += divisor
|
||||
return int(new_filters)
|
||||
|
||||
@staticmethod
|
||||
def round_repeats(repeats, global_params):
|
||||
"""Round number of filters based on depth multiplier."""
|
||||
multiplier = global_params.depth_coefficient
|
||||
if not multiplier:
|
||||
return repeats
|
||||
return int(math.ceil(multiplier * repeats))
|
||||
|
||||
|
||||
class ConvBlock(nn.Layer):
|
||||
def __init__(self, block_params):
|
||||
super(ConvBlock, self).__init__()
|
||||
self.block_args = block_params
|
||||
self.has_se = (self.block_args.se_ratio is not None) and \
|
||||
(0 < self.block_args.se_ratio <= 1)
|
||||
self.id_skip = block_params.id_skip
|
||||
|
||||
# expansion phase
|
||||
self.input_filters = self.block_args.input_filters
|
||||
output_filters = \
|
||||
self.block_args.input_filters * self.block_args.expand_ratio
|
||||
if self.block_args.expand_ratio != 1:
|
||||
self.expand_conv = nn.Conv2D(
|
||||
self.input_filters, output_filters, 1, bias_attr=False)
|
||||
self.bn0 = nn.BatchNorm(output_filters)
|
||||
|
||||
# depthwise conv phase
|
||||
k = self.block_args.kernel_size
|
||||
s = self.block_args.stride
|
||||
self.depthwise_conv = nn.Conv2D(
|
||||
output_filters,
|
||||
output_filters,
|
||||
groups=output_filters,
|
||||
kernel_size=k,
|
||||
stride=s,
|
||||
padding='same',
|
||||
bias_attr=False)
|
||||
self.bn1 = nn.BatchNorm(output_filters)
|
||||
|
||||
# squeeze and excitation layer, if desired
|
||||
if self.has_se:
|
||||
num_squeezed_channels = max(1,
|
||||
int(self.block_args.input_filters *
|
||||
self.block_args.se_ratio))
|
||||
self.se_reduce = nn.Conv2D(output_filters, num_squeezed_channels, 1)
|
||||
self.se_expand = nn.Conv2D(num_squeezed_channels, output_filters, 1)
|
||||
|
||||
# output phase
|
||||
self.final_oup = self.block_args.output_filters
|
||||
self.project_conv = nn.Conv2D(
|
||||
output_filters, self.final_oup, 1, bias_attr=False)
|
||||
self.bn2 = nn.BatchNorm(self.final_oup)
|
||||
self.swish = nn.Swish()
|
||||
|
||||
def drop_connect(self, inputs, p, training):
|
||||
if not training:
|
||||
return inputs
|
||||
|
||||
batch_size = inputs.shape[0]
|
||||
keep_prob = 1 - p
|
||||
random_tensor = keep_prob
|
||||
random_tensor += paddle.rand([batch_size, 1, 1, 1], dtype=inputs.dtype)
|
||||
random_tensor = paddle.to_tensor(random_tensor, place=inputs.place)
|
||||
binary_tensor = paddle.floor(random_tensor)
|
||||
output = inputs / keep_prob * binary_tensor
|
||||
return output
|
||||
|
||||
def forward(self, inputs, drop_connect_rate=None):
|
||||
# expansion and depthwise conv
|
||||
x = inputs
|
||||
if self.block_args.expand_ratio != 1:
|
||||
x = self.swish(self.bn0(self.expand_conv(inputs)))
|
||||
x = self.swish(self.bn1(self.depthwise_conv(x)))
|
||||
|
||||
# squeeze and excitation
|
||||
if self.has_se:
|
||||
x_squeezed = F.adaptive_avg_pool2d(x, 1)
|
||||
x_squeezed = self.se_expand(self.swish(self.se_reduce(x_squeezed)))
|
||||
x = F.sigmoid(x_squeezed) * x
|
||||
x = self.bn2(self.project_conv(x))
|
||||
|
||||
# skip conntection and drop connect
|
||||
if self.id_skip and self.block_args.stride == 1 and \
|
||||
self.input_filters == self.final_oup:
|
||||
if drop_connect_rate:
|
||||
x = self.drop_connect(
|
||||
x, p=drop_connect_rate, training=self.training)
|
||||
x = x + inputs
|
||||
return x
|
||||
|
||||
|
||||
class EfficientNetb3_PREN(nn.Layer):
|
||||
def __init__(self, in_channels):
|
||||
super(EfficientNetb3_PREN, self).__init__()
|
||||
self.blocks_params = EffB3Params.get_block_params()
|
||||
self.global_params = EffB3Params.get_global_params()
|
||||
self.out_channels = []
|
||||
# stem
|
||||
stem_channels = EffUtils.round_filters(32, self.global_params)
|
||||
self.conv_stem = nn.Conv2D(
|
||||
in_channels, stem_channels, 3, 2, padding='same', bias_attr=False)
|
||||
self.bn0 = nn.BatchNorm(stem_channels)
|
||||
|
||||
self.blocks = []
|
||||
# to extract three feature maps for fpn based on efficientnetb3 backbone
|
||||
self.concerned_block_idxes = [7, 17, 25]
|
||||
concerned_idx = 0
|
||||
for i, block_params in enumerate(self.blocks_params):
|
||||
block_params = block_params._replace(
|
||||
input_filters=EffUtils.round_filters(block_params.input_filters,
|
||||
self.global_params),
|
||||
output_filters=EffUtils.round_filters(
|
||||
block_params.output_filters, self.global_params),
|
||||
num_repeat=EffUtils.round_repeats(block_params.num_repeat,
|
||||
self.global_params))
|
||||
self.blocks.append(
|
||||
self.add_sublayer("{}-0".format(i), ConvBlock(block_params)))
|
||||
concerned_idx += 1
|
||||
if concerned_idx in self.concerned_block_idxes:
|
||||
self.out_channels.append(block_params.output_filters)
|
||||
if block_params.num_repeat > 1:
|
||||
block_params = block_params._replace(
|
||||
input_filters=block_params.output_filters, stride=1)
|
||||
for j in range(block_params.num_repeat - 1):
|
||||
self.blocks.append(
|
||||
self.add_sublayer('{}-{}'.format(i, j + 1),
|
||||
ConvBlock(block_params)))
|
||||
concerned_idx += 1
|
||||
if concerned_idx in self.concerned_block_idxes:
|
||||
self.out_channels.append(block_params.output_filters)
|
||||
|
||||
self.swish = nn.Swish()
|
||||
|
||||
def forward(self, inputs):
|
||||
outs = []
|
||||
|
||||
x = self.swish(self.bn0(self.conv_stem(inputs)))
|
||||
for idx, block in enumerate(self.blocks):
|
||||
drop_connect_rate = self.global_params.drop_connect_rate
|
||||
if drop_connect_rate:
|
||||
drop_connect_rate *= float(idx) / len(self.blocks)
|
||||
x = block(x, drop_connect_rate=drop_connect_rate)
|
||||
if idx in self.concerned_block_idxes:
|
||||
outs.append(x)
|
||||
return outs
|
||||
@@ -21,6 +21,7 @@ def build_head(config):
|
||||
from .det_east_head import EASTHead
|
||||
from .det_sast_head import SASTHead
|
||||
from .det_pse_head import PSEHead
|
||||
from .det_fce_head import FCEHead
|
||||
from .e2e_pg_head import PGHead
|
||||
|
||||
# rec head
|
||||
@@ -30,6 +31,7 @@ def build_head(config):
|
||||
from .rec_nrtr_head import Transformer
|
||||
from .rec_sar_head import SARHead
|
||||
from .rec_aster_head import AsterHead
|
||||
from .rec_pren_head import PRENHead
|
||||
|
||||
# cls head
|
||||
from .cls_head import ClsHead
|
||||
@@ -40,9 +42,9 @@ def build_head(config):
|
||||
from .table_att_head import TableAttentionHead
|
||||
|
||||
support_dict = [
|
||||
'DBHead', 'PSEHead', 'EASTHead', 'SASTHead', 'CTCHead', 'ClsHead',
|
||||
'AttentionHead', 'SRNHead', 'PGHead', 'Transformer',
|
||||
'TableAttentionHead', 'SARHead', 'AsterHead', 'SDMGRHead'
|
||||
'DBHead', 'PSEHead', 'FCEHead', 'EASTHead', 'SASTHead', 'CTCHead',
|
||||
'ClsHead', 'AttentionHead', 'SRNHead', 'PGHead', 'Transformer',
|
||||
'TableAttentionHead', 'SARHead', 'AsterHead', 'SDMGRHead', 'PRENHead'
|
||||
]
|
||||
|
||||
#table head
|
||||
|
||||
@@ -0,0 +1,99 @@
|
||||
# copyright (c) 2022 PaddlePaddle Authors. All Rights Reserve.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
"""
|
||||
This code is refer from:
|
||||
https://github.com/open-mmlab/mmocr/blob/main/mmocr/models/textdet/dense_heads/fce_head.py
|
||||
"""
|
||||
|
||||
from paddle import nn
|
||||
from paddle import ParamAttr
|
||||
import paddle.nn.functional as F
|
||||
from paddle.nn.initializer import Normal
|
||||
import paddle
|
||||
from functools import partial
|
||||
|
||||
|
||||
def multi_apply(func, *args, **kwargs):
|
||||
pfunc = partial(func, **kwargs) if kwargs else func
|
||||
map_results = map(pfunc, *args)
|
||||
return tuple(map(list, zip(*map_results)))
|
||||
|
||||
|
||||
class FCEHead(nn.Layer):
|
||||
"""The class for implementing FCENet head.
|
||||
FCENet(CVPR2021): Fourier Contour Embedding for Arbitrary-shaped Text
|
||||
Detection.
|
||||
|
||||
[https://arxiv.org/abs/2104.10442]
|
||||
|
||||
Args:
|
||||
in_channels (int): The number of input channels.
|
||||
scales (list[int]) : The scale of each layer.
|
||||
fourier_degree (int) : The maximum Fourier transform degree k.
|
||||
"""
|
||||
|
||||
def __init__(self, in_channels, fourier_degree=5):
|
||||
super().__init__()
|
||||
assert isinstance(in_channels, int)
|
||||
|
||||
self.downsample_ratio = 1.0
|
||||
self.in_channels = in_channels
|
||||
self.fourier_degree = fourier_degree
|
||||
self.out_channels_cls = 4
|
||||
self.out_channels_reg = (2 * self.fourier_degree + 1) * 2
|
||||
|
||||
self.out_conv_cls = nn.Conv2D(
|
||||
in_channels=self.in_channels,
|
||||
out_channels=self.out_channels_cls,
|
||||
kernel_size=3,
|
||||
stride=1,
|
||||
padding=1,
|
||||
groups=1,
|
||||
weight_attr=ParamAttr(
|
||||
name='cls_weights',
|
||||
initializer=Normal(
|
||||
mean=paddle.to_tensor(0.), std=paddle.to_tensor(0.01))),
|
||||
bias_attr=True)
|
||||
self.out_conv_reg = nn.Conv2D(
|
||||
in_channels=self.in_channels,
|
||||
out_channels=self.out_channels_reg,
|
||||
kernel_size=3,
|
||||
stride=1,
|
||||
padding=1,
|
||||
groups=1,
|
||||
weight_attr=ParamAttr(
|
||||
name='reg_weights',
|
||||
initializer=Normal(
|
||||
mean=paddle.to_tensor(0.), std=paddle.to_tensor(0.01))),
|
||||
bias_attr=True)
|
||||
|
||||
def forward(self, feats, targets=None):
|
||||
cls_res, reg_res = multi_apply(self.forward_single, feats)
|
||||
level_num = len(cls_res)
|
||||
outs = {}
|
||||
if not self.training:
|
||||
for i in range(level_num):
|
||||
tr_pred = F.softmax(cls_res[i][:, 0:2, :, :], axis=1)
|
||||
tcl_pred = F.softmax(cls_res[i][:, 2:, :, :], axis=1)
|
||||
outs['level_{}'.format(i)] = paddle.concat(
|
||||
[tr_pred, tcl_pred, reg_res[i]], axis=1)
|
||||
else:
|
||||
preds = [[cls_res[i], reg_res[i]] for i in range(level_num)]
|
||||
outs['levels'] = preds
|
||||
return outs
|
||||
|
||||
def forward_single(self, x):
|
||||
cls_predict = self.out_conv_cls(x)
|
||||
reg_predict = self.out_conv_reg(x)
|
||||
return cls_predict, reg_predict
|
||||
@@ -0,0 +1,34 @@
|
||||
# copyright (c) 2022 PaddlePaddle Authors. All Rights Reserve.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
from __future__ import absolute_import
|
||||
from __future__ import division
|
||||
from __future__ import print_function
|
||||
|
||||
from paddle import nn
|
||||
from paddle.nn import functional as F
|
||||
|
||||
|
||||
class PRENHead(nn.Layer):
|
||||
def __init__(self, in_channels, out_channels, **kwargs):
|
||||
super(PRENHead, self).__init__()
|
||||
self.linear = nn.Linear(in_channels, out_channels)
|
||||
|
||||
def forward(self, x, targets=None):
|
||||
predicts = self.linear(x)
|
||||
|
||||
if not self.training:
|
||||
predicts = F.softmax(predicts, axis=2)
|
||||
|
||||
return predicts
|
||||
@@ -23,7 +23,12 @@ def build_neck(config):
|
||||
from .pg_fpn import PGFPN
|
||||
from .table_fpn import TableFPN
|
||||
from .fpn import FPN
|
||||
support_dict = ['FPN','DBFPN', 'EASTFPN', 'SASTFPN', 'SequenceEncoder', 'PGFPN', 'TableFPN']
|
||||
from .fce_fpn import FCEFPN
|
||||
from .pren_fpn import PRENFPN
|
||||
support_dict = [
|
||||
'FPN', 'FCEFPN', 'DBFPN', 'EASTFPN', 'SASTFPN', 'SequenceEncoder',
|
||||
'PGFPN', 'TableFPN', 'PRENFPN'
|
||||
]
|
||||
|
||||
module_name = config.pop('name')
|
||||
assert module_name in support_dict, Exception('neck only support {}'.format(
|
||||
|
||||
@@ -0,0 +1,280 @@
|
||||
# copyright (c) 2022 PaddlePaddle Authors. All Rights Reserve.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
"""
|
||||
This code is refer from:
|
||||
https://github.com/PaddlePaddle/PaddleDetection/blob/release/2.3/ppdet/modeling/necks/fpn.py
|
||||
"""
|
||||
|
||||
import paddle.nn as nn
|
||||
import paddle.nn.functional as F
|
||||
from paddle import ParamAttr
|
||||
from paddle.nn.initializer import XavierUniform
|
||||
from paddle.nn.initializer import Normal
|
||||
from paddle.regularizer import L2Decay
|
||||
|
||||
__all__ = ['FCEFPN']
|
||||
|
||||
|
||||
class ConvNormLayer(nn.Layer):
|
||||
def __init__(self,
|
||||
ch_in,
|
||||
ch_out,
|
||||
filter_size,
|
||||
stride,
|
||||
groups=1,
|
||||
norm_type='bn',
|
||||
norm_decay=0.,
|
||||
norm_groups=32,
|
||||
lr_scale=1.,
|
||||
freeze_norm=False,
|
||||
initializer=Normal(
|
||||
mean=0., std=0.01)):
|
||||
super(ConvNormLayer, self).__init__()
|
||||
assert norm_type in ['bn', 'sync_bn', 'gn']
|
||||
|
||||
bias_attr = False
|
||||
|
||||
self.conv = nn.Conv2D(
|
||||
in_channels=ch_in,
|
||||
out_channels=ch_out,
|
||||
kernel_size=filter_size,
|
||||
stride=stride,
|
||||
padding=(filter_size - 1) // 2,
|
||||
groups=groups,
|
||||
weight_attr=ParamAttr(
|
||||
initializer=initializer, learning_rate=1.),
|
||||
bias_attr=bias_attr)
|
||||
|
||||
norm_lr = 0. if freeze_norm else 1.
|
||||
param_attr = ParamAttr(
|
||||
learning_rate=norm_lr,
|
||||
regularizer=L2Decay(norm_decay) if norm_decay is not None else None)
|
||||
bias_attr = ParamAttr(
|
||||
learning_rate=norm_lr,
|
||||
regularizer=L2Decay(norm_decay) if norm_decay is not None else None)
|
||||
if norm_type == 'bn':
|
||||
self.norm = nn.BatchNorm2D(
|
||||
ch_out, weight_attr=param_attr, bias_attr=bias_attr)
|
||||
elif norm_type == 'sync_bn':
|
||||
self.norm = nn.SyncBatchNorm(
|
||||
ch_out, weight_attr=param_attr, bias_attr=bias_attr)
|
||||
elif norm_type == 'gn':
|
||||
self.norm = nn.GroupNorm(
|
||||
num_groups=norm_groups,
|
||||
num_channels=ch_out,
|
||||
weight_attr=param_attr,
|
||||
bias_attr=bias_attr)
|
||||
|
||||
def forward(self, inputs):
|
||||
out = self.conv(inputs)
|
||||
out = self.norm(out)
|
||||
return out
|
||||
|
||||
|
||||
class FCEFPN(nn.Layer):
|
||||
"""
|
||||
Feature Pyramid Network, see https://arxiv.org/abs/1612.03144
|
||||
Args:
|
||||
in_channels (list[int]): input channels of each level which can be
|
||||
derived from the output shape of backbone by from_config
|
||||
out_channels (list[int]): output channel of each level
|
||||
spatial_scales (list[float]): the spatial scales between input feature
|
||||
maps and original input image which can be derived from the output
|
||||
shape of backbone by from_config
|
||||
has_extra_convs (bool): whether to add extra conv to the last level.
|
||||
default False
|
||||
extra_stage (int): the number of extra stages added to the last level.
|
||||
default 1
|
||||
use_c5 (bool): Whether to use c5 as the input of extra stage,
|
||||
otherwise p5 is used. default True
|
||||
norm_type (string|None): The normalization type in FPN module. If
|
||||
norm_type is None, norm will not be used after conv and if
|
||||
norm_type is string, bn, gn, sync_bn are available. default None
|
||||
norm_decay (float): weight decay for normalization layer weights.
|
||||
default 0.
|
||||
freeze_norm (bool): whether to freeze normalization layer.
|
||||
default False
|
||||
relu_before_extra_convs (bool): whether to add relu before extra convs.
|
||||
default False
|
||||
|
||||
"""
|
||||
|
||||
def __init__(self,
|
||||
in_channels,
|
||||
out_channels,
|
||||
spatial_scales=[0.25, 0.125, 0.0625, 0.03125],
|
||||
has_extra_convs=False,
|
||||
extra_stage=1,
|
||||
use_c5=True,
|
||||
norm_type=None,
|
||||
norm_decay=0.,
|
||||
freeze_norm=False,
|
||||
relu_before_extra_convs=True):
|
||||
super(FCEFPN, self).__init__()
|
||||
self.out_channels = out_channels
|
||||
for s in range(extra_stage):
|
||||
spatial_scales = spatial_scales + [spatial_scales[-1] / 2.]
|
||||
self.spatial_scales = spatial_scales
|
||||
self.has_extra_convs = has_extra_convs
|
||||
self.extra_stage = extra_stage
|
||||
self.use_c5 = use_c5
|
||||
self.relu_before_extra_convs = relu_before_extra_convs
|
||||
self.norm_type = norm_type
|
||||
self.norm_decay = norm_decay
|
||||
self.freeze_norm = freeze_norm
|
||||
|
||||
self.lateral_convs = []
|
||||
self.fpn_convs = []
|
||||
fan = out_channels * 3 * 3
|
||||
|
||||
# stage index 0,1,2,3 stands for res2,res3,res4,res5 on ResNet Backbone
|
||||
# 0 <= st_stage < ed_stage <= 3
|
||||
st_stage = 4 - len(in_channels)
|
||||
ed_stage = st_stage + len(in_channels) - 1
|
||||
for i in range(st_stage, ed_stage + 1):
|
||||
if i == 3:
|
||||
lateral_name = 'fpn_inner_res5_sum'
|
||||
else:
|
||||
lateral_name = 'fpn_inner_res{}_sum_lateral'.format(i + 2)
|
||||
in_c = in_channels[i - st_stage]
|
||||
if self.norm_type is not None:
|
||||
lateral = self.add_sublayer(
|
||||
lateral_name,
|
||||
ConvNormLayer(
|
||||
ch_in=in_c,
|
||||
ch_out=out_channels,
|
||||
filter_size=1,
|
||||
stride=1,
|
||||
norm_type=self.norm_type,
|
||||
norm_decay=self.norm_decay,
|
||||
freeze_norm=self.freeze_norm,
|
||||
initializer=XavierUniform(fan_out=in_c)))
|
||||
else:
|
||||
lateral = self.add_sublayer(
|
||||
lateral_name,
|
||||
nn.Conv2D(
|
||||
in_channels=in_c,
|
||||
out_channels=out_channels,
|
||||
kernel_size=1,
|
||||
weight_attr=ParamAttr(
|
||||
initializer=XavierUniform(fan_out=in_c))))
|
||||
self.lateral_convs.append(lateral)
|
||||
|
||||
for i in range(st_stage, ed_stage + 1):
|
||||
fpn_name = 'fpn_res{}_sum'.format(i + 2)
|
||||
if self.norm_type is not None:
|
||||
fpn_conv = self.add_sublayer(
|
||||
fpn_name,
|
||||
ConvNormLayer(
|
||||
ch_in=out_channels,
|
||||
ch_out=out_channels,
|
||||
filter_size=3,
|
||||
stride=1,
|
||||
norm_type=self.norm_type,
|
||||
norm_decay=self.norm_decay,
|
||||
freeze_norm=self.freeze_norm,
|
||||
initializer=XavierUniform(fan_out=fan)))
|
||||
else:
|
||||
fpn_conv = self.add_sublayer(
|
||||
fpn_name,
|
||||
nn.Conv2D(
|
||||
in_channels=out_channels,
|
||||
out_channels=out_channels,
|
||||
kernel_size=3,
|
||||
padding=1,
|
||||
weight_attr=ParamAttr(
|
||||
initializer=XavierUniform(fan_out=fan))))
|
||||
self.fpn_convs.append(fpn_conv)
|
||||
|
||||
# add extra conv levels for RetinaNet(use_c5)/FCOS(use_p5)
|
||||
if self.has_extra_convs:
|
||||
for i in range(self.extra_stage):
|
||||
lvl = ed_stage + 1 + i
|
||||
if i == 0 and self.use_c5:
|
||||
in_c = in_channels[-1]
|
||||
else:
|
||||
in_c = out_channels
|
||||
extra_fpn_name = 'fpn_{}'.format(lvl + 2)
|
||||
if self.norm_type is not None:
|
||||
extra_fpn_conv = self.add_sublayer(
|
||||
extra_fpn_name,
|
||||
ConvNormLayer(
|
||||
ch_in=in_c,
|
||||
ch_out=out_channels,
|
||||
filter_size=3,
|
||||
stride=2,
|
||||
norm_type=self.norm_type,
|
||||
norm_decay=self.norm_decay,
|
||||
freeze_norm=self.freeze_norm,
|
||||
initializer=XavierUniform(fan_out=fan)))
|
||||
else:
|
||||
extra_fpn_conv = self.add_sublayer(
|
||||
extra_fpn_name,
|
||||
nn.Conv2D(
|
||||
in_channels=in_c,
|
||||
out_channels=out_channels,
|
||||
kernel_size=3,
|
||||
stride=2,
|
||||
padding=1,
|
||||
weight_attr=ParamAttr(
|
||||
initializer=XavierUniform(fan_out=fan))))
|
||||
self.fpn_convs.append(extra_fpn_conv)
|
||||
|
||||
@classmethod
|
||||
def from_config(cls, cfg, input_shape):
|
||||
return {
|
||||
'in_channels': [i.channels for i in input_shape],
|
||||
'spatial_scales': [1.0 / i.stride for i in input_shape],
|
||||
}
|
||||
|
||||
def forward(self, body_feats):
|
||||
laterals = []
|
||||
num_levels = len(body_feats)
|
||||
|
||||
for i in range(num_levels):
|
||||
laterals.append(self.lateral_convs[i](body_feats[i]))
|
||||
|
||||
for i in range(1, num_levels):
|
||||
lvl = num_levels - i
|
||||
upsample = F.interpolate(
|
||||
laterals[lvl],
|
||||
scale_factor=2.,
|
||||
mode='nearest', )
|
||||
laterals[lvl - 1] += upsample
|
||||
|
||||
fpn_output = []
|
||||
for lvl in range(num_levels):
|
||||
fpn_output.append(self.fpn_convs[lvl](laterals[lvl]))
|
||||
|
||||
if self.extra_stage > 0:
|
||||
# use max pool to get more levels on top of outputs (Faster R-CNN, Mask R-CNN)
|
||||
if not self.has_extra_convs:
|
||||
assert self.extra_stage == 1, 'extra_stage should be 1 if FPN has not extra convs'
|
||||
fpn_output.append(F.max_pool2d(fpn_output[-1], 1, stride=2))
|
||||
# add extra conv levels for RetinaNet(use_c5)/FCOS(use_p5)
|
||||
else:
|
||||
if self.use_c5:
|
||||
extra_source = body_feats[-1]
|
||||
else:
|
||||
extra_source = fpn_output[-1]
|
||||
fpn_output.append(self.fpn_convs[num_levels](extra_source))
|
||||
|
||||
for i in range(1, self.extra_stage):
|
||||
if self.relu_before_extra_convs:
|
||||
fpn_output.append(self.fpn_convs[num_levels + i](F.relu(
|
||||
fpn_output[-1])))
|
||||
else:
|
||||
fpn_output.append(self.fpn_convs[num_levels + i](
|
||||
fpn_output[-1]))
|
||||
return fpn_output
|
||||
@@ -0,0 +1,163 @@
|
||||
# copyright (c) 2022 PaddlePaddle Authors. All Rights Reserve.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
"""
|
||||
Code is refer from:
|
||||
https://github.com/RuijieJ/pren/blob/main/Nets/Aggregation.py
|
||||
"""
|
||||
|
||||
from __future__ import absolute_import
|
||||
from __future__ import division
|
||||
from __future__ import print_function
|
||||
|
||||
import paddle
|
||||
from paddle import nn
|
||||
import paddle.nn.functional as F
|
||||
|
||||
|
||||
class PoolAggregate(nn.Layer):
|
||||
def __init__(self, n_r, d_in, d_middle=None, d_out=None):
|
||||
super(PoolAggregate, self).__init__()
|
||||
if not d_middle:
|
||||
d_middle = d_in
|
||||
if not d_out:
|
||||
d_out = d_in
|
||||
|
||||
self.d_in = d_in
|
||||
self.d_middle = d_middle
|
||||
self.d_out = d_out
|
||||
self.act = nn.Swish()
|
||||
|
||||
self.n_r = n_r
|
||||
self.aggs = self._build_aggs()
|
||||
|
||||
def _build_aggs(self):
|
||||
aggs = []
|
||||
for i in range(self.n_r):
|
||||
aggs.append(
|
||||
self.add_sublayer(
|
||||
'{}'.format(i),
|
||||
nn.Sequential(
|
||||
('conv1', nn.Conv2D(
|
||||
self.d_in, self.d_middle, 3, 2, 1, bias_attr=False)
|
||||
), ('bn1', nn.BatchNorm(self.d_middle)),
|
||||
('act', self.act), ('conv2', nn.Conv2D(
|
||||
self.d_middle, self.d_out, 3, 2, 1, bias_attr=False
|
||||
)), ('bn2', nn.BatchNorm(self.d_out)))))
|
||||
return aggs
|
||||
|
||||
def forward(self, x):
|
||||
b = x.shape[0]
|
||||
outs = []
|
||||
for agg in self.aggs:
|
||||
y = agg(x)
|
||||
p = F.adaptive_avg_pool2d(y, 1)
|
||||
outs.append(p.reshape((b, 1, self.d_out)))
|
||||
out = paddle.concat(outs, 1)
|
||||
return out
|
||||
|
||||
|
||||
class WeightAggregate(nn.Layer):
|
||||
def __init__(self, n_r, d_in, d_middle=None, d_out=None):
|
||||
super(WeightAggregate, self).__init__()
|
||||
if not d_middle:
|
||||
d_middle = d_in
|
||||
if not d_out:
|
||||
d_out = d_in
|
||||
|
||||
self.n_r = n_r
|
||||
self.d_out = d_out
|
||||
self.act = nn.Swish()
|
||||
|
||||
self.conv_n = nn.Sequential(
|
||||
('conv1', nn.Conv2D(
|
||||
d_in, d_in, 3, 1, 1,
|
||||
bias_attr=False)), ('bn1', nn.BatchNorm(d_in)),
|
||||
('act1', self.act), ('conv2', nn.Conv2D(
|
||||
d_in, n_r, 1, bias_attr=False)), ('bn2', nn.BatchNorm(n_r)),
|
||||
('act2', nn.Sigmoid()))
|
||||
self.conv_d = nn.Sequential(
|
||||
('conv1', nn.Conv2D(
|
||||
d_in, d_middle, 3, 1, 1,
|
||||
bias_attr=False)), ('bn1', nn.BatchNorm(d_middle)),
|
||||
('act1', self.act), ('conv2', nn.Conv2D(
|
||||
d_middle, d_out, 1,
|
||||
bias_attr=False)), ('bn2', nn.BatchNorm(d_out)))
|
||||
|
||||
def forward(self, x):
|
||||
b, _, h, w = x.shape
|
||||
|
||||
hmaps = self.conv_n(x)
|
||||
fmaps = self.conv_d(x)
|
||||
r = paddle.bmm(
|
||||
hmaps.reshape((b, self.n_r, h * w)),
|
||||
fmaps.reshape((b, self.d_out, h * w)).transpose((0, 2, 1)))
|
||||
return r
|
||||
|
||||
|
||||
class GCN(nn.Layer):
|
||||
def __init__(self, d_in, n_in, d_out=None, n_out=None, dropout=0.1):
|
||||
super(GCN, self).__init__()
|
||||
if not d_out:
|
||||
d_out = d_in
|
||||
if not n_out:
|
||||
n_out = d_in
|
||||
|
||||
self.conv_n = nn.Conv1D(n_in, n_out, 1)
|
||||
self.linear = nn.Linear(d_in, d_out)
|
||||
self.dropout = nn.Dropout(dropout)
|
||||
self.act = nn.Swish()
|
||||
|
||||
def forward(self, x):
|
||||
x = self.conv_n(x)
|
||||
x = self.dropout(self.linear(x))
|
||||
return self.act(x)
|
||||
|
||||
|
||||
class PRENFPN(nn.Layer):
|
||||
def __init__(self, in_channels, n_r, d_model, max_len, dropout):
|
||||
super(PRENFPN, self).__init__()
|
||||
assert len(in_channels) == 3, "in_channels' length must be 3."
|
||||
c1, c2, c3 = in_channels # the depths are from big to small
|
||||
# build fpn
|
||||
assert d_model % 3 == 0, "{} can't be divided by 3.".format(d_model)
|
||||
self.agg_p1 = PoolAggregate(n_r, c1, d_out=d_model // 3)
|
||||
self.agg_p2 = PoolAggregate(n_r, c2, d_out=d_model // 3)
|
||||
self.agg_p3 = PoolAggregate(n_r, c3, d_out=d_model // 3)
|
||||
|
||||
self.agg_w1 = WeightAggregate(n_r, c1, 4 * c1, d_model // 3)
|
||||
self.agg_w2 = WeightAggregate(n_r, c2, 4 * c2, d_model // 3)
|
||||
self.agg_w3 = WeightAggregate(n_r, c3, 4 * c3, d_model // 3)
|
||||
|
||||
self.gcn_pool = GCN(d_model, n_r, d_model, max_len, dropout)
|
||||
self.gcn_weight = GCN(d_model, n_r, d_model, max_len, dropout)
|
||||
|
||||
self.out_channels = d_model
|
||||
|
||||
def forward(self, inputs):
|
||||
f3, f5, f7 = inputs
|
||||
|
||||
rp1 = self.agg_p1(f3)
|
||||
rp2 = self.agg_p2(f5)
|
||||
rp3 = self.agg_p3(f7)
|
||||
rp = paddle.concat([rp1, rp2, rp3], 2) # [b,nr,d]
|
||||
|
||||
rw1 = self.agg_w1(f3)
|
||||
rw2 = self.agg_w2(f5)
|
||||
rw3 = self.agg_w3(f7)
|
||||
rw = paddle.concat([rw1, rw2, rw3], 2) # [b,nr,d]
|
||||
|
||||
y1 = self.gcn_pool(rp)
|
||||
y2 = self.gcn_weight(rw)
|
||||
y = 0.5 * (y1 + y2)
|
||||
return y # [b,max_len,d]
|
||||
@@ -24,8 +24,10 @@ __all__ = ['build_post_process']
|
||||
from .db_postprocess import DBPostProcess, DistillationDBPostProcess
|
||||
from .east_postprocess import EASTPostProcess
|
||||
from .sast_postprocess import SASTPostProcess
|
||||
from .rec_postprocess import CTCLabelDecode, AttnLabelDecode, SRNLabelDecode, DistillationCTCLabelDecode, \
|
||||
TableLabelDecode, NRTRLabelDecode, SARLabelDecode, SEEDLabelDecode
|
||||
from .fce_postprocess import FCEPostProcess
|
||||
from .rec_postprocess import CTCLabelDecode, AttnLabelDecode, SRNLabelDecode, \
|
||||
DistillationCTCLabelDecode, TableLabelDecode, NRTRLabelDecode, SARLabelDecode, \
|
||||
SEEDLabelDecode, PRENLabelDecode
|
||||
from .cls_postprocess import ClsPostProcess
|
||||
from .pg_postprocess import PGPostProcess
|
||||
from .vqa_token_ser_layoutlm_postprocess import VQASerTokenLayoutLMPostProcess
|
||||
@@ -34,12 +36,12 @@ from .vqa_token_re_layoutlm_postprocess import VQAReTokenLayoutLMPostProcess
|
||||
|
||||
def build_post_process(config, global_config=None):
|
||||
support_dict = [
|
||||
'DBPostProcess', 'EASTPostProcess', 'SASTPostProcess', 'CTCLabelDecode',
|
||||
'AttnLabelDecode', 'ClsPostProcess', 'SRNLabelDecode', 'PGPostProcess',
|
||||
'DistillationCTCLabelDecode', 'TableLabelDecode',
|
||||
'DBPostProcess', 'EASTPostProcess', 'SASTPostProcess', 'FCEPostProcess',
|
||||
'CTCLabelDecode', 'AttnLabelDecode', 'ClsPostProcess', 'SRNLabelDecode',
|
||||
'PGPostProcess', 'DistillationCTCLabelDecode', 'TableLabelDecode',
|
||||
'DistillationDBPostProcess', 'NRTRLabelDecode', 'SARLabelDecode',
|
||||
'SEEDLabelDecode', 'VQASerTokenLayoutLMPostProcess',
|
||||
'VQAReTokenLayoutLMPostProcess'
|
||||
'VQAReTokenLayoutLMPostProcess', 'PRENLabelDecode'
|
||||
]
|
||||
|
||||
if config['name'] == 'PSEPostProcess':
|
||||
|
||||
@@ -0,0 +1,241 @@
|
||||
# copyright (c) 2022 PaddlePaddle Authors. All Rights Reserve.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
"""
|
||||
This code is refer from:
|
||||
https://github.com/open-mmlab/mmocr/blob/v0.3.0/mmocr/models/textdet/postprocess/wrapper.py
|
||||
"""
|
||||
|
||||
import cv2
|
||||
import paddle
|
||||
import numpy as np
|
||||
from numpy.fft import ifft
|
||||
from ppocr.utils.poly_nms import poly_nms, valid_boundary
|
||||
|
||||
|
||||
def fill_hole(input_mask):
|
||||
h, w = input_mask.shape
|
||||
canvas = np.zeros((h + 2, w + 2), np.uint8)
|
||||
canvas[1:h + 1, 1:w + 1] = input_mask.copy()
|
||||
|
||||
mask = np.zeros((h + 4, w + 4), np.uint8)
|
||||
|
||||
cv2.floodFill(canvas, mask, (0, 0), 1)
|
||||
canvas = canvas[1:h + 1, 1:w + 1].astype(np.bool)
|
||||
|
||||
return ~canvas | input_mask
|
||||
|
||||
|
||||
def fourier2poly(fourier_coeff, num_reconstr_points=50):
|
||||
""" Inverse Fourier transform
|
||||
Args:
|
||||
fourier_coeff (ndarray): Fourier coefficients shaped (n, 2k+1),
|
||||
with n and k being candidates number and Fourier degree
|
||||
respectively.
|
||||
num_reconstr_points (int): Number of reconstructed polygon points.
|
||||
Returns:
|
||||
Polygons (ndarray): The reconstructed polygons shaped (n, n')
|
||||
"""
|
||||
|
||||
a = np.zeros((len(fourier_coeff), num_reconstr_points), dtype='complex')
|
||||
k = (len(fourier_coeff[0]) - 1) // 2
|
||||
|
||||
a[:, 0:k + 1] = fourier_coeff[:, k:]
|
||||
a[:, -k:] = fourier_coeff[:, :k]
|
||||
|
||||
poly_complex = ifft(a) * num_reconstr_points
|
||||
polygon = np.zeros((len(fourier_coeff), num_reconstr_points, 2))
|
||||
polygon[:, :, 0] = poly_complex.real
|
||||
polygon[:, :, 1] = poly_complex.imag
|
||||
return polygon.astype('int32').reshape((len(fourier_coeff), -1))
|
||||
|
||||
|
||||
class FCEPostProcess(object):
|
||||
"""
|
||||
The post process for FCENet.
|
||||
"""
|
||||
|
||||
def __init__(self,
|
||||
scales,
|
||||
fourier_degree=5,
|
||||
num_reconstr_points=50,
|
||||
decoding_type='fcenet',
|
||||
score_thr=0.3,
|
||||
nms_thr=0.1,
|
||||
alpha=1.0,
|
||||
beta=1.0,
|
||||
box_type='poly',
|
||||
**kwargs):
|
||||
|
||||
self.scales = scales
|
||||
self.fourier_degree = fourier_degree
|
||||
self.num_reconstr_points = num_reconstr_points
|
||||
self.decoding_type = decoding_type
|
||||
self.score_thr = score_thr
|
||||
self.nms_thr = nms_thr
|
||||
self.alpha = alpha
|
||||
self.beta = beta
|
||||
self.box_type = box_type
|
||||
|
||||
def __call__(self, preds, shape_list):
|
||||
score_maps = []
|
||||
for key, value in preds.items():
|
||||
if isinstance(value, paddle.Tensor):
|
||||
value = value.numpy()
|
||||
cls_res = value[:, :4, :, :]
|
||||
reg_res = value[:, 4:, :, :]
|
||||
score_maps.append([cls_res, reg_res])
|
||||
|
||||
return self.get_boundary(score_maps, shape_list)
|
||||
|
||||
def resize_boundary(self, boundaries, scale_factor):
|
||||
"""Rescale boundaries via scale_factor.
|
||||
|
||||
Args:
|
||||
boundaries (list[list[float]]): The boundary list. Each boundary
|
||||
with size 2k+1 with k>=4.
|
||||
scale_factor(ndarray): The scale factor of size (4,).
|
||||
|
||||
Returns:
|
||||
boundaries (list[list[float]]): The scaled boundaries.
|
||||
"""
|
||||
boxes = []
|
||||
scores = []
|
||||
for b in boundaries:
|
||||
sz = len(b)
|
||||
valid_boundary(b, True)
|
||||
scores.append(b[-1])
|
||||
b = (np.array(b[:sz - 1]) *
|
||||
(np.tile(scale_factor[:2], int(
|
||||
(sz - 1) / 2)).reshape(1, sz - 1))).flatten().tolist()
|
||||
boxes.append(np.array(b).reshape([-1, 2]))
|
||||
|
||||
return np.array(boxes, dtype=np.float32), scores
|
||||
|
||||
def get_boundary(self, score_maps, shape_list):
|
||||
assert len(score_maps) == len(self.scales)
|
||||
boundaries = []
|
||||
for idx, score_map in enumerate(score_maps):
|
||||
scale = self.scales[idx]
|
||||
boundaries = boundaries + self._get_boundary_single(score_map,
|
||||
scale)
|
||||
|
||||
# nms
|
||||
boundaries = poly_nms(boundaries, self.nms_thr)
|
||||
boundaries, scores = self.resize_boundary(
|
||||
boundaries, (1 / shape_list[0, 2:]).tolist()[::-1])
|
||||
|
||||
boxes_batch = [dict(points=boundaries, scores=scores)]
|
||||
return boxes_batch
|
||||
|
||||
def _get_boundary_single(self, score_map, scale):
|
||||
assert len(score_map) == 2
|
||||
assert score_map[1].shape[1] == 4 * self.fourier_degree + 2
|
||||
|
||||
return self.fcenet_decode(
|
||||
preds=score_map,
|
||||
fourier_degree=self.fourier_degree,
|
||||
num_reconstr_points=self.num_reconstr_points,
|
||||
scale=scale,
|
||||
alpha=self.alpha,
|
||||
beta=self.beta,
|
||||
box_type=self.box_type,
|
||||
score_thr=self.score_thr,
|
||||
nms_thr=self.nms_thr)
|
||||
|
||||
def fcenet_decode(self,
|
||||
preds,
|
||||
fourier_degree,
|
||||
num_reconstr_points,
|
||||
scale,
|
||||
alpha=1.0,
|
||||
beta=2.0,
|
||||
box_type='poly',
|
||||
score_thr=0.3,
|
||||
nms_thr=0.1):
|
||||
"""Decoding predictions of FCENet to instances.
|
||||
|
||||
Args:
|
||||
preds (list(Tensor)): The head output tensors.
|
||||
fourier_degree (int): The maximum Fourier transform degree k.
|
||||
num_reconstr_points (int): The points number of the polygon
|
||||
reconstructed from predicted Fourier coefficients.
|
||||
scale (int): The down-sample scale of the prediction.
|
||||
alpha (float) : The parameter to calculate final scores. Score_{final}
|
||||
= (Score_{text region} ^ alpha)
|
||||
* (Score_{text center region}^ beta)
|
||||
beta (float) : The parameter to calculate final score.
|
||||
box_type (str): Boundary encoding type 'poly' or 'quad'.
|
||||
score_thr (float) : The threshold used to filter out the final
|
||||
candidates.
|
||||
nms_thr (float) : The threshold of nms.
|
||||
|
||||
Returns:
|
||||
boundaries (list[list[float]]): The instance boundary and confidence
|
||||
list.
|
||||
"""
|
||||
assert isinstance(preds, list)
|
||||
assert len(preds) == 2
|
||||
assert box_type in ['poly', 'quad']
|
||||
|
||||
cls_pred = preds[0][0]
|
||||
tr_pred = cls_pred[0:2]
|
||||
tcl_pred = cls_pred[2:]
|
||||
|
||||
reg_pred = preds[1][0].transpose([1, 2, 0])
|
||||
x_pred = reg_pred[:, :, :2 * fourier_degree + 1]
|
||||
y_pred = reg_pred[:, :, 2 * fourier_degree + 1:]
|
||||
|
||||
score_pred = (tr_pred[1]**alpha) * (tcl_pred[1]**beta)
|
||||
tr_pred_mask = (score_pred) > score_thr
|
||||
tr_mask = fill_hole(tr_pred_mask)
|
||||
|
||||
tr_contours, _ = cv2.findContours(
|
||||
tr_mask.astype(np.uint8), cv2.RETR_TREE,
|
||||
cv2.CHAIN_APPROX_SIMPLE) # opencv4
|
||||
|
||||
mask = np.zeros_like(tr_mask)
|
||||
boundaries = []
|
||||
for cont in tr_contours:
|
||||
deal_map = mask.copy().astype(np.int8)
|
||||
cv2.drawContours(deal_map, [cont], -1, 1, -1)
|
||||
|
||||
score_map = score_pred * deal_map
|
||||
score_mask = score_map > 0
|
||||
xy_text = np.argwhere(score_mask)
|
||||
dxy = xy_text[:, 1] + xy_text[:, 0] * 1j
|
||||
|
||||
x, y = x_pred[score_mask], y_pred[score_mask]
|
||||
c = x + y * 1j
|
||||
c[:, fourier_degree] = c[:, fourier_degree] + dxy
|
||||
c *= scale
|
||||
|
||||
polygons = fourier2poly(c, num_reconstr_points)
|
||||
score = score_map[score_mask].reshape(-1, 1)
|
||||
polygons = poly_nms(np.hstack((polygons, score)).tolist(), nms_thr)
|
||||
|
||||
boundaries = boundaries + polygons
|
||||
|
||||
boundaries = poly_nms(boundaries, nms_thr)
|
||||
|
||||
if box_type == 'quad':
|
||||
new_boundaries = []
|
||||
for boundary in boundaries:
|
||||
poly = np.array(boundary[:-1]).reshape(-1, 2).astype(np.float32)
|
||||
score = boundary[-1]
|
||||
points = cv2.boxPoints(cv2.minAreaRect(poly))
|
||||
points = np.int0(points)
|
||||
new_boundaries.append(points.reshape(-1).tolist() + [score])
|
||||
boundaries = new_boundaries
|
||||
|
||||
return boundaries
|
||||
@@ -37,10 +37,10 @@ class PSEPostProcess(object):
|
||||
thresh=0.5,
|
||||
box_thresh=0.85,
|
||||
min_area=16,
|
||||
box_type='box',
|
||||
box_type='quad',
|
||||
scale=4,
|
||||
**kwargs):
|
||||
assert box_type in ['box', 'poly'], 'Only box and poly is supported'
|
||||
assert box_type in ['quad', 'poly'], 'Only quad and poly is supported'
|
||||
self.thresh = thresh
|
||||
self.box_thresh = box_thresh
|
||||
self.min_area = min_area
|
||||
@@ -95,7 +95,7 @@ class PSEPostProcess(object):
|
||||
label[ind] = 0
|
||||
continue
|
||||
|
||||
if self.box_type == 'box':
|
||||
if self.box_type == 'quad':
|
||||
rect = cv2.minAreaRect(points)
|
||||
bbox = cv2.boxPoints(rect)
|
||||
elif self.box_type == 'poly':
|
||||
|
||||
@@ -11,8 +11,8 @@
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
import numpy as np
|
||||
import string
|
||||
import paddle
|
||||
from paddle.nn import functional as F
|
||||
import re
|
||||
@@ -652,3 +652,63 @@ class SARLabelDecode(BaseRecLabelDecode):
|
||||
|
||||
def get_ignored_tokens(self):
|
||||
return [self.padding_idx]
|
||||
|
||||
|
||||
class PRENLabelDecode(BaseRecLabelDecode):
|
||||
""" Convert between text-label and text-index """
|
||||
|
||||
def __init__(self, character_dict_path=None, use_space_char=False,
|
||||
**kwargs):
|
||||
super(PRENLabelDecode, self).__init__(character_dict_path,
|
||||
use_space_char)
|
||||
|
||||
def add_special_char(self, dict_character):
|
||||
padding_str = '<PAD>' # 0
|
||||
end_str = '<EOS>' # 1
|
||||
unknown_str = '<UNK>' # 2
|
||||
|
||||
dict_character = [padding_str, end_str, unknown_str] + dict_character
|
||||
self.padding_idx = 0
|
||||
self.end_idx = 1
|
||||
self.unknown_idx = 2
|
||||
|
||||
return dict_character
|
||||
|
||||
def decode(self, text_index, text_prob=None):
|
||||
""" convert text-index into text-label. """
|
||||
result_list = []
|
||||
batch_size = len(text_index)
|
||||
|
||||
for batch_idx in range(batch_size):
|
||||
char_list = []
|
||||
conf_list = []
|
||||
for idx in range(len(text_index[batch_idx])):
|
||||
if text_index[batch_idx][idx] == self.end_idx:
|
||||
break
|
||||
if text_index[batch_idx][idx] in \
|
||||
[self.padding_idx, self.unknown_idx]:
|
||||
continue
|
||||
char_list.append(self.character[int(text_index[batch_idx][
|
||||
idx])])
|
||||
if text_prob is not None:
|
||||
conf_list.append(text_prob[batch_idx][idx])
|
||||
else:
|
||||
conf_list.append(1)
|
||||
|
||||
text = ''.join(char_list)
|
||||
if len(text) > 0:
|
||||
result_list.append((text, np.mean(conf_list)))
|
||||
else:
|
||||
# here confidence of empty recog result is 1
|
||||
result_list.append(('', 1))
|
||||
return result_list
|
||||
|
||||
def __call__(self, preds, label=None, *args, **kwargs):
|
||||
preds = preds.numpy()
|
||||
preds_idx = preds.argmax(axis=2)
|
||||
preds_prob = preds.max(axis=2)
|
||||
text = self.decode(preds_idx, preds_prob)
|
||||
if label is None:
|
||||
return text
|
||||
label = self.decode(label)
|
||||
return text, label
|
||||
|
||||
@@ -0,0 +1,146 @@
|
||||
# copyright (c) 2022 PaddlePaddle Authors. All Rights Reserve.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
import numpy as np
|
||||
from shapely.geometry import Polygon
|
||||
|
||||
|
||||
def points2polygon(points):
|
||||
"""Convert k points to 1 polygon.
|
||||
|
||||
Args:
|
||||
points (ndarray or list): A ndarray or a list of shape (2k)
|
||||
that indicates k points.
|
||||
|
||||
Returns:
|
||||
polygon (Polygon): A polygon object.
|
||||
"""
|
||||
if isinstance(points, list):
|
||||
points = np.array(points)
|
||||
|
||||
assert isinstance(points, np.ndarray)
|
||||
assert (points.size % 2 == 0) and (points.size >= 8)
|
||||
|
||||
point_mat = points.reshape([-1, 2])
|
||||
return Polygon(point_mat)
|
||||
|
||||
|
||||
def poly_intersection(poly_det, poly_gt, buffer=0.0001):
|
||||
"""Calculate the intersection area between two polygon.
|
||||
|
||||
Args:
|
||||
poly_det (Polygon): A polygon predicted by detector.
|
||||
poly_gt (Polygon): A gt polygon.
|
||||
|
||||
Returns:
|
||||
intersection_area (float): The intersection area between two polygons.
|
||||
"""
|
||||
assert isinstance(poly_det, Polygon)
|
||||
assert isinstance(poly_gt, Polygon)
|
||||
|
||||
if buffer == 0:
|
||||
poly_inter = poly_det & poly_gt
|
||||
else:
|
||||
poly_inter = poly_det.buffer(buffer) & poly_gt.buffer(buffer)
|
||||
return poly_inter.area, poly_inter
|
||||
|
||||
|
||||
def poly_union(poly_det, poly_gt):
|
||||
"""Calculate the union area between two polygon.
|
||||
|
||||
Args:
|
||||
poly_det (Polygon): A polygon predicted by detector.
|
||||
poly_gt (Polygon): A gt polygon.
|
||||
|
||||
Returns:
|
||||
union_area (float): The union area between two polygons.
|
||||
"""
|
||||
assert isinstance(poly_det, Polygon)
|
||||
assert isinstance(poly_gt, Polygon)
|
||||
|
||||
area_det = poly_det.area
|
||||
area_gt = poly_gt.area
|
||||
area_inters, _ = poly_intersection(poly_det, poly_gt)
|
||||
return area_det + area_gt - area_inters
|
||||
|
||||
|
||||
def valid_boundary(x, with_score=True):
|
||||
num = len(x)
|
||||
if num < 8:
|
||||
return False
|
||||
if num % 2 == 0 and (not with_score):
|
||||
return True
|
||||
if num % 2 == 1 and with_score:
|
||||
return True
|
||||
|
||||
return False
|
||||
|
||||
|
||||
def boundary_iou(src, target):
|
||||
"""Calculate the IOU between two boundaries.
|
||||
|
||||
Args:
|
||||
src (list): Source boundary.
|
||||
target (list): Target boundary.
|
||||
|
||||
Returns:
|
||||
iou (float): The iou between two boundaries.
|
||||
"""
|
||||
assert valid_boundary(src, False)
|
||||
assert valid_boundary(target, False)
|
||||
src_poly = points2polygon(src)
|
||||
target_poly = points2polygon(target)
|
||||
|
||||
return poly_iou(src_poly, target_poly)
|
||||
|
||||
|
||||
def poly_iou(poly_det, poly_gt):
|
||||
"""Calculate the IOU between two polygons.
|
||||
|
||||
Args:
|
||||
poly_det (Polygon): A polygon predicted by detector.
|
||||
poly_gt (Polygon): A gt polygon.
|
||||
|
||||
Returns:
|
||||
iou (float): The IOU between two polygons.
|
||||
"""
|
||||
assert isinstance(poly_det, Polygon)
|
||||
assert isinstance(poly_gt, Polygon)
|
||||
area_inters, _ = poly_intersection(poly_det, poly_gt)
|
||||
area_union = poly_union(poly_det, poly_gt)
|
||||
if area_union == 0:
|
||||
return 0.0
|
||||
return area_inters / area_union
|
||||
|
||||
|
||||
def poly_nms(polygons, threshold):
|
||||
assert isinstance(polygons, list)
|
||||
|
||||
polygons = np.array(sorted(polygons, key=lambda x: x[-1]))
|
||||
|
||||
keep_poly = []
|
||||
index = [i for i in range(polygons.shape[0])]
|
||||
|
||||
while len(index) > 0:
|
||||
keep_poly.append(polygons[index[-1]].tolist())
|
||||
A = polygons[index[-1]][:-1]
|
||||
index = np.delete(index, -1)
|
||||
iou_list = np.zeros((len(index), ))
|
||||
for i in range(len(index)):
|
||||
B = polygons[index[i]][:-1]
|
||||
iou_list[i] = boundary_iou(A, B)
|
||||
remove_index = np.where(iou_list > threshold)
|
||||
index = np.delete(index, remove_index)
|
||||
|
||||
return keep_poly
|
||||
@@ -98,9 +98,9 @@ PP-Structure Series Model List (Updating)
|
||||
|
||||
### 7.1 Layout analysis model
|
||||
|
||||
|model name|description|download|
|
||||
| --- | --- | --- |
|
||||
| ppyolov2_r50vd_dcn_365e_publaynet | The layout analysis model trained on the PubLayNet dataset can divide image into 5 types of areas **text, title, table, picture, and list** | [PubLayNet](https://paddle-model-ecology.bj.bcebos.com/model/layout-parser/ppyolov2_r50vd_dcn_365e_publaynet.tar) |
|
||||
|model name|description|download|label_map|
|
||||
| --- | --- | --- |--- |
|
||||
| ppyolov2_r50vd_dcn_365e_publaynet | The layout analysis model trained on the PubLayNet dataset can divide image into 5 types of areas **text, title, table, picture, and list** | [PubLayNet](https://paddle-model-ecology.bj.bcebos.com/model/layout-parser/ppyolov2_r50vd_dcn_365e_publaynet.tar) | {0: "Text", 1: "Title", 2: "List", 3:"Table", 4:"Figure"}|
|
||||
|
||||
### 7.2 OCR and table recognition model
|
||||
|
||||
|
||||
@@ -96,9 +96,9 @@ PP-Structure系列模型列表(更新中)
|
||||
|
||||
### 7.1 版面分析模型
|
||||
|
||||
|模型名称|模型简介|下载地址|
|
||||
| --- | --- | --- |
|
||||
| ppyolov2_r50vd_dcn_365e_publaynet | PubLayNet 数据集训练的版面分析模型,可以划分**文字、标题、表格、图片以及列表**5类区域 | [PubLayNet](https://paddle-model-ecology.bj.bcebos.com/model/layout-parser/ppyolov2_r50vd_dcn_365e_publaynet.tar) |
|
||||
|模型名称|模型简介|下载地址| label_map|
|
||||
| --- | --- | --- | --- |
|
||||
| ppyolov2_r50vd_dcn_365e_publaynet | PubLayNet 数据集训练的版面分析模型,可以划分**文字、标题、表格、图片以及列表**5类区域 | [PubLayNet](https://paddle-model-ecology.bj.bcebos.com/model/layout-parser/ppyolov2_r50vd_dcn_365e_publaynet.tar) | {0: "Text", 1: "Title", 2: "List", 3:"Table", 4:"Figure"}|
|
||||
|
||||
### 7.2 OCR和表格识别模型
|
||||
|
||||
|
||||
@@ -11,11 +11,11 @@
|
||||
|
||||
## 1. LayoutParser 模型
|
||||
|
||||
|模型名称|模型简介|下载地址|
|
||||
| --- | --- | --- |
|
||||
| ppyolov2_r50vd_dcn_365e_publaynet | PubLayNet 数据集训练的版面分析模型,可以划分**文字、标题、表格、图片以及列表**5类区域 | [PubLayNet](https://paddle-model-ecology.bj.bcebos.com/model/layout-parser/ppyolov2_r50vd_dcn_365e_publaynet.tar) |
|
||||
| ppyolov2_r50vd_dcn_365e_tableBank_word | TableBank Word 数据集训练的版面分析模型,只能检测表格 | [TableBank Word](https://paddle-model-ecology.bj.bcebos.com/model/layout-parser/ppyolov2_r50vd_dcn_365e_tableBank_word.tar) |
|
||||
| ppyolov2_r50vd_dcn_365e_tableBank_latex | TableBank Latex 数据集训练的版面分析模型,只能检测表格 | [TableBank Latex](https://paddle-model-ecology.bj.bcebos.com/model/layout-parser/ppyolov2_r50vd_dcn_365e_tableBank_latex.tar) |
|
||||
|模型名称|模型简介|下载地址|label_map|
|
||||
| --- | --- | --- | --- |
|
||||
| ppyolov2_r50vd_dcn_365e_publaynet | PubLayNet 数据集训练的版面分析模型,可以划分**文字、标题、表格、图片以及列表**5类区域 | [推理模型](https://paddle-model-ecology.bj.bcebos.com/model/layout-parser/ppyolov2_r50vd_dcn_365e_publaynet.tar) / [训练模型](https://paddle-model-ecology.bj.bcebos.com/model/layout-parser/ppyolov2_r50vd_dcn_365e_publaynet_pretrained.pdparams) |{0: "Text", 1: "Title", 2: "List", 3:"Table", 4:"Figure"}|
|
||||
| ppyolov2_r50vd_dcn_365e_tableBank_word | TableBank Word 数据集训练的版面分析模型,只能检测表格 | [推理模型](https://paddle-model-ecology.bj.bcebos.com/model/layout-parser/ppyolov2_r50vd_dcn_365e_tableBank_word.tar) | {0:"Table"}|
|
||||
| ppyolov2_r50vd_dcn_365e_tableBank_latex | TableBank Latex 数据集训练的版面分析模型,只能检测表格 | [推理模型](https://paddle-model-ecology.bj.bcebos.com/model/layout-parser/ppyolov2_r50vd_dcn_365e_tableBank_latex.tar) | {0:"Table"}|
|
||||
|
||||
## 2. OCR和表格识别模型
|
||||
|
||||
|
||||
@@ -100,7 +100,9 @@ dict 里各个字段说明如下
|
||||
| output | excel和识别结果保存的地址 | ./output/table |
|
||||
| table_max_len | 表格结构模型预测时,图像的长边resize尺度 | 488 |
|
||||
| table_model_dir | 表格结构模型 inference 模型地址 | None |
|
||||
| table_char_type | 表格结构模型所用字典地址 | ../ppocr/utils/dict/table_structure_dict.txt |
|
||||
| table_char_dict_path | 表格结构模型所用字典地址 | ../ppocr/utils/dict/table_structure_dict.txt |
|
||||
| layout_path_model | 版面分析模型模型地址,可以为在线地址或者本地地址,当为本地地址时,需要指定 layout_label_map, 命令行模式下可通过--layout_label_map='{0: "Text", 1: "Title", 2: "List", 3:"Table", 4:"Figure"}' 指定 | lp://PubLayNet/ppyolov2_r50vd_dcn_365e_publaynet/config |
|
||||
| layout_label_map | 版面分析模型模型label映射字典 | None |
|
||||
| model_name_or_path | VQA SER模型地址 | None |
|
||||
| max_seq_length | VQA SER模型最大支持token长度 | 512 |
|
||||
| label_map_path | VQA SER 标签文件地址 | ./vqa/labels/labels_ser.txt |
|
||||
|
||||
@@ -52,7 +52,7 @@ The following figure shows the result, with different colored detection boxes re
|
||||
| threshold | threshold of prediction score | 0.5 | \ |
|
||||
| input_shape | picture size of reshape | [3,640,640] | \ |
|
||||
| batch_size | testing batch size | 1 | \ |
|
||||
| label_map | category mapping table | None | Setting config_ path, it can be none, and the label is automatically obtained according to the dataset name_ map |
|
||||
| label_map | category mapping table | None | Setting config_ path, it can be none, and the label is automatically obtained according to the dataset name_ map, You need to specify it manually when setting model_path |
|
||||
| enforce_cpu | whether to use CPU | False | False to use GPU, and True to force the use of CPU |
|
||||
| enforce_mkldnn | whether mkldnn acceleration is enabled in CPU prediction | True | \ |
|
||||
| thread_num | the number of CPU threads | 10 | \ |
|
||||
|
||||
@@ -52,7 +52,7 @@ show_img.show()
|
||||
| threshold | 预测得分的阈值 | 0.5 | \ |
|
||||
| input_shape | reshape之后图片尺寸 | [3,640,640] | \ |
|
||||
| batch_size | 测试batch size | 1 | \ |
|
||||
| label_map | 类别映射表 | None | 设置config_path时,可以为None,根据数据集名称自动获取label_map |
|
||||
| label_map | 类别映射表 | None | 设置config_path时,可以为None,根据数据集名称自动获取label_map,设置model_path时需要手动指定 |
|
||||
| enforce_cpu | 代码是否使用CPU运行 | False | 设置为False表示使用GPU,True表示强制使用CPU |
|
||||
| enforce_mkldnn | CPU预测中是否开启MKLDNN加速 | True | \ |
|
||||
| thread_num | 设置CPU线程数 | 10 | \ |
|
||||
|
||||
@@ -58,6 +58,7 @@ class OCRSystem(object):
|
||||
self.table_layout = lp.PaddleDetectionLayoutModel(
|
||||
config_path=config_path,
|
||||
model_path=model_path,
|
||||
label_map=args.layout_label_map,
|
||||
threshold=0.5,
|
||||
enable_mkldnn=args.enable_mkldnn,
|
||||
enforce_cpu=not args.use_gpu,
|
||||
|
||||
@@ -12,6 +12,7 @@
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
import ast
|
||||
from PIL import Image
|
||||
import numpy as np
|
||||
from tools.infer.utility import draw_ocr_box_txt, init_args as infer_args
|
||||
@@ -34,7 +35,11 @@ def init_args():
|
||||
"--layout_path_model",
|
||||
type=str,
|
||||
default="lp://PubLayNet/ppyolov2_r50vd_dcn_365e_publaynet/config")
|
||||
|
||||
parser.add_argument(
|
||||
"--layout_label_map",
|
||||
type=ast.literal_eval,
|
||||
default=None,
|
||||
help='label map according to ppstructure/layout/README_ch.md')
|
||||
# params for ser
|
||||
parser.add_argument("--model_name_or_path", type=str)
|
||||
parser.add_argument("--max_seq_length", type=int, default=512)
|
||||
|
||||