mirror of
https://github.com/PaddlePaddle/PaddleOCR.git
synced 2026-09-24 23:33:08 +08:00
Merge branch 'dygraph' into robustscanner_branch
This commit is contained in:
 smilelite
@@ -131,7 +131,7 @@ pip3 install dist/PPOCRLabel-1.0.2-py2.py3-none-any.whl -i https://mirror.baidu.
|
||||
|
||||
> 注意:如果表格中存在空白单元格,同样需要使用一个标注框将其标出,使得单元格总数与图像中保持一致。
|
||||
|
||||
3. **调整单元格顺序:**点击软件`视图-显示框编号` 打开标注框序号,在软件界面右侧拖动 `识别结果` 一栏下的所有结果,使得标注框编号按照从左到右,从上到下的顺序排列
|
||||
3. **调整单元格顺序**:点击软件`视图-显示框编号` 打开标注框序号,在软件界面右侧拖动 `识别结果` 一栏下的所有结果,使得标注框编号按照从左到右,从上到下的顺序排列,按行依次标注。
|
||||
|
||||
4. 标注表格结构:**在外部Excel软件中,将存在文字的单元格标记为任意标识符(如 `1` )**,保证Excel中的单元格合并情况与原图相同即可(即不需要Excel中的单元格文字与图片中的文字完全相同)
|
||||
|
||||
|
||||
+68
-31
@@ -1,41 +1,78 @@
|
||||
[English](README_en.md) | 简体中文
|
||||
|
||||
# 场景应用
|
||||
|
||||
PaddleOCR场景应用覆盖通用,制造、金融、交通行业的主要OCR垂类应用,在PP-OCR、PP-Structure的通用能力基础之上,以notebook的形式展示利用场景数据微调、模型优化方法、数据增广等内容,为开发者快速落地OCR应用提供示范与启发。
|
||||
|
||||
> 如需下载全部垂类模型,可以扫描下方二维码,关注公众号填写问卷后,加入PaddleOCR官方交流群获取20G OCR学习大礼包(内含《动手学OCR》电子书、课程回放视频、前沿论文等重磅资料)
|
||||
- [教程文档](#1)
|
||||
- [通用](#11)
|
||||
- [制造](#12)
|
||||
- [金融](#13)
|
||||
- [交通](#14)
|
||||
|
||||
- [模型下载](#2)
|
||||
|
||||
<a name="1"></a>
|
||||
|
||||
## 教程文档
|
||||
|
||||
<a name="11"></a>
|
||||
|
||||
### 通用
|
||||
|
||||
| 类别 | 亮点 | 模型下载 | 教程 |
|
||||
| ---------------------- | ------------ | -------------- | --------------------------------------- |
|
||||
| 高精度中文识别模型SVTR | 比PP-OCRv3识别模型精度高3%,可用于数据挖掘或对预测效率要求不高的场景。| [模型下载](#2) | [中文](./高精度中文识别模型.md)/English |
|
||||
| 手写体识别 | 新增字形支持 | | |
|
||||
|
||||
<a name="12"></a>
|
||||
|
||||
### 制造
|
||||
|
||||
| 类别 | 亮点 | 模型下载 | 教程 | 示例图 |
|
||||
| -------------- | ------------------------------ | -------------- | ------------------------------------------------------------ | ------------------------------------------------------------ |
|
||||
| 数码管识别 | 数码管数据合成、漏识别调优 | [模型下载](#2) | [中文](./光功率计数码管字符识别/光功率计数码管字符识别.md)/English | <img src="https://ai-studio-static-online.cdn.bcebos.com/7d5774a273f84efba5b9ce7fd3f86e9ef24b6473e046444db69fa3ca20ac0986" width = "200" height = "100" /> |
|
||||
| 液晶屏读数识别 | 检测模型蒸馏、Serving部署 | [模型下载](#2) | [中文](./液晶屏读数识别.md)/English | <img src="https://ai-studio-static-online.cdn.bcebos.com/901ab741cb46441ebec510b37e63b9d8d1b7c95f63cc4e5e8757f35179ae6373" width = "200" height = "100" /> |
|
||||
| 包装生产日期 | 点阵字符合成、过曝过暗文字识别 | [模型下载](#2) | [中文](./包装生产日期识别.md)/English | <img src="https://ai-studio-static-online.cdn.bcebos.com/d9e0533cc1df47ffa3bbe99de9e42639a3ebfa5bce834bafb1ca4574bf9db684" width = "200" height = "100" /> |
|
||||
| PCB文字识别 | 小尺寸文本检测与识别 | [模型下载](#2) | [中文](./PCB字符识别/PCB字符识别.md)/English | <img src="https://ai-studio-static-online.cdn.bcebos.com/95d8e95bf1ab476987f2519c0f8f0c60a0cdc2c444804ed6ab08f2f7ab054880" width = "200" height = "100" /> |
|
||||
| 电表识别 | 大分辨率图像检测调优 | [模型下载](#2) | | |
|
||||
| 液晶屏缺陷检测 | 非文字字符识别 | | | |
|
||||
|
||||
<a name="13"></a>
|
||||
|
||||
### 金融
|
||||
|
||||
| 类别 | 亮点 | 模型下载 | 教程 | 示例图 |
|
||||
| -------------- | ------------------------ | -------------- | ----------------------------------- | ------------------------------------------------------------ |
|
||||
| 表单VQA | 多模态通用表单结构化提取 | [模型下载](#2) | [中文](./多模态表单识别.md)/English | <img src="https://ai-studio-static-online.cdn.bcebos.com/a3b25766f3074d2facdf88d4a60fc76612f51992fd124cf5bd846b213130665b" width = "200" height = "200" /> |
|
||||
| 增值税发票 | 尽请期待 | | | |
|
||||
| 印章检测与识别 | 端到端弯曲文本识别 | | | |
|
||||
| 通用卡证识别 | 通用结构化提取 | | | |
|
||||
| 身份证识别 | 结构化提取、图像阴影 | | | |
|
||||
| 合同比对 | 密集文本检测、NLP串联 | | | |
|
||||
|
||||
<a name="14"></a>
|
||||
|
||||
### 交通
|
||||
|
||||
| 类别 | 亮点 | 模型下载 | 教程 | 示例图 |
|
||||
| ----------------- | ------------------------------ | -------------- | ----------------------------------- | ------------------------------------------------------------ |
|
||||
| 车牌识别 | 多角度图像、轻量模型、端侧部署 | [模型下载](#2) | [中文](./轻量级车牌识别.md)/English | <img src="https://ai-studio-static-online.cdn.bcebos.com/76b6a0939c2c4cf49039b6563c4b28e241e11285d7464e799e81c58c0f7707a7" width = "200" height = "100" /> |
|
||||
| 驾驶证/行驶证识别 | 尽请期待 | | | |
|
||||
| 快递单识别 | 尽请期待 | | | |
|
||||
|
||||
<a name="2"></a>
|
||||
|
||||
## 模型下载
|
||||
|
||||
如需下载上述场景中已经训练好的垂类模型,可以扫描下方二维码,关注公众号填写问卷后,加入PaddleOCR官方交流群获取20G OCR学习大礼包(内含《动手学OCR》电子书、课程回放视频、前沿论文等重磅资料)
|
||||
|
||||
<div align="center">
|
||||
<img src="https://ai-studio-static-online.cdn.bcebos.com/dd721099bd50478f9d5fb13d8dd00fad69c22d6848244fd3a1d3980d7fefc63e" width = "150" height = "150" />
|
||||
</div>
|
||||
|
||||
如果您是企业开发者且未在上述场景中找到合适的方案,可以填写[OCR应用合作调研问卷](https://paddle.wjx.cn/vj/QwF7GKw.aspx),免费与官方团队展开不同层次的合作,包括但不限于问题抽象、确定技术方案、项目答疑、共同研发等。如果您已经使用PaddleOCR落地项目,也可以填写此问卷,与飞桨平台共同宣传推广,提升企业技术品宣。期待您的提交!
|
||||
|
||||
> 如果您是企业开发者且未在下述场景中找到合适的方案,可以填写[OCR应用合作调研问卷](https://paddle.wjx.cn/vj/QwF7GKw.aspx),免费与官方团队展开不同层次的合作,包括但不限于问题抽象、确定技术方案、项目答疑、共同研发等。如果您已经使用PaddleOCR落地项目,也可以填写此问卷,与飞桨平台共同宣传推广,提升企业技术品宣。期待您的提交!
|
||||
|
||||
## 通用
|
||||
|
||||
| 类别 | 亮点 | 类别 | 亮点 |
|
||||
| ------------------------------------------------- | -------- | ---------- | ------------ |
|
||||
| [高精度中文识别模型SVTR](./高精度中文识别模型.md) | 新增模型 | 手写体识别 | 新增字形支持 |
|
||||
|
||||
## 制造
|
||||
|
||||
| 类别 | 亮点 | 类别 | 亮点 |
|
||||
| ------------------------------------------------------------ | ------------------------------ | ------------------------------------------- | -------------------- |
|
||||
| [数码管识别](./光功率计数码管字符识别/光功率计数码管字符识别.md) | 数码管数据合成、漏识别调优 | 电表识别 | 大分辨率图像检测调优 |
|
||||
| [液晶屏读数识别](./液晶屏读数识别.md) | 检测模型蒸馏、Serving部署 | [PCB文字识别](./PCB字符识别/PCB字符识别.md) | 小尺寸文本检测与识别 |
|
||||
| [包装生产日期](./包装生产日期识别.md) | 点阵字符合成、过曝过暗文字识别 | 液晶屏缺陷检测 | 非文字字符识别 |
|
||||
|
||||
## 金融
|
||||
|
||||
| 类别 | 亮点 | 类别 | 亮点 |
|
||||
| ------------------------------ | ------------------------ | ------------ | --------------------- |
|
||||
| [表单VQA](./多模态表单识别.md) | 多模态通用表单结构化提取 | 通用卡证识别 | 通用结构化提取 |
|
||||
| 增值税发票 | 尽请期待 | 身份证识别 | 结构化提取、图像阴影 |
|
||||
| 印章检测与识别 | 端到端弯曲文本识别 | 合同比对 | 密集文本检测、NLP串联 |
|
||||
|
||||
## 交通
|
||||
|
||||
| 类别 | 亮点 | 类别 | 亮点 |
|
||||
| ------------------------------- | ------------------------------ | ---------- | -------- |
|
||||
| [车牌识别](./轻量级车牌识别.md) | 多角度图像、轻量模型、端侧部署 | 快递单识别 | 尽请期待 |
|
||||
| 驾驶证/行驶证识别 | 尽请期待 | | |
|
||||
<a href="https://trackgit.com">
|
||||
<img src="https://us-central1-trackgit-analytics.cloudfunctions.net/token/ping/l63cvzo0w09yxypc7ygl" alt="traffic" />
|
||||
</a>
|
||||
|
||||
@@ -0,0 +1,251 @@
|
||||
# 基于PP-OCRv3的手写文字识别
|
||||
|
||||
- [1. 项目背景及意义](#1-项目背景及意义)
|
||||
- [2. 项目内容](#2-项目内容)
|
||||
- [3. PP-OCRv3识别算法介绍](#3-PP-OCRv3识别算法介绍)
|
||||
- [4. 安装环境](#4-安装环境)
|
||||
- [5. 数据准备](#5-数据准备)
|
||||
- [6. 模型训练](#6-模型训练)
|
||||
- [6.1 下载预训练模型](#61-下载预训练模型)
|
||||
- [6.2 修改配置文件](#62-修改配置文件)
|
||||
- [6.3 开始训练](#63-开始训练)
|
||||
- [7. 模型评估](#7-模型评估)
|
||||
- [8. 模型导出推理](#8-模型导出推理)
|
||||
- [8.1 模型导出](#81-模型导出)
|
||||
- [8.2 模型推理](#82-模型推理)
|
||||
|
||||
|
||||
## 1. 项目背景及意义
|
||||
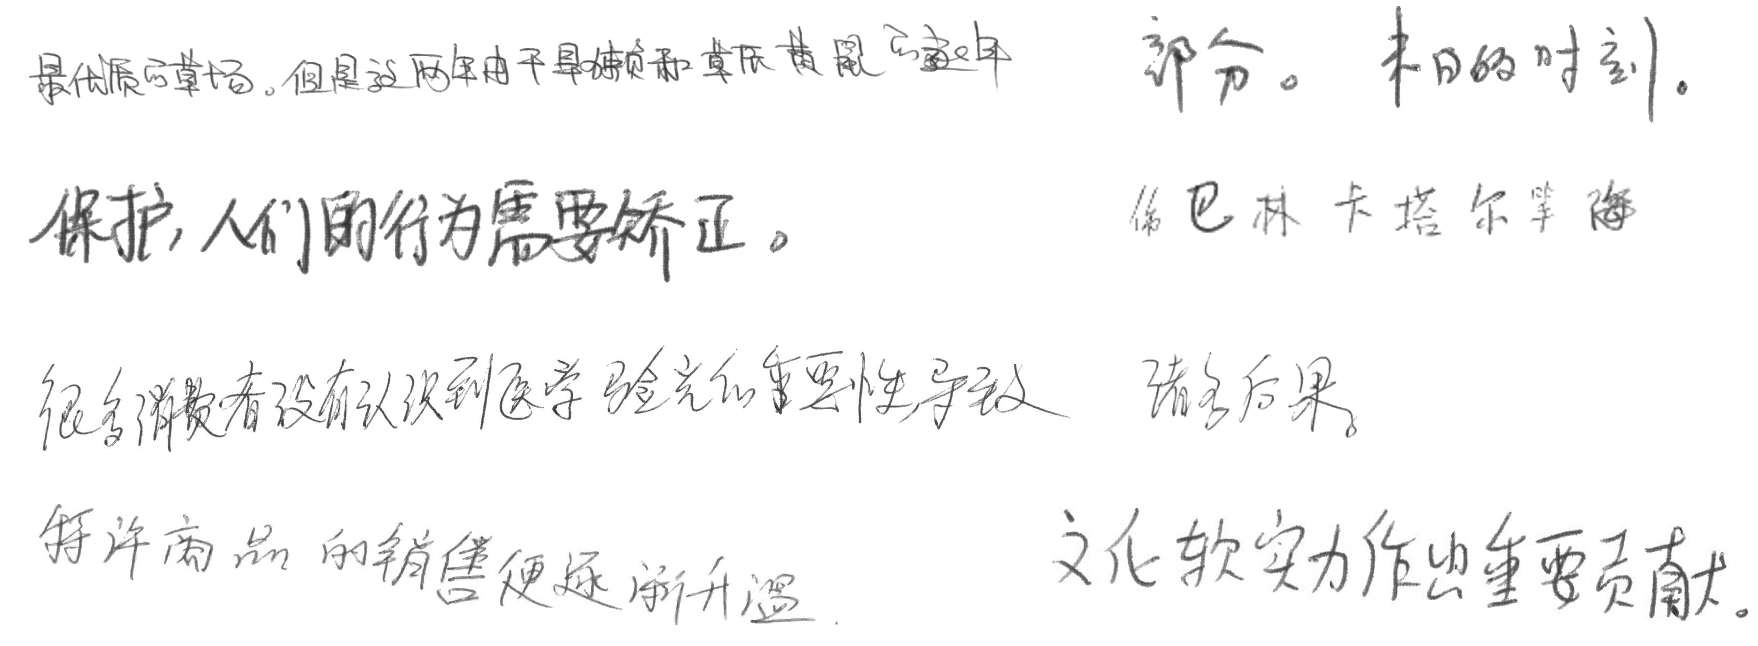
目前光学字符识别(OCR)技术在我们的生活当中被广泛使用,但是大多数模型在通用场景下的准确性还有待提高。针对于此我们借助飞桨提供的PaddleOCR套件较容易的实现了在垂类场景下的应用。手写体在日常生活中较为常见,然而手写体的识别却存在着很大的挑战,因为每个人的手写字体风格不一样,这对于视觉模型来说还是相当有挑战的。因此训练一个手写体识别模型具有很好的现实意义。下面给出一些手写体的示例图:
|
||||
|
||||
|
||||
|
||||
## 2. 项目内容
|
||||
本项目基于PaddleOCR套件,以PP-OCRv3识别模型为基础,针对手写文字识别场景进行优化。
|
||||
|
||||
Aistudio项目链接:[OCR手写文字识别](https://aistudio.baidu.com/aistudio/projectdetail/4330587)
|
||||
|
||||
## 3. PP-OCRv3识别算法介绍
|
||||
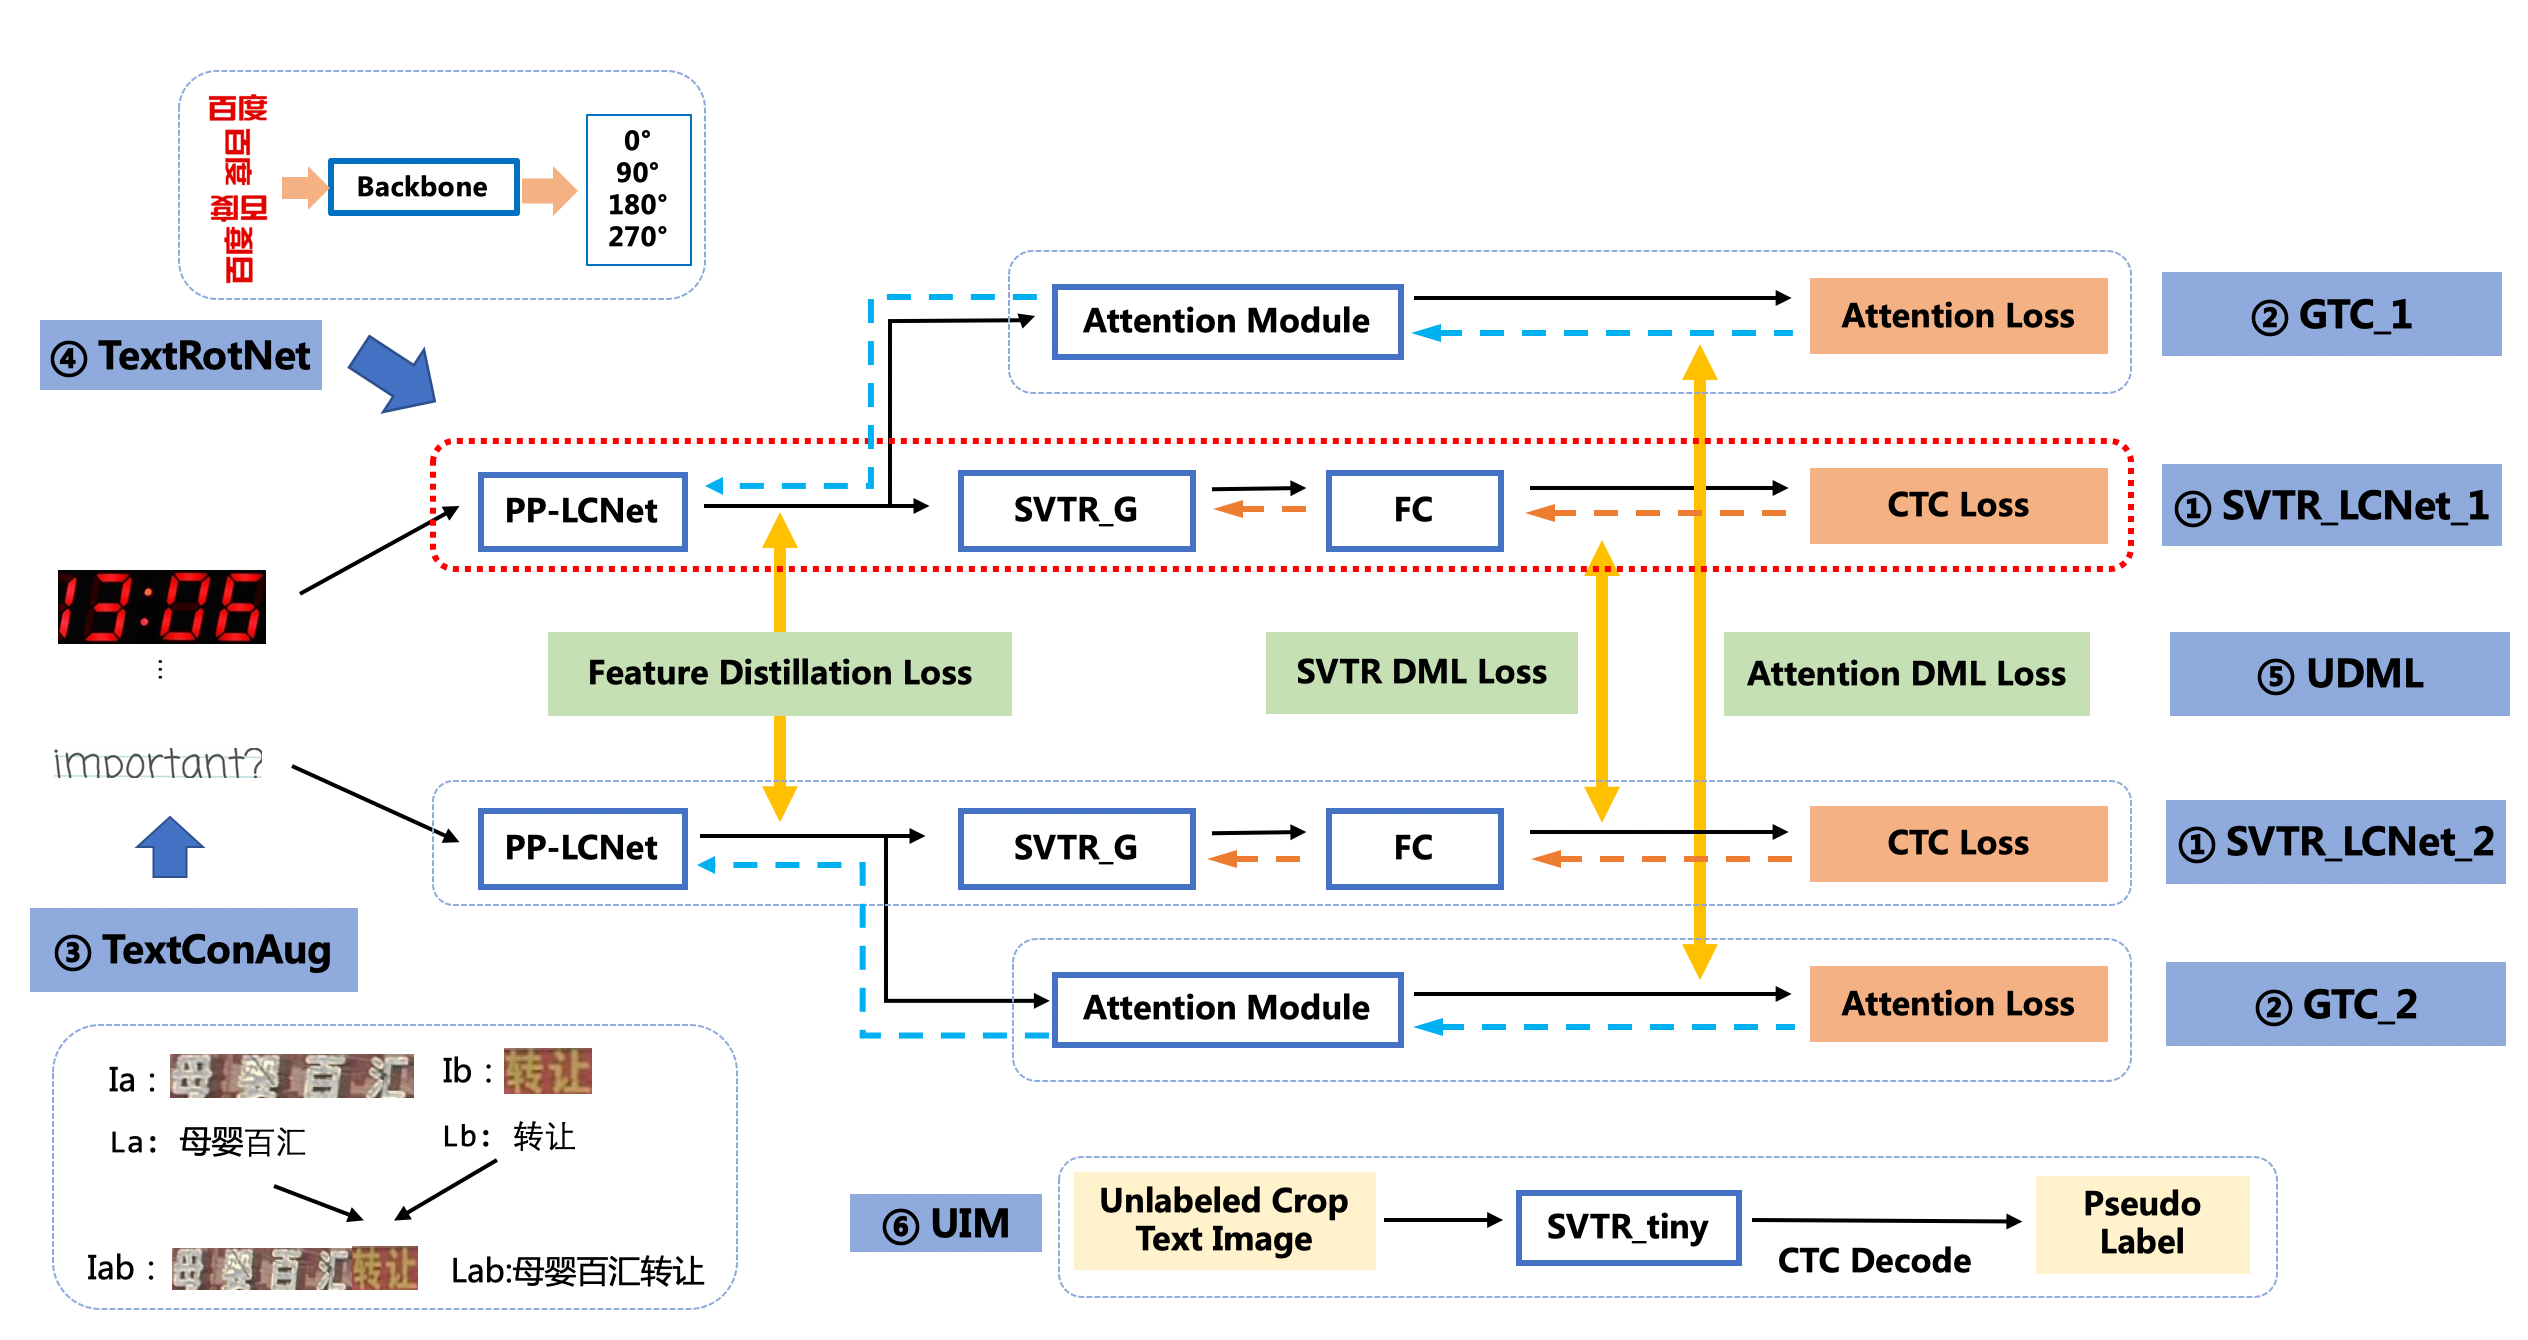
PP-OCRv3的识别模块是基于文本识别算法[SVTR](https://arxiv.org/abs/2205.00159)优化。SVTR不再采用RNN结构,通过引入Transformers结构更加有效地挖掘文本行图像的上下文信息,从而提升文本识别能力。如下图所示,PP-OCRv3采用了6个优化策略。
|
||||
|
||||
|
||||
|
||||
优化策略汇总如下:
|
||||
|
||||
* SVTR_LCNet:轻量级文本识别网络
|
||||
* GTC:Attention指导CTC训练策略
|
||||
* TextConAug:挖掘文字上下文信息的数据增广策略
|
||||
* TextRotNet:自监督的预训练模型
|
||||
* UDML:联合互学习策略
|
||||
* UIM:无标注数据挖掘方案
|
||||
|
||||
详细优化策略描述请参考[PP-OCRv3优化策略](https://github.com/PaddlePaddle/PaddleOCR/blob/release/2.5/doc/doc_ch/PP-OCRv3_introduction.md#3-%E8%AF%86%E5%88%AB%E4%BC%98%E5%8C%96)
|
||||
|
||||
## 4. 安装环境
|
||||
|
||||
|
||||
```python
|
||||
# 首先git官方的PaddleOCR项目,安装需要的依赖
|
||||
git clone https://github.com/PaddlePaddle/PaddleOCR.git
|
||||
cd PaddleOCR
|
||||
pip install -r requirements.txt
|
||||
```
|
||||
|
||||
## 5. 数据准备
|
||||
本项目使用公开的手写文本识别数据集,包含Chinese OCR, 中科院自动化研究所-手写中文数据集[CASIA-HWDB2.x](http://www.nlpr.ia.ac.cn/databases/handwriting/Download.html),以及由中科院手写数据和网上开源数据合并组合的[数据集](https://aistudio.baidu.com/aistudio/datasetdetail/102884/0)等,该项目已经挂载处理好的数据集,可直接下载使用进行训练。
|
||||
|
||||
|
||||
```python
|
||||
下载并解压数据
|
||||
tar -xf hw_data.tar
|
||||
```
|
||||
|
||||
## 6. 模型训练
|
||||
### 6.1 下载预训练模型
|
||||
首先需要下载我们需要的PP-OCRv3识别预训练模型,更多选择请自行选择其他的[文字识别模型](https://github.com/PaddlePaddle/PaddleOCR/blob/release/2.5/doc/doc_ch/models_list.md#2-%E6%96%87%E6%9C%AC%E8%AF%86%E5%88%AB%E6%A8%A1%E5%9E%8B)
|
||||
|
||||
|
||||
```python
|
||||
# 使用该指令下载需要的预训练模型
|
||||
wget -P ./pretrained_models/ https://paddleocr.bj.bcebos.com/PP-OCRv3/chinese/ch_PP-OCRv3_rec_train.tar
|
||||
# 解压预训练模型文件
|
||||
tar -xf ./pretrained_models/ch_PP-OCRv3_rec_train.tar -C pretrained_models
|
||||
```
|
||||
|
||||
### 6.2 修改配置文件
|
||||
我们使用`configs/rec/PP-OCRv3/ch_PP-OCRv3_rec_distillation.yml`,主要修改训练轮数和学习率参相关参数,设置预训练模型路径,设置数据集路径。 另外,batch_size可根据自己机器显存大小进行调整。 具体修改如下几个地方:
|
||||
|
||||
```
|
||||
epoch_num: 100 # 训练epoch数
|
||||
save_model_dir: ./output/ch_PP-OCR_v3_rec
|
||||
save_epoch_step: 10
|
||||
eval_batch_step: [0, 100] # 评估间隔,每隔100step评估一次
|
||||
pretrained_model: ./pretrained_models/ch_PP-OCRv3_rec_train/best_accuracy # 预训练模型路径
|
||||
|
||||
|
||||
lr:
|
||||
name: Cosine # 修改学习率衰减策略为Cosine
|
||||
learning_rate: 0.0001 # 修改fine-tune的学习率
|
||||
warmup_epoch: 2 # 修改warmup轮数
|
||||
|
||||
Train:
|
||||
dataset:
|
||||
name: SimpleDataSet
|
||||
data_dir: ./train_data # 训练集图片路径
|
||||
ext_op_transform_idx: 1
|
||||
label_file_list:
|
||||
- ./train_data/chineseocr-data/rec_hand_line_all_label_train.txt # 训练集标签
|
||||
- ./train_data/handwrite/HWDB2.0Train_label.txt
|
||||
- ./train_data/handwrite/HWDB2.1Train_label.txt
|
||||
- ./train_data/handwrite/HWDB2.2Train_label.txt
|
||||
- ./train_data/handwrite/hwdb_ic13/handwriting_hwdb_train_labels.txt
|
||||
- ./train_data/handwrite/HW_Chinese/train_hw.txt
|
||||
ratio_list:
|
||||
- 0.1
|
||||
- 1.0
|
||||
- 1.0
|
||||
- 1.0
|
||||
- 0.02
|
||||
- 1.0
|
||||
loader:
|
||||
shuffle: true
|
||||
batch_size_per_card: 64
|
||||
drop_last: true
|
||||
num_workers: 4
|
||||
Eval:
|
||||
dataset:
|
||||
name: SimpleDataSet
|
||||
data_dir: ./train_data # 测试集图片路径
|
||||
label_file_list:
|
||||
- ./train_data/chineseocr-data/rec_hand_line_all_label_val.txt # 测试集标签
|
||||
- ./train_data/handwrite/HWDB2.0Test_label.txt
|
||||
- ./train_data/handwrite/HWDB2.1Test_label.txt
|
||||
- ./train_data/handwrite/HWDB2.2Test_label.txt
|
||||
- ./train_data/handwrite/hwdb_ic13/handwriting_hwdb_val_labels.txt
|
||||
- ./train_data/handwrite/HW_Chinese/test_hw.txt
|
||||
loader:
|
||||
shuffle: false
|
||||
drop_last: false
|
||||
batch_size_per_card: 64
|
||||
num_workers: 4
|
||||
```
|
||||
由于数据集大多是长文本,因此需要**注释**掉下面的数据增广策略,以便训练出更好的模型。
|
||||
```
|
||||
- RecConAug:
|
||||
prob: 0.5
|
||||
ext_data_num: 2
|
||||
image_shape: [48, 320, 3]
|
||||
```
|
||||
|
||||
|
||||
### 6.3 开始训练
|
||||
我们使用上面修改好的配置文件`configs/rec/PP-OCRv3/ch_PP-OCRv3_rec_distillation.yml`,预训练模型,数据集路径,学习率,训练轮数等都已经设置完毕后,可以使用下面命令开始训练。
|
||||
|
||||
|
||||
```python
|
||||
# 开始训练识别模型
|
||||
python tools/train.py -c configs/rec/PP-OCRv3/ch_PP-OCRv3_rec_distillation.yml
|
||||
|
||||
```
|
||||
|
||||
## 7. 模型评估
|
||||
在训练之前,我们可以直接使用下面命令来评估预训练模型的效果:
|
||||
|
||||
|
||||
|
||||
```python
|
||||
# 评估预训练模型
|
||||
python tools/eval.py -c configs/rec/PP-OCRv3/ch_PP-OCRv3_rec_distillation.yml -o Global.pretrained_model="./pretrained_models/ch_PP-OCRv3_rec_train/best_accuracy"
|
||||
```
|
||||
```
|
||||
[2022/07/14 10:46:22] ppocr INFO: load pretrain successful from ./pretrained_models/ch_PP-OCRv3_rec_train/best_accuracy
|
||||
eval model:: 100%|████████████████████████████| 687/687 [03:29<00:00, 3.27it/s]
|
||||
[2022/07/14 10:49:52] ppocr INFO: metric eval ***************
|
||||
[2022/07/14 10:49:52] ppocr INFO: acc:0.03724954461811258
|
||||
[2022/07/14 10:49:52] ppocr INFO: norm_edit_dis:0.4859541065843199
|
||||
[2022/07/14 10:49:52] ppocr INFO: Teacher_acc:0.0371584699368947
|
||||
[2022/07/14 10:49:52] ppocr INFO: Teacher_norm_edit_dis:0.48718814890536477
|
||||
[2022/07/14 10:49:52] ppocr INFO: fps:947.8562684823883
|
||||
```
|
||||
|
||||
可以看出,直接加载预训练模型进行评估,效果较差,因为预训练模型并不是基于手写文字进行单独训练的,所以我们需要基于预训练模型进行finetune。
|
||||
训练完成后,可以进行测试评估,评估命令如下:
|
||||
|
||||
|
||||
|
||||
```python
|
||||
# 评估finetune效果
|
||||
python tools/eval.py -c configs/rec/PP-OCRv3/ch_PP-OCRv3_rec_distillation.yml -o Global.pretrained_model="./output/ch_PP-OCR_v3_rec/best_accuracy"
|
||||
|
||||
```
|
||||
|
||||
评估结果如下,可以看出识别准确率为54.3%。
|
||||
```
|
||||
[2022/07/14 10:54:06] ppocr INFO: metric eval ***************
|
||||
[2022/07/14 10:54:06] ppocr INFO: acc:0.5430100180913
|
||||
[2022/07/14 10:54:06] ppocr INFO: norm_edit_dis:0.9203322593158589
|
||||
[2022/07/14 10:54:06] ppocr INFO: Teacher_acc:0.5401183969626324
|
||||
[2022/07/14 10:54:06] ppocr INFO: Teacher_norm_edit_dis:0.919827504507755
|
||||
[2022/07/14 10:54:06] ppocr INFO: fps:928.948733797251
|
||||
```
|
||||
|
||||
如需获取已训练模型,请扫码填写问卷,加入PaddleOCR官方交流群获取全部OCR垂类模型下载链接、《动手学OCR》电子书等全套OCR学习资料🎁
|
||||
<div align="left">
|
||||
<img src="https://ai-studio-static-online.cdn.bcebos.com/dd721099bd50478f9d5fb13d8dd00fad69c22d6848244fd3a1d3980d7fefc63e" width = "150" height = "150" />
|
||||
</div>
|
||||
将下载或训练完成的模型放置在对应目录下即可完成模型推理。
|
||||
|
||||
## 8. 模型导出推理
|
||||
训练完成后,可以将训练模型转换成inference模型。inference 模型会额外保存模型的结构信息,在预测部署、加速推理上性能优越,灵活方便,适合于实际系统集成。
|
||||
|
||||
|
||||
### 8.1 模型导出
|
||||
导出命令如下:
|
||||
|
||||
|
||||
|
||||
```python
|
||||
# 转化为推理模型
|
||||
python tools/export_model.py -c configs/rec/PP-OCRv3/ch_PP-OCRv3_rec_distillation.yml -o Global.pretrained_model="./output/ch_PP-OCR_v3_rec/best_accuracy" Global.save_inference_dir="./inference/rec_ppocrv3/"
|
||||
|
||||
```
|
||||
|
||||
### 8.2 模型推理
|
||||
导出模型后,可以使用如下命令进行推理预测:
|
||||
|
||||
|
||||
|
||||
```python
|
||||
# 推理预测
|
||||
python tools/infer/predict_rec.py --image_dir="train_data/handwrite/HWDB2.0Test_images/104-P16_4.jpg" --rec_model_dir="./inference/rec_ppocrv3/Student"
|
||||
```
|
||||
|
||||
```
|
||||
[2022/07/14 10:55:56] ppocr INFO: In PP-OCRv3, rec_image_shape parameter defaults to '3, 48, 320', if you are using recognition model with PP-OCRv2 or an older version, please set --rec_image_shape='3,32,320
|
||||
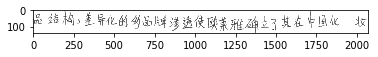
[2022/07/14 10:55:58] ppocr INFO: Predicts of train_data/handwrite/HWDB2.0Test_images/104-P16_4.jpg:('品结构,差异化的多品牌渗透使欧莱雅确立了其在中国化妆', 0.9904912114143372)
|
||||
```
|
||||
|
||||
|
||||
```python
|
||||
# 可视化文字识别图片
|
||||
from PIL import Image
|
||||
import matplotlib.pyplot as plt
|
||||
import numpy as np
|
||||
import os
|
||||
|
||||
|
||||
img_path = 'train_data/handwrite/HWDB2.0Test_images/104-P16_4.jpg'
|
||||
|
||||
def vis(img_path):
|
||||
plt.figure()
|
||||
image = Image.open(img_path)
|
||||
plt.imshow(image)
|
||||
plt.show()
|
||||
# image = image.resize([208, 208])
|
||||
|
||||
|
||||
vis(img_path)
|
||||
```
|
||||
|
||||
|
||||
|
||||
@@ -2,7 +2,7 @@
|
||||
|
||||
## 1. 简介
|
||||
|
||||
PP-OCRv3是百度开源的超轻量级场景文本检测识别模型库,其中超轻量的场景中文识别模型SVTR_LCNet使用了SVTR算法结构。为了保证速度,SVTR_LCNet将SVTR模型的Local Blocks替换为LCNet,使用两层Global Blocks。在中文场景中,PP-OCRv3识别主要使用如下优化策略:
|
||||
PP-OCRv3是百度开源的超轻量级场景文本检测识别模型库,其中超轻量的场景中文识别模型SVTR_LCNet使用了SVTR算法结构。为了保证速度,SVTR_LCNet将SVTR模型的Local Blocks替换为LCNet,使用两层Global Blocks。在中文场景中,PP-OCRv3识别主要使用如下优化策略([详细技术报告](../doc/doc_ch/PP-OCRv3_introduction.md)):
|
||||
- GTC:Attention指导CTC训练策略;
|
||||
- TextConAug:挖掘文字上下文信息的数据增广策略;
|
||||
- TextRotNet:自监督的预训练模型;
|
||||
|
||||
+2
-2
@@ -6,11 +6,11 @@ Global:
|
||||
save_model_dir: ./output/re_layoutlmv2_xfund_zh
|
||||
save_epoch_step: 2000
|
||||
# evaluation is run every 10 iterations after the 0th iteration
|
||||
eval_batch_step: [ 0, 57 ]
|
||||
eval_batch_step: [ 0, 19 ]
|
||||
cal_metric_during_train: False
|
||||
save_inference_dir:
|
||||
use_visualdl: False
|
||||
seed: 2048
|
||||
seed: 2022
|
||||
infer_img: ppstructure/docs/vqa/input/zh_val_21.jpg
|
||||
save_res_path: ./output/re_layoutlmv2_xfund_zh/res/
|
||||
|
||||
+4
-4
@@ -1,9 +1,9 @@
|
||||
Global:
|
||||
use_gpu: True
|
||||
epoch_num: &epoch_num 200
|
||||
epoch_num: &epoch_num 130
|
||||
log_smooth_window: 10
|
||||
print_batch_step: 10
|
||||
save_model_dir: ./output/re_layoutxlm/
|
||||
save_model_dir: ./output/re_layoutxlm_xfund_zh
|
||||
save_epoch_step: 2000
|
||||
# evaluation is run every 10 iterations after the 0th iteration
|
||||
eval_batch_step: [ 0, 19 ]
|
||||
@@ -12,7 +12,7 @@ Global:
|
||||
use_visualdl: False
|
||||
seed: 2022
|
||||
infer_img: ppstructure/docs/vqa/input/zh_val_21.jpg
|
||||
save_res_path: ./output/re/
|
||||
save_res_path: ./output/re_layoutxlm_xfund_zh/res/
|
||||
|
||||
Architecture:
|
||||
model_type: vqa
|
||||
@@ -81,7 +81,7 @@ Train:
|
||||
loader:
|
||||
shuffle: True
|
||||
drop_last: False
|
||||
batch_size_per_card: 8
|
||||
batch_size_per_card: 2
|
||||
num_workers: 8
|
||||
collate_fn: ListCollator
|
||||
|
||||
+3
-2
@@ -6,13 +6,13 @@ Global:
|
||||
save_model_dir: ./output/ser_layoutlm_xfund_zh
|
||||
save_epoch_step: 2000
|
||||
# evaluation is run every 10 iterations after the 0th iteration
|
||||
eval_batch_step: [ 0, 57 ]
|
||||
eval_batch_step: [ 0, 19 ]
|
||||
cal_metric_during_train: False
|
||||
save_inference_dir:
|
||||
use_visualdl: False
|
||||
seed: 2022
|
||||
infer_img: ppstructure/docs/vqa/input/zh_val_42.jpg
|
||||
save_res_path: ./output/ser_layoutlm_xfund_zh/res/
|
||||
save_res_path: ./output/re_layoutlm_xfund_zh/res
|
||||
|
||||
Architecture:
|
||||
model_type: vqa
|
||||
@@ -55,6 +55,7 @@ Train:
|
||||
data_dir: train_data/XFUND/zh_train/image
|
||||
label_file_list:
|
||||
- train_data/XFUND/zh_train/train.json
|
||||
ratio_list: [ 1.0 ]
|
||||
transforms:
|
||||
- DecodeImage: # load image
|
||||
img_mode: RGB
|
||||
+1
@@ -27,6 +27,7 @@ Architecture:
|
||||
Loss:
|
||||
name: VQASerTokenLayoutLMLoss
|
||||
num_classes: *num_classes
|
||||
key: "backbone_out"
|
||||
|
||||
Optimizer:
|
||||
name: AdamW
|
||||
+1
@@ -27,6 +27,7 @@ Architecture:
|
||||
Loss:
|
||||
name: VQASerTokenLayoutLMLoss
|
||||
num_classes: *num_classes
|
||||
key: "backbone_out"
|
||||
|
||||
Optimizer:
|
||||
name: AdamW
|
||||
+20
-20
@@ -1,18 +1,18 @@
|
||||
Global:
|
||||
use_gpu: True
|
||||
epoch_num: &epoch_num 200
|
||||
epoch_num: &epoch_num 130
|
||||
log_smooth_window: 10
|
||||
print_batch_step: 10
|
||||
save_model_dir: ./output/re_layoutxlm_funsd
|
||||
save_model_dir: ./output/re_vi_layoutxlm_xfund_zh
|
||||
save_epoch_step: 2000
|
||||
# evaluation is run every 10 iterations after the 0th iteration
|
||||
eval_batch_step: [ 0, 57 ]
|
||||
eval_batch_step: [ 0, 19 ]
|
||||
cal_metric_during_train: False
|
||||
save_inference_dir:
|
||||
use_visualdl: False
|
||||
seed: 2022
|
||||
infer_img: train_data/FUNSD/testing_data/images/83624198.png
|
||||
save_res_path: ./output/re_layoutxlm_funsd/res/
|
||||
infer_img: ppstructure/docs/vqa/input/zh_val_21.jpg
|
||||
save_res_path: ./output/re/xfund_zh/with_gt
|
||||
|
||||
Architecture:
|
||||
model_type: vqa
|
||||
@@ -21,6 +21,7 @@ Architecture:
|
||||
Backbone:
|
||||
name: LayoutXLMForRe
|
||||
pretrained: True
|
||||
mode: vi
|
||||
checkpoints:
|
||||
|
||||
Loss:
|
||||
@@ -50,10 +51,9 @@ Metric:
|
||||
Train:
|
||||
dataset:
|
||||
name: SimpleDataSet
|
||||
data_dir: ./train_data/FUNSD/training_data/images/
|
||||
data_dir: train_data/XFUND/zh_train/image
|
||||
label_file_list:
|
||||
- ./train_data/FUNSD/train_v4.json
|
||||
# - ./train_data/FUNSD/train.json
|
||||
- train_data/XFUND/zh_train/train.json
|
||||
ratio_list: [ 1.0 ]
|
||||
transforms:
|
||||
- DecodeImage: # load image
|
||||
@@ -62,8 +62,9 @@ Train:
|
||||
- VQATokenLabelEncode: # Class handling label
|
||||
contains_re: True
|
||||
algorithm: *algorithm
|
||||
class_path: &class_path ./train_data/FUNSD/class_list.txt
|
||||
class_path: &class_path train_data/XFUND/class_list_xfun.txt
|
||||
use_textline_bbox_info: &use_textline_bbox_info True
|
||||
order_method: &order_method "tb-yx"
|
||||
- VQATokenPad:
|
||||
max_seq_len: &max_seq_len 512
|
||||
return_attention_mask: True
|
||||
@@ -79,22 +80,20 @@ Train:
|
||||
order: 'hwc'
|
||||
- ToCHWImage:
|
||||
- KeepKeys:
|
||||
# dataloader will return list in this order
|
||||
keep_keys: [ 'input_ids', 'bbox', 'attention_mask', 'token_type_ids', 'image', 'entities', 'relations']
|
||||
keep_keys: [ 'input_ids', 'bbox','attention_mask', 'token_type_ids', 'image', 'entities', 'relations'] # dataloader will return list in this order
|
||||
loader:
|
||||
shuffle: False
|
||||
shuffle: True
|
||||
drop_last: False
|
||||
batch_size_per_card: 8
|
||||
num_workers: 16
|
||||
batch_size_per_card: 2
|
||||
num_workers: 4
|
||||
collate_fn: ListCollator
|
||||
|
||||
Eval:
|
||||
dataset:
|
||||
name: SimpleDataSet
|
||||
data_dir: ./train_data/FUNSD/testing_data/images/
|
||||
label_file_list:
|
||||
- ./train_data/FUNSD/test_v4.json
|
||||
# - ./train_data/FUNSD/test.json
|
||||
data_dir: train_data/XFUND/zh_val/image
|
||||
label_file_list:
|
||||
- train_data/XFUND/zh_val/val.json
|
||||
transforms:
|
||||
- DecodeImage: # load image
|
||||
img_mode: RGB
|
||||
@@ -104,6 +103,7 @@ Eval:
|
||||
algorithm: *algorithm
|
||||
class_path: *class_path
|
||||
use_textline_bbox_info: *use_textline_bbox_info
|
||||
order_method: *order_method
|
||||
- VQATokenPad:
|
||||
max_seq_len: *max_seq_len
|
||||
return_attention_mask: True
|
||||
@@ -119,11 +119,11 @@ Eval:
|
||||
order: 'hwc'
|
||||
- ToCHWImage:
|
||||
- KeepKeys:
|
||||
# dataloader will return list in this order
|
||||
keep_keys: [ 'input_ids', 'bbox', 'attention_mask', 'token_type_ids', 'image', 'entities', 'relations']
|
||||
keep_keys: [ 'input_ids', 'bbox', 'attention_mask', 'token_type_ids', 'image', 'entities', 'relations'] # dataloader will return list in this order
|
||||
loader:
|
||||
shuffle: False
|
||||
drop_last: False
|
||||
batch_size_per_card: 8
|
||||
num_workers: 8
|
||||
collate_fn: ListCollator
|
||||
|
||||
@@ -0,0 +1,175 @@
|
||||
Global:
|
||||
use_gpu: True
|
||||
epoch_num: &epoch_num 130
|
||||
log_smooth_window: 10
|
||||
print_batch_step: 10
|
||||
save_model_dir: ./output/re_vi_layoutxlm_xfund_zh_udml
|
||||
save_epoch_step: 2000
|
||||
# evaluation is run every 10 iterations after the 0th iteration
|
||||
eval_batch_step: [ 0, 19 ]
|
||||
cal_metric_during_train: False
|
||||
save_inference_dir:
|
||||
use_visualdl: False
|
||||
seed: 2022
|
||||
infer_img: ppstructure/docs/vqa/input/zh_val_21.jpg
|
||||
save_res_path: ./output/re/xfund_zh/with_gt
|
||||
|
||||
Architecture:
|
||||
model_type: &model_type "vqa"
|
||||
name: DistillationModel
|
||||
algorithm: Distillation
|
||||
Models:
|
||||
Teacher:
|
||||
pretrained:
|
||||
freeze_params: false
|
||||
return_all_feats: true
|
||||
model_type: *model_type
|
||||
algorithm: &algorithm "LayoutXLM"
|
||||
Transform:
|
||||
Backbone:
|
||||
name: LayoutXLMForRe
|
||||
pretrained: True
|
||||
mode: vi
|
||||
checkpoints:
|
||||
Student:
|
||||
pretrained:
|
||||
freeze_params: false
|
||||
return_all_feats: true
|
||||
model_type: *model_type
|
||||
algorithm: *algorithm
|
||||
Transform:
|
||||
Backbone:
|
||||
name: LayoutXLMForRe
|
||||
pretrained: True
|
||||
mode: vi
|
||||
checkpoints:
|
||||
|
||||
Loss:
|
||||
name: CombinedLoss
|
||||
loss_config_list:
|
||||
- DistillationLossFromOutput:
|
||||
weight: 1.0
|
||||
model_name_list: ["Student", "Teacher"]
|
||||
key: loss
|
||||
reduction: mean
|
||||
- DistillationVQADistanceLoss:
|
||||
weight: 0.5
|
||||
mode: "l2"
|
||||
model_name_pairs:
|
||||
- ["Student", "Teacher"]
|
||||
key: hidden_states_5
|
||||
name: "loss_5"
|
||||
- DistillationVQADistanceLoss:
|
||||
weight: 0.5
|
||||
mode: "l2"
|
||||
model_name_pairs:
|
||||
- ["Student", "Teacher"]
|
||||
key: hidden_states_8
|
||||
name: "loss_8"
|
||||
|
||||
|
||||
Optimizer:
|
||||
name: AdamW
|
||||
beta1: 0.9
|
||||
beta2: 0.999
|
||||
clip_norm: 10
|
||||
lr:
|
||||
learning_rate: 0.00005
|
||||
warmup_epoch: 10
|
||||
regularizer:
|
||||
name: L2
|
||||
factor: 0.00000
|
||||
|
||||
PostProcess:
|
||||
name: DistillationRePostProcess
|
||||
model_name: ["Student", "Teacher"]
|
||||
key: null
|
||||
|
||||
|
||||
Metric:
|
||||
name: DistillationMetric
|
||||
base_metric_name: VQAReTokenMetric
|
||||
main_indicator: hmean
|
||||
key: "Student"
|
||||
|
||||
Train:
|
||||
dataset:
|
||||
name: SimpleDataSet
|
||||
data_dir: train_data/XFUND/zh_train/image
|
||||
label_file_list:
|
||||
- train_data/XFUND/zh_train/train.json
|
||||
ratio_list: [ 1.0 ]
|
||||
transforms:
|
||||
- DecodeImage: # load image
|
||||
img_mode: RGB
|
||||
channel_first: False
|
||||
- VQATokenLabelEncode: # Class handling label
|
||||
contains_re: True
|
||||
algorithm: *algorithm
|
||||
class_path: &class_path train_data/XFUND/class_list_xfun.txt
|
||||
use_textline_bbox_info: &use_textline_bbox_info True
|
||||
# [None, "tb-yx"]
|
||||
order_method: &order_method "tb-yx"
|
||||
- VQATokenPad:
|
||||
max_seq_len: &max_seq_len 512
|
||||
return_attention_mask: True
|
||||
- VQAReTokenRelation:
|
||||
- VQAReTokenChunk:
|
||||
max_seq_len: *max_seq_len
|
||||
- Resize:
|
||||
size: [224,224]
|
||||
- NormalizeImage:
|
||||
scale: 1
|
||||
mean: [ 123.675, 116.28, 103.53 ]
|
||||
std: [ 58.395, 57.12, 57.375 ]
|
||||
order: 'hwc'
|
||||
- ToCHWImage:
|
||||
- KeepKeys:
|
||||
keep_keys: [ 'input_ids', 'bbox','attention_mask', 'token_type_ids', 'image', 'entities', 'relations'] # dataloader will return list in this order
|
||||
loader:
|
||||
shuffle: True
|
||||
drop_last: False
|
||||
batch_size_per_card: 2
|
||||
num_workers: 4
|
||||
collate_fn: ListCollator
|
||||
|
||||
Eval:
|
||||
dataset:
|
||||
name: SimpleDataSet
|
||||
data_dir: train_data/XFUND/zh_val/image
|
||||
label_file_list:
|
||||
- train_data/XFUND/zh_val/val.json
|
||||
transforms:
|
||||
- DecodeImage: # load image
|
||||
img_mode: RGB
|
||||
channel_first: False
|
||||
- VQATokenLabelEncode: # Class handling label
|
||||
contains_re: True
|
||||
algorithm: *algorithm
|
||||
class_path: *class_path
|
||||
use_textline_bbox_info: *use_textline_bbox_info
|
||||
order_method: *order_method
|
||||
- VQATokenPad:
|
||||
max_seq_len: *max_seq_len
|
||||
return_attention_mask: True
|
||||
- VQAReTokenRelation:
|
||||
- VQAReTokenChunk:
|
||||
max_seq_len: *max_seq_len
|
||||
- Resize:
|
||||
size: [224,224]
|
||||
- NormalizeImage:
|
||||
scale: 1
|
||||
mean: [ 123.675, 116.28, 103.53 ]
|
||||
std: [ 58.395, 57.12, 57.375 ]
|
||||
order: 'hwc'
|
||||
- ToCHWImage:
|
||||
- KeepKeys:
|
||||
keep_keys: [ 'input_ids', 'bbox', 'attention_mask', 'token_type_ids', 'image', 'entities', 'relations'] # dataloader will return list in this order
|
||||
loader:
|
||||
shuffle: False
|
||||
drop_last: False
|
||||
batch_size_per_card: 8
|
||||
num_workers: 8
|
||||
collate_fn: ListCollator
|
||||
|
||||
|
||||
+25
-15
@@ -3,30 +3,38 @@ Global:
|
||||
epoch_num: &epoch_num 200
|
||||
log_smooth_window: 10
|
||||
print_batch_step: 10
|
||||
save_model_dir: ./output/ser_layoutlm_funsd
|
||||
save_model_dir: ./output/ser_vi_layoutxlm_xfund_zh
|
||||
save_epoch_step: 2000
|
||||
# evaluation is run every 10 iterations after the 0th iteration
|
||||
eval_batch_step: [ 0, 57 ]
|
||||
eval_batch_step: [ 0, 19 ]
|
||||
cal_metric_during_train: False
|
||||
save_inference_dir:
|
||||
use_visualdl: False
|
||||
seed: 2022
|
||||
infer_img: train_data/FUNSD/testing_data/images/83624198.png
|
||||
save_res_path: ./output/ser_layoutlm_funsd/res/
|
||||
infer_img: ppstructure/docs/vqa/input/zh_val_42.jpg
|
||||
# if you want to predict using the groundtruth ocr info,
|
||||
# you can use the following config
|
||||
# infer_img: train_data/XFUND/zh_val/val.json
|
||||
# infer_mode: False
|
||||
|
||||
save_res_path: ./output/ser/xfund_zh/res
|
||||
|
||||
Architecture:
|
||||
model_type: vqa
|
||||
algorithm: &algorithm "LayoutLM"
|
||||
algorithm: &algorithm "LayoutXLM"
|
||||
Transform:
|
||||
Backbone:
|
||||
name: LayoutLMForSer
|
||||
name: LayoutXLMForSer
|
||||
pretrained: True
|
||||
checkpoints:
|
||||
# one of base or vi
|
||||
mode: vi
|
||||
num_classes: &num_classes 7
|
||||
|
||||
Loss:
|
||||
name: VQASerTokenLayoutLMLoss
|
||||
num_classes: *num_classes
|
||||
key: "backbone_out"
|
||||
|
||||
Optimizer:
|
||||
name: AdamW
|
||||
@@ -43,7 +51,7 @@ Optimizer:
|
||||
|
||||
PostProcess:
|
||||
name: VQASerTokenLayoutLMPostProcess
|
||||
class_path: &class_path ./train_data/FUNSD/class_list.txt
|
||||
class_path: &class_path train_data/XFUND/class_list_xfun.txt
|
||||
|
||||
Metric:
|
||||
name: VQASerTokenMetric
|
||||
@@ -52,9 +60,10 @@ Metric:
|
||||
Train:
|
||||
dataset:
|
||||
name: SimpleDataSet
|
||||
data_dir: ./train_data/FUNSD/training_data/images/
|
||||
data_dir: train_data/XFUND/zh_train/image
|
||||
label_file_list:
|
||||
- ./train_data/FUNSD/train.json
|
||||
- train_data/XFUND/zh_train/train.json
|
||||
ratio_list: [ 1.0 ]
|
||||
transforms:
|
||||
- DecodeImage: # load image
|
||||
img_mode: RGB
|
||||
@@ -64,6 +73,8 @@ Train:
|
||||
algorithm: *algorithm
|
||||
class_path: *class_path
|
||||
use_textline_bbox_info: &use_textline_bbox_info True
|
||||
# one of [None, "tb-yx"]
|
||||
order_method: &order_method "tb-yx"
|
||||
- VQATokenPad:
|
||||
max_seq_len: &max_seq_len 512
|
||||
return_attention_mask: True
|
||||
@@ -78,8 +89,7 @@ Train:
|
||||
order: 'hwc'
|
||||
- ToCHWImage:
|
||||
- KeepKeys:
|
||||
# dataloader will return list in this order
|
||||
keep_keys: [ 'input_ids', 'bbox', 'attention_mask', 'token_type_ids', 'image', 'labels']
|
||||
keep_keys: [ 'input_ids', 'bbox', 'attention_mask', 'token_type_ids', 'image', 'labels'] # dataloader will return list in this order
|
||||
loader:
|
||||
shuffle: True
|
||||
drop_last: False
|
||||
@@ -89,9 +99,9 @@ Train:
|
||||
Eval:
|
||||
dataset:
|
||||
name: SimpleDataSet
|
||||
data_dir: train_data/FUNSD/testing_data/images/
|
||||
data_dir: train_data/XFUND/zh_val/image
|
||||
label_file_list:
|
||||
- ./train_data/FUNSD/test.json
|
||||
- train_data/XFUND/zh_val/val.json
|
||||
transforms:
|
||||
- DecodeImage: # load image
|
||||
img_mode: RGB
|
||||
@@ -101,6 +111,7 @@ Eval:
|
||||
algorithm: *algorithm
|
||||
class_path: *class_path
|
||||
use_textline_bbox_info: *use_textline_bbox_info
|
||||
order_method: *order_method
|
||||
- VQATokenPad:
|
||||
max_seq_len: *max_seq_len
|
||||
return_attention_mask: True
|
||||
@@ -115,8 +126,7 @@ Eval:
|
||||
order: 'hwc'
|
||||
- ToCHWImage:
|
||||
- KeepKeys:
|
||||
# dataloader will return list in this order
|
||||
keep_keys: [ 'input_ids', 'bbox', 'attention_mask', 'token_type_ids', 'image', 'labels']
|
||||
keep_keys: [ 'input_ids', 'bbox', 'attention_mask', 'token_type_ids', 'image', 'labels'] # dataloader will return list in this order
|
||||
loader:
|
||||
shuffle: False
|
||||
drop_last: False
|
||||
@@ -0,0 +1,183 @@
|
||||
Global:
|
||||
use_gpu: True
|
||||
epoch_num: &epoch_num 200
|
||||
log_smooth_window: 10
|
||||
print_batch_step: 10
|
||||
save_model_dir: ./output/ser_vi_layoutxlm_xfund_zh_udml
|
||||
save_epoch_step: 2000
|
||||
# evaluation is run every 10 iterations after the 0th iteration
|
||||
eval_batch_step: [ 0, 19 ]
|
||||
cal_metric_during_train: False
|
||||
save_inference_dir:
|
||||
use_visualdl: False
|
||||
seed: 2022
|
||||
infer_img: ppstructure/docs/vqa/input/zh_val_42.jpg
|
||||
save_res_path: ./output/ser_layoutxlm_xfund_zh/res
|
||||
|
||||
|
||||
Architecture:
|
||||
model_type: &model_type "vqa"
|
||||
name: DistillationModel
|
||||
algorithm: Distillation
|
||||
Models:
|
||||
Teacher:
|
||||
pretrained:
|
||||
freeze_params: false
|
||||
return_all_feats: true
|
||||
model_type: *model_type
|
||||
algorithm: &algorithm "LayoutXLM"
|
||||
Transform:
|
||||
Backbone:
|
||||
name: LayoutXLMForSer
|
||||
pretrained: True
|
||||
# one of base or vi
|
||||
mode: vi
|
||||
checkpoints:
|
||||
num_classes: &num_classes 7
|
||||
Student:
|
||||
pretrained:
|
||||
freeze_params: false
|
||||
return_all_feats: true
|
||||
model_type: *model_type
|
||||
algorithm: *algorithm
|
||||
Transform:
|
||||
Backbone:
|
||||
name: LayoutXLMForSer
|
||||
pretrained: True
|
||||
# one of base or vi
|
||||
mode: vi
|
||||
checkpoints:
|
||||
num_classes: *num_classes
|
||||
|
||||
|
||||
Loss:
|
||||
name: CombinedLoss
|
||||
loss_config_list:
|
||||
- DistillationVQASerTokenLayoutLMLoss:
|
||||
weight: 1.0
|
||||
model_name_list: ["Student", "Teacher"]
|
||||
key: backbone_out
|
||||
num_classes: *num_classes
|
||||
- DistillationSERDMLLoss:
|
||||
weight: 1.0
|
||||
act: "softmax"
|
||||
use_log: true
|
||||
model_name_pairs:
|
||||
- ["Student", "Teacher"]
|
||||
key: backbone_out
|
||||
- DistillationVQADistanceLoss:
|
||||
weight: 0.5
|
||||
mode: "l2"
|
||||
model_name_pairs:
|
||||
- ["Student", "Teacher"]
|
||||
key: hidden_states_5
|
||||
name: "loss_5"
|
||||
- DistillationVQADistanceLoss:
|
||||
weight: 0.5
|
||||
mode: "l2"
|
||||
model_name_pairs:
|
||||
- ["Student", "Teacher"]
|
||||
key: hidden_states_8
|
||||
name: "loss_8"
|
||||
|
||||
|
||||
|
||||
Optimizer:
|
||||
name: AdamW
|
||||
beta1: 0.9
|
||||
beta2: 0.999
|
||||
lr:
|
||||
name: Linear
|
||||
learning_rate: 0.00005
|
||||
epochs: *epoch_num
|
||||
warmup_epoch: 10
|
||||
regularizer:
|
||||
name: L2
|
||||
factor: 0.00000
|
||||
|
||||
PostProcess:
|
||||
name: DistillationSerPostProcess
|
||||
model_name: ["Student", "Teacher"]
|
||||
key: backbone_out
|
||||
class_path: &class_path train_data/XFUND/class_list_xfun.txt
|
||||
|
||||
Metric:
|
||||
name: DistillationMetric
|
||||
base_metric_name: VQASerTokenMetric
|
||||
main_indicator: hmean
|
||||
key: "Student"
|
||||
|
||||
Train:
|
||||
dataset:
|
||||
name: SimpleDataSet
|
||||
data_dir: train_data/XFUND/zh_train/image
|
||||
label_file_list:
|
||||
- train_data/XFUND/zh_train/train.json
|
||||
ratio_list: [ 1.0 ]
|
||||
transforms:
|
||||
- DecodeImage: # load image
|
||||
img_mode: RGB
|
||||
channel_first: False
|
||||
- VQATokenLabelEncode: # Class handling label
|
||||
contains_re: False
|
||||
algorithm: *algorithm
|
||||
class_path: *class_path
|
||||
# one of [None, "tb-yx"]
|
||||
order_method: &order_method "tb-yx"
|
||||
- VQATokenPad:
|
||||
max_seq_len: &max_seq_len 512
|
||||
return_attention_mask: True
|
||||
- VQASerTokenChunk:
|
||||
max_seq_len: *max_seq_len
|
||||
- Resize:
|
||||
size: [224,224]
|
||||
- NormalizeImage:
|
||||
scale: 1
|
||||
mean: [ 123.675, 116.28, 103.53 ]
|
||||
std: [ 58.395, 57.12, 57.375 ]
|
||||
order: 'hwc'
|
||||
- ToCHWImage:
|
||||
- KeepKeys:
|
||||
keep_keys: [ 'input_ids', 'bbox', 'attention_mask', 'token_type_ids', 'image', 'labels'] # dataloader will return list in this order
|
||||
loader:
|
||||
shuffle: True
|
||||
drop_last: False
|
||||
batch_size_per_card: 4
|
||||
num_workers: 4
|
||||
|
||||
Eval:
|
||||
dataset:
|
||||
name: SimpleDataSet
|
||||
data_dir: train_data/XFUND/zh_val/image
|
||||
label_file_list:
|
||||
- train_data/XFUND/zh_val/val.json
|
||||
transforms:
|
||||
- DecodeImage: # load image
|
||||
img_mode: RGB
|
||||
channel_first: False
|
||||
- VQATokenLabelEncode: # Class handling label
|
||||
contains_re: False
|
||||
algorithm: *algorithm
|
||||
class_path: *class_path
|
||||
order_method: *order_method
|
||||
- VQATokenPad:
|
||||
max_seq_len: *max_seq_len
|
||||
return_attention_mask: True
|
||||
- VQASerTokenChunk:
|
||||
max_seq_len: *max_seq_len
|
||||
- Resize:
|
||||
size: [224,224]
|
||||
- NormalizeImage:
|
||||
scale: 1
|
||||
mean: [ 123.675, 116.28, 103.53 ]
|
||||
std: [ 58.395, 57.12, 57.375 ]
|
||||
order: 'hwc'
|
||||
- ToCHWImage:
|
||||
- KeepKeys:
|
||||
keep_keys: [ 'input_ids', 'bbox', 'attention_mask', 'token_type_ids', 'image', 'labels'] # dataloader will return list in this order
|
||||
loader:
|
||||
shuffle: False
|
||||
drop_last: False
|
||||
batch_size_per_card: 8
|
||||
num_workers: 4
|
||||
|
||||
@@ -1,125 +0,0 @@
|
||||
Global:
|
||||
use_gpu: True
|
||||
epoch_num: &epoch_num 200
|
||||
log_smooth_window: 10
|
||||
print_batch_step: 10
|
||||
save_model_dir: ./output/re_layoutlmv2_funsd
|
||||
save_epoch_step: 2000
|
||||
# evaluation is run every 10 iterations after the 0th iteration
|
||||
eval_batch_step: [ 0, 57 ]
|
||||
cal_metric_during_train: False
|
||||
save_inference_dir:
|
||||
use_visualdl: False
|
||||
seed: 2022
|
||||
infer_img: train_data/FUNSD/testing_data/images/83624198.png
|
||||
save_res_path: ./output/re_layoutlmv2_funsd/res/
|
||||
|
||||
Architecture:
|
||||
model_type: vqa
|
||||
algorithm: &algorithm "LayoutLMv2"
|
||||
Transform:
|
||||
Backbone:
|
||||
name: LayoutLMv2ForRe
|
||||
pretrained: True
|
||||
checkpoints:
|
||||
|
||||
Loss:
|
||||
name: LossFromOutput
|
||||
key: loss
|
||||
reduction: mean
|
||||
|
||||
Optimizer:
|
||||
name: AdamW
|
||||
beta1: 0.9
|
||||
beta2: 0.999
|
||||
clip_norm: 10
|
||||
lr:
|
||||
learning_rate: 0.00005
|
||||
warmup_epoch: 10
|
||||
regularizer:
|
||||
name: L2
|
||||
factor: 0.00000
|
||||
|
||||
PostProcess:
|
||||
name: VQAReTokenLayoutLMPostProcess
|
||||
|
||||
Metric:
|
||||
name: VQAReTokenMetric
|
||||
main_indicator: hmean
|
||||
|
||||
Train:
|
||||
dataset:
|
||||
name: SimpleDataSet
|
||||
data_dir: ./train_data/FUNSD/training_data/images/
|
||||
label_file_list:
|
||||
- ./train_data/FUNSD/train.json
|
||||
ratio_list: [ 1.0 ]
|
||||
transforms:
|
||||
- DecodeImage: # load image
|
||||
img_mode: RGB
|
||||
channel_first: False
|
||||
- VQATokenLabelEncode: # Class handling label
|
||||
contains_re: True
|
||||
algorithm: *algorithm
|
||||
class_path: &class_path train_data/FUNSD/class_list.txt
|
||||
- VQATokenPad:
|
||||
max_seq_len: &max_seq_len 512
|
||||
return_attention_mask: True
|
||||
- VQAReTokenRelation:
|
||||
- VQAReTokenChunk:
|
||||
max_seq_len: *max_seq_len
|
||||
- Resize:
|
||||
size: [224,224]
|
||||
- NormalizeImage:
|
||||
scale: 1./255.
|
||||
mean: [0.485, 0.456, 0.406]
|
||||
std: [0.229, 0.224, 0.225]
|
||||
order: 'hwc'
|
||||
- ToCHWImage:
|
||||
- KeepKeys:
|
||||
# dataloader will return list in this order
|
||||
keep_keys: [ 'input_ids', 'bbox', 'attention_mask', 'token_type_ids', 'image', 'entities', 'relations']
|
||||
loader:
|
||||
shuffle: True
|
||||
drop_last: False
|
||||
batch_size_per_card: 8
|
||||
num_workers: 8
|
||||
collate_fn: ListCollator
|
||||
|
||||
Eval:
|
||||
dataset:
|
||||
name: SimpleDataSet
|
||||
data_dir: ./train_data/FUNSD/testing_data/images/
|
||||
label_file_list:
|
||||
- ./train_data/FUNSD/test.json
|
||||
transforms:
|
||||
- DecodeImage: # load image
|
||||
img_mode: RGB
|
||||
channel_first: False
|
||||
- VQATokenLabelEncode: # Class handling label
|
||||
contains_re: True
|
||||
algorithm: *algorithm
|
||||
class_path: *class_path
|
||||
- VQATokenPad:
|
||||
max_seq_len: *max_seq_len
|
||||
return_attention_mask: True
|
||||
- VQAReTokenRelation:
|
||||
- VQAReTokenChunk:
|
||||
max_seq_len: *max_seq_len
|
||||
- Resize:
|
||||
size: [224,224]
|
||||
- NormalizeImage:
|
||||
scale: 1./255.
|
||||
mean: [0.485, 0.456, 0.406]
|
||||
std: [0.229, 0.224, 0.225]
|
||||
order: 'hwc'
|
||||
- ToCHWImage:
|
||||
- KeepKeys:
|
||||
# dataloader will return list in this order
|
||||
keep_keys: [ 'input_ids', 'bbox', 'attention_mask', 'token_type_ids', 'image', 'entities', 'relations']
|
||||
loader:
|
||||
shuffle: False
|
||||
drop_last: False
|
||||
batch_size_per_card: 8
|
||||
num_workers: 8
|
||||
collate_fn: ListCollator
|
||||
@@ -1,124 +0,0 @@
|
||||
Global:
|
||||
use_gpu: True
|
||||
epoch_num: &epoch_num 200
|
||||
log_smooth_window: 10
|
||||
print_batch_step: 10
|
||||
save_model_dir: ./output/ser_layoutlm_sroie
|
||||
save_epoch_step: 2000
|
||||
# evaluation is run every 10 iterations after the 0th iteration
|
||||
eval_batch_step: [ 0, 200 ]
|
||||
cal_metric_during_train: False
|
||||
save_inference_dir:
|
||||
use_visualdl: False
|
||||
seed: 2022
|
||||
infer_img: train_data/SROIE/test/X00016469670.jpg
|
||||
save_res_path: ./output/ser_layoutlm_sroie/res/
|
||||
|
||||
Architecture:
|
||||
model_type: vqa
|
||||
algorithm: &algorithm "LayoutLM"
|
||||
Transform:
|
||||
Backbone:
|
||||
name: LayoutLMForSer
|
||||
pretrained: True
|
||||
checkpoints:
|
||||
num_classes: &num_classes 9
|
||||
|
||||
Loss:
|
||||
name: VQASerTokenLayoutLMLoss
|
||||
num_classes: *num_classes
|
||||
|
||||
Optimizer:
|
||||
name: AdamW
|
||||
beta1: 0.9
|
||||
beta2: 0.999
|
||||
lr:
|
||||
name: Linear
|
||||
learning_rate: 0.00005
|
||||
epochs: *epoch_num
|
||||
warmup_epoch: 2
|
||||
regularizer:
|
||||
name: L2
|
||||
factor: 0.00000
|
||||
|
||||
PostProcess:
|
||||
name: VQASerTokenLayoutLMPostProcess
|
||||
class_path: &class_path ./train_data/SROIE/class_list.txt
|
||||
|
||||
Metric:
|
||||
name: VQASerTokenMetric
|
||||
main_indicator: hmean
|
||||
|
||||
Train:
|
||||
dataset:
|
||||
name: SimpleDataSet
|
||||
data_dir: ./train_data/SROIE/train
|
||||
label_file_list:
|
||||
- ./train_data/SROIE/train.txt
|
||||
transforms:
|
||||
- DecodeImage: # load image
|
||||
img_mode: RGB
|
||||
channel_first: False
|
||||
- VQATokenLabelEncode: # Class handling label
|
||||
contains_re: False
|
||||
algorithm: *algorithm
|
||||
class_path: *class_path
|
||||
use_textline_bbox_info: &use_textline_bbox_info True
|
||||
- VQATokenPad:
|
||||
max_seq_len: &max_seq_len 512
|
||||
return_attention_mask: True
|
||||
- VQASerTokenChunk:
|
||||
max_seq_len: *max_seq_len
|
||||
- Resize:
|
||||
size: [224,224]
|
||||
- NormalizeImage:
|
||||
scale: 1
|
||||
mean: [ 123.675, 116.28, 103.53 ]
|
||||
std: [ 58.395, 57.12, 57.375 ]
|
||||
order: 'hwc'
|
||||
- ToCHWImage:
|
||||
- KeepKeys:
|
||||
# dataloader will return list in this order
|
||||
keep_keys: [ 'input_ids', 'bbox', 'attention_mask', 'token_type_ids', 'image', 'labels']
|
||||
loader:
|
||||
shuffle: True
|
||||
drop_last: False
|
||||
batch_size_per_card: 8
|
||||
num_workers: 4
|
||||
|
||||
Eval:
|
||||
dataset:
|
||||
name: SimpleDataSet
|
||||
data_dir: ./train_data/SROIE/test
|
||||
label_file_list:
|
||||
- ./train_data/SROIE/test.txt
|
||||
transforms:
|
||||
- DecodeImage: # load image
|
||||
img_mode: RGB
|
||||
channel_first: False
|
||||
- VQATokenLabelEncode: # Class handling label
|
||||
contains_re: False
|
||||
algorithm: *algorithm
|
||||
class_path: *class_path
|
||||
use_textline_bbox_info: *use_textline_bbox_info
|
||||
- VQATokenPad:
|
||||
max_seq_len: *max_seq_len
|
||||
return_attention_mask: True
|
||||
- VQASerTokenChunk:
|
||||
max_seq_len: *max_seq_len
|
||||
- Resize:
|
||||
size: [224,224]
|
||||
- NormalizeImage:
|
||||
scale: 1
|
||||
mean: [ 123.675, 116.28, 103.53 ]
|
||||
std: [ 58.395, 57.12, 57.375 ]
|
||||
order: 'hwc'
|
||||
- ToCHWImage:
|
||||
- KeepKeys:
|
||||
# dataloader will return list in this order
|
||||
keep_keys: [ 'input_ids', 'bbox', 'attention_mask', 'token_type_ids', 'image', 'labels']
|
||||
loader:
|
||||
shuffle: False
|
||||
drop_last: False
|
||||
batch_size_per_card: 8
|
||||
num_workers: 4
|
||||
@@ -1,123 +0,0 @@
|
||||
Global:
|
||||
use_gpu: True
|
||||
epoch_num: &epoch_num 200
|
||||
log_smooth_window: 10
|
||||
print_batch_step: 10
|
||||
save_model_dir: ./output/ser_layoutlmv2_funsd
|
||||
save_epoch_step: 2000
|
||||
# evaluation is run every 10 iterations after the 0th iteration
|
||||
eval_batch_step: [ 0, 100 ]
|
||||
cal_metric_during_train: False
|
||||
save_inference_dir:
|
||||
use_visualdl: False
|
||||
seed: 2022
|
||||
infer_img: train_data/FUNSD/testing_data/images/83624198.png
|
||||
save_res_path: ./output/ser_layoutlmv2_funsd/res/
|
||||
|
||||
Architecture:
|
||||
model_type: vqa
|
||||
algorithm: &algorithm "LayoutLMv2"
|
||||
Transform:
|
||||
Backbone:
|
||||
name: LayoutLMv2ForSer
|
||||
pretrained: True
|
||||
checkpoints:
|
||||
num_classes: &num_classes 7
|
||||
|
||||
Loss:
|
||||
name: VQASerTokenLayoutLMLoss
|
||||
num_classes: *num_classes
|
||||
|
||||
Optimizer:
|
||||
name: AdamW
|
||||
beta1: 0.9
|
||||
beta2: 0.999
|
||||
lr:
|
||||
name: Linear
|
||||
learning_rate: 0.00005
|
||||
epochs: *epoch_num
|
||||
warmup_epoch: 2
|
||||
regularizer:
|
||||
|
||||
name: L2
|
||||
factor: 0.00000
|
||||
|
||||
PostProcess:
|
||||
name: VQASerTokenLayoutLMPostProcess
|
||||
class_path: &class_path train_data/FUNSD/class_list.txt
|
||||
|
||||
Metric:
|
||||
name: VQASerTokenMetric
|
||||
main_indicator: hmean
|
||||
|
||||
Train:
|
||||
dataset:
|
||||
name: SimpleDataSet
|
||||
data_dir: ./train_data/FUNSD/training_data/images/
|
||||
label_file_list:
|
||||
- ./train_data/FUNSD/train.json
|
||||
transforms:
|
||||
- DecodeImage: # load image
|
||||
img_mode: RGB
|
||||
channel_first: False
|
||||
- VQATokenLabelEncode: # Class handling label
|
||||
contains_re: False
|
||||
algorithm: *algorithm
|
||||
class_path: *class_path
|
||||
- VQATokenPad:
|
||||
max_seq_len: &max_seq_len 512
|
||||
return_attention_mask: True
|
||||
- VQASerTokenChunk:
|
||||
max_seq_len: *max_seq_len
|
||||
- Resize:
|
||||
size: [224,224]
|
||||
- NormalizeImage:
|
||||
scale: 1
|
||||
mean: [ 123.675, 116.28, 103.53 ]
|
||||
std: [ 58.395, 57.12, 57.375 ]
|
||||
order: 'hwc'
|
||||
- ToCHWImage:
|
||||
- KeepKeys:
|
||||
# dataloader will return list in this order
|
||||
keep_keys: [ 'input_ids', 'bbox', 'attention_mask', 'token_type_ids', 'image', 'labels']
|
||||
loader:
|
||||
shuffle: True
|
||||
drop_last: False
|
||||
batch_size_per_card: 8
|
||||
num_workers: 4
|
||||
|
||||
Eval:
|
||||
dataset:
|
||||
name: SimpleDataSet
|
||||
data_dir: ./train_data/FUNSD/testing_data/images/
|
||||
label_file_list:
|
||||
- ./train_data/FUNSD/test.json
|
||||
transforms:
|
||||
- DecodeImage: # load image
|
||||
img_mode: RGB
|
||||
channel_first: False
|
||||
- VQATokenLabelEncode: # Class handling label
|
||||
contains_re: False
|
||||
algorithm: *algorithm
|
||||
class_path: *class_path
|
||||
- VQATokenPad:
|
||||
max_seq_len: *max_seq_len
|
||||
return_attention_mask: True
|
||||
- VQASerTokenChunk:
|
||||
max_seq_len: *max_seq_len
|
||||
- Resize:
|
||||
size: [224,224]
|
||||
- NormalizeImage:
|
||||
scale: 1
|
||||
mean: [ 123.675, 116.28, 103.53 ]
|
||||
std: [ 58.395, 57.12, 57.375 ]
|
||||
order: 'hwc'
|
||||
- ToCHWImage:
|
||||
- KeepKeys:
|
||||
# dataloader will return list in this order
|
||||
keep_keys: [ 'input_ids', 'bbox', 'attention_mask', 'token_type_ids', 'image', 'labels']
|
||||
loader:
|
||||
shuffle: False
|
||||
drop_last: False
|
||||
batch_size_per_card: 8
|
||||
num_workers: 4
|
||||
@@ -1,123 +0,0 @@
|
||||
Global:
|
||||
use_gpu: True
|
||||
epoch_num: &epoch_num 200
|
||||
log_smooth_window: 10
|
||||
print_batch_step: 10
|
||||
save_model_dir: ./output/ser_layoutlmv2_sroie
|
||||
save_epoch_step: 2000
|
||||
# evaluation is run every 10 iterations after the 0th iteration
|
||||
eval_batch_step: [ 0, 200 ]
|
||||
cal_metric_during_train: False
|
||||
save_inference_dir:
|
||||
use_visualdl: False
|
||||
seed: 2022
|
||||
infer_img: train_data/SROIE/test/X00016469670.jpg
|
||||
save_res_path: ./output/ser_layoutlmv2_sroie/res/
|
||||
|
||||
Architecture:
|
||||
model_type: vqa
|
||||
algorithm: &algorithm "LayoutLMv2"
|
||||
Transform:
|
||||
Backbone:
|
||||
name: LayoutLMv2ForSer
|
||||
pretrained: True
|
||||
checkpoints:
|
||||
num_classes: &num_classes 9
|
||||
|
||||
Loss:
|
||||
name: VQASerTokenLayoutLMLoss
|
||||
num_classes: *num_classes
|
||||
|
||||
Optimizer:
|
||||
name: AdamW
|
||||
beta1: 0.9
|
||||
beta2: 0.999
|
||||
lr:
|
||||
name: Linear
|
||||
learning_rate: 0.00005
|
||||
epochs: *epoch_num
|
||||
warmup_epoch: 2
|
||||
regularizer:
|
||||
|
||||
name: L2
|
||||
factor: 0.00000
|
||||
|
||||
PostProcess:
|
||||
name: VQASerTokenLayoutLMPostProcess
|
||||
class_path: &class_path ./train_data/SROIE/class_list.txt
|
||||
|
||||
Metric:
|
||||
name: VQASerTokenMetric
|
||||
main_indicator: hmean
|
||||
|
||||
Train:
|
||||
dataset:
|
||||
name: SimpleDataSet
|
||||
data_dir: ./train_data/SROIE/train
|
||||
label_file_list:
|
||||
- ./train_data/SROIE/train.txt
|
||||
transforms:
|
||||
- DecodeImage: # load image
|
||||
img_mode: RGB
|
||||
channel_first: False
|
||||
- VQATokenLabelEncode: # Class handling label
|
||||
contains_re: False
|
||||
algorithm: *algorithm
|
||||
class_path: *class_path
|
||||
- VQATokenPad:
|
||||
max_seq_len: &max_seq_len 512
|
||||
return_attention_mask: True
|
||||
- VQASerTokenChunk:
|
||||
max_seq_len: *max_seq_len
|
||||
- Resize:
|
||||
size: [224,224]
|
||||
- NormalizeImage:
|
||||
scale: 1
|
||||
mean: [ 123.675, 116.28, 103.53 ]
|
||||
std: [ 58.395, 57.12, 57.375 ]
|
||||
order: 'hwc'
|
||||
- ToCHWImage:
|
||||
- KeepKeys:
|
||||
# dataloader will return list in this order
|
||||
keep_keys: [ 'input_ids', 'bbox', 'attention_mask', 'token_type_ids', 'image', 'labels']
|
||||
loader:
|
||||
shuffle: True
|
||||
drop_last: False
|
||||
batch_size_per_card: 8
|
||||
num_workers: 4
|
||||
|
||||
Eval:
|
||||
dataset:
|
||||
name: SimpleDataSet
|
||||
data_dir: ./train_data/SROIE/test
|
||||
label_file_list:
|
||||
- ./train_data/SROIE/test.txt
|
||||
transforms:
|
||||
- DecodeImage: # load image
|
||||
img_mode: RGB
|
||||
channel_first: False
|
||||
- VQATokenLabelEncode: # Class handling label
|
||||
contains_re: False
|
||||
algorithm: *algorithm
|
||||
class_path: *class_path
|
||||
- VQATokenPad:
|
||||
max_seq_len: *max_seq_len
|
||||
return_attention_mask: True
|
||||
- VQASerTokenChunk:
|
||||
max_seq_len: *max_seq_len
|
||||
- Resize:
|
||||
size: [224,224]
|
||||
- NormalizeImage:
|
||||
scale: 1
|
||||
mean: [ 123.675, 116.28, 103.53 ]
|
||||
std: [ 58.395, 57.12, 57.375 ]
|
||||
order: 'hwc'
|
||||
- ToCHWImage:
|
||||
- KeepKeys:
|
||||
# dataloader will return list in this order
|
||||
keep_keys: [ 'input_ids', 'bbox', 'attention_mask', 'token_type_ids', 'image', 'labels']
|
||||
loader:
|
||||
shuffle: False
|
||||
drop_last: False
|
||||
batch_size_per_card: 8
|
||||
num_workers: 4
|
||||
@@ -1,123 +0,0 @@
|
||||
Global:
|
||||
use_gpu: True
|
||||
epoch_num: &epoch_num 200
|
||||
log_smooth_window: 10
|
||||
print_batch_step: 10
|
||||
save_model_dir: ./output/ser_layoutxlm_funsd
|
||||
save_epoch_step: 2000
|
||||
# evaluation is run every 10 iterations after the 0th iteration
|
||||
eval_batch_step: [ 0, 57 ]
|
||||
cal_metric_during_train: False
|
||||
save_inference_dir:
|
||||
use_visualdl: False
|
||||
seed: 2022
|
||||
infer_img: train_data/FUNSD/testing_data/images/83624198.png
|
||||
save_res_path: output/ser_layoutxlm_funsd/res/
|
||||
|
||||
Architecture:
|
||||
model_type: vqa
|
||||
algorithm: &algorithm "LayoutXLM"
|
||||
Transform:
|
||||
Backbone:
|
||||
name: LayoutXLMForSer
|
||||
pretrained: True
|
||||
checkpoints:
|
||||
num_classes: &num_classes 7
|
||||
|
||||
Loss:
|
||||
name: VQASerTokenLayoutLMLoss
|
||||
num_classes: *num_classes
|
||||
|
||||
Optimizer:
|
||||
name: AdamW
|
||||
beta1: 0.9
|
||||
beta2: 0.999
|
||||
lr:
|
||||
name: Linear
|
||||
learning_rate: 0.00005
|
||||
epochs: *epoch_num
|
||||
warmup_epoch: 2
|
||||
regularizer:
|
||||
name: L2
|
||||
factor: 0.00000
|
||||
|
||||
PostProcess:
|
||||
name: VQASerTokenLayoutLMPostProcess
|
||||
class_path: &class_path ./train_data/FUNSD/class_list.txt
|
||||
|
||||
Metric:
|
||||
name: VQASerTokenMetric
|
||||
main_indicator: hmean
|
||||
|
||||
Train:
|
||||
dataset:
|
||||
name: SimpleDataSet
|
||||
data_dir: ./train_data/FUNSD/training_data/images/
|
||||
label_file_list:
|
||||
- ./train_data/FUNSD/train.json
|
||||
ratio_list: [ 1.0 ]
|
||||
transforms:
|
||||
- DecodeImage: # load image
|
||||
img_mode: RGB
|
||||
channel_first: False
|
||||
- VQATokenLabelEncode: # Class handling label
|
||||
contains_re: False
|
||||
algorithm: *algorithm
|
||||
class_path: *class_path
|
||||
- VQATokenPad:
|
||||
max_seq_len: &max_seq_len 512
|
||||
return_attention_mask: True
|
||||
- VQASerTokenChunk:
|
||||
max_seq_len: *max_seq_len
|
||||
- Resize:
|
||||
size: [224,224]
|
||||
- NormalizeImage:
|
||||
scale: 1
|
||||
mean: [ 123.675, 116.28, 103.53 ]
|
||||
std: [ 58.395, 57.12, 57.375 ]
|
||||
order: 'hwc'
|
||||
- ToCHWImage:
|
||||
- KeepKeys:
|
||||
# dataloader will return list in this order
|
||||
keep_keys: [ 'input_ids', 'bbox', 'attention_mask', 'token_type_ids', 'image', 'labels']
|
||||
loader:
|
||||
shuffle: True
|
||||
drop_last: False
|
||||
batch_size_per_card: 8
|
||||
num_workers: 4
|
||||
|
||||
Eval:
|
||||
dataset:
|
||||
name: SimpleDataSet
|
||||
data_dir: train_data/FUNSD/testing_data/images/
|
||||
label_file_list:
|
||||
- ./train_data/FUNSD/test.json
|
||||
transforms:
|
||||
- DecodeImage: # load image
|
||||
img_mode: RGB
|
||||
channel_first: False
|
||||
- VQATokenLabelEncode: # Class handling label
|
||||
contains_re: False
|
||||
algorithm: *algorithm
|
||||
class_path: *class_path
|
||||
- VQATokenPad:
|
||||
max_seq_len: *max_seq_len
|
||||
return_attention_mask: True
|
||||
- VQASerTokenChunk:
|
||||
max_seq_len: *max_seq_len
|
||||
- Resize:
|
||||
size: [224,224]
|
||||
- NormalizeImage:
|
||||
scale: 1
|
||||
mean: [ 123.675, 116.28, 103.53 ]
|
||||
std: [ 58.395, 57.12, 57.375 ]
|
||||
order: 'hwc'
|
||||
- ToCHWImage:
|
||||
- KeepKeys:
|
||||
# dataloader will return list in this order
|
||||
keep_keys: [ 'input_ids', 'bbox', 'attention_mask', 'token_type_ids', 'image', 'labels']
|
||||
loader:
|
||||
shuffle: False
|
||||
drop_last: False
|
||||
batch_size_per_card: 8
|
||||
num_workers: 4
|
||||
@@ -1,123 +0,0 @@
|
||||
Global:
|
||||
use_gpu: True
|
||||
epoch_num: &epoch_num 200
|
||||
log_smooth_window: 10
|
||||
print_batch_step: 10
|
||||
save_model_dir: ./output/ser_layoutxlm_sroie
|
||||
save_epoch_step: 2000
|
||||
# evaluation is run every 10 iterations after the 0th iteration
|
||||
eval_batch_step: [ 0, 200 ]
|
||||
cal_metric_during_train: False
|
||||
save_inference_dir:
|
||||
use_visualdl: False
|
||||
seed: 2022
|
||||
infer_img: train_data/SROIE/test/X00016469670.jpg
|
||||
save_res_path: res_img_aug_with_gt
|
||||
|
||||
Architecture:
|
||||
model_type: vqa
|
||||
algorithm: &algorithm "LayoutXLM"
|
||||
Transform:
|
||||
Backbone:
|
||||
name: LayoutXLMForSer
|
||||
pretrained: True
|
||||
checkpoints:
|
||||
num_classes: &num_classes 9
|
||||
|
||||
Loss:
|
||||
name: VQASerTokenLayoutLMLoss
|
||||
num_classes: *num_classes
|
||||
|
||||
Optimizer:
|
||||
name: AdamW
|
||||
beta1: 0.9
|
||||
beta2: 0.999
|
||||
lr:
|
||||
name: Linear
|
||||
learning_rate: 0.00005
|
||||
epochs: *epoch_num
|
||||
warmup_epoch: 2
|
||||
regularizer:
|
||||
name: L2
|
||||
factor: 0.00000
|
||||
|
||||
PostProcess:
|
||||
name: VQASerTokenLayoutLMPostProcess
|
||||
class_path: &class_path ./train_data/SROIE/class_list.txt
|
||||
|
||||
Metric:
|
||||
name: VQASerTokenMetric
|
||||
main_indicator: hmean
|
||||
|
||||
Train:
|
||||
dataset:
|
||||
name: SimpleDataSet
|
||||
data_dir: ./train_data/SROIE/train
|
||||
label_file_list:
|
||||
- ./train_data/SROIE/train.txt
|
||||
ratio_list: [ 1.0 ]
|
||||
transforms:
|
||||
- DecodeImage: # load image
|
||||
img_mode: RGB
|
||||
channel_first: False
|
||||
- VQATokenLabelEncode: # Class handling label
|
||||
contains_re: False
|
||||
algorithm: *algorithm
|
||||
class_path: *class_path
|
||||
- VQATokenPad:
|
||||
max_seq_len: &max_seq_len 512
|
||||
return_attention_mask: True
|
||||
- VQASerTokenChunk:
|
||||
max_seq_len: *max_seq_len
|
||||
- Resize:
|
||||
size: [224,224]
|
||||
- NormalizeImage:
|
||||
scale: 1
|
||||
mean: [ 123.675, 116.28, 103.53 ]
|
||||
std: [ 58.395, 57.12, 57.375 ]
|
||||
order: 'hwc'
|
||||
- ToCHWImage:
|
||||
- KeepKeys:
|
||||
# dataloader will return list in this order
|
||||
keep_keys: [ 'input_ids', 'bbox', 'attention_mask', 'token_type_ids', 'image', 'labels']
|
||||
loader:
|
||||
shuffle: True
|
||||
drop_last: False
|
||||
batch_size_per_card: 8
|
||||
num_workers: 4
|
||||
|
||||
Eval:
|
||||
dataset:
|
||||
name: SimpleDataSet
|
||||
data_dir: train_data/SROIE/test
|
||||
label_file_list:
|
||||
- ./train_data/SROIE/test.txt
|
||||
transforms:
|
||||
- DecodeImage: # load image
|
||||
img_mode: RGB
|
||||
channel_first: False
|
||||
- VQATokenLabelEncode: # Class handling label
|
||||
contains_re: False
|
||||
algorithm: *algorithm
|
||||
class_path: *class_path
|
||||
- VQATokenPad:
|
||||
max_seq_len: *max_seq_len
|
||||
return_attention_mask: True
|
||||
- VQASerTokenChunk:
|
||||
max_seq_len: *max_seq_len
|
||||
- Resize:
|
||||
size: [224,224]
|
||||
- NormalizeImage:
|
||||
scale: 1
|
||||
mean: [ 123.675, 116.28, 103.53 ]
|
||||
std: [ 58.395, 57.12, 57.375 ]
|
||||
order: 'hwc'
|
||||
- ToCHWImage:
|
||||
- KeepKeys:
|
||||
# dataloader will return list in this order
|
||||
keep_keys: [ 'input_ids', 'bbox', 'attention_mask', 'token_type_ids', 'image', 'labels']
|
||||
loader:
|
||||
shuffle: False
|
||||
drop_last: False
|
||||
batch_size_per_card: 8
|
||||
num_workers: 4
|
||||
@@ -1,123 +0,0 @@
|
||||
Global:
|
||||
use_gpu: True
|
||||
epoch_num: &epoch_num 100
|
||||
log_smooth_window: 10
|
||||
print_batch_step: 10
|
||||
save_model_dir: ./output/ser_layoutxlm_wildreceipt
|
||||
save_epoch_step: 2000
|
||||
# evaluation is run every 10 iterations after the 0th iteration
|
||||
eval_batch_step: [ 0, 200 ]
|
||||
cal_metric_during_train: False
|
||||
save_inference_dir:
|
||||
use_visualdl: False
|
||||
seed: 2022
|
||||
infer_img: train_data//wildreceipt/image_files/Image_12/10/845be0dd6f5b04866a2042abd28d558032ef2576.jpeg
|
||||
save_res_path: ./output/ser_layoutxlm_wildreceipt/res
|
||||
|
||||
Architecture:
|
||||
model_type: vqa
|
||||
algorithm: &algorithm "LayoutXLM"
|
||||
Transform:
|
||||
Backbone:
|
||||
name: LayoutXLMForSer
|
||||
pretrained: True
|
||||
checkpoints:
|
||||
num_classes: &num_classes 51
|
||||
|
||||
Loss:
|
||||
name: VQASerTokenLayoutLMLoss
|
||||
num_classes: *num_classes
|
||||
|
||||
Optimizer:
|
||||
name: AdamW
|
||||
beta1: 0.9
|
||||
beta2: 0.999
|
||||
lr:
|
||||
name: Linear
|
||||
learning_rate: 0.00005
|
||||
epochs: *epoch_num
|
||||
warmup_epoch: 2
|
||||
regularizer:
|
||||
name: L2
|
||||
factor: 0.00000
|
||||
|
||||
PostProcess:
|
||||
name: VQASerTokenLayoutLMPostProcess
|
||||
class_path: &class_path ./train_data/wildreceipt/class_list.txt
|
||||
|
||||
Metric:
|
||||
name: VQASerTokenMetric
|
||||
main_indicator: hmean
|
||||
|
||||
Train:
|
||||
dataset:
|
||||
name: SimpleDataSet
|
||||
data_dir: ./train_data/wildreceipt/
|
||||
label_file_list:
|
||||
- ./train_data/wildreceipt/wildreceipt_train.txt
|
||||
ratio_list: [ 1.0 ]
|
||||
transforms:
|
||||
- DecodeImage: # load image
|
||||
img_mode: RGB
|
||||
channel_first: False
|
||||
- VQATokenLabelEncode: # Class handling label
|
||||
contains_re: False
|
||||
algorithm: *algorithm
|
||||
class_path: *class_path
|
||||
- VQATokenPad:
|
||||
max_seq_len: &max_seq_len 512
|
||||
return_attention_mask: True
|
||||
- VQASerTokenChunk:
|
||||
max_seq_len: *max_seq_len
|
||||
- Resize:
|
||||
size: [224,224]
|
||||
- NormalizeImage:
|
||||
scale: 1
|
||||
mean: [ 123.675, 116.28, 103.53 ]
|
||||
std: [ 58.395, 57.12, 57.375 ]
|
||||
order: 'hwc'
|
||||
- ToCHWImage:
|
||||
- KeepKeys:
|
||||
# dataloader will return list in this order
|
||||
keep_keys: [ 'input_ids', 'bbox', 'attention_mask', 'token_type_ids', 'image', 'labels']
|
||||
loader:
|
||||
shuffle: True
|
||||
drop_last: False
|
||||
batch_size_per_card: 8
|
||||
num_workers: 4
|
||||
|
||||
Eval:
|
||||
dataset:
|
||||
name: SimpleDataSet
|
||||
data_dir: train_data/wildreceipt
|
||||
label_file_list:
|
||||
- ./train_data/wildreceipt/wildreceipt_test.txt
|
||||
transforms:
|
||||
- DecodeImage: # load image
|
||||
img_mode: RGB
|
||||
channel_first: False
|
||||
- VQATokenLabelEncode: # Class handling label
|
||||
contains_re: False
|
||||
algorithm: *algorithm
|
||||
class_path: *class_path
|
||||
- VQATokenPad:
|
||||
max_seq_len: *max_seq_len
|
||||
return_attention_mask: True
|
||||
- VQASerTokenChunk:
|
||||
max_seq_len: *max_seq_len
|
||||
- Resize:
|
||||
size: [224,224]
|
||||
- NormalizeImage:
|
||||
scale: 1
|
||||
mean: [ 123.675, 116.28, 103.53 ]
|
||||
std: [ 58.395, 57.12, 57.375 ]
|
||||
order: 'hwc'
|
||||
- ToCHWImage:
|
||||
- KeepKeys:
|
||||
# dataloader will return list in this order
|
||||
keep_keys: [ 'input_ids', 'bbox', 'attention_mask', 'token_type_ids', 'image', 'labels']
|
||||
loader:
|
||||
shuffle: False
|
||||
drop_last: False
|
||||
batch_size_per_card: 8
|
||||
num_workers: 4
|
||||
@@ -53,10 +53,11 @@ PP-OCRv3检测模型是对PP-OCRv2中的[CML](https://arxiv.org/pdf/2109.03144.p
|
||||
|
||||
|序号|策略|模型大小|hmean|速度(cpu + mkldnn)|
|
||||
|-|-|-|-|-|
|
||||
|baseline teacher|DB-R50|99M|83.5%|260ms|
|
||||
|baseline teacher|PP-OCR server|49M|83.2%|171ms|
|
||||
|teacher1|DB-R50-LK-PAN|124M|85.0%|396ms|
|
||||
|teacher2|DB-R50-LK-PAN-DML|124M|86.0%|396ms|
|
||||
|baseline student|PP-OCRv2|3M|83.2%|117ms|
|
||||
|student0|DB-MV3-RSE-FPN|3.6M|84.5%|124ms|
|
||||
|student1|DB-MV3-CML(teacher2)|3M|84.3%|117ms|
|
||||
|student2|DB-MV3-RSE-FPN-CML(teacher2)|3.6M|85.4%|124ms|
|
||||
|
||||
@@ -184,7 +185,7 @@ UDML(Unified-Deep Mutual Learning)联合互学习是PP-OCRv2中就采用的
|
||||
|
||||
**(6)UIM:无标注数据挖掘方案**
|
||||
|
||||
UIM(Unlabeled Images Mining)是一种非常简单的无标注数据挖掘方案。核心思想是利用高精度的文本识别大模型对无标注数据进行预测,获取伪标签,并且选择预测置信度高的样本作为训练数据,用于训练小模型。使用该策略,识别模型的准确率进一步提升到79.4%(+1%)。
|
||||
UIM(Unlabeled Images Mining)是一种非常简单的无标注数据挖掘方案。核心思想是利用高精度的文本识别大模型对无标注数据进行预测,获取伪标签,并且选择预测置信度高的样本作为训练数据,用于训练小模型。使用该策略,识别模型的准确率进一步提升到79.4%(+1%)。实际操作中,我们使用全量数据集训练高精度SVTR-Tiny模型(acc=82.5%)进行数据挖掘,点击获取[模型下载地址和使用教程](../../applications/高精度中文识别模型.md)。
|
||||
|
||||
<div align="center">
|
||||
<img src="../ppocr_v3/UIM.png" width="500">
|
||||
|
||||
@@ -65,7 +65,7 @@ python3 -m paddle.distributed.launch --gpus '0,1,2,3' tools/train.py -c configs/
|
||||
|
||||
```
|
||||
|
||||
上述指令中,通过-c 选择训练使用configs/det/det_db_mv3.yml配置文件。
|
||||
上述指令中,通过-c 选择训练使用configs/det/det_mv3_db.yml配置文件。
|
||||
有关配置文件的详细解释,请参考[链接](./config.md)。
|
||||
|
||||
您也可以通过-o参数在不需要修改yml文件的情况下,改变训练的参数,比如,调整训练的学习率为0.0001
|
||||
|
||||
@@ -55,10 +55,11 @@ The ablation experiments are as follows:
|
||||
|
||||
|ID|Strategy|Model Size|Hmean|The Inference Time(cpu + mkldnn)|
|
||||
|-|-|-|-|-|
|
||||
|baseline teacher|DB-R50|99M|83.5%|260ms|
|
||||
|baseline teacher|PP-OCR server|49M|83.2%|171ms|
|
||||
|teacher1|DB-R50-LK-PAN|124M|85.0%|396ms|
|
||||
|teacher2|DB-R50-LK-PAN-DML|124M|86.0%|396ms|
|
||||
|baseline student|PP-OCRv2|3M|83.2%|117ms|
|
||||
|student0|DB-MV3-RSE-FPN|3.6M|84.5%|124ms|
|
||||
|student1|DB-MV3-CML(teacher2)|3M|84.3%|117ms|
|
||||
|student2|DB-MV3-RSE-FPN-CML(teacher2)|3.6M|85.4%|124ms|
|
||||
|
||||
@@ -199,7 +200,7 @@ UDML (Unified-Deep Mutual Learning) is a strategy proposed in PP-OCRv2 which is
|
||||
|
||||
**(6)UIM:Unlabeled Images Mining**
|
||||
|
||||
UIM (Unlabeled Images Mining) is a very simple unlabeled data mining strategy. The main idea is to use a high-precision text recognition model to predict unlabeled images to obtain pseudo-labels, and select samples with high prediction confidence as training data for training lightweight models. Using this strategy, the accuracy of the recognition model is further improved to 79.4% (+1%).
|
||||
UIM (Unlabeled Images Mining) is a very simple unlabeled data mining strategy. The main idea is to use a high-precision text recognition model to predict unlabeled images to obtain pseudo-labels, and select samples with high prediction confidence as training data for training lightweight models. Using this strategy, the accuracy of the recognition model is further improved to 79.4% (+1%). In practice, we use the full data set to train the high-precision SVTR_Tiny model (acc=82.5%) for data mining. [SVTR_Tiny model download and tutorial](../../applications/高精度中文识别模型.md).
|
||||
|
||||
<div align="center">
|
||||
<img src="../ppocr_v3/UIM.png" width="500">
|
||||
|
||||
@@ -51,7 +51,7 @@ python3 tools/train.py -c configs/det/det_mv3_db.yml \
|
||||
-o Global.pretrained_model=./pretrain_models/MobileNetV3_large_x0_5_pretrained
|
||||
```
|
||||
|
||||
In the above instruction, use `-c` to select the training to use the `configs/det/det_db_mv3.yml` configuration file.
|
||||
In the above instruction, use `-c` to select the training to use the `configs/det/det_mv3_db.yml` configuration file.
|
||||
For a detailed explanation of the configuration file, please refer to [config](./config_en.md).
|
||||
|
||||
You can also use `-o` to change the training parameters without modifying the yml file. For example, adjust the training learning rate to 0.0001
|
||||
|
||||
@@ -24,6 +24,7 @@ from shapely.geometry import LineString, Point, Polygon
|
||||
import json
|
||||
import copy
|
||||
from ppocr.utils.logging import get_logger
|
||||
from ppocr.data.imaug.vqa.augment import order_by_tbyx
|
||||
|
||||
|
||||
class ClsLabelEncode(object):
|
||||
@@ -870,6 +871,7 @@ class VQATokenLabelEncode(object):
|
||||
add_special_ids=False,
|
||||
algorithm='LayoutXLM',
|
||||
use_textline_bbox_info=True,
|
||||
order_method=None,
|
||||
infer_mode=False,
|
||||
ocr_engine=None,
|
||||
**kwargs):
|
||||
@@ -899,6 +901,8 @@ class VQATokenLabelEncode(object):
|
||||
self.infer_mode = infer_mode
|
||||
self.ocr_engine = ocr_engine
|
||||
self.use_textline_bbox_info = use_textline_bbox_info
|
||||
self.order_method = order_method
|
||||
assert self.order_method in [None, "tb-yx"]
|
||||
|
||||
def split_bbox(self, bbox, text, tokenizer):
|
||||
words = text.split()
|
||||
@@ -938,6 +942,14 @@ class VQATokenLabelEncode(object):
|
||||
# load bbox and label info
|
||||
ocr_info = self._load_ocr_info(data)
|
||||
|
||||
for idx in range(len(ocr_info)):
|
||||
if "bbox" not in ocr_info[idx]:
|
||||
ocr_info[idx]["bbox"] = self.trans_poly_to_bbox(ocr_info[idx][
|
||||
"points"])
|
||||
|
||||
if self.order_method == "tb-yx":
|
||||
ocr_info = order_by_tbyx(ocr_info)
|
||||
|
||||
# for re
|
||||
train_re = self.contains_re and not self.infer_mode
|
||||
if train_re:
|
||||
@@ -977,7 +989,10 @@ class VQATokenLabelEncode(object):
|
||||
info["bbox"] = self.trans_poly_to_bbox(info["points"])
|
||||
|
||||
encode_res = self.tokenizer.encode(
|
||||
text, pad_to_max_seq_len=False, return_attention_mask=True)
|
||||
text,
|
||||
pad_to_max_seq_len=False,
|
||||
return_attention_mask=True,
|
||||
return_token_type_ids=True)
|
||||
|
||||
if not self.add_special_ids:
|
||||
# TODO: use tok.all_special_ids to remove
|
||||
@@ -1049,10 +1064,10 @@ class VQATokenLabelEncode(object):
|
||||
return data
|
||||
|
||||
def trans_poly_to_bbox(self, poly):
|
||||
x1 = np.min([p[0] for p in poly])
|
||||
x2 = np.max([p[0] for p in poly])
|
||||
y1 = np.min([p[1] for p in poly])
|
||||
y2 = np.max([p[1] for p in poly])
|
||||
x1 = int(np.min([p[0] for p in poly]))
|
||||
x2 = int(np.max([p[0] for p in poly]))
|
||||
y1 = int(np.min([p[1] for p in poly]))
|
||||
y2 = int(np.max([p[1] for p in poly]))
|
||||
return [x1, y1, x2, y2]
|
||||
|
||||
def _load_ocr_info(self, data):
|
||||
@@ -1217,6 +1232,7 @@ class ABINetLabelEncode(BaseRecLabelEncode):
|
||||
dict_character = ['</s>'] + dict_character
|
||||
return dict_character
|
||||
|
||||
|
||||
class SPINLabelEncode(AttnLabelEncode):
|
||||
""" Convert between text-label and text-index """
|
||||
|
||||
@@ -1229,6 +1245,7 @@ class SPINLabelEncode(AttnLabelEncode):
|
||||
super(SPINLabelEncode, self).__init__(
|
||||
max_text_length, character_dict_path, use_space_char)
|
||||
self.lower = lower
|
||||
|
||||
def add_special_char(self, dict_character):
|
||||
self.beg_str = "sos"
|
||||
self.end_str = "eos"
|
||||
@@ -1248,4 +1265,4 @@ class SPINLabelEncode(AttnLabelEncode):
|
||||
|
||||
padded_text[:len(target)] = target
|
||||
data['label'] = np.array(padded_text)
|
||||
return data
|
||||
return data
|
||||
|
||||
@@ -13,12 +13,10 @@
|
||||
# limitations under the License.
|
||||
|
||||
from .token import VQATokenPad, VQASerTokenChunk, VQAReTokenChunk, VQAReTokenRelation
|
||||
from .augment import DistortBBox
|
||||
|
||||
__all__ = [
|
||||
'VQATokenPad',
|
||||
'VQASerTokenChunk',
|
||||
'VQAReTokenChunk',
|
||||
'VQAReTokenRelation',
|
||||
'DistortBBox',
|
||||
]
|
||||
|
||||
@@ -16,22 +16,18 @@ import os
|
||||
import sys
|
||||
import numpy as np
|
||||
import random
|
||||
from copy import deepcopy
|
||||
|
||||
|
||||
class DistortBBox:
|
||||
def __init__(self, prob=0.5, max_scale=1, **kwargs):
|
||||
"""Random distort bbox
|
||||
"""
|
||||
self.prob = prob
|
||||
self.max_scale = max_scale
|
||||
|
||||
def __call__(self, data):
|
||||
if random.random() > self.prob:
|
||||
return data
|
||||
bbox = np.array(data['bbox'])
|
||||
rnd_scale = (np.random.rand(*bbox.shape) - 0.5) * 2 * self.max_scale
|
||||
bbox = np.round(bbox + rnd_scale).astype(bbox.dtype)
|
||||
data['bbox'] = np.clip(data['bbox'], 0, 1000)
|
||||
data['bbox'] = bbox.tolist()
|
||||
sys.stdout.flush()
|
||||
return data
|
||||
def order_by_tbyx(ocr_info):
|
||||
res = sorted(ocr_info, key=lambda r: (r["bbox"][1], r["bbox"][0]))
|
||||
for i in range(len(res) - 1):
|
||||
for j in range(i, 0, -1):
|
||||
if abs(res[j + 1]["bbox"][1] - res[j]["bbox"][1]) < 20 and \
|
||||
(res[j + 1]["bbox"][0] < res[j]["bbox"][0]):
|
||||
tmp = deepcopy(res[j])
|
||||
res[j] = deepcopy(res[j + 1])
|
||||
res[j + 1] = deepcopy(tmp)
|
||||
else:
|
||||
break
|
||||
return res
|
||||
|
||||
@@ -63,18 +63,21 @@ class KLJSLoss(object):
|
||||
def __call__(self, p1, p2, reduction="mean"):
|
||||
|
||||
if self.mode.lower() == 'kl':
|
||||
loss = paddle.multiply(p2, paddle.log((p2 + 1e-5) / (p1 + 1e-5) + 1e-5))
|
||||
loss = paddle.multiply(p2,
|
||||
paddle.log((p2 + 1e-5) / (p1 + 1e-5) + 1e-5))
|
||||
loss += paddle.multiply(
|
||||
p1, paddle.log((p1 + 1e-5) / (p2 + 1e-5) + 1e-5))
|
||||
p1, paddle.log((p1 + 1e-5) / (p2 + 1e-5) + 1e-5))
|
||||
loss *= 0.5
|
||||
elif self.mode.lower() == "js":
|
||||
loss = paddle.multiply(p2, paddle.log((2*p2 + 1e-5) / (p1 + p2 + 1e-5) + 1e-5))
|
||||
loss = paddle.multiply(
|
||||
p2, paddle.log((2 * p2 + 1e-5) / (p1 + p2 + 1e-5) + 1e-5))
|
||||
loss += paddle.multiply(
|
||||
p1, paddle.log((2*p1 + 1e-5) / (p1 + p2 + 1e-5) + 1e-5))
|
||||
p1, paddle.log((2 * p1 + 1e-5) / (p1 + p2 + 1e-5) + 1e-5))
|
||||
loss *= 0.5
|
||||
else:
|
||||
raise ValueError("The mode.lower() if KLJSLoss should be one of ['kl', 'js']")
|
||||
|
||||
raise ValueError(
|
||||
"The mode.lower() if KLJSLoss should be one of ['kl', 'js']")
|
||||
|
||||
if reduction == "mean":
|
||||
loss = paddle.mean(loss, axis=[1, 2])
|
||||
elif reduction == "none" or reduction is None:
|
||||
@@ -154,7 +157,9 @@ class LossFromOutput(nn.Layer):
|
||||
self.reduction = reduction
|
||||
|
||||
def forward(self, predicts, batch):
|
||||
loss = predicts[self.key]
|
||||
loss = predicts
|
||||
if self.key is not None and isinstance(predicts, dict):
|
||||
loss = loss[self.key]
|
||||
if self.reduction == 'mean':
|
||||
loss = paddle.mean(loss)
|
||||
elif self.reduction == 'sum':
|
||||
|
||||
@@ -24,6 +24,9 @@ from .distillation_loss import DistillationCTCLoss
|
||||
from .distillation_loss import DistillationSARLoss
|
||||
from .distillation_loss import DistillationDMLLoss
|
||||
from .distillation_loss import DistillationDistanceLoss, DistillationDBLoss, DistillationDilaDBLoss
|
||||
from .distillation_loss import DistillationVQASerTokenLayoutLMLoss, DistillationSERDMLLoss
|
||||
from .distillation_loss import DistillationLossFromOutput
|
||||
from .distillation_loss import DistillationVQADistanceLoss
|
||||
|
||||
|
||||
class CombinedLoss(nn.Layer):
|
||||
|
||||
@@ -21,8 +21,10 @@ from .rec_ctc_loss import CTCLoss
|
||||
from .rec_sar_loss import SARLoss
|
||||
from .basic_loss import DMLLoss
|
||||
from .basic_loss import DistanceLoss
|
||||
from .basic_loss import LossFromOutput
|
||||
from .det_db_loss import DBLoss
|
||||
from .det_basic_loss import BalanceLoss, MaskL1Loss, DiceLoss
|
||||
from .vqa_token_layoutlm_loss import VQASerTokenLayoutLMLoss
|
||||
|
||||
|
||||
def _sum_loss(loss_dict):
|
||||
@@ -322,3 +324,133 @@ class DistillationDistanceLoss(DistanceLoss):
|
||||
loss_dict["{}_{}_{}_{}".format(self.name, pair[0], pair[1],
|
||||
idx)] = loss
|
||||
return loss_dict
|
||||
|
||||
|
||||
class DistillationVQASerTokenLayoutLMLoss(VQASerTokenLayoutLMLoss):
|
||||
def __init__(self,
|
||||
num_classes,
|
||||
model_name_list=[],
|
||||
key=None,
|
||||
name="loss_ser"):
|
||||
super().__init__(num_classes=num_classes)
|
||||
self.model_name_list = model_name_list
|
||||
self.key = key
|
||||
self.name = name
|
||||
|
||||
def forward(self, predicts, batch):
|
||||
loss_dict = dict()
|
||||
for idx, model_name in enumerate(self.model_name_list):
|
||||
out = predicts[model_name]
|
||||
if self.key is not None:
|
||||
out = out[self.key]
|
||||
loss = super().forward(out, batch)
|
||||
loss_dict["{}_{}".format(self.name, model_name)] = loss["loss"]
|
||||
return loss_dict
|
||||
|
||||
|
||||
class DistillationLossFromOutput(LossFromOutput):
|
||||
def __init__(self,
|
||||
reduction="none",
|
||||
model_name_list=[],
|
||||
dist_key=None,
|
||||
key="loss",
|
||||
name="loss_re"):
|
||||
super().__init__(key=key, reduction=reduction)
|
||||
self.model_name_list = model_name_list
|
||||
self.name = name
|
||||
self.dist_key = dist_key
|
||||
|
||||
def forward(self, predicts, batch):
|
||||
loss_dict = dict()
|
||||
for idx, model_name in enumerate(self.model_name_list):
|
||||
out = predicts[model_name]
|
||||
if self.dist_key is not None:
|
||||
out = out[self.dist_key]
|
||||
loss = super().forward(out, batch)
|
||||
loss_dict["{}_{}".format(self.name, model_name)] = loss["loss"]
|
||||
return loss_dict
|
||||
|
||||
|
||||
class DistillationSERDMLLoss(DMLLoss):
|
||||
"""
|
||||
"""
|
||||
|
||||
def __init__(self,
|
||||
act="softmax",
|
||||
use_log=True,
|
||||
num_classes=7,
|
||||
model_name_pairs=[],
|
||||
key=None,
|
||||
name="loss_dml_ser"):
|
||||
super().__init__(act=act, use_log=use_log)
|
||||
assert isinstance(model_name_pairs, list)
|
||||
self.key = key
|
||||
self.name = name
|
||||
self.num_classes = num_classes
|
||||
self.model_name_pairs = model_name_pairs
|
||||
|
||||
def forward(self, predicts, batch):
|
||||
loss_dict = dict()
|
||||
for idx, pair in enumerate(self.model_name_pairs):
|
||||
out1 = predicts[pair[0]]
|
||||
out2 = predicts[pair[1]]
|
||||
if self.key is not None:
|
||||
out1 = out1[self.key]
|
||||
out2 = out2[self.key]
|
||||
out1 = out1.reshape([-1, out1.shape[-1]])
|
||||
out2 = out2.reshape([-1, out2.shape[-1]])
|
||||
|
||||
attention_mask = batch[2]
|
||||
if attention_mask is not None:
|
||||
active_output = attention_mask.reshape([-1, ]) == 1
|
||||
out1 = out1[active_output]
|
||||
out2 = out2[active_output]
|
||||
|
||||
loss_dict["{}_{}".format(self.name, idx)] = super().forward(out1,
|
||||
out2)
|
||||
|
||||
return loss_dict
|
||||
|
||||
|
||||
class DistillationVQADistanceLoss(DistanceLoss):
|
||||
def __init__(self,
|
||||
mode="l2",
|
||||
model_name_pairs=[],
|
||||
key=None,
|
||||
name="loss_distance",
|
||||
**kargs):
|
||||
super().__init__(mode=mode, **kargs)
|
||||
assert isinstance(model_name_pairs, list)
|
||||
self.key = key
|
||||
self.model_name_pairs = model_name_pairs
|
||||
self.name = name + "_l2"
|
||||
|
||||
def forward(self, predicts, batch):
|
||||
loss_dict = dict()
|
||||
for idx, pair in enumerate(self.model_name_pairs):
|
||||
out1 = predicts[pair[0]]
|
||||
out2 = predicts[pair[1]]
|
||||
attention_mask = batch[2]
|
||||
if self.key is not None:
|
||||
out1 = out1[self.key]
|
||||
out2 = out2[self.key]
|
||||
if attention_mask is not None:
|
||||
max_len = attention_mask.shape[-1]
|
||||
out1 = out1[:, :max_len]
|
||||
out2 = out2[:, :max_len]
|
||||
out1 = out1.reshape([-1, out1.shape[-1]])
|
||||
out2 = out2.reshape([-1, out2.shape[-1]])
|
||||
if attention_mask is not None:
|
||||
active_output = attention_mask.reshape([-1, ]) == 1
|
||||
out1 = out1[active_output]
|
||||
out2 = out2[active_output]
|
||||
|
||||
loss = super().forward(out1, out2)
|
||||
if isinstance(loss, dict):
|
||||
for key in loss:
|
||||
loss_dict["{}_{}nohu_{}".format(self.name, key,
|
||||
idx)] = loss[key]
|
||||
else:
|
||||
loss_dict["{}_{}_{}_{}".format(self.name, pair[0], pair[1],
|
||||
idx)] = loss
|
||||
return loss_dict
|
||||
|
||||
@@ -17,26 +17,30 @@ from __future__ import division
|
||||
from __future__ import print_function
|
||||
|
||||
from paddle import nn
|
||||
from ppocr.losses.basic_loss import DMLLoss
|
||||
|
||||
|
||||
class VQASerTokenLayoutLMLoss(nn.Layer):
|
||||
def __init__(self, num_classes):
|
||||
def __init__(self, num_classes, key=None):
|
||||
super().__init__()
|
||||
self.loss_class = nn.CrossEntropyLoss()
|
||||
self.num_classes = num_classes
|
||||
self.ignore_index = self.loss_class.ignore_index
|
||||
self.key = key
|
||||
|
||||
def forward(self, predicts, batch):
|
||||
if isinstance(predicts, dict) and self.key is not None:
|
||||
predicts = predicts[self.key]
|
||||
labels = batch[5]
|
||||
attention_mask = batch[2]
|
||||
if attention_mask is not None:
|
||||
active_loss = attention_mask.reshape([-1, ]) == 1
|
||||
active_outputs = predicts.reshape(
|
||||
active_output = predicts.reshape(
|
||||
[-1, self.num_classes])[active_loss]
|
||||
active_labels = labels.reshape([-1, ])[active_loss]
|
||||
loss = self.loss_class(active_outputs, active_labels)
|
||||
active_label = labels.reshape([-1, ])[active_loss]
|
||||
loss = self.loss_class(active_output, active_label)
|
||||
else:
|
||||
loss = self.loss_class(
|
||||
predicts.reshape([-1, self.num_classes]),
|
||||
labels.reshape([-1, ]))
|
||||
return {'loss': loss}
|
||||
return {'loss': loss}
|
||||
@@ -19,6 +19,8 @@ from .rec_metric import RecMetric
|
||||
from .det_metric import DetMetric
|
||||
from .e2e_metric import E2EMetric
|
||||
from .cls_metric import ClsMetric
|
||||
from .vqa_token_ser_metric import VQASerTokenMetric
|
||||
from .vqa_token_re_metric import VQAReTokenMetric
|
||||
|
||||
|
||||
class DistillationMetric(object):
|
||||
|
||||
@@ -73,28 +73,40 @@ class BaseModel(nn.Layer):
|
||||
self.return_all_feats = config.get("return_all_feats", False)
|
||||
|
||||
def forward(self, x, data=None):
|
||||
|
||||
y = dict()
|
||||
if self.use_transform:
|
||||
x = self.transform(x)
|
||||
x = self.backbone(x)
|
||||
y["backbone_out"] = x
|
||||
if self.use_neck:
|
||||
x = self.neck(x)
|
||||
y["neck_out"] = x
|
||||
if self.use_head:
|
||||
x = self.head(x, targets=data)
|
||||
# for multi head, save ctc neck out for udml
|
||||
if isinstance(x, dict) and 'ctc_neck' in x.keys():
|
||||
y["neck_out"] = x["ctc_neck"]
|
||||
y["head_out"] = x
|
||||
elif isinstance(x, dict):
|
||||
if isinstance(x, dict):
|
||||
y.update(x)
|
||||
else:
|
||||
y["head_out"] = x
|
||||
y["backbone_out"] = x
|
||||
final_name = "backbone_out"
|
||||
if self.use_neck:
|
||||
x = self.neck(x)
|
||||
if isinstance(x, dict):
|
||||
y.update(x)
|
||||
else:
|
||||
y["neck_out"] = x
|
||||
final_name = "neck_out"
|
||||
if self.use_head:
|
||||
x = self.head(x, targets=data)
|
||||
# for multi head, save ctc neck out for udml
|
||||
if isinstance(x, dict) and 'ctc_neck' in x.keys():
|
||||
y["neck_out"] = x["ctc_neck"]
|
||||
y["head_out"] = x
|
||||
elif isinstance(x, dict):
|
||||
y.update(x)
|
||||
else:
|
||||
y["head_out"] = x
|
||||
final_name = "head_out"
|
||||
if self.return_all_feats:
|
||||
if self.training:
|
||||
return y
|
||||
elif isinstance(x, dict):
|
||||
return x
|
||||
else:
|
||||
return {"head_out": y["head_out"]}
|
||||
return {final_name: x}
|
||||
else:
|
||||
return x
|
||||
|
||||
@@ -22,13 +22,22 @@ from paddle import nn
|
||||
from paddlenlp.transformers import LayoutXLMModel, LayoutXLMForTokenClassification, LayoutXLMForRelationExtraction
|
||||
from paddlenlp.transformers import LayoutLMModel, LayoutLMForTokenClassification
|
||||
from paddlenlp.transformers import LayoutLMv2Model, LayoutLMv2ForTokenClassification, LayoutLMv2ForRelationExtraction
|
||||
from paddlenlp.transformers import AutoModel
|
||||
|
||||
__all__ = ["LayoutXLMForSer", 'LayoutLMForSer']
|
||||
__all__ = ["LayoutXLMForSer", "LayoutLMForSer"]
|
||||
|
||||
pretrained_model_dict = {
|
||||
LayoutXLMModel: 'layoutxlm-base-uncased',
|
||||
LayoutLMModel: 'layoutlm-base-uncased',
|
||||
LayoutLMv2Model: 'layoutlmv2-base-uncased'
|
||||
LayoutXLMModel: {
|
||||
"base": "layoutxlm-base-uncased",
|
||||
"vi": "layoutxlm-wo-backbone-base-uncased",
|
||||
},
|
||||
LayoutLMModel: {
|
||||
"base": "layoutlm-base-uncased",
|
||||
},
|
||||
LayoutLMv2Model: {
|
||||
"base": "layoutlmv2-base-uncased",
|
||||
"vi": "layoutlmv2-wo-backbone-base-uncased",
|
||||
},
|
||||
}
|
||||
|
||||
|
||||
@@ -36,42 +45,47 @@ class NLPBaseModel(nn.Layer):
|
||||
def __init__(self,
|
||||
base_model_class,
|
||||
model_class,
|
||||
type='ser',
|
||||
mode="base",
|
||||
type="ser",
|
||||
pretrained=True,
|
||||
checkpoints=None,
|
||||
**kwargs):
|
||||
super(NLPBaseModel, self).__init__()
|
||||
if checkpoints is not None:
|
||||
if checkpoints is not None: # load the trained model
|
||||
self.model = model_class.from_pretrained(checkpoints)
|
||||
elif isinstance(pretrained, (str, )) and os.path.exists(pretrained):
|
||||
self.model = model_class.from_pretrained(pretrained)
|
||||
else:
|
||||
pretrained_model_name = pretrained_model_dict[base_model_class]
|
||||
else: # load the pretrained-model
|
||||
pretrained_model_name = pretrained_model_dict[base_model_class][
|
||||
mode]
|
||||
if pretrained is True:
|
||||
base_model = base_model_class.from_pretrained(
|
||||
pretrained_model_name)
|
||||
else:
|
||||
base_model = base_model_class(
|
||||
**base_model_class.pretrained_init_configuration[
|
||||
pretrained_model_name])
|
||||
if type == 'ser':
|
||||
base_model = base_model_class.from_pretrained(pretrained)
|
||||
if type == "ser":
|
||||
self.model = model_class(
|
||||
base_model, num_classes=kwargs['num_classes'], dropout=None)
|
||||
base_model, num_classes=kwargs["num_classes"], dropout=None)
|
||||
else:
|
||||
self.model = model_class(base_model, dropout=None)
|
||||
self.out_channels = 1
|
||||
self.use_visual_backbone = True
|
||||
|
||||
|
||||
class LayoutLMForSer(NLPBaseModel):
|
||||
def __init__(self, num_classes, pretrained=True, checkpoints=None,
|
||||
def __init__(self,
|
||||
num_classes,
|
||||
pretrained=True,
|
||||
checkpoints=None,
|
||||
mode="base",
|
||||
**kwargs):
|
||||
super(LayoutLMForSer, self).__init__(
|
||||
LayoutLMModel,
|
||||
LayoutLMForTokenClassification,
|
||||
'ser',
|
||||
mode,
|
||||
"ser",
|
||||
pretrained,
|
||||
checkpoints,
|
||||
num_classes=num_classes)
|
||||
num_classes=num_classes, )
|
||||
self.use_visual_backbone = False
|
||||
|
||||
def forward(self, x):
|
||||
x = self.model(
|
||||
@@ -85,62 +99,92 @@ class LayoutLMForSer(NLPBaseModel):
|
||||
|
||||
|
||||
class LayoutLMv2ForSer(NLPBaseModel):
|
||||
def __init__(self, num_classes, pretrained=True, checkpoints=None,
|
||||
def __init__(self,
|
||||
num_classes,
|
||||
pretrained=True,
|
||||
checkpoints=None,
|
||||
mode="base",
|
||||
**kwargs):
|
||||
super(LayoutLMv2ForSer, self).__init__(
|
||||
LayoutLMv2Model,
|
||||
LayoutLMv2ForTokenClassification,
|
||||
'ser',
|
||||
mode,
|
||||
"ser",
|
||||
pretrained,
|
||||
checkpoints,
|
||||
num_classes=num_classes)
|
||||
self.use_visual_backbone = True
|
||||
if hasattr(self.model.layoutlmv2, "use_visual_backbone"
|
||||
) and self.model.layoutlmv2.use_visual_backbone is False:
|
||||
self.use_visual_backbone = False
|
||||
|
||||
def forward(self, x):
|
||||
if self.use_visual_backbone is True:
|
||||
image = x[4]
|
||||
else:
|
||||
image = None
|
||||
x = self.model(
|
||||
input_ids=x[0],
|
||||
bbox=x[1],
|
||||
attention_mask=x[2],
|
||||
token_type_ids=x[3],
|
||||
image=x[4],
|
||||
image=image,
|
||||
position_ids=None,
|
||||
head_mask=None,
|
||||
labels=None)
|
||||
if not self.training:
|
||||
if self.training:
|
||||
res = {"backbone_out": x[0]}
|
||||
res.update(x[1])
|
||||
return res
|
||||
else:
|
||||
return x
|
||||
return x[0]
|
||||
|
||||
|
||||
class LayoutXLMForSer(NLPBaseModel):
|
||||
def __init__(self, num_classes, pretrained=True, checkpoints=None,
|
||||
def __init__(self,
|
||||
num_classes,
|
||||
pretrained=True,
|
||||
checkpoints=None,
|
||||
mode="base",
|
||||
**kwargs):
|
||||
super(LayoutXLMForSer, self).__init__(
|
||||
LayoutXLMModel,
|
||||
LayoutXLMForTokenClassification,
|
||||
'ser',
|
||||
mode,
|
||||
"ser",
|
||||
pretrained,
|
||||
checkpoints,
|
||||
num_classes=num_classes)
|
||||
self.use_visual_backbone = True
|
||||
|
||||
def forward(self, x):
|
||||
if self.use_visual_backbone is True:
|
||||
image = x[4]
|
||||
else:
|
||||
image = None
|
||||
x = self.model(
|
||||
input_ids=x[0],
|
||||
bbox=x[1],
|
||||
attention_mask=x[2],
|
||||
token_type_ids=x[3],
|
||||
image=x[4],
|
||||
image=image,
|
||||
position_ids=None,
|
||||
head_mask=None,
|
||||
labels=None)
|
||||
if not self.training:
|
||||
if self.training:
|
||||
res = {"backbone_out": x[0]}
|
||||
res.update(x[1])
|
||||
return res
|
||||
else:
|
||||
return x
|
||||
return x[0]
|
||||
|
||||
|
||||
class LayoutLMv2ForRe(NLPBaseModel):
|
||||
def __init__(self, pretrained=True, checkpoints=None, **kwargs):
|
||||
super(LayoutLMv2ForRe, self).__init__(LayoutLMv2Model,
|
||||
LayoutLMv2ForRelationExtraction,
|
||||
're', pretrained, checkpoints)
|
||||
def __init__(self, pretrained=True, checkpoints=None, mode="base",
|
||||
**kwargs):
|
||||
super(LayoutLMv2ForRe, self).__init__(
|
||||
LayoutLMv2Model, LayoutLMv2ForRelationExtraction, mode, "re",
|
||||
pretrained, checkpoints)
|
||||
|
||||
def forward(self, x):
|
||||
x = self.model(
|
||||
@@ -158,18 +202,27 @@ class LayoutLMv2ForRe(NLPBaseModel):
|
||||
|
||||
|
||||
class LayoutXLMForRe(NLPBaseModel):
|
||||
def __init__(self, pretrained=True, checkpoints=None, **kwargs):
|
||||
super(LayoutXLMForRe, self).__init__(LayoutXLMModel,
|
||||
LayoutXLMForRelationExtraction,
|
||||
're', pretrained, checkpoints)
|
||||
def __init__(self, pretrained=True, checkpoints=None, mode="base",
|
||||
**kwargs):
|
||||
super(LayoutXLMForRe, self).__init__(
|
||||
LayoutXLMModel, LayoutXLMForRelationExtraction, mode, "re",
|
||||
pretrained, checkpoints)
|
||||
self.use_visual_backbone = True
|
||||
if hasattr(self.model.layoutxlm, "use_visual_backbone"
|
||||
) and self.model.layoutxlm.use_visual_backbone is False:
|
||||
self.use_visual_backbone = False
|
||||
|
||||
def forward(self, x):
|
||||
if self.use_visual_backbone is True:
|
||||
image = x[4]
|
||||
else:
|
||||
image = None
|
||||
x = self.model(
|
||||
input_ids=x[0],
|
||||
bbox=x[1],
|
||||
attention_mask=x[2],
|
||||
token_type_ids=x[3],
|
||||
image=x[4],
|
||||
image=image,
|
||||
position_ids=None,
|
||||
head_mask=None,
|
||||
labels=None,
|
||||
|
||||
@@ -31,21 +31,38 @@ from .rec_postprocess import CTCLabelDecode, AttnLabelDecode, SRNLabelDecode, \
|
||||
SPINLabelDecode
|
||||
from .cls_postprocess import ClsPostProcess
|
||||
from .pg_postprocess import PGPostProcess
|
||||
from .vqa_token_ser_layoutlm_postprocess import VQASerTokenLayoutLMPostProcess
|
||||
from .vqa_token_re_layoutlm_postprocess import VQAReTokenLayoutLMPostProcess
|
||||
from .vqa_token_ser_layoutlm_postprocess import VQASerTokenLayoutLMPostProcess, DistillationSerPostProcess
|
||||
from .vqa_token_re_layoutlm_postprocess import VQAReTokenLayoutLMPostProcess, DistillationRePostProcess
|
||||
from .table_postprocess import TableMasterLabelDecode, TableLabelDecode
|
||||
|
||||
|
||||
def build_post_process(config, global_config=None):
|
||||
support_dict = [
|
||||
'DBPostProcess', 'EASTPostProcess', 'SASTPostProcess', 'FCEPostProcess',
|
||||
'CTCLabelDecode', 'AttnLabelDecode', 'ClsPostProcess', 'SRNLabelDecode',
|
||||
'PGPostProcess', 'DistillationCTCLabelDecode', 'TableLabelDecode',
|
||||
'DistillationDBPostProcess', 'NRTRLabelDecode', 'SARLabelDecode',
|
||||
'SEEDLabelDecode', 'VQASerTokenLayoutLMPostProcess',
|
||||
'VQAReTokenLayoutLMPostProcess', 'PRENLabelDecode',
|
||||
'DistillationSARLabelDecode', 'ViTSTRLabelDecode', 'ABINetLabelDecode',
|
||||
'TableMasterLabelDecode', 'SPINLabelDecode'
|
||||
'DBPostProcess',
|
||||
'EASTPostProcess',
|
||||
'SASTPostProcess',
|
||||
'FCEPostProcess',
|
||||
'CTCLabelDecode',
|
||||
'AttnLabelDecode',
|
||||
'ClsPostProcess',
|
||||
'SRNLabelDecode',
|
||||
'PGPostProcess',
|
||||
'DistillationCTCLabelDecode',
|
||||
'TableLabelDecode',
|
||||
'DistillationDBPostProcess',
|
||||
'NRTRLabelDecode',
|
||||
'SARLabelDecode',
|
||||
'SEEDLabelDecode',
|
||||
'VQASerTokenLayoutLMPostProcess',
|
||||
'VQAReTokenLayoutLMPostProcess',
|
||||
'PRENLabelDecode',
|
||||
'DistillationSARLabelDecode',
|
||||
'ViTSTRLabelDecode',
|
||||
'ABINetLabelDecode',
|
||||
'TableMasterLabelDecode',
|
||||
'SPINLabelDecode',
|
||||
'DistillationSerPostProcess',
|
||||
'DistillationRePostProcess',
|
||||
]
|
||||
|
||||
if config['name'] == 'PSEPostProcess':
|
||||
|
||||
@@ -49,3 +49,25 @@ class VQAReTokenLayoutLMPostProcess(object):
|
||||
result.append((ocr_info_head, ocr_info_tail))
|
||||
results.append(result)
|
||||
return results
|
||||
|
||||
|
||||
class DistillationRePostProcess(VQAReTokenLayoutLMPostProcess):
|
||||
"""
|
||||
DistillationRePostProcess
|
||||
"""
|
||||
|
||||
def __init__(self, model_name=["Student"], key=None, **kwargs):
|
||||
super().__init__(**kwargs)
|
||||
if not isinstance(model_name, list):
|
||||
model_name = [model_name]
|
||||
self.model_name = model_name
|
||||
self.key = key
|
||||
|
||||
def __call__(self, preds, *args, **kwargs):
|
||||
output = dict()
|
||||
for name in self.model_name:
|
||||
pred = preds[name]
|
||||
if self.key is not None:
|
||||
pred = pred[self.key]
|
||||
output[name] = super().__call__(pred, *args, **kwargs)
|
||||
return output
|
||||
|
||||
@@ -93,3 +93,25 @@ class VQASerTokenLayoutLMPostProcess(object):
|
||||
ocr_info[idx]["pred"] = self.id2label_map_for_show[int(pred_id)]
|
||||
results.append(ocr_info)
|
||||
return results
|
||||
|
||||
|
||||
class DistillationSerPostProcess(VQASerTokenLayoutLMPostProcess):
|
||||
"""
|
||||
DistillationSerPostProcess
|
||||
"""
|
||||
|
||||
def __init__(self, class_path, model_name=["Student"], key=None, **kwargs):
|
||||
super().__init__(class_path, **kwargs)
|
||||
if not isinstance(model_name, list):
|
||||
model_name = [model_name]
|
||||
self.model_name = model_name
|
||||
self.key = key
|
||||
|
||||
def __call__(self, preds, batch=None, *args, **kwargs):
|
||||
output = dict()
|
||||
for name in self.model_name:
|
||||
pred = preds[name]
|
||||
if self.key is not None:
|
||||
pred = pred[self.key]
|
||||
output[name] = super().__call__(pred, batch=batch, *args, **kwargs)
|
||||
return output
|
||||
|
||||
@@ -55,6 +55,9 @@ def load_model(config, model, optimizer=None, model_type='det'):
|
||||
best_model_dict = {}
|
||||
|
||||
if model_type == 'vqa':
|
||||
# NOTE: for vqa model, resume training is not supported now
|
||||
if config["Architecture"]["algorithm"] in ["Distillation"]:
|
||||
return best_model_dict
|
||||
checkpoints = config['Architecture']['Backbone']['checkpoints']
|
||||
# load vqa method metric
|
||||
if checkpoints:
|
||||
@@ -78,6 +81,7 @@ def load_model(config, model, optimizer=None, model_type='det'):
|
||||
logger.warning(
|
||||
"{}.pdopt is not exists, params of optimizer is not loaded".
|
||||
format(checkpoints))
|
||||
|
||||
return best_model_dict
|
||||
|
||||
if checkpoints:
|
||||
@@ -166,15 +170,19 @@ def save_model(model,
|
||||
"""
|
||||
_mkdir_if_not_exist(model_path, logger)
|
||||
model_prefix = os.path.join(model_path, prefix)
|
||||
paddle.save(optimizer.state_dict(), model_prefix + '.pdopt')
|
||||
if config['Architecture']["model_type"] != 'vqa':
|
||||
paddle.save(optimizer.state_dict(), model_prefix + '.pdopt')
|
||||
if config['Architecture']["model_type"] != 'vqa':
|
||||
paddle.save(model.state_dict(), model_prefix + '.pdparams')
|
||||
metric_prefix = model_prefix
|
||||
else:
|
||||
else: # for vqa system, we follow the save/load rules in NLP
|
||||
if config['Global']['distributed']:
|
||||
model._layers.backbone.model.save_pretrained(model_prefix)
|
||||
arch = model._layers
|
||||
else:
|
||||
model.backbone.model.save_pretrained(model_prefix)
|
||||
arch = model
|
||||
if config["Architecture"]["algorithm"] in ["Distillation"]:
|
||||
arch = arch.Student
|
||||
arch.backbone.model.save_pretrained(model_prefix)
|
||||
metric_prefix = os.path.join(model_prefix, 'metric')
|
||||
# save metric and config
|
||||
with open(metric_prefix + '.states', 'wb') as f:
|
||||
|
||||
@@ -216,7 +216,7 @@ Use the following command to complete the tandem prediction of `OCR + SER` based
|
||||
|
||||
```shell
|
||||
cd ppstructure
|
||||
CUDA_VISIBLE_DEVICES=0 python3.7 vqa/predict_vqa_token_ser.py --vqa_algorithm=LayoutXLM --ser_model_dir=../output/ser/infer --ser_dict_path=../train_data/XFUND/class_list_xfun.txt --image_dir=docs/vqa/input/zh_val_42.jpg --output=output
|
||||
CUDA_VISIBLE_DEVICES=0 python3.7 vqa/predict_vqa_token_ser.py --vqa_algorithm=LayoutXLM --ser_model_dir=../output/ser/infer --ser_dict_path=../train_data/XFUND/class_list_xfun.txt --vis_font_path=../doc/fonts/simfang.ttf --image_dir=docs/vqa/input/zh_val_42.jpg --output=output
|
||||
```
|
||||
After the prediction is successful, the visualization images and results will be saved in the directory specified by the `output` field
|
||||
|
||||
|
||||
@@ -215,7 +215,7 @@ python3.7 tools/export_model.py -c configs/vqa/ser/layoutxlm.yml -o Architecture
|
||||
|
||||
```shell
|
||||
cd ppstructure
|
||||
CUDA_VISIBLE_DEVICES=0 python3.7 vqa/predict_vqa_token_ser.py --vqa_algorithm=LayoutXLM --ser_model_dir=../output/ser/infer --ser_dict_path=../train_data/XFUND/class_list_xfun.txt --image_dir=docs/vqa/input/zh_val_42.jpg --output=output
|
||||
CUDA_VISIBLE_DEVICES=0 python3.7 vqa/predict_vqa_token_ser.py --vqa_algorithm=LayoutXLM --ser_model_dir=../output/ser/infer --ser_dict_path=../train_data/XFUND/class_list_xfun.txt --vis_font_path=../doc/fonts/simfang.ttf --image_dir=docs/vqa/input/zh_val_42.jpg --output=output
|
||||
```
|
||||
预测成功后,可视化图片和结果会保存在`output`字段指定的目录下
|
||||
|
||||
|
||||
@@ -153,7 +153,7 @@ def main(args):
|
||||
img_res = draw_ser_results(
|
||||
image_file,
|
||||
ser_res,
|
||||
font_path="../doc/fonts/simfang.ttf", )
|
||||
font_path=args.vis_font_path, )
|
||||
|
||||
img_save_path = os.path.join(args.output,
|
||||
os.path.basename(image_file))
|
||||
|
||||
@@ -114,7 +114,7 @@ Train:
|
||||
name: SimpleDataSet
|
||||
data_dir: ./train_data/ic15_data/
|
||||
label_file_list:
|
||||
- ./train_data/ic15_data/rec_gt_train4w.txt
|
||||
- ./train_data/ic15_data/rec_gt_train.txt
|
||||
transforms:
|
||||
- DecodeImage:
|
||||
img_mode: BGR
|
||||
|
||||
@@ -153,7 +153,7 @@ Train:
|
||||
data_dir: ./train_data/ic15_data/
|
||||
ext_op_transform_idx: 1
|
||||
label_file_list:
|
||||
- ./train_data/ic15_data/rec_gt_train4w.txt
|
||||
- ./train_data/ic15_data/rec_gt_train.txt
|
||||
transforms:
|
||||
- DecodeImage:
|
||||
img_mode: BGR
|
||||
|
||||
@@ -52,8 +52,9 @@ null:null
|
||||
===========================infer_benchmark_params==========================
|
||||
random_infer_input:[{float32,[3,48,320]}]
|
||||
===========================train_benchmark_params==========================
|
||||
batch_size:128
|
||||
batch_size:64
|
||||
fp_items:fp32|fp16
|
||||
epoch:1
|
||||
--profiler_options:batch_range=[10,20];state=GPU;tracer_option=Default;profile_path=model.profile
|
||||
flags:FLAGS_eager_delete_tensor_gb=0.0;FLAGS_fraction_of_gpu_memory_to_use=0.98;FLAGS_conv_workspace_size_limit=4096
|
||||
|
||||
|
||||
+1
-1
@@ -1,5 +1,5 @@
|
||||
===========================cpp_infer_params===========================
|
||||
model_name:ch_ppocr_mobile_v2.0
|
||||
model_name:ch_ppocr_mobile_v2_0
|
||||
use_opencv:True
|
||||
infer_model:./inference/ch_ppocr_mobile_v2.0_det_infer/
|
||||
infer_quant:False
|
||||
+1
-1
@@ -1,5 +1,5 @@
|
||||
===========================ch_ppocr_mobile_v2.0===========================
|
||||
model_name:ch_ppocr_mobile_v2.0
|
||||
model_name:ch_ppocr_mobile_v2_0
|
||||
python:python3.7
|
||||
infer_model:./inference/ch_ppocr_mobile_v2.0_det_infer/
|
||||
infer_export:null
|
||||
+1
-1
@@ -1,5 +1,5 @@
|
||||
===========================paddle2onnx_params===========================
|
||||
model_name:ch_ppocr_mobile_v2.0
|
||||
model_name:ch_ppocr_mobile_v2_0
|
||||
python:python3.7
|
||||
2onnx: paddle2onnx
|
||||
--det_model_dir:./inference/ch_ppocr_mobile_v2.0_det_infer/
|
||||
+1
-1
@@ -1,5 +1,5 @@
|
||||
===========================serving_params===========================
|
||||
model_name:ch_ppocr_mobile_v2.0
|
||||
model_name:ch_ppocr_mobile_v2_0
|
||||
python:python3.7
|
||||
trans_model:-m paddle_serving_client.convert
|
||||
--det_dirname:./inference/ch_ppocr_mobile_v2.0_det_infer/
|
||||
+1
-1
@@ -1,5 +1,5 @@
|
||||
===========================cpp_infer_params===========================
|
||||
model_name:ch_ppocr_mobile_v2.0_det
|
||||
model_name:ch_ppocr_mobile_v2_0_det
|
||||
use_opencv:True
|
||||
infer_model:./inference/ch_ppocr_mobile_v2.0_det_infer/
|
||||
infer_quant:False
|
||||
+1
-1
@@ -1,5 +1,5 @@
|
||||
===========================infer_params===========================
|
||||
model_name:ch_ppocr_mobile_v2.0_det
|
||||
model_name:ch_ppocr_mobile_v2_0_det
|
||||
python:python
|
||||
infer_model:./inference/ch_ppocr_mobile_v2.0_det_infer
|
||||
infer_export:null
|
||||
+1
-1
@@ -1,5 +1,5 @@
|
||||
===========================paddle2onnx_params===========================
|
||||
model_name:ch_ppocr_mobile_v2.0_det
|
||||
model_name:ch_ppocr_mobile_v2_0_det
|
||||
python:python3.7
|
||||
2onnx: paddle2onnx
|
||||
--det_model_dir:./inference/ch_ppocr_mobile_v2.0_det_infer/
|
||||
+1
-1
@@ -1,5 +1,5 @@
|
||||
===========================serving_params===========================
|
||||
model_name:ch_ppocr_mobile_v2.0_det
|
||||
model_name:ch_ppocr_mobile_v2_0_det
|
||||
python:python3.7
|
||||
trans_model:-m paddle_serving_client.convert
|
||||
--det_dirname:./inference/ch_ppocr_mobile_v2.0_det_infer/
|
||||
+1
-1
@@ -1,5 +1,5 @@
|
||||
===========================train_params===========================
|
||||
model_name:ch_ppocr_mobile_v2.0_det
|
||||
model_name:ch_ppocr_mobile_v2_0_det
|
||||
python:python3.7
|
||||
gpu_list:0|0,1
|
||||
Global.use_gpu:True|True
|
||||
+1
-1
@@ -1,5 +1,5 @@
|
||||
===========================train_params===========================
|
||||
model_name:ch_ppocr_mobile_v2.0_det
|
||||
model_name:ch_ppocr_mobile_v2_0_det
|
||||
python:python3.7
|
||||
gpu_list:192.168.0.1,192.168.0.2;0,1
|
||||
Global.use_gpu:True
|
||||
+1
-1
@@ -1,5 +1,5 @@
|
||||
===========================train_params===========================
|
||||
model_name:ch_ppocr_mobile_v2.0_det
|
||||
model_name:ch_ppocr_mobile_v2_0_det
|
||||
python:python3.7
|
||||
gpu_list:0|0,1
|
||||
Global.use_gpu:True|True
|
||||
+1
-1
@@ -1,5 +1,5 @@
|
||||
===========================train_params===========================
|
||||
model_name:ch_ppocr_mobile_v2.0_det_PACT
|
||||
model_name:ch_ppocr_mobile_v2_0_det_PACT
|
||||
python:python3.7
|
||||
gpu_list:0|0,1
|
||||
Global.use_gpu:True|True
|
||||
+1
-1
@@ -1,5 +1,5 @@
|
||||
===========================kl_quant_params===========================
|
||||
model_name:ch_ppocr_mobile_v2.0_det_KL
|
||||
model_name:ch_ppocr_mobile_v2_0_det_KL
|
||||
python:python3.7
|
||||
Global.pretrained_model:null
|
||||
Global.save_inference_dir:null
|
||||
+1
-1
@@ -1,5 +1,5 @@
|
||||
===========================train_params===========================
|
||||
model_name:ch_ppocr_mobile_v2.0_det_FPGM
|
||||
model_name:ch_ppocr_mobile_v2_0_det_FPGM
|
||||
python:python3.7
|
||||
gpu_list:0|0,1
|
||||
Global.use_gpu:True|True
|
||||
+1
-1
@@ -1,5 +1,5 @@
|
||||
===========================train_params===========================
|
||||
model_name:ch_ppocr_mobile_v2.0_det_FPGM
|
||||
model_name:ch_ppocr_mobile_v2_0_det_FPGM
|
||||
python:python3.7
|
||||
gpu_list:0|0,1
|
||||
Global.use_gpu:True|True
|
||||
+1
-1
@@ -1,5 +1,5 @@
|
||||
===========================cpp_infer_params===========================
|
||||
model_name:ch_ppocr_mobile_v2.0_det_KL
|
||||
model_name:ch_ppocr_mobile_v2_0_det_KL
|
||||
use_opencv:True
|
||||
infer_model:./inference/ch_ppocr_mobile_v2.0_det_klquant_infer
|
||||
infer_quant:False
|
||||
+1
-1
@@ -1,5 +1,5 @@
|
||||
===========================serving_params===========================
|
||||
model_name:ch_ppocr_mobile_v2.0_rec_KL
|
||||
model_name:ch_ppocr_mobile_v2_0_det_KL
|
||||
python:python3.7
|
||||
trans_model:-m paddle_serving_client.convert
|
||||
--det_dirname:./inference/ch_ppocr_mobile_v2.0_det_klquant_infer/
|
||||
+1
-1
@@ -1,5 +1,5 @@
|
||||
===========================serving_params===========================
|
||||
model_name:ch_ppocr_mobile_v2.0_det_KL
|
||||
model_name:ch_ppocr_mobile_v2_0_det_KL
|
||||
python:python3.7
|
||||
trans_model:-m paddle_serving_client.convert
|
||||
--det_dirname:./inference/ch_ppocr_mobile_v2.0_det_klquant_infer/
|
||||
+1
-1
@@ -1,5 +1,5 @@
|
||||
===========================cpp_infer_params===========================
|
||||
model_name:ch_ppocr_mobile_v2.0_det_PACT
|
||||
model_name:ch_ppocr_mobile_v2_0_det_PACT
|
||||
use_opencv:True
|
||||
infer_model:./inference/ch_ppocr_mobile_v2.0_det_pact_infer
|
||||
infer_quant:False
|
||||
+1
-1
@@ -1,5 +1,5 @@
|
||||
===========================serving_params===========================
|
||||
model_name:ch_ppocr_mobile_v2.0_rec_PACT
|
||||
model_name:ch_ppocr_mobile_v2_0_det_PACT
|
||||
python:python3.7
|
||||
trans_model:-m paddle_serving_client.convert
|
||||
--det_dirname:./inference/ch_ppocr_mobile_v2.0_det_pact_infer/
|
||||
+1
-1
@@ -1,5 +1,5 @@
|
||||
===========================serving_params===========================
|
||||
model_name:ch_ppocr_mobile_v2.0_det_PACT
|
||||
model_name:ch_ppocr_mobile_v2_0_det_PACT
|
||||
python:python3.7
|
||||
trans_model:-m paddle_serving_client.convert
|
||||
--det_dirname:./inference/ch_ppocr_mobile_v2.0_det_pact_infer/
|
||||
+1
-1
@@ -1,5 +1,5 @@
|
||||
===========================cpp_infer_params===========================
|
||||
model_name:ch_ppocr_mobile_v2.0_rec
|
||||
model_name:ch_ppocr_mobile_v2_0_rec
|
||||
use_opencv:True
|
||||
infer_model:./inference/ch_ppocr_mobile_v2.0_rec_infer/
|
||||
infer_quant:False
|
||||
+1
-1
@@ -1,5 +1,5 @@
|
||||
===========================paddle2onnx_params===========================
|
||||
model_name:ch_ppocr_mobile_v2.0_rec
|
||||
model_name:ch_ppocr_mobile_v2_0_rec
|
||||
python:python3.7
|
||||
2onnx: paddle2onnx
|
||||
--det_model_dir:
|
||||
+1
-1
@@ -1,5 +1,5 @@
|
||||
===========================serving_params===========================
|
||||
model_name:ch_ppocr_mobile_v2.0_rec
|
||||
model_name:ch_ppocr_mobile_v2_0_rec
|
||||
python:python3.7
|
||||
trans_model:-m paddle_serving_client.convert
|
||||
--det_dirname:null
|
||||
+1
-1
@@ -1,5 +1,5 @@
|
||||
===========================train_params===========================
|
||||
model_name:ch_ppocr_mobile_v2.0_rec
|
||||
model_name:ch_ppocr_mobile_v2_0_rec
|
||||
python:python3.7
|
||||
gpu_list:0|0,1
|
||||
Global.use_gpu:True|True
|
||||
+1
-1
@@ -1,5 +1,5 @@
|
||||
===========================train_params===========================
|
||||
model_name:ch_ppocr_mobile_v2.0_rec
|
||||
model_name:ch_ppocr_mobile_v2_0_rec
|
||||
python:python3.7
|
||||
gpu_list:192.168.0.1,192.168.0.2;0,1
|
||||
Global.use_gpu:True
|
||||
+1
-1
@@ -1,5 +1,5 @@
|
||||
===========================train_params===========================
|
||||
model_name:ch_ppocr_mobile_v2.0_rec
|
||||
model_name:ch_ppocr_mobile_v2_0_rec
|
||||
python:python3.7
|
||||
gpu_list:0|0,1
|
||||
Global.use_gpu:True|True
|
||||
+3
-3
@@ -1,5 +1,5 @@
|
||||
===========================train_params===========================
|
||||
model_name:ch_ppocr_mobile_v2.0_rec_PACT
|
||||
model_name:ch_ppocr_mobile_v2_0_rec_PACT
|
||||
python:python3.7
|
||||
gpu_list:0
|
||||
Global.use_gpu:True|True
|
||||
@@ -14,7 +14,7 @@ null:null
|
||||
##
|
||||
trainer:pact_train
|
||||
norm_train:null
|
||||
pact_train:deploy/slim/quantization/quant.py -c test_tipc/configs/ch_ppocr_mobile_v2.0_rec_PACT/rec_chinese_lite_train_v2.0.yml -o
|
||||
pact_train:deploy/slim/quantization/quant.py -c test_tipc/configs/ch_ppocr_mobile_v2_0_rec_PACT/rec_chinese_lite_train_v2.0.yml -o
|
||||
fpgm_train:null
|
||||
distill_train:null
|
||||
null:null
|
||||
@@ -28,7 +28,7 @@ null:null
|
||||
Global.save_inference_dir:./output/
|
||||
Global.checkpoints:
|
||||
norm_export:null
|
||||
quant_export:deploy/slim/quantization/export_model.py -c test_tipc/configs/ch_ppocr_mobile_v2.0_rec_PACT/rec_chinese_lite_train_v2.0.yml -o
|
||||
quant_export:deploy/slim/quantization/export_model.py -c test_tipc/configs/ch_ppocr_mobile_v2_0_rec_PACT/rec_chinese_lite_train_v2.0.yml -o
|
||||
fpgm_export:null
|
||||
distill_export:null
|
||||
export1:null
|
||||
+2
-2
@@ -1,10 +1,10 @@
|
||||
===========================kl_quant_params===========================
|
||||
model_name:ch_ppocr_mobile_v2.0_rec_KL
|
||||
model_name:ch_ppocr_mobile_v2_0_rec_KL
|
||||
python:python3.7
|
||||
Global.pretrained_model:null
|
||||
Global.save_inference_dir:null
|
||||
infer_model:./inference/ch_ppocr_mobile_v2.0_rec_infer/
|
||||
infer_export:deploy/slim/quantization/quant_kl.py -c test_tipc/configs/ch_ppocr_mobile_v2.0_rec_KL/rec_chinese_lite_train_v2.0.yml -o
|
||||
infer_export:deploy/slim/quantization/quant_kl.py -c test_tipc/configs/ch_ppocr_mobile_v2_0_rec_KL/rec_chinese_lite_train_v2.0.yml -o
|
||||
infer_quant:True
|
||||
inference:tools/infer/predict_rec.py --rec_image_shape="3,32,320"
|
||||
--use_gpu:False|True
|
||||
+3
-3
@@ -1,5 +1,5 @@
|
||||
===========================train_params===========================
|
||||
model_name:ch_ppocr_mobile_v2.0_rec_FPGM
|
||||
model_name:ch_ppocr_mobile_v2_0_rec_FPGM
|
||||
python:python3.7
|
||||
gpu_list:0
|
||||
Global.use_gpu:True|True
|
||||
@@ -15,7 +15,7 @@ null:null
|
||||
trainer:fpgm_train
|
||||
norm_train:null
|
||||
pact_train:null
|
||||
fpgm_train:deploy/slim/prune/sensitivity_anal.py -c test_tipc/configs/ch_ppocr_mobile_v2.0_rec_FPGM/rec_chinese_lite_train_v2.0.yml -o Global.pretrained_model=./pretrain_models/ch_ppocr_mobile_v2.0_rec_train/best_accuracy
|
||||
fpgm_train:deploy/slim/prune/sensitivity_anal.py -c test_tipc/configs/ch_ppocr_mobile_v2_0_rec_FPGM/rec_chinese_lite_train_v2.0.yml -o Global.pretrained_model=./pretrain_models/ch_ppocr_mobile_v2.0_rec_train/best_accuracy
|
||||
distill_train:null
|
||||
null:null
|
||||
null:null
|
||||
@@ -29,7 +29,7 @@ Global.save_inference_dir:./output/
|
||||
Global.checkpoints:
|
||||
norm_export:null
|
||||
quant_export:null
|
||||
fpgm_export:deploy/slim/prune/export_prune_model.py -c test_tipc/configs/ch_ppocr_mobile_v2.0_rec_FPGM/rec_chinese_lite_train_v2.0.yml -o
|
||||
fpgm_export:deploy/slim/prune/export_prune_model.py -c test_tipc/configs/ch_ppocr_mobile_v2_0_rec_FPGM/rec_chinese_lite_train_v2.0.yml -o
|
||||
distill_export:null
|
||||
export1:null
|
||||
export2:null
|
||||
+1
-1
@@ -1,5 +1,5 @@
|
||||
===========================cpp_infer_params===========================
|
||||
model_name:ch_ppocr_mobile_v2.0_rec_KL
|
||||
model_name:ch_ppocr_mobile_v2_0_rec_KL
|
||||
use_opencv:True
|
||||
infer_model:./inference/ch_ppocr_mobile_v2.0_rec_klquant_infer
|
||||
infer_quant:False
|
||||
+1
-1
@@ -1,5 +1,5 @@
|
||||
===========================serving_params===========================
|
||||
model_name:ch_ppocr_mobile_v2.0_det_KL
|
||||
model_name:ch_ppocr_mobile_v2_0_rec_KL
|
||||
python:python3.7
|
||||
trans_model:-m paddle_serving_client.convert
|
||||
--det_dirname:./inference/ch_ppocr_mobile_v2.0_det_klquant_infer/
|
||||
+1
-1
@@ -1,5 +1,5 @@
|
||||
===========================serving_params===========================
|
||||
model_name:ch_ppocr_mobile_v2.0_rec_KL
|
||||
model_name:ch_ppocr_mobile_v2_0_rec_KL
|
||||
python:python3.7
|
||||
trans_model:-m paddle_serving_client.convert
|
||||
--det_dirname:null
|
||||
+1
-1
@@ -1,5 +1,5 @@
|
||||
===========================cpp_infer_params===========================
|
||||
model_name:ch_ppocr_mobile_v2.0_rec_PACT
|
||||
model_name:ch_ppocr_mobile_v2_0_rec_PACT
|
||||
use_opencv:True
|
||||
infer_model:./inference/ch_ppocr_mobile_v2.0_rec_pact_infer
|
||||
infer_quant:False
|
||||
+1
-1
@@ -1,5 +1,5 @@
|
||||
===========================serving_params===========================
|
||||
model_name:ch_ppocr_mobile_v2.0_det_PACT
|
||||
model_name:ch_ppocr_mobile_v2_0_rec_PACT
|
||||
python:python3.7
|
||||
trans_model:-m paddle_serving_client.convert
|
||||
--det_dirname:./inference/ch_ppocr_mobile_v2.0_det_pact_infer/
|
||||
+1
-1
@@ -1,5 +1,5 @@
|
||||
===========================serving_params===========================
|
||||
model_name:ch_ppocr_mobile_v2.0_rec_PACT
|
||||
model_name:ch_ppocr_mobile_v2_0_rec_PACT
|
||||
python:python3.7
|
||||
trans_model:-m paddle_serving_client.convert
|
||||
--det_dirname:null
|
||||
+1
-1
@@ -1,5 +1,5 @@
|
||||
===========================cpp_infer_params===========================
|
||||
model_name:ch_ppocr_server_v2.0
|
||||
model_name:ch_ppocr_server_v2_0
|
||||
use_opencv:True
|
||||
infer_model:./inference/ch_ppocr_server_v2.0_det_infer/
|
||||
infer_quant:False
|
||||
+1
-1
@@ -1,5 +1,5 @@
|
||||
===========================ch_ppocr_server_v2.0===========================
|
||||
model_name:ch_ppocr_server_v2.0
|
||||
model_name:ch_ppocr_server_v2_0
|
||||
python:python3.7
|
||||
infer_model:./inference/ch_ppocr_server_v2.0_det_infer/
|
||||
infer_export:null
|
||||
+1
-1
@@ -1,5 +1,5 @@
|
||||
===========================paddle2onnx_params===========================
|
||||
model_name:ch_ppocr_server_v2.0
|
||||
model_name:ch_ppocr_server_v2_0
|
||||
python:python3.7
|
||||
2onnx: paddle2onnx
|
||||
--det_model_dir:./inference/ch_ppocr_server_v2.0_det_infer/
|
||||
+1
-1
@@ -1,5 +1,5 @@
|
||||
===========================serving_params===========================
|
||||
model_name:ch_ppocr_server_v2.0
|
||||
model_name:ch_ppocr_server_v2_0
|
||||
python:python3.7
|
||||
trans_model:-m paddle_serving_client.convert
|
||||
--det_dirname:./inference/ch_ppocr_server_v2.0_det_infer/
|
||||
Some files were not shown because too many files have changed in this diff Show More
Reference in New Issue
Block a user