mirror of
https://github.com/AstrBotDevs/AstrBot.git
synced 2026-09-24 16:39:52 +08:00
refactor: remove default web search (#7416)
* refactor: remove default web search

* chore: ruff format
This commit is contained in:
 Soulter
@@ -1,112 +0,0 @@
|
||||
import random
|
||||
import urllib.parse
|
||||
from dataclasses import dataclass
|
||||
|
||||
from aiohttp import ClientSession
|
||||
from bs4 import BeautifulSoup, Tag
|
||||
|
||||
HEADERS = {
|
||||
"User-Agent": "Mozilla/5.0 (Windows NT 6.1; rv:84.0) Gecko/20100101 Firefox/84.0",
|
||||
"Accept": "*/*",
|
||||
"Connection": "keep-alive",
|
||||
"Accept-Language": "en-GB,en;q=0.5",
|
||||
}
|
||||
|
||||
USER_AGENT_BING = "Mozilla/5.0 (Windows NT 6.1; rv:84.0) Gecko/20100101 Firefox/84.0"
|
||||
USER_AGENTS = [
|
||||
"Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/92.0.4515.131 Safari/537.36",
|
||||
"Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/91.0.4472.124 Safari/537.36",
|
||||
"Mozilla/5.0 (Windows NT 10.0; Win64; x64; rv:89.0) Gecko/20100101 Firefox/89.0",
|
||||
"Mozilla/5.0 (Windows NT 10.0; Win64; x64; rv:88.0) Gecko/20100101 Firefox/88.0",
|
||||
"Mozilla/5.0 (Macintosh; Intel Mac OS X 10_15_7) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/92.0.4515.131 Safari/537.36",
|
||||
"Mozilla/5.0 (Macintosh; Intel Mac OS X 10_15_7) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/91.0.4472.124 Safari/537.36",
|
||||
"Mozilla/5.0 (Macintosh; Intel Mac OS X 10_15_7) AppleWebKit/537.36 (KHTML, like Gecko) Version/14.1.2 Safari/537.36",
|
||||
"Mozilla/5.0 (Macintosh; Intel Mac OS X 10_15_7) AppleWebKit/537.36 (KHTML, like Gecko) Version/14.1 Safari/537.36",
|
||||
"Mozilla/5.0 (X11; Ubuntu; Linux x86_64; rv:89.0) Gecko/20100101 Firefox/89.0",
|
||||
"Mozilla/5.0 (X11; Ubuntu; Linux x86_64; rv:88.0) Gecko/20100101 Firefox/88.0",
|
||||
]
|
||||
|
||||
|
||||
@dataclass
|
||||
class SearchResult:
|
||||
title: str
|
||||
url: str
|
||||
snippet: str
|
||||
favicon: str | None = None
|
||||
|
||||
def __str__(self) -> str:
|
||||
return f"{self.title} - {self.url}\n{self.snippet}"
|
||||
|
||||
|
||||
class SearchEngine:
|
||||
"""搜索引擎爬虫基类"""
|
||||
|
||||
def __init__(self) -> None:
|
||||
self.TIMEOUT = 10
|
||||
self.page = 1
|
||||
self.headers = HEADERS
|
||||
|
||||
def _set_selector(self, selector: str) -> str:
|
||||
raise NotImplementedError
|
||||
|
||||
async def _get_next_page(self, query: str) -> str:
|
||||
raise NotImplementedError
|
||||
|
||||
async def _get_html(self, url: str, data: dict | None = None) -> str:
|
||||
headers = self.headers
|
||||
headers["Referer"] = url
|
||||
headers["User-Agent"] = random.choice(USER_AGENTS)
|
||||
if data:
|
||||
async with (
|
||||
ClientSession() as session,
|
||||
session.post(
|
||||
url,
|
||||
headers=headers,
|
||||
data=data,
|
||||
timeout=self.TIMEOUT,
|
||||
) as resp,
|
||||
):
|
||||
ret = await resp.text(encoding="utf-8")
|
||||
return ret
|
||||
else:
|
||||
async with (
|
||||
ClientSession() as session,
|
||||
session.get(
|
||||
url,
|
||||
headers=headers,
|
||||
timeout=self.TIMEOUT,
|
||||
) as resp,
|
||||
):
|
||||
ret = await resp.text(encoding="utf-8")
|
||||
return ret
|
||||
|
||||
def tidy_text(self, text: str) -> str:
|
||||
"""清理文本,去除空格、换行符等"""
|
||||
return text.strip().replace("\n", " ").replace("\r", " ").replace(" ", " ")
|
||||
|
||||
def _get_url(self, tag: Tag) -> str:
|
||||
return self.tidy_text(tag.get_text())
|
||||
|
||||
async def search(self, query: str, num_results: int) -> list[SearchResult]:
|
||||
query = urllib.parse.quote(query)
|
||||
|
||||
try:
|
||||
resp = await self._get_next_page(query)
|
||||
soup = BeautifulSoup(resp, "html.parser")
|
||||
links = soup.select(self._set_selector("links"))
|
||||
results = []
|
||||
for link in links:
|
||||
# Safely get the title text (select_one may return None)
|
||||
title_elem = link.select_one(self._set_selector("title"))
|
||||
title = ""
|
||||
if title_elem is not None:
|
||||
title = self.tidy_text(title_elem.get_text())
|
||||
|
||||
url_tag = link.select_one(self._set_selector("url"))
|
||||
snippet = ""
|
||||
if title and url_tag:
|
||||
url = self._get_url(url_tag)
|
||||
results.append(SearchResult(title=title, url=url, snippet=snippet))
|
||||
return results[:num_results] if len(results) > num_results else results
|
||||
except Exception as e:
|
||||
raise e
|
||||
@@ -1,30 +0,0 @@
|
||||
from . import USER_AGENT_BING, SearchEngine
|
||||
|
||||
|
||||
class Bing(SearchEngine):
|
||||
def __init__(self) -> None:
|
||||
super().__init__()
|
||||
self.base_urls = ["https://cn.bing.com", "https://www.bing.com"]
|
||||
self.headers.update({"User-Agent": USER_AGENT_BING})
|
||||
|
||||
def _set_selector(self, selector: str):
|
||||
selectors = {
|
||||
"url": "div.b_attribution cite",
|
||||
"title": "h2",
|
||||
"text": "p",
|
||||
"links": "ol#b_results > li.b_algo",
|
||||
"next": 'div#b_content nav[role="navigation"] a.sb_pagN',
|
||||
}
|
||||
return selectors[selector]
|
||||
|
||||
async def _get_next_page(self, query) -> str:
|
||||
# if self.page == 1:
|
||||
# await self._get_html(self.base_url)
|
||||
for base_url in self.base_urls:
|
||||
try:
|
||||
url = f"{base_url}/search?q={query}"
|
||||
return await self._get_html(url, None)
|
||||
except Exception as _:
|
||||
self.base_url = base_url
|
||||
continue
|
||||
raise Exception("Bing search failed")
|
||||
@@ -1,52 +0,0 @@
|
||||
import random
|
||||
import re
|
||||
from typing import cast
|
||||
|
||||
from bs4 import BeautifulSoup, Tag
|
||||
|
||||
from . import USER_AGENTS, SearchEngine, SearchResult
|
||||
|
||||
|
||||
class Sogo(SearchEngine):
|
||||
def __init__(self) -> None:
|
||||
super().__init__()
|
||||
self.base_url = "https://www.sogou.com"
|
||||
self.headers["User-Agent"] = random.choice(USER_AGENTS)
|
||||
|
||||
def _set_selector(self, selector: str):
|
||||
selectors = {
|
||||
"url": "h3 > a",
|
||||
"title": "h3",
|
||||
"text": "",
|
||||
"links": "div.results > div.vrwrap:not(.middle-better-hintBox)",
|
||||
"next": "",
|
||||
}
|
||||
return selectors[selector]
|
||||
|
||||
async def _get_next_page(self, query) -> str:
|
||||
url = f"{self.base_url}/web?query={query}"
|
||||
return await self._get_html(url, None)
|
||||
|
||||
def _get_url(self, tag: Tag) -> str:
|
||||
return cast(str, tag.get("href"))
|
||||
|
||||
async def search(self, query: str, num_results: int) -> list[SearchResult]:
|
||||
results = await super().search(query, num_results)
|
||||
for result in results:
|
||||
if result.url.startswith("/link?"):
|
||||
result.url = self.base_url + result.url
|
||||
result.url = await self._parse_url(result.url)
|
||||
return results
|
||||
|
||||
async def _parse_url(self, url) -> str:
|
||||
html = await self._get_html(url)
|
||||
soup = BeautifulSoup(html, "html.parser")
|
||||
script = soup.find("script")
|
||||
if script:
|
||||
script_text = (
|
||||
script.string if script.string is not None else script.get_text()
|
||||
)
|
||||
match = re.search(r'window.location.replace\("(.+?)"\)', script_text)
|
||||
if match:
|
||||
url = match.group(1)
|
||||
return url
|
||||
@@ -1,737 +0,0 @@
|
||||
import asyncio
|
||||
import json
|
||||
import random
|
||||
import uuid
|
||||
|
||||
import aiohttp
|
||||
from bs4 import BeautifulSoup
|
||||
from readability import Document
|
||||
|
||||
from astrbot.api import AstrBotConfig, llm_tool, logger, sp, star
|
||||
from astrbot.api.event import AstrMessageEvent, filter
|
||||
from astrbot.api.provider import ProviderRequest
|
||||
from astrbot.core.provider.func_tool_manager import FunctionToolManager
|
||||
|
||||
from .engines import HEADERS, USER_AGENTS, SearchResult
|
||||
from .engines.bing import Bing
|
||||
from .engines.sogo import Sogo
|
||||
|
||||
|
||||
class Main(star.Star):
|
||||
TOOLS = [
|
||||
"web_search",
|
||||
"fetch_url",
|
||||
"web_search_tavily",
|
||||
"tavily_extract_web_page",
|
||||
"web_search_bocha",
|
||||
"web_search_brave",
|
||||
]
|
||||
|
||||
def __init__(self, context: star.Context) -> None:
|
||||
self.context = context
|
||||
self.tavily_key_index = 0
|
||||
self.tavily_key_lock = asyncio.Lock()
|
||||
|
||||
self.bocha_key_index = 0
|
||||
self.bocha_key_lock = asyncio.Lock()
|
||||
self.brave_key_index = 0
|
||||
self.brave_key_lock = asyncio.Lock()
|
||||
|
||||
# 将 str 类型的 key 迁移至 list[str],并保存
|
||||
cfg = self.context.get_config()
|
||||
provider_settings = cfg.get("provider_settings")
|
||||
if provider_settings:
|
||||
tavily_key = provider_settings.get("websearch_tavily_key")
|
||||
if isinstance(tavily_key, str):
|
||||
logger.info(
|
||||
"检测到旧版 websearch_tavily_key (字符串格式),自动迁移为列表格式并保存。",
|
||||
)
|
||||
if tavily_key:
|
||||
provider_settings["websearch_tavily_key"] = [tavily_key]
|
||||
else:
|
||||
provider_settings["websearch_tavily_key"] = []
|
||||
cfg.save_config()
|
||||
|
||||
bocha_key = provider_settings.get("websearch_bocha_key")
|
||||
if isinstance(bocha_key, str):
|
||||
if bocha_key:
|
||||
provider_settings["websearch_bocha_key"] = [bocha_key]
|
||||
else:
|
||||
provider_settings["websearch_bocha_key"] = []
|
||||
cfg.save_config()
|
||||
|
||||
brave_key = provider_settings.get("websearch_brave_key")
|
||||
if isinstance(brave_key, str):
|
||||
if brave_key:
|
||||
provider_settings["websearch_brave_key"] = [brave_key]
|
||||
else:
|
||||
provider_settings["websearch_brave_key"] = []
|
||||
cfg.save_config()
|
||||
|
||||
self.bing_search = Bing()
|
||||
self.sogo_search = Sogo()
|
||||
self.baidu_initialized = False
|
||||
|
||||
async def _tidy_text(self, text: str) -> str:
|
||||
"""清理文本,去除空格、换行符等"""
|
||||
return text.strip().replace("\n", " ").replace("\r", " ").replace(" ", " ")
|
||||
|
||||
async def _get_from_url(self, url: str) -> str:
|
||||
"""获取网页内容"""
|
||||
header = HEADERS
|
||||
header.update({"User-Agent": random.choice(USER_AGENTS)})
|
||||
async with aiohttp.ClientSession(trust_env=True) as session:
|
||||
async with session.get(url, headers=header) as response:
|
||||
html = await response.text(encoding="utf-8")
|
||||
doc = Document(html)
|
||||
ret = doc.summary(html_partial=True)
|
||||
soup = BeautifulSoup(ret, "html.parser")
|
||||
ret = await self._tidy_text(soup.get_text())
|
||||
return ret
|
||||
|
||||
async def _process_search_result(
|
||||
self,
|
||||
result: SearchResult,
|
||||
idx: int,
|
||||
websearch_link: bool,
|
||||
) -> str:
|
||||
"""处理单个搜索结果"""
|
||||
logger.info(f"web_searcher - scraping web: {result.title} - {result.url}")
|
||||
try:
|
||||
site_result = await self._get_from_url(result.url)
|
||||
except BaseException:
|
||||
site_result = ""
|
||||
site_result = (
|
||||
f"{site_result[:700]}..." if len(site_result) > 700 else site_result
|
||||
)
|
||||
|
||||
header = f"{idx}. {result.title} "
|
||||
|
||||
if websearch_link and result.url:
|
||||
header += result.url
|
||||
|
||||
return f"{header}\n{result.snippet}\n{site_result}\n\n"
|
||||
|
||||
async def _web_search_default(
|
||||
self,
|
||||
query,
|
||||
num_results: int = 5,
|
||||
) -> list[SearchResult]:
|
||||
results = []
|
||||
try:
|
||||
results = await self.bing_search.search(query, num_results)
|
||||
except Exception as e:
|
||||
logger.error(f"bing search error: {e}, try the next one...")
|
||||
if len(results) == 0:
|
||||
logger.debug("search bing failed")
|
||||
try:
|
||||
results = await self.sogo_search.search(query, num_results)
|
||||
except Exception as e:
|
||||
logger.error(f"sogo search error: {e}")
|
||||
if len(results) == 0:
|
||||
logger.debug("search sogo failed")
|
||||
return []
|
||||
|
||||
return results
|
||||
|
||||
async def _get_tavily_key(self, cfg: AstrBotConfig) -> str:
|
||||
"""并发安全的从列表中获取并轮换Tavily API密钥。"""
|
||||
tavily_keys = cfg.get("provider_settings", {}).get("websearch_tavily_key", [])
|
||||
if not tavily_keys:
|
||||
raise ValueError("错误:Tavily API密钥未在AstrBot中配置。")
|
||||
|
||||
async with self.tavily_key_lock:
|
||||
key = tavily_keys[self.tavily_key_index]
|
||||
self.tavily_key_index = (self.tavily_key_index + 1) % len(tavily_keys)
|
||||
return key
|
||||
|
||||
async def _web_search_tavily(
|
||||
self,
|
||||
cfg: AstrBotConfig,
|
||||
payload: dict,
|
||||
) -> list[SearchResult]:
|
||||
"""使用 Tavily 搜索引擎进行搜索"""
|
||||
tavily_key = await self._get_tavily_key(cfg)
|
||||
url = "https://api.tavily.com/search"
|
||||
header = {
|
||||
"Authorization": f"Bearer {tavily_key}",
|
||||
"Content-Type": "application/json",
|
||||
}
|
||||
async with aiohttp.ClientSession(trust_env=True) as session:
|
||||
async with session.post(
|
||||
url,
|
||||
json=payload,
|
||||
headers=header,
|
||||
) as response:
|
||||
if response.status != 200:
|
||||
reason = await response.text()
|
||||
raise Exception(
|
||||
f"Tavily web search failed: {reason}, status: {response.status}",
|
||||
)
|
||||
data = await response.json()
|
||||
results = []
|
||||
for item in data.get("results", []):
|
||||
result = SearchResult(
|
||||
title=item.get("title"),
|
||||
url=item.get("url"),
|
||||
snippet=item.get("content"),
|
||||
favicon=item.get("favicon"),
|
||||
)
|
||||
results.append(result)
|
||||
return results
|
||||
|
||||
async def _extract_tavily(self, cfg: AstrBotConfig, payload: dict) -> list[dict]:
|
||||
"""使用 Tavily 提取网页内容"""
|
||||
tavily_key = await self._get_tavily_key(cfg)
|
||||
url = "https://api.tavily.com/extract"
|
||||
header = {
|
||||
"Authorization": f"Bearer {tavily_key}",
|
||||
"Content-Type": "application/json",
|
||||
}
|
||||
async with aiohttp.ClientSession(trust_env=True) as session:
|
||||
async with session.post(
|
||||
url,
|
||||
json=payload,
|
||||
headers=header,
|
||||
) as response:
|
||||
if response.status != 200:
|
||||
reason = await response.text()
|
||||
raise Exception(
|
||||
f"Tavily web search failed: {reason}, status: {response.status}",
|
||||
)
|
||||
data = await response.json()
|
||||
results: list[dict] = data.get("results", [])
|
||||
if not results:
|
||||
raise ValueError(
|
||||
"Error: Tavily web searcher does not return any results.",
|
||||
)
|
||||
return results
|
||||
|
||||
@llm_tool(name="web_search")
|
||||
async def search_from_search_engine(
|
||||
self,
|
||||
event: AstrMessageEvent,
|
||||
query: str,
|
||||
max_results: int = 5,
|
||||
) -> str:
|
||||
"""搜索网络以回答用户的问题。当用户需要搜索网络以获取即时性的信息时调用此工具。
|
||||
|
||||
Args:
|
||||
query(string): 和用户的问题最相关的搜索关键词,用于在 Google 上搜索。
|
||||
max_results(number): 返回的最大搜索结果数量,默认为 5。
|
||||
|
||||
"""
|
||||
logger.info(f"web_searcher - search_from_search_engine: {query}")
|
||||
cfg = self.context.get_config(umo=event.unified_msg_origin)
|
||||
websearch_link = cfg["provider_settings"].get("web_search_link", False)
|
||||
|
||||
results = await self._web_search_default(query, max_results)
|
||||
if not results:
|
||||
return "Error: web searcher does not return any results."
|
||||
|
||||
tasks = []
|
||||
for idx, result in enumerate(results, 1):
|
||||
task = self._process_search_result(result, idx, websearch_link)
|
||||
tasks.append(task)
|
||||
processed_results = await asyncio.gather(*tasks, return_exceptions=True)
|
||||
ret = ""
|
||||
for processed_result in processed_results:
|
||||
if isinstance(processed_result, BaseException):
|
||||
logger.error(f"Error processing search result: {processed_result}")
|
||||
continue
|
||||
ret += processed_result
|
||||
|
||||
if websearch_link:
|
||||
ret += "\n\n针对问题,请根据上面的结果分点总结,并且在结尾处附上对应内容的参考链接(如有)。"
|
||||
|
||||
return ret
|
||||
|
||||
async def ensure_baidu_ai_search_mcp(self, umo: str | None = None) -> None:
|
||||
if self.baidu_initialized:
|
||||
return
|
||||
cfg = self.context.get_config(umo=umo)
|
||||
key = cfg.get("provider_settings", {}).get(
|
||||
"websearch_baidu_app_builder_key",
|
||||
"",
|
||||
)
|
||||
if not key:
|
||||
raise ValueError(
|
||||
"Error: Baidu AI Search API key is not configured in AstrBot.",
|
||||
)
|
||||
func_tool_mgr = self.context.get_llm_tool_manager()
|
||||
await func_tool_mgr.enable_mcp_server(
|
||||
"baidu_ai_search",
|
||||
config={
|
||||
"transport": "sse",
|
||||
"url": f"http://appbuilder.baidu.com/v2/ai_search/mcp/sse?api_key={key}",
|
||||
"headers": {},
|
||||
"timeout": 600,
|
||||
},
|
||||
)
|
||||
self.baidu_initialized = True
|
||||
logger.info("Successfully initialized Baidu AI Search MCP server.")
|
||||
|
||||
@llm_tool(name="fetch_url")
|
||||
async def fetch_website_content(self, event: AstrMessageEvent, url: str) -> str:
|
||||
"""Fetch the content of a website with the given web url
|
||||
|
||||
Args:
|
||||
url(string): The url of the website to fetch content from
|
||||
|
||||
"""
|
||||
resp = await self._get_from_url(url)
|
||||
return resp
|
||||
|
||||
@llm_tool("web_search_tavily")
|
||||
async def search_from_tavily(
|
||||
self,
|
||||
event: AstrMessageEvent,
|
||||
query: str,
|
||||
max_results: int = 7,
|
||||
search_depth: str = "basic",
|
||||
topic: str = "general",
|
||||
days: int = 3,
|
||||
time_range: str = "",
|
||||
start_date: str = "",
|
||||
end_date: str = "",
|
||||
) -> str:
|
||||
"""A web search tool that uses Tavily to search the web for relevant content.
|
||||
Ideal for gathering current information, news, and detailed web content analysis.
|
||||
|
||||
Args:
|
||||
query(string): Required. Search query.
|
||||
max_results(number): Optional. The maximum number of results to return. Default is 7. Range is 5-20.
|
||||
search_depth(string): Optional. The depth of the search, must be one of 'basic', 'advanced'. Default is "basic".
|
||||
topic(string): Optional. The topic of the search, must be one of 'general', 'news'. Default is "general".
|
||||
days(number): Optional. The number of days back from the current date to include in the search results. Please note that this feature is only available when using the 'news' search topic.
|
||||
time_range(string): Optional. The time range back from the current date to include in the search results. This feature is available for both 'general' and 'news' search topics. Must be one of 'day', 'week', 'month', 'year'.
|
||||
start_date(string): Optional. The start date for the search results in the format 'YYYY-MM-DD'.
|
||||
end_date(string): Optional. The end date for the search results in the format 'YYYY-MM-DD'.
|
||||
|
||||
"""
|
||||
logger.info(f"web_searcher - search_from_tavily: {query}")
|
||||
cfg = self.context.get_config(umo=event.unified_msg_origin)
|
||||
# websearch_link = cfg["provider_settings"].get("web_search_link", False)
|
||||
if not cfg.get("provider_settings", {}).get("websearch_tavily_key", []):
|
||||
raise ValueError("Error: Tavily API key is not configured in AstrBot.")
|
||||
|
||||
# build payload
|
||||
payload = {"query": query, "max_results": max_results, "include_favicon": True}
|
||||
if search_depth not in ["basic", "advanced"]:
|
||||
search_depth = "basic"
|
||||
payload["search_depth"] = search_depth
|
||||
|
||||
if topic not in ["general", "news"]:
|
||||
topic = "general"
|
||||
payload["topic"] = topic
|
||||
|
||||
if topic == "news":
|
||||
payload["days"] = days
|
||||
|
||||
if time_range in ["day", "week", "month", "year"]:
|
||||
payload["time_range"] = time_range
|
||||
if start_date:
|
||||
payload["start_date"] = start_date
|
||||
if end_date:
|
||||
payload["end_date"] = end_date
|
||||
|
||||
results = await self._web_search_tavily(cfg, payload)
|
||||
if not results:
|
||||
return "Error: Tavily web searcher does not return any results."
|
||||
|
||||
ret_ls = []
|
||||
ref_uuid = str(uuid.uuid4())[:4]
|
||||
for idx, result in enumerate(results, 1):
|
||||
index = f"{ref_uuid}.{idx}"
|
||||
ret_ls.append(
|
||||
{
|
||||
"title": f"{result.title}",
|
||||
"url": f"{result.url}",
|
||||
"snippet": f"{result.snippet}",
|
||||
# TODO: do not need ref for non-webchat platform adapter
|
||||
"index": index,
|
||||
}
|
||||
)
|
||||
if result.favicon:
|
||||
sp.temporary_cache["_ws_favicon"][result.url] = result.favicon
|
||||
# ret = "\n".join(ret_ls)
|
||||
ret = json.dumps({"results": ret_ls}, ensure_ascii=False)
|
||||
return ret
|
||||
|
||||
@llm_tool("tavily_extract_web_page")
|
||||
async def tavily_extract_web_page(
|
||||
self,
|
||||
event: AstrMessageEvent,
|
||||
url: str = "",
|
||||
extract_depth: str = "basic",
|
||||
) -> str:
|
||||
"""Extract the content of a web page using Tavily.
|
||||
|
||||
Args:
|
||||
url(string): Required. An URl to extract content from.
|
||||
extract_depth(string): Optional. The depth of the extraction, must be one of 'basic', 'advanced'. Default is "basic".
|
||||
|
||||
"""
|
||||
cfg = self.context.get_config(umo=event.unified_msg_origin)
|
||||
if not cfg.get("provider_settings", {}).get("websearch_tavily_key", []):
|
||||
raise ValueError("Error: Tavily API key is not configured in AstrBot.")
|
||||
|
||||
if not url:
|
||||
raise ValueError("Error: url must be a non-empty string.")
|
||||
if extract_depth not in ["basic", "advanced"]:
|
||||
extract_depth = "basic"
|
||||
payload = {
|
||||
"urls": [url],
|
||||
"extract_depth": extract_depth,
|
||||
}
|
||||
results = await self._extract_tavily(cfg, payload)
|
||||
ret_ls = []
|
||||
for result in results:
|
||||
ret_ls.append(f"URL: {result.get('url', 'No URL')}")
|
||||
ret_ls.append(f"Content: {result.get('raw_content', 'No content')}")
|
||||
ret = "\n".join(ret_ls)
|
||||
if not ret:
|
||||
return "Error: Tavily web searcher does not return any results."
|
||||
return ret
|
||||
|
||||
async def _get_bocha_key(self, cfg: AstrBotConfig) -> str:
|
||||
"""并发安全的从列表中获取并轮换BoCha API密钥。"""
|
||||
bocha_keys = cfg.get("provider_settings", {}).get("websearch_bocha_key", [])
|
||||
if not bocha_keys:
|
||||
raise ValueError("错误:BoCha API密钥未在AstrBot中配置。")
|
||||
|
||||
async with self.bocha_key_lock:
|
||||
key = bocha_keys[self.bocha_key_index]
|
||||
self.bocha_key_index = (self.bocha_key_index + 1) % len(bocha_keys)
|
||||
return key
|
||||
|
||||
async def _web_search_bocha(
|
||||
self,
|
||||
cfg: AstrBotConfig,
|
||||
payload: dict,
|
||||
) -> list[SearchResult]:
|
||||
"""使用 BoCha 搜索引擎进行搜索"""
|
||||
bocha_key = await self._get_bocha_key(cfg)
|
||||
url = "https://api.bochaai.com/v1/web-search"
|
||||
header = {
|
||||
"Authorization": f"Bearer {bocha_key}",
|
||||
"Content-Type": "application/json",
|
||||
}
|
||||
async with aiohttp.ClientSession(trust_env=True) as session:
|
||||
async with session.post(
|
||||
url,
|
||||
json=payload,
|
||||
headers=header,
|
||||
) as response:
|
||||
if response.status != 200:
|
||||
reason = await response.text()
|
||||
raise Exception(
|
||||
f"BoCha web search failed: {reason}, status: {response.status}",
|
||||
)
|
||||
data = await response.json()
|
||||
data = data["data"]["webPages"]["value"]
|
||||
results = []
|
||||
for item in data:
|
||||
result = SearchResult(
|
||||
title=item.get("name"),
|
||||
url=item.get("url"),
|
||||
snippet=item.get("snippet"),
|
||||
favicon=item.get("siteIcon"),
|
||||
)
|
||||
results.append(result)
|
||||
return results
|
||||
|
||||
async def _get_brave_key(self, cfg: AstrBotConfig) -> str:
|
||||
"""并发安全的从列表中获取并轮换 Brave API 密钥。"""
|
||||
brave_keys = cfg.get("provider_settings", {}).get("websearch_brave_key", [])
|
||||
|
||||
async with self.brave_key_lock:
|
||||
key = brave_keys[self.brave_key_index]
|
||||
self.brave_key_index = (self.brave_key_index + 1) % len(brave_keys)
|
||||
return key
|
||||
|
||||
async def _web_search_brave(
|
||||
self,
|
||||
cfg: AstrBotConfig,
|
||||
payload: dict,
|
||||
) -> list[SearchResult]:
|
||||
"""使用 Brave 搜索引擎进行搜索"""
|
||||
brave_key = await self._get_brave_key(cfg)
|
||||
url = "https://api.search.brave.com/res/v1/web/search"
|
||||
header = {
|
||||
"Accept": "application/json",
|
||||
"X-Subscription-Token": brave_key,
|
||||
}
|
||||
async with aiohttp.ClientSession(trust_env=True) as session:
|
||||
async with session.get(
|
||||
url,
|
||||
params=payload,
|
||||
headers=header,
|
||||
) as response:
|
||||
if response.status != 200:
|
||||
reason = await response.text()
|
||||
raise Exception(
|
||||
f"Brave web search failed: {reason}, status: {response.status}",
|
||||
)
|
||||
data = await response.json()
|
||||
rows = data.get("web", {}).get("results", [])
|
||||
results = []
|
||||
for item in rows:
|
||||
result = SearchResult(
|
||||
title=item.get("title", ""),
|
||||
url=item.get("url", ""),
|
||||
snippet=item.get("description", ""),
|
||||
)
|
||||
results.append(result)
|
||||
return results
|
||||
|
||||
@llm_tool("web_search_bocha")
|
||||
async def search_from_bocha(
|
||||
self,
|
||||
event: AstrMessageEvent,
|
||||
query: str,
|
||||
freshness: str = "noLimit",
|
||||
summary: bool = False,
|
||||
include: str = "",
|
||||
exclude: str = "",
|
||||
count: int = 10,
|
||||
) -> str:
|
||||
"""
|
||||
A web search tool based on Bocha Search API, used to retrieve web pages
|
||||
related to the user's query.
|
||||
|
||||
Args:
|
||||
query (string): Required. User's search query.
|
||||
|
||||
freshness (string): Optional. Specifies the time range of the search.
|
||||
Supported values:
|
||||
- "noLimit": No time limit (default, recommended).
|
||||
- "oneDay": Within one day.
|
||||
- "oneWeek": Within one week.
|
||||
- "oneMonth": Within one month.
|
||||
- "oneYear": Within one year.
|
||||
- "YYYY-MM-DD..YYYY-MM-DD": Search within a specific date range.
|
||||
Example: "2025-01-01..2025-04-06".
|
||||
- "YYYY-MM-DD": Search on a specific date.
|
||||
Example: "2025-04-06".
|
||||
It is recommended to use "noLimit", as the search algorithm will
|
||||
automatically optimize time relevance. Manually restricting the
|
||||
time range may result in no search results.
|
||||
|
||||
summary (boolean): Optional. Whether to include a text summary
|
||||
for each search result.
|
||||
- True: Include summary.
|
||||
- False: Do not include summary (default).
|
||||
|
||||
include (string): Optional. Specifies the domains to include in
|
||||
the search. Multiple domains can be separated by "|" or ",".
|
||||
A maximum of 100 domains is allowed.
|
||||
Examples:
|
||||
- "qq.com"
|
||||
- "qq.com|m.163.com"
|
||||
|
||||
exclude (string): Optional. Specifies the domains to exclude from
|
||||
the search. Multiple domains can be separated by "|" or ",".
|
||||
A maximum of 100 domains is allowed.
|
||||
Examples:
|
||||
- "qq.com"
|
||||
- "qq.com|m.163.com"
|
||||
|
||||
count (number): Optional. Number of search results to return.
|
||||
- Range: 1–50
|
||||
- Default: 10
|
||||
The actual number of returned results may be less than the
|
||||
specified count.
|
||||
"""
|
||||
logger.info(f"web_searcher - search_from_bocha: {query}")
|
||||
cfg = self.context.get_config(umo=event.unified_msg_origin)
|
||||
# websearch_link = cfg["provider_settings"].get("web_search_link", False)
|
||||
if not cfg.get("provider_settings", {}).get("websearch_bocha_key", []):
|
||||
raise ValueError("Error: BoCha API key is not configured in AstrBot.")
|
||||
|
||||
# build payload
|
||||
payload = {
|
||||
"query": query,
|
||||
"count": count,
|
||||
}
|
||||
|
||||
# freshness:时间范围
|
||||
if freshness:
|
||||
payload["freshness"] = freshness
|
||||
|
||||
# 是否返回摘要
|
||||
payload["summary"] = summary
|
||||
|
||||
# include:限制搜索域
|
||||
if include:
|
||||
payload["include"] = include
|
||||
|
||||
# exclude:排除搜索域
|
||||
if exclude:
|
||||
payload["exclude"] = exclude
|
||||
|
||||
results = await self._web_search_bocha(cfg, payload)
|
||||
if not results:
|
||||
return "Error: BoCha web searcher does not return any results."
|
||||
|
||||
ret_ls = []
|
||||
ref_uuid = str(uuid.uuid4())[:4]
|
||||
for idx, result in enumerate(results, 1):
|
||||
index = f"{ref_uuid}.{idx}"
|
||||
ret_ls.append(
|
||||
{
|
||||
"title": f"{result.title}",
|
||||
"url": f"{result.url}",
|
||||
"snippet": f"{result.snippet}",
|
||||
"index": index,
|
||||
}
|
||||
)
|
||||
if result.favicon:
|
||||
sp.temporary_cache["_ws_favicon"][result.url] = result.favicon
|
||||
# ret = "\n".join(ret_ls)
|
||||
ret = json.dumps({"results": ret_ls}, ensure_ascii=False)
|
||||
return ret
|
||||
|
||||
@llm_tool("web_search_brave")
|
||||
async def search_from_brave(
|
||||
self,
|
||||
event: AstrMessageEvent,
|
||||
query: str,
|
||||
count: int = 10,
|
||||
country: str = "US",
|
||||
search_lang: str = "zh-hans",
|
||||
freshness: str = "",
|
||||
) -> str:
|
||||
"""
|
||||
A web search tool based on Brave Search API.
|
||||
|
||||
Args:
|
||||
query(string): Required. Search query.
|
||||
count(number): Optional. Number of results to return. Range: 1–20. Default is 10.
|
||||
country(string): Optional. Country code for region-specific results (e.g., "US", "CN").
|
||||
search_lang(string): Optional. Brave language code (e.g., "zh-hans", "en", "en-gb").
|
||||
freshness(string): Optional. "day", "week", "month", "year".
|
||||
"""
|
||||
logger.info(f"web_searcher - search_from_brave: {query}")
|
||||
cfg = self.context.get_config(umo=event.unified_msg_origin)
|
||||
if not cfg.get("provider_settings", {}).get("websearch_brave_key", []):
|
||||
raise ValueError("Error: Brave API key is not configured in AstrBot.")
|
||||
|
||||
if count < 1:
|
||||
count = 1
|
||||
if count > 20:
|
||||
count = 20
|
||||
|
||||
payload = {
|
||||
"q": query,
|
||||
"count": count,
|
||||
"country": country,
|
||||
"search_lang": search_lang,
|
||||
}
|
||||
if freshness in ["day", "week", "month", "year"]:
|
||||
payload["freshness"] = freshness
|
||||
|
||||
results = await self._web_search_brave(cfg, payload)
|
||||
if not results:
|
||||
return "Error: Brave web searcher does not return any results."
|
||||
|
||||
ret_ls = []
|
||||
ref_uuid = str(uuid.uuid4())[:4]
|
||||
for idx, result in enumerate(results, 1):
|
||||
index = f"{ref_uuid}.{idx}"
|
||||
ret_ls.append(
|
||||
{
|
||||
"title": f"{result.title}",
|
||||
"url": f"{result.url}",
|
||||
"snippet": f"{result.snippet}",
|
||||
"index": index,
|
||||
}
|
||||
)
|
||||
ret = json.dumps({"results": ret_ls}, ensure_ascii=False)
|
||||
return ret
|
||||
|
||||
@filter.on_llm_request(priority=-10000)
|
||||
async def edit_web_search_tools(
|
||||
self,
|
||||
event: AstrMessageEvent,
|
||||
req: ProviderRequest,
|
||||
) -> None:
|
||||
"""Get the session conversation for the given event."""
|
||||
cfg = self.context.get_config(umo=event.unified_msg_origin)
|
||||
prov_settings = cfg.get("provider_settings", {})
|
||||
websearch_enable = prov_settings.get("web_search", False)
|
||||
provider = prov_settings.get("websearch_provider", "default")
|
||||
|
||||
tool_set = req.func_tool
|
||||
if isinstance(tool_set, FunctionToolManager):
|
||||
req.func_tool = tool_set.get_full_tool_set()
|
||||
tool_set = req.func_tool
|
||||
|
||||
if not tool_set:
|
||||
return
|
||||
|
||||
if not websearch_enable:
|
||||
# pop tools
|
||||
for tool_name in self.TOOLS:
|
||||
tool_set.remove_tool(tool_name)
|
||||
return
|
||||
|
||||
func_tool_mgr = self.context.get_llm_tool_manager()
|
||||
if provider == "default":
|
||||
web_search_t = func_tool_mgr.get_func("web_search")
|
||||
fetch_url_t = func_tool_mgr.get_func("fetch_url")
|
||||
if web_search_t and web_search_t.active:
|
||||
tool_set.add_tool(web_search_t)
|
||||
if fetch_url_t and fetch_url_t.active:
|
||||
tool_set.add_tool(fetch_url_t)
|
||||
tool_set.remove_tool("web_search_tavily")
|
||||
tool_set.remove_tool("tavily_extract_web_page")
|
||||
tool_set.remove_tool("AIsearch")
|
||||
tool_set.remove_tool("web_search_bocha")
|
||||
tool_set.remove_tool("web_search_brave")
|
||||
elif provider == "tavily":
|
||||
web_search_tavily = func_tool_mgr.get_func("web_search_tavily")
|
||||
tavily_extract_web_page = func_tool_mgr.get_func("tavily_extract_web_page")
|
||||
if web_search_tavily and web_search_tavily.active:
|
||||
tool_set.add_tool(web_search_tavily)
|
||||
if tavily_extract_web_page and tavily_extract_web_page.active:
|
||||
tool_set.add_tool(tavily_extract_web_page)
|
||||
tool_set.remove_tool("web_search")
|
||||
tool_set.remove_tool("fetch_url")
|
||||
tool_set.remove_tool("AIsearch")
|
||||
tool_set.remove_tool("web_search_bocha")
|
||||
tool_set.remove_tool("web_search_brave")
|
||||
elif provider == "baidu_ai_search":
|
||||
try:
|
||||
await self.ensure_baidu_ai_search_mcp(event.unified_msg_origin)
|
||||
aisearch_tool = func_tool_mgr.get_func("AIsearch")
|
||||
if aisearch_tool and aisearch_tool.active:
|
||||
tool_set.add_tool(aisearch_tool)
|
||||
tool_set.remove_tool("web_search")
|
||||
tool_set.remove_tool("fetch_url")
|
||||
tool_set.remove_tool("web_search_tavily")
|
||||
tool_set.remove_tool("tavily_extract_web_page")
|
||||
tool_set.remove_tool("web_search_bocha")
|
||||
tool_set.remove_tool("web_search_brave")
|
||||
except Exception as e:
|
||||
logger.error(f"Cannot Initialize Baidu AI Search MCP Server: {e}")
|
||||
elif provider == "bocha":
|
||||
web_search_bocha = func_tool_mgr.get_func("web_search_bocha")
|
||||
if web_search_bocha and web_search_bocha.active:
|
||||
tool_set.add_tool(web_search_bocha)
|
||||
tool_set.remove_tool("web_search")
|
||||
tool_set.remove_tool("fetch_url")
|
||||
tool_set.remove_tool("AIsearch")
|
||||
tool_set.remove_tool("web_search_tavily")
|
||||
tool_set.remove_tool("tavily_extract_web_page")
|
||||
tool_set.remove_tool("web_search_brave")
|
||||
elif provider == "brave":
|
||||
web_search_brave = func_tool_mgr.get_func("web_search_brave")
|
||||
if web_search_brave and web_search_brave.active:
|
||||
tool_set.add_tool(web_search_brave)
|
||||
tool_set.remove_tool("web_search")
|
||||
tool_set.remove_tool("fetch_url")
|
||||
tool_set.remove_tool("AIsearch")
|
||||
tool_set.remove_tool("web_search_tavily")
|
||||
tool_set.remove_tool("tavily_extract_web_page")
|
||||
tool_set.remove_tool("web_search_bocha")
|
||||
@@ -1,4 +0,0 @@
|
||||
name: astrbot-web-searcher
|
||||
desc: 让 LLM 具有网页检索能力
|
||||
author: Soulter
|
||||
version: 1.14.514
|
||||
@@ -60,7 +60,12 @@ class MainAgentHooks(BaseAgentRunHooks[AstrAgentContext]):
|
||||
if (
|
||||
platform_name == "webchat"
|
||||
and tool.name
|
||||
in ["web_search_tavily", "web_search_bocha", "web_search_brave"]
|
||||
in [
|
||||
"web_search_baidu",
|
||||
"web_search_tavily",
|
||||
"web_search_bocha",
|
||||
"web_search_brave",
|
||||
]
|
||||
and len(run_context.messages) > 0
|
||||
and tool_result
|
||||
and len(tool_result.content)
|
||||
|
||||
@@ -67,6 +67,14 @@ from astrbot.core.tools.cron_tools import (
|
||||
DELETE_CRON_JOB_TOOL,
|
||||
LIST_CRON_JOBS_TOOL,
|
||||
)
|
||||
from astrbot.core.tools.web_search_tools import (
|
||||
TAVILY_EXTRACT_WEB_PAGE_TOOL,
|
||||
WEB_SEARCH_BAIDU_TOOL,
|
||||
WEB_SEARCH_BOCHA_TOOL,
|
||||
WEB_SEARCH_BRAVE_TOOL,
|
||||
WEB_SEARCH_TAVILY_TOOL,
|
||||
normalize_legacy_web_search_config,
|
||||
)
|
||||
from astrbot.core.utils.file_extract import extract_file_moonshotai
|
||||
from astrbot.core.utils.llm_metadata import LLM_METADATAS
|
||||
from astrbot.core.utils.media_utils import (
|
||||
@@ -1054,6 +1062,33 @@ def _proactive_cron_job_tools(req: ProviderRequest) -> None:
|
||||
req.func_tool.add_tool(LIST_CRON_JOBS_TOOL)
|
||||
|
||||
|
||||
async def _apply_web_search_tools(
|
||||
event: AstrMessageEvent,
|
||||
req: ProviderRequest,
|
||||
plugin_context: Context,
|
||||
) -> None:
|
||||
cfg = plugin_context.get_config(umo=event.unified_msg_origin)
|
||||
normalize_legacy_web_search_config(cfg)
|
||||
prov_settings = cfg.get("provider_settings", {})
|
||||
|
||||
if not prov_settings.get("web_search", False):
|
||||
return
|
||||
|
||||
if req.func_tool is None:
|
||||
req.func_tool = ToolSet()
|
||||
|
||||
provider = prov_settings.get("websearch_provider", "tavily")
|
||||
if provider == "tavily":
|
||||
req.func_tool.add_tool(WEB_SEARCH_TAVILY_TOOL)
|
||||
req.func_tool.add_tool(TAVILY_EXTRACT_WEB_PAGE_TOOL)
|
||||
elif provider == "bocha":
|
||||
req.func_tool.add_tool(WEB_SEARCH_BOCHA_TOOL)
|
||||
elif provider == "brave":
|
||||
req.func_tool.add_tool(WEB_SEARCH_BRAVE_TOOL)
|
||||
elif provider == "baidu_ai_search":
|
||||
req.func_tool.add_tool(WEB_SEARCH_BAIDU_TOOL)
|
||||
|
||||
|
||||
def _get_compress_provider(
|
||||
config: MainAgentBuildConfig, plugin_context: Context
|
||||
) -> Provider | None:
|
||||
@@ -1295,6 +1330,7 @@ async def build_main_agent(
|
||||
|
||||
_modalities_fix(provider, req)
|
||||
_plugin_tool_fix(event, req)
|
||||
await _apply_web_search_tools(event, req, plugin_context)
|
||||
_sanitize_context_by_modalities(config, provider, req)
|
||||
|
||||
if config.llm_safety_mode:
|
||||
|
||||
@@ -106,7 +106,7 @@ DEFAULT_CONFIG = {
|
||||
"provider_pool": ["*"], # "*" 表示使用所有可用的提供者
|
||||
"wake_prefix": "",
|
||||
"web_search": False,
|
||||
"websearch_provider": "default",
|
||||
"websearch_provider": "tavily",
|
||||
"websearch_tavily_key": [],
|
||||
"websearch_bocha_key": [],
|
||||
"websearch_brave_key": [],
|
||||
@@ -3175,7 +3175,6 @@ CONFIG_METADATA_3 = {
|
||||
"description": "网页搜索提供商",
|
||||
"type": "string",
|
||||
"options": [
|
||||
"default",
|
||||
"tavily",
|
||||
"baidu_ai_search",
|
||||
"bocha",
|
||||
|
||||
@@ -0,0 +1,602 @@
|
||||
import asyncio
|
||||
import json
|
||||
import uuid
|
||||
from dataclasses import dataclass as std_dataclass
|
||||
from dataclasses import field
|
||||
|
||||
import aiohttp
|
||||
from pydantic import Field
|
||||
from pydantic.dataclasses import dataclass as pydantic_dataclass
|
||||
|
||||
from astrbot.core import logger, sp
|
||||
from astrbot.core.agent.tool import FunctionTool, ToolExecResult
|
||||
from astrbot.core.astr_agent_context import AstrAgentContext
|
||||
|
||||
WEB_SEARCH_TOOL_NAMES = [
|
||||
"web_search_baidu",
|
||||
"web_search_tavily",
|
||||
"tavily_extract_web_page",
|
||||
"web_search_bocha",
|
||||
"web_search_brave",
|
||||
]
|
||||
|
||||
|
||||
@std_dataclass
|
||||
class SearchResult:
|
||||
title: str
|
||||
url: str
|
||||
snippet: str
|
||||
favicon: str | None = None
|
||||
|
||||
|
||||
@std_dataclass
|
||||
class _KeyRotator:
|
||||
setting_name: str
|
||||
provider_name: str
|
||||
index: int = 0
|
||||
lock: asyncio.Lock = field(default_factory=asyncio.Lock)
|
||||
|
||||
async def get(self, provider_settings: dict) -> str:
|
||||
keys = provider_settings.get(self.setting_name, [])
|
||||
if not keys:
|
||||
raise ValueError(
|
||||
f"Error: {self.provider_name} API key is not configured in AstrBot."
|
||||
)
|
||||
|
||||
async with self.lock:
|
||||
key = keys[self.index]
|
||||
self.index = (self.index + 1) % len(keys)
|
||||
return key
|
||||
|
||||
|
||||
_TAVILY_KEY_ROTATOR = _KeyRotator("websearch_tavily_key", "Tavily")
|
||||
_BOCHA_KEY_ROTATOR = _KeyRotator("websearch_bocha_key", "BoCha")
|
||||
_BRAVE_KEY_ROTATOR = _KeyRotator("websearch_brave_key", "Brave")
|
||||
|
||||
|
||||
def normalize_legacy_web_search_config(cfg) -> None:
|
||||
provider_settings = cfg.get("provider_settings")
|
||||
if not provider_settings:
|
||||
return
|
||||
|
||||
changed = False
|
||||
if provider_settings.get(
|
||||
"websearch_provider"
|
||||
) == "default" and provider_settings.get("web_search", False):
|
||||
provider_settings["web_search"] = False
|
||||
changed = True
|
||||
logger.warning(
|
||||
"The default websearch provider is no longer supported. "
|
||||
"Web search has been disabled and the config was saved.",
|
||||
)
|
||||
|
||||
for setting_name in (
|
||||
"websearch_tavily_key",
|
||||
"websearch_bocha_key",
|
||||
"websearch_brave_key",
|
||||
):
|
||||
value = provider_settings.get(setting_name)
|
||||
if isinstance(value, str):
|
||||
provider_settings[setting_name] = [value] if value else []
|
||||
changed = True
|
||||
|
||||
if changed:
|
||||
cfg.save_config()
|
||||
|
||||
|
||||
def _get_runtime(context) -> tuple[dict, dict, str]:
|
||||
agent_ctx = context.context
|
||||
event = agent_ctx.event
|
||||
cfg = agent_ctx.context.get_config(umo=event.unified_msg_origin)
|
||||
provider_settings = cfg.get("provider_settings", {})
|
||||
return cfg, provider_settings, event.unified_msg_origin
|
||||
|
||||
|
||||
def _cache_favicon(url: str, favicon: str | None) -> None:
|
||||
if favicon:
|
||||
sp.temporary_cache["_ws_favicon"][url] = favicon
|
||||
|
||||
|
||||
def _search_result_payload(results: list[SearchResult]) -> str:
|
||||
ref_uuid = str(uuid.uuid4())[:4]
|
||||
ret_ls = []
|
||||
for idx, result in enumerate(results, 1):
|
||||
index = f"{ref_uuid}.{idx}"
|
||||
ret_ls.append(
|
||||
{
|
||||
"title": f"{result.title}",
|
||||
"url": f"{result.url}",
|
||||
"snippet": f"{result.snippet}",
|
||||
"index": index,
|
||||
}
|
||||
)
|
||||
_cache_favicon(result.url, result.favicon)
|
||||
return json.dumps({"results": ret_ls}, ensure_ascii=False)
|
||||
|
||||
|
||||
async def _tavily_search(
|
||||
provider_settings: dict,
|
||||
payload: dict,
|
||||
) -> list[SearchResult]:
|
||||
tavily_key = await _TAVILY_KEY_ROTATOR.get(provider_settings)
|
||||
header = {
|
||||
"Authorization": f"Bearer {tavily_key}",
|
||||
"Content-Type": "application/json",
|
||||
}
|
||||
async with aiohttp.ClientSession(trust_env=True) as session:
|
||||
async with session.post(
|
||||
"https://api.tavily.com/search",
|
||||
json=payload,
|
||||
headers=header,
|
||||
) as response:
|
||||
if response.status != 200:
|
||||
reason = await response.text()
|
||||
raise Exception(
|
||||
f"Tavily web search failed: {reason}, status: {response.status}",
|
||||
)
|
||||
data = await response.json()
|
||||
return [
|
||||
SearchResult(
|
||||
title=item.get("title"),
|
||||
url=item.get("url"),
|
||||
snippet=item.get("content"),
|
||||
favicon=item.get("favicon"),
|
||||
)
|
||||
for item in data.get("results", [])
|
||||
]
|
||||
|
||||
|
||||
async def _tavily_extract(provider_settings: dict, payload: dict) -> list[dict]:
|
||||
tavily_key = await _TAVILY_KEY_ROTATOR.get(provider_settings)
|
||||
header = {
|
||||
"Authorization": f"Bearer {tavily_key}",
|
||||
"Content-Type": "application/json",
|
||||
}
|
||||
async with aiohttp.ClientSession(trust_env=True) as session:
|
||||
async with session.post(
|
||||
"https://api.tavily.com/extract",
|
||||
json=payload,
|
||||
headers=header,
|
||||
) as response:
|
||||
if response.status != 200:
|
||||
reason = await response.text()
|
||||
raise Exception(
|
||||
f"Tavily web search failed: {reason}, status: {response.status}",
|
||||
)
|
||||
data = await response.json()
|
||||
results: list[dict] = data.get("results", [])
|
||||
if not results:
|
||||
raise ValueError(
|
||||
"Error: Tavily web searcher does not return any results."
|
||||
)
|
||||
return results
|
||||
|
||||
|
||||
async def _bocha_search(
|
||||
provider_settings: dict,
|
||||
payload: dict,
|
||||
) -> list[SearchResult]:
|
||||
bocha_key = await _BOCHA_KEY_ROTATOR.get(provider_settings)
|
||||
header = {
|
||||
"Authorization": f"Bearer {bocha_key}",
|
||||
"Content-Type": "application/json",
|
||||
}
|
||||
async with aiohttp.ClientSession(trust_env=True) as session:
|
||||
async with session.post(
|
||||
"https://api.bochaai.com/v1/web-search",
|
||||
json=payload,
|
||||
headers=header,
|
||||
) as response:
|
||||
if response.status != 200:
|
||||
reason = await response.text()
|
||||
raise Exception(
|
||||
f"BoCha web search failed: {reason}, status: {response.status}",
|
||||
)
|
||||
data = await response.json()
|
||||
rows = data["data"]["webPages"]["value"]
|
||||
return [
|
||||
SearchResult(
|
||||
title=item.get("name"),
|
||||
url=item.get("url"),
|
||||
snippet=item.get("snippet"),
|
||||
favicon=item.get("siteIcon"),
|
||||
)
|
||||
for item in rows
|
||||
]
|
||||
|
||||
|
||||
async def _brave_search(
|
||||
provider_settings: dict,
|
||||
payload: dict,
|
||||
) -> list[SearchResult]:
|
||||
brave_key = await _BRAVE_KEY_ROTATOR.get(provider_settings)
|
||||
header = {
|
||||
"Accept": "application/json",
|
||||
"X-Subscription-Token": brave_key,
|
||||
}
|
||||
async with aiohttp.ClientSession(trust_env=True) as session:
|
||||
async with session.get(
|
||||
"https://api.search.brave.com/res/v1/web/search",
|
||||
params=payload,
|
||||
headers=header,
|
||||
) as response:
|
||||
if response.status != 200:
|
||||
reason = await response.text()
|
||||
raise Exception(
|
||||
f"Brave web search failed: {reason}, status: {response.status}",
|
||||
)
|
||||
data = await response.json()
|
||||
rows = data.get("web", {}).get("results", [])
|
||||
return [
|
||||
SearchResult(
|
||||
title=item.get("title", ""),
|
||||
url=item.get("url", ""),
|
||||
snippet=item.get("description", ""),
|
||||
)
|
||||
for item in rows
|
||||
]
|
||||
|
||||
|
||||
async def _baidu_search(
|
||||
provider_settings: dict,
|
||||
payload: dict,
|
||||
) -> list[SearchResult]:
|
||||
api_key = provider_settings.get("websearch_baidu_app_builder_key", "")
|
||||
if not api_key:
|
||||
raise ValueError("Error: Baidu AI Search API key is not configured in AstrBot.")
|
||||
|
||||
headers = {
|
||||
"Authorization": f"Bearer {api_key}",
|
||||
"X-Appbuilder-Authorization": f"Bearer {api_key}",
|
||||
"Content-Type": "application/json",
|
||||
}
|
||||
async with aiohttp.ClientSession(trust_env=True) as session:
|
||||
async with session.post(
|
||||
"https://qianfan.baidubce.com/v2/ai_search/web_search",
|
||||
json=payload,
|
||||
headers=headers,
|
||||
) as response:
|
||||
if response.status != 200:
|
||||
reason = await response.text()
|
||||
raise Exception(
|
||||
f"Baidu AI Search failed: {reason}, status: {response.status}",
|
||||
)
|
||||
data = await response.json()
|
||||
references = data.get("references", [])
|
||||
return [
|
||||
SearchResult(
|
||||
title=item.get("title", ""),
|
||||
url=item.get("url", ""),
|
||||
snippet=item.get("content", ""),
|
||||
favicon=item.get("icon"),
|
||||
)
|
||||
for item in references
|
||||
if item.get("url")
|
||||
]
|
||||
|
||||
|
||||
@pydantic_dataclass
|
||||
class TavilyWebSearchTool(FunctionTool[AstrAgentContext]):
|
||||
name: str = "web_search_tavily"
|
||||
description: str = (
|
||||
"A web search tool that uses Tavily to search the web for relevant content. "
|
||||
"Ideal for gathering current information, news, and detailed web content analysis."
|
||||
)
|
||||
parameters: dict = Field(
|
||||
default_factory=lambda: {
|
||||
"type": "object",
|
||||
"properties": {
|
||||
"query": {"type": "string", "description": "Required. Search query."},
|
||||
"max_results": {
|
||||
"type": "integer",
|
||||
"description": "Optional. The maximum number of results to return. Default is 7. Range is 5-20.",
|
||||
},
|
||||
"search_depth": {
|
||||
"type": "string",
|
||||
"description": 'Optional. The depth of the search, must be one of "basic", "advanced". Default is "basic".',
|
||||
},
|
||||
"topic": {
|
||||
"type": "string",
|
||||
"description": 'Optional. The topic of the search, must be one of "general", "news". Default is "general".',
|
||||
},
|
||||
"days": {
|
||||
"type": "integer",
|
||||
"description": 'Optional. The number of days back from the current date to include in the search results. This only applies when topic is "news".',
|
||||
},
|
||||
"time_range": {
|
||||
"type": "string",
|
||||
"description": 'Optional. The time range back from the current date to include in the search results. Must be one of "day", "week", "month", "year".',
|
||||
},
|
||||
"start_date": {
|
||||
"type": "string",
|
||||
"description": "Optional. The start date for the search results in the format YYYY-MM-DD.",
|
||||
},
|
||||
"end_date": {
|
||||
"type": "string",
|
||||
"description": "Optional. The end date for the search results in the format YYYY-MM-DD.",
|
||||
},
|
||||
},
|
||||
"required": ["query"],
|
||||
}
|
||||
)
|
||||
|
||||
async def call(self, context, **kwargs) -> ToolExecResult:
|
||||
_, provider_settings, _ = _get_runtime(context)
|
||||
if not provider_settings.get("websearch_tavily_key", []):
|
||||
return "Error: Tavily API key is not configured in AstrBot."
|
||||
|
||||
search_depth = kwargs.get("search_depth", "basic")
|
||||
if search_depth not in ["basic", "advanced"]:
|
||||
search_depth = "basic"
|
||||
|
||||
topic = kwargs.get("topic", "general")
|
||||
if topic not in ["general", "news"]:
|
||||
topic = "general"
|
||||
|
||||
payload = {
|
||||
"query": kwargs["query"],
|
||||
"max_results": kwargs.get("max_results", 7),
|
||||
"include_favicon": True,
|
||||
"search_depth": search_depth,
|
||||
"topic": topic,
|
||||
}
|
||||
if topic == "news":
|
||||
payload["days"] = kwargs.get("days", 3)
|
||||
|
||||
time_range = kwargs.get("time_range", "")
|
||||
if time_range in ["day", "week", "month", "year"]:
|
||||
payload["time_range"] = time_range
|
||||
if kwargs.get("start_date"):
|
||||
payload["start_date"] = kwargs["start_date"]
|
||||
if kwargs.get("end_date"):
|
||||
payload["end_date"] = kwargs["end_date"]
|
||||
|
||||
results = await _tavily_search(provider_settings, payload)
|
||||
if not results:
|
||||
return "Error: Tavily web searcher does not return any results."
|
||||
return _search_result_payload(results)
|
||||
|
||||
|
||||
@pydantic_dataclass
|
||||
class TavilyExtractWebPageTool(FunctionTool[AstrAgentContext]):
|
||||
name: str = "tavily_extract_web_page"
|
||||
description: str = "Extract the content of a web page using Tavily."
|
||||
parameters: dict = Field(
|
||||
default_factory=lambda: {
|
||||
"type": "object",
|
||||
"properties": {
|
||||
"url": {
|
||||
"type": "string",
|
||||
"description": "Required. A URL to extract content from.",
|
||||
},
|
||||
"extract_depth": {
|
||||
"type": "string",
|
||||
"description": 'Optional. The depth of the extraction, must be one of "basic", "advanced". Default is "basic".',
|
||||
},
|
||||
},
|
||||
"required": ["url"],
|
||||
}
|
||||
)
|
||||
|
||||
async def call(self, context, **kwargs) -> ToolExecResult:
|
||||
_, provider_settings, _ = _get_runtime(context)
|
||||
if not provider_settings.get("websearch_tavily_key", []):
|
||||
return "Error: Tavily API key is not configured in AstrBot."
|
||||
|
||||
url = str(kwargs.get("url", "")).strip()
|
||||
if not url:
|
||||
return "Error: url must be a non-empty string."
|
||||
|
||||
extract_depth = kwargs.get("extract_depth", "basic")
|
||||
if extract_depth not in ["basic", "advanced"]:
|
||||
extract_depth = "basic"
|
||||
|
||||
results = await _tavily_extract(
|
||||
provider_settings,
|
||||
{"urls": [url], "extract_depth": extract_depth},
|
||||
)
|
||||
ret_ls = []
|
||||
for result in results:
|
||||
ret_ls.append(f"URL: {result.get('url', 'No URL')}")
|
||||
ret_ls.append(f"Content: {result.get('raw_content', 'No content')}")
|
||||
ret = "\n".join(ret_ls)
|
||||
return ret or "Error: Tavily web searcher does not return any results."
|
||||
|
||||
|
||||
@pydantic_dataclass
|
||||
class BochaWebSearchTool(FunctionTool[AstrAgentContext]):
|
||||
name: str = "web_search_bocha"
|
||||
description: str = (
|
||||
"A web search tool based on Bocha Search API, used to retrieve web pages "
|
||||
"related to the user's query."
|
||||
)
|
||||
parameters: dict = Field(
|
||||
default_factory=lambda: {
|
||||
"type": "object",
|
||||
"properties": {
|
||||
"query": {
|
||||
"type": "string",
|
||||
"description": "Required. User's search query.",
|
||||
},
|
||||
"freshness": {
|
||||
"type": "string",
|
||||
"description": 'Optional. Time range of the search. Recommended value is "noLimit".',
|
||||
},
|
||||
"summary": {
|
||||
"type": "boolean",
|
||||
"description": "Optional. Whether to include a text summary for each search result.",
|
||||
},
|
||||
"include": {
|
||||
"type": "string",
|
||||
"description": "Optional. Domains to include in the search, separated by | or ,.",
|
||||
},
|
||||
"exclude": {
|
||||
"type": "string",
|
||||
"description": "Optional. Domains to exclude from the search, separated by | or ,.",
|
||||
},
|
||||
"count": {
|
||||
"type": "integer",
|
||||
"description": "Optional. Number of search results to return. Range: 1-50.",
|
||||
},
|
||||
},
|
||||
"required": ["query"],
|
||||
}
|
||||
)
|
||||
|
||||
async def call(self, context, **kwargs) -> ToolExecResult:
|
||||
_, provider_settings, _ = _get_runtime(context)
|
||||
if not provider_settings.get("websearch_bocha_key", []):
|
||||
return "Error: BoCha API key is not configured in AstrBot."
|
||||
|
||||
payload = {
|
||||
"query": kwargs["query"],
|
||||
"count": kwargs.get("count", 10),
|
||||
"summary": bool(kwargs.get("summary", False)),
|
||||
}
|
||||
if kwargs.get("freshness"):
|
||||
payload["freshness"] = kwargs["freshness"]
|
||||
if kwargs.get("include"):
|
||||
payload["include"] = kwargs["include"]
|
||||
if kwargs.get("exclude"):
|
||||
payload["exclude"] = kwargs["exclude"]
|
||||
|
||||
results = await _bocha_search(provider_settings, payload)
|
||||
if not results:
|
||||
return "Error: BoCha web searcher does not return any results."
|
||||
return _search_result_payload(results)
|
||||
|
||||
|
||||
@pydantic_dataclass
|
||||
class BraveWebSearchTool(FunctionTool[AstrAgentContext]):
|
||||
name: str = "web_search_brave"
|
||||
description: str = "A web search tool based on Brave Search API."
|
||||
parameters: dict = Field(
|
||||
default_factory=lambda: {
|
||||
"type": "object",
|
||||
"properties": {
|
||||
"query": {"type": "string", "description": "Required. Search query."},
|
||||
"count": {
|
||||
"type": "integer",
|
||||
"description": "Optional. Number of results to return. Range: 1-20.",
|
||||
},
|
||||
"country": {
|
||||
"type": "string",
|
||||
"description": 'Optional. Country code for region-specific results, for example "US" or "CN".',
|
||||
},
|
||||
"search_lang": {
|
||||
"type": "string",
|
||||
"description": 'Optional. Brave language code, for example "zh-hans" or "en".',
|
||||
},
|
||||
"freshness": {
|
||||
"type": "string",
|
||||
"description": 'Optional. One of "day", "week", "month", "year".',
|
||||
},
|
||||
},
|
||||
"required": ["query"],
|
||||
}
|
||||
)
|
||||
|
||||
async def call(self, context, **kwargs) -> ToolExecResult:
|
||||
_, provider_settings, _ = _get_runtime(context)
|
||||
if not provider_settings.get("websearch_brave_key", []):
|
||||
return "Error: Brave API key is not configured in AstrBot."
|
||||
|
||||
count = int(kwargs.get("count", 10))
|
||||
if count < 1:
|
||||
count = 1
|
||||
if count > 20:
|
||||
count = 20
|
||||
|
||||
payload = {
|
||||
"q": kwargs["query"],
|
||||
"count": count,
|
||||
"country": kwargs.get("country", "US"),
|
||||
"search_lang": kwargs.get("search_lang", "zh-hans"),
|
||||
}
|
||||
freshness = kwargs.get("freshness", "")
|
||||
if freshness in ["day", "week", "month", "year"]:
|
||||
payload["freshness"] = freshness
|
||||
|
||||
results = await _brave_search(provider_settings, payload)
|
||||
if not results:
|
||||
return "Error: Brave web searcher does not return any results."
|
||||
return _search_result_payload(results)
|
||||
|
||||
|
||||
@pydantic_dataclass
|
||||
class BaiduWebSearchTool(FunctionTool[AstrAgentContext]):
|
||||
name: str = "web_search_baidu"
|
||||
description: str = (
|
||||
"A web search tool based on Baidu AI Search. "
|
||||
"Use this for real-time web retrieval when Baidu AI Search is configured."
|
||||
)
|
||||
parameters: dict = Field(
|
||||
default_factory=lambda: {
|
||||
"type": "object",
|
||||
"properties": {
|
||||
"query": {"type": "string", "description": "Required. Search query."},
|
||||
"top_k": {
|
||||
"type": "integer",
|
||||
"description": "Optional. Number of web results to return. Maximum 50. Default is 10.",
|
||||
},
|
||||
"search_recency_filter": {
|
||||
"type": "string",
|
||||
"description": 'Optional. One of "week", "month", "semiyear", "year".',
|
||||
},
|
||||
"site": {
|
||||
"type": "string",
|
||||
"description": "Optional. Restrict search to specific sites, separated by commas.",
|
||||
},
|
||||
},
|
||||
"required": ["query"],
|
||||
}
|
||||
)
|
||||
|
||||
async def call(self, context, **kwargs) -> ToolExecResult:
|
||||
_, provider_settings, _ = _get_runtime(context)
|
||||
if not provider_settings.get("websearch_baidu_app_builder_key", ""):
|
||||
return "Error: Baidu AI Search API key is not configured in AstrBot."
|
||||
|
||||
top_k = int(kwargs.get("top_k", 10))
|
||||
if top_k < 1:
|
||||
top_k = 1
|
||||
if top_k > 50:
|
||||
top_k = 50
|
||||
|
||||
payload = {
|
||||
"messages": [{"role": "user", "content": str(kwargs["query"])[:72]}],
|
||||
"search_source": "baidu_search_v2",
|
||||
"resource_type_filter": [{"type": "web", "top_k": top_k}],
|
||||
}
|
||||
|
||||
search_recency_filter = kwargs.get("search_recency_filter", "")
|
||||
if search_recency_filter in ["week", "month", "semiyear", "year"]:
|
||||
payload["search_recency_filter"] = search_recency_filter
|
||||
|
||||
site = str(kwargs.get("site", "")).strip()
|
||||
if site:
|
||||
sites = [s.strip() for s in site.replace("|", ",").split(",") if s.strip()]
|
||||
if sites:
|
||||
payload["search_filter"] = {"match": {"site": sites[:100]}}
|
||||
|
||||
results = await _baidu_search(provider_settings, payload)
|
||||
if not results:
|
||||
return "Error: Baidu AI Search does not return any results."
|
||||
return _search_result_payload(results)
|
||||
|
||||
|
||||
WEB_SEARCH_TAVILY_TOOL = TavilyWebSearchTool()
|
||||
TAVILY_EXTRACT_WEB_PAGE_TOOL = TavilyExtractWebPageTool()
|
||||
WEB_SEARCH_BOCHA_TOOL = BochaWebSearchTool()
|
||||
WEB_SEARCH_BRAVE_TOOL = BraveWebSearchTool()
|
||||
WEB_SEARCH_BAIDU_TOOL = BaiduWebSearchTool()
|
||||
|
||||
__all__ = [
|
||||
"WEB_SEARCH_BAIDU_TOOL",
|
||||
"WEB_SEARCH_BOCHA_TOOL",
|
||||
"WEB_SEARCH_BRAVE_TOOL",
|
||||
"WEB_SEARCH_TAVILY_TOOL",
|
||||
"TAVILY_EXTRACT_WEB_PAGE_TOOL",
|
||||
"WEB_SEARCH_TOOL_NAMES",
|
||||
"normalize_legacy_web_search_config",
|
||||
]
|
||||
@@ -224,7 +224,12 @@ class ChatRoute(Route):
|
||||
Returns:
|
||||
包含 used 列表的字典,记录被引用的搜索结果
|
||||
"""
|
||||
supported = ["web_search_tavily", "web_search_bocha", "web_search_brave"]
|
||||
supported = [
|
||||
"web_search_baidu",
|
||||
"web_search_tavily",
|
||||
"web_search_bocha",
|
||||
"web_search_brave",
|
||||
]
|
||||
# 从 accumulated_parts 中找到所有 web_search_tavily 的工具调用结果
|
||||
web_search_results = {}
|
||||
tool_call_parts = [
|
||||
|
||||
@@ -198,7 +198,12 @@ class LiveChatRoute(Route):
|
||||
self, accumulated_text: str, accumulated_parts: list
|
||||
) -> dict:
|
||||
"""从消息中提取 web_search 引用。"""
|
||||
supported = ["web_search_tavily", "web_search_bocha", "web_search_brave"]
|
||||
supported = [
|
||||
"web_search_baidu",
|
||||
"web_search_tavily",
|
||||
"web_search_bocha",
|
||||
"web_search_brave",
|
||||
]
|
||||
web_search_results = {}
|
||||
tool_call_parts = [
|
||||
p
|
||||
|
||||
@@ -304,7 +304,7 @@ export default {
|
||||
part.tool_calls.forEach(toolCall => {
|
||||
// 检查是否是支持引用解析的 web_search 工具调用
|
||||
if (
|
||||
!['web_search_tavily', 'web_search_bocha', 'web_search_brave'].includes(toolCall.name) ||
|
||||
!['web_search_baidu', 'web_search_tavily', 'web_search_bocha', 'web_search_brave'].includes(toolCall.name) ||
|
||||
!toolCall.result
|
||||
) {
|
||||
return;
|
||||
|
||||
@@ -58,7 +58,7 @@ The default AstrBot configuration is as follows:
|
||||
"provider_pool": ["*"], # "*" means use all available providers
|
||||
"wake_prefix": "",
|
||||
"web_search": False,
|
||||
"websearch_provider": "default",
|
||||
"websearch_provider": "tavily",
|
||||
"websearch_tavily_key": [],
|
||||
"websearch_bocha_key": [],
|
||||
"websearch_brave_key": [],
|
||||
@@ -288,9 +288,7 @@ Whether to enable AstrBot's built-in web search capability. Default is `false`.
|
||||
|
||||
#### `provider_settings.websearch_provider`
|
||||
|
||||
Web search provider type. Default is `default`. Currently supports `default`, `tavily`, `bocha`, `baidu_ai_search`, and `brave`.
|
||||
|
||||
- `default`: Works best when Google is accessible. If Google fails, it tries Bing and Sogou in order.
|
||||
Web search provider type. Default is `tavily`. Currently supports `tavily`, `bocha`, `baidu_ai_search`, and `brave`.
|
||||
|
||||
- `tavily`: Uses the Tavily search engine.
|
||||
- `bocha`: Uses the BoCha search engine.
|
||||
|
||||
@@ -1,7 +1,7 @@
|
||||
|
||||
# Web Search
|
||||
|
||||
The web search feature aims to provide large language models with the ability to invoke search engines like Google, Bing, and Sogou to obtain recent world information, which can improve the accuracy of model responses and reduce hallucinations to some extent.
|
||||
The web search feature gives large language models internet retrieval capability for recent information, which can improve response accuracy and reduce hallucinations to some extent.
|
||||
|
||||
AstrBot's built-in web search functionality relies on the large language model's `function calling` capability. If you're not familiar with function calling, please refer to: [Function Calling](/use/websearch).
|
||||
|
||||
@@ -14,22 +14,28 @@ When using a large language model that supports function calling with the web se
|
||||
|
||||
And other prompts with search intent to trigger the model to invoke the search tool.
|
||||
|
||||
AstrBot supports 3 types of web search source integration: `default`, `Tavily`, and `Baidu AI Search`.
|
||||
|
||||
The former uses AstrBot's built-in web search requester to query Google, Bing, and Sogou search engines, performing best in network environments with Google access. **We recommend using Tavily**.
|
||||
AstrBot currently supports 4 web search providers: `Tavily`, `BoCha`, `Baidu AI Search`, and `Brave`.
|
||||
|
||||
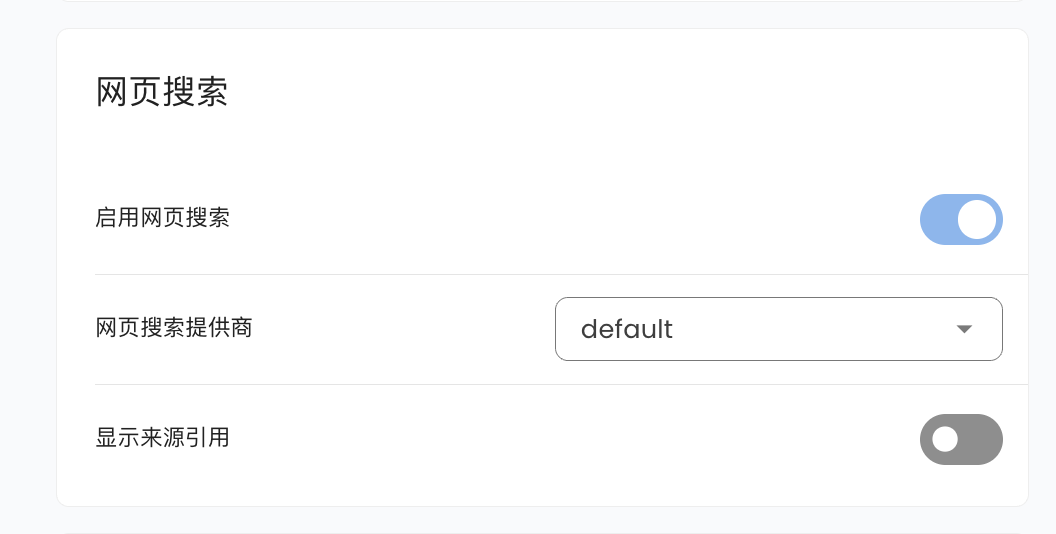
|
||||
|
||||
Go to `Configuration`, scroll down to find Web Search, where you can select `default` (default, not recommended) or `Tavily`.
|
||||
|
||||
### default (Not Recommended)
|
||||
|
||||
If your device is in China and you have a proxy, you can enable the proxy and enter the HTTP proxy address in `Admin Panel - Other Configuration - HTTP Proxy` to apply the proxy.
|
||||
Go to `Configuration`, scroll down to find Web Search, where you can select `Tavily`, `BoCha`, `Baidu AI Search`, or `Brave`.
|
||||
|
||||
### Tavily
|
||||
|
||||
Go to [Tavily](https://app.tavily.com/home) to get an API Key, then fill it in the corresponding configuration item.
|
||||
|
||||
### BoCha
|
||||
|
||||
Get an API Key from the BoCha platform, then fill it in the corresponding configuration item.
|
||||
|
||||
### Baidu AI Search
|
||||
|
||||
Get an API Key from Baidu Qianfan APP Builder, then fill it in the corresponding configuration item.
|
||||
|
||||
### Brave
|
||||
|
||||
Get an API Key from Brave Search, then fill it in the corresponding configuration item.
|
||||
|
||||
If you use Tavily as your web search source, you will get a better experience optimization on AstrBot ChatUI, including citation source display and more:
|
||||
|
||||
|
||||
|
||||
@@ -58,7 +58,7 @@ AstrBot 默认配置如下:
|
||||
"provider_pool": ["*"], # "*" 表示使用所有可用的提供者
|
||||
"wake_prefix": "",
|
||||
"web_search": False,
|
||||
"websearch_provider": "default",
|
||||
"websearch_provider": "tavily",
|
||||
"websearch_tavily_key": [],
|
||||
"websearch_bocha_key": [],
|
||||
"websearch_brave_key": [],
|
||||
@@ -288,9 +288,7 @@ ID 白名单。填写后,将只处理所填写的 ID 发来的消息事件。
|
||||
|
||||
#### `provider_settings.websearch_provider`
|
||||
|
||||
网页搜索提供商类型。默认为 `default`。目前支持 `default`、`tavily`、`bocha`、`baidu_ai_search`、`brave`。
|
||||
|
||||
- `default`:能访问 Google 时效果最佳。如果 Google 访问失败,程序会依次访问 Bing, Sogo 搜索引擎。
|
||||
网页搜索提供商类型。默认为 `tavily`。目前支持 `tavily`、`bocha`、`baidu_ai_search`、`brave`。
|
||||
|
||||
- `tavily`:使用 Tavily 搜索引擎。
|
||||
- `bocha`:使用 BoCha 搜索引擎。
|
||||
|
||||
+16
-10
@@ -1,6 +1,6 @@
|
||||
# 网页搜索
|
||||
|
||||
网页搜索功能旨在提供大模型调用 Google,Bing,搜狗等搜索引擎以获取世界最近信息的能力,一定程度上能够提高大模型的回复准确度,减少幻觉。
|
||||
网页搜索功能旨在为大模型提供联网检索能力,以获取最近信息,一定程度上能够提高回复准确度,减少幻觉。
|
||||
|
||||
AstrBot 内置的网页搜索功能依赖大模型提供 `函数调用` 能力。如果你不了解函数调用,请参考:[函数调用](/use/websearch)。
|
||||
|
||||
@@ -13,22 +13,28 @@ AstrBot 内置的网页搜索功能依赖大模型提供 `函数调用` 能力
|
||||
|
||||
等等带有搜索意味的提示让大模型触发调用搜索工具。
|
||||
|
||||
AstrBot 支持 3 种网页搜索源接入方式:`默认`、`Tavily`、`百度 AI 搜索`。
|
||||
|
||||
前者使用 AstrBot 内置的网页搜索请求器请求 Google、Bing、搜狗搜索引擎,在能够使用 Google 的网络环境下表现最佳。**我们推荐使用 Tavily**。
|
||||
AstrBot 当前支持 4 种网页搜索源接入方式:`Tavily`、`BoCha`、`百度 AI 搜索`、`Brave`。
|
||||
|
||||

|
||||
|
||||
进入 `配置`,下拉找到网页搜索,您可选择 `default`(默认,不推荐) 或 `Tavily`。
|
||||
|
||||
### default(不推荐)
|
||||
|
||||
如果您的设备在国内并且有代理,可以开启代理并在 `管理面板-其他配置-HTTP代理` 填入 HTTP 代理地址以应用代理。
|
||||
进入 `配置`,下拉找到网页搜索,您可选择 `Tavily`、`BoCha`、`百度 AI 搜索` 或 `Brave`。
|
||||
|
||||
### Tavily
|
||||
|
||||
前往 [Tavily](https://app.tavily.com/home) 得到 API Key,然后填写在相应的配置项。
|
||||
|
||||
### BoCha
|
||||
|
||||
前往 BoCha 平台获取 API Key,然后填写在相应的配置项。
|
||||
|
||||
### 百度 AI 搜索
|
||||
|
||||
前往百度千帆 APP Builder 获取 API Key,然后填写在相应的配置项。
|
||||
|
||||
### Brave
|
||||
|
||||
前往 Brave Search 获取 API Key,然后填写在相应的配置项。
|
||||
|
||||
如果您使用 Tavily 作为网页搜索源,在 AstrBot ChatUI 上将会获得更好的体验优化,包括引用来源展示等:
|
||||
|
||||

|
||||

|
||||
|
||||
Reference in New Issue
Block a user