diff --git a/.gitignore b/.gitignore
index 3235390..f889629 100644
--- a/.gitignore
+++ b/.gitignore
@@ -14,6 +14,7 @@ tmp/*
/.tmp-*
/main.js
/NUL
+/.playwright-cli/
.DS_Store
Thumbs.db
diff --git a/README.md b/README.md
index 1cbd83c..a869fab 100644
--- a/README.md
+++ b/README.md
@@ -208,21 +208,60 @@
模型广场 — 一站式浏览所有可用模型的覆盖率、定价和性能指标
-### ✅ 自动签到 · 💰 余额管理 · 🔔 告警通知 · 📊 数据看板
+### ✅ 自动签到
-- **自动签到**:Cron 定时执行,智能解析奖励金额,签到失败自动通知
-- **余额管理**:定时刷新,收入追踪,余额兜底估算,凭证过期自动重登录
-- **告警通知**:支持 Webhook / Bark / Server酱 / Telegram Bot / SMTP 邮件,覆盖余额不足、站点异常、签到失败等场景
-- **数据看板**:余额分布饼图、消费趋势图表、全局搜索、代理请求日志
+- Cron 定时执行(默认每日 08:00)
+- 智能解析奖励金额,签到失败自动通知
+- 按账号启用/禁用控制
+- 完整签到日志与历史查询
+- 并发锁防止重复签到
+
+### 💰 余额管理
+
+- 定时余额刷新(默认每小时),批量更新所有活跃账号
+- 收入追踪:每日/累计收入与消费趋势分析
+- 余额兜底估算:API 不可用时通过代理日志推算余额变动
+- 凭证过期自动重新登录
+
+### 🔔 告警通知
+
+支持五种通知渠道:
+
+| 渠道 | 说明 |
+| --- | --- |
+| **Webhook** | 自定义 HTTP 推送 |
+| **Bark** | iOS 推送通知 |
+| **Server酱** | 微信通知 |
+| **Telegram Bot** | Telegram 消息通知 |
+| **SMTP 邮件** | 标准邮件通知 |
+
+告警场景:余额不足预警、站点/账号异常、签到失败、代理请求失败、Token 过期提醒、每日摘要报告。告警冷却机制(默认 300 秒)防止重复通知。
+
+### 📊 数据看板
+
+- 站点余额饼图、每日消费趋势图
+- 全局搜索(站点、账号、模型)
+- 系统事件日志、代理请求日志(模型、状态、延迟、Token 用量、成本估算)

数据看板 — 余额分布、消费趋势、系统健康状态一目了然
+### 🎮 模型操练场
+
+- 交互式聊天测试,即时验证模型可用性与响应质量
+- 选择任意路由模型,对比不同通道输出
+- 流式 / 非流式双模式测试
+
+
+

+
模型操练场 — 在线交互测试,验证模型可用性与响应质量
+
 +### Docker Compose(推荐)
+
```bash
-docker run -d --name metapi -p 4000:4000 \
+mkdir metapi && cd metapi
+
+cat > docker-compose.yml << 'EOF'
+services:
+ metapi:
+ image: 1467078763/metapi:latest
+ ports:
+ - "4000:4000"
+ volumes:
+ - ./data:/app/data
+ environment:
+ AUTH_TOKEN: ${AUTH_TOKEN:?AUTH_TOKEN is required}
+ PROXY_TOKEN: ${PROXY_TOKEN:?PROXY_TOKEN is required}
+ CHECKIN_CRON: "0 8 * * *"
+ BALANCE_REFRESH_CRON: "0 * * * *"
+ PORT: ${PORT:-4000}
+ DATA_DIR: /app/data
+ TZ: ${TZ:-Asia/Shanghai}
+ restart: unless-stopped
+EOF
+
+# 设置 Token 并启动
+# AUTH_TOKEN = 管理后台登录令牌(登录时输入此值)
+export AUTH_TOKEN=your-admin-token
+# PROXY_TOKEN = 下游客户端调用 /v1/* 的 Token
+export PROXY_TOKEN=your-proxy-sk-token
+docker compose up -d
+```
+
+
+一行 Docker 命令
+
+```bash
+docker run -d --name metapi \
+ -p 4000:4000 \
-e AUTH_TOKEN=your-admin-token \
-e PROXY_TOKEN=your-proxy-sk-token \
- -v ./data:/app/data --restart unless-stopped \
+ -e TZ=Asia/Shanghai \
+ -v ./data:/app/data \
+ --restart unless-stopped \
1467078763/metapi:latest
```
+
+
启动后访问 `http://localhost:4000`,用 `AUTH_TOKEN` 登录即可。
> [!IMPORTANT]
-> 请务必修改 `AUTH_TOKEN` 和 `PROXY_TOKEN`,不要使用默认值。
+> 请务必修改 `AUTH_TOKEN` 和 `PROXY_TOKEN`,不要使用默认值。数据存储在 `./data` 目录,升级不会丢失。
-📖 **[完整部署文档](https://metapi.cita777.me/deployment)** — Zeabur 一键部署 / Docker Compose / 桌面版安装包 / 反向代理 / 升级回滚
+> [!TIP]
+> 初始管理员令牌即启动时配置的 `AUTH_TOKEN`。
+> 若在 Compose 外运行且未显式设置 `AUTH_TOKEN`,默认为 `change-me-admin-token`(仅用于本地调试)。
+> 如果在「设置」面板中修改了管理员令牌,后续登录请使用新令牌。
-📖 **[环境变量与配置](https://metapi.cita777.me/configuration)** — 全部环境变量、路由参数、通知渠道
+Docker Compose、桌面安装包、反向代理、升级与数据库选项等详见 [部署指南](https://metapi.cita777.me/deployment)。
-📖 **[客户端接入指南](https://metapi.cita777.me/client-integration)** — Cursor / Claude Code / Codex / Open WebUI 等配置方法
+📖 **[环境变量与配置](https://metapi.cita777.me/configuration)** · **[客户端接入指南](https://metapi.cita777.me/client-integration)** · **[常见问题](https://metapi.cita777.me/faq)**
---
@@ -349,7 +431,7 @@ Metapi 完全自托管,所有数据(账号、令牌、路由、日志)均
## ⭐ Star History
-[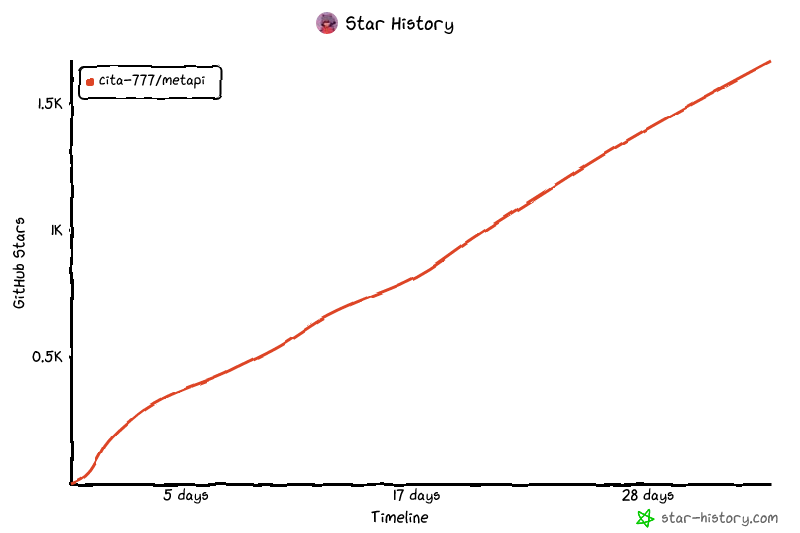](https://www.star-history.com/?repos=cita-777%2Fmetapi&type=timeline&legend=top-left)
+[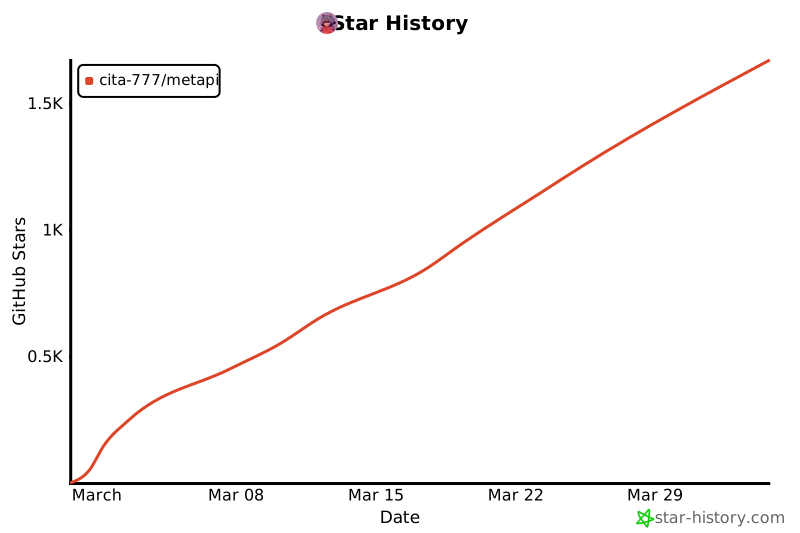](https://www.star-history.com/#cita-777/metapi&type=date&legend=top-left)
---
diff --git a/README_EN.md b/README_EN.md
index 702e136..482c38e 100644
--- a/README_EN.md
+++ b/README_EN.md
@@ -27,7 +27,10 @@ into one API Key, one endpoint, with automatic model discovery,

 +-->
+
+
@@ -36,11 +39,12 @@ into one API Key, one endpoint, with automatic model discovery,
- Docs ·
- Quick Start ·
- Deployment ·
- Configuration ·
- FAQ ·
+ Docs ·
+ Quick Start ·
+ Deployment ·
+ Configuration ·
+ Client Integration ·
+ FAQ ·
Contributing
@@ -575,6 +579,7 @@ If you discover a security issue, please refer to [SECURITY.md](SECURITY.md) and
## Star History
[](https://www.star-history.com/#cita-777/metapi&type=date&legend=top-left)
+
---
diff --git a/docs/.vitepress/config.test.ts b/docs/.vitepress/config.test.ts
new file mode 100644
index 0000000..0e60588
--- /dev/null
+++ b/docs/.vitepress/config.test.ts
@@ -0,0 +1,96 @@
+import { existsSync, globSync } from 'node:fs';
+import { resolve } from 'node:path';
+import { fileURLToPath } from 'node:url';
+import { describe, expect, it } from 'vitest';
+import config from './config';
+
+const getAliasEntry = (aliasConfig: unknown, specifier: string) => {
+ if (!aliasConfig) return undefined;
+
+ if (Array.isArray(aliasConfig)) {
+ return aliasConfig.find(
+ (entry) =>
+ entry &&
+ typeof entry === 'object' &&
+ 'find' in entry &&
+ ((typeof entry.find === 'string' && entry.find === specifier) ||
+ (entry.find instanceof RegExp && entry.find.test(specifier))),
+ );
+ }
+
+ if (typeof aliasConfig === 'object' && aliasConfig !== null && specifier in aliasConfig) {
+ return {
+ find: specifier,
+ replacement: String((aliasConfig as Record
)[specifier]),
+ };
+ }
+
+ return undefined;
+};
+
+const getAlias = (aliasConfig: unknown, specifier: string): string | undefined => {
+ const aliasEntry = getAliasEntry(aliasConfig, specifier);
+ return aliasEntry && typeof aliasEntry === 'object' && 'replacement' in aliasEntry ? String(aliasEntry.replacement) : undefined;
+};
+
+const repoRoot = fileURLToPath(new URL('../..', import.meta.url));
+
+const getExpectedEntry = (hoistedRelativePath: string, pnpmPattern: string) => {
+ const hoistedEntry = resolve(repoRoot, hoistedRelativePath);
+ if (existsSync(hoistedEntry)) return hoistedEntry;
+
+ const [pnpmEntry] = globSync(resolve(repoRoot, pnpmPattern));
+ return pnpmEntry;
+};
+
+describe('docs vitepress config', () => {
+ it('ships copied main-app favicon assets for docs', () => {
+ expect(existsSync(resolve(repoRoot, 'docs/public/favicon.png'))).toBe(true);
+ expect(existsSync(resolve(repoRoot, 'docs/public/favicon-64.png'))).toBe(true);
+ expect(existsSync(resolve(repoRoot, 'docs/public/favicon.ico'))).toBe(true);
+ });
+
+ it('ships a fallback favicon.ico for browsers that probe the default path', () => {
+ expect(existsSync(resolve(repoRoot, 'docs/public/favicon.ico'))).toBe(true);
+ });
+
+ it('declares the main-app favicon assets in docs head tags', () => {
+ const iconLinks =
+ config.head?.filter(
+ (entry) =>
+ entry[0] === 'link' &&
+ typeof entry[1] === 'object' &&
+ entry[1] !== null &&
+ 'rel' in entry[1] &&
+ (entry[1].rel === 'icon' || entry[1].rel === 'shortcut icon'),
+ ) ?? [];
+
+ expect(iconLinks.some((entry) => typeof entry[1] === 'object' && entry[1] !== null && 'href' in entry[1] && entry[1].href === '/favicon.png')).toBe(true);
+ expect(iconLinks.some((entry) => typeof entry[1] === 'object' && entry[1] !== null && 'href' in entry[1] && entry[1].href === '/favicon-64.png')).toBe(true);
+ expect(iconLinks.some((entry) => typeof entry[1] === 'object' && entry[1] !== null && 'href' in entry[1] && entry[1].href === '/favicon.ico')).toBe(true);
+ });
+
+ it('aliases dayjs to the ESM entry for mermaid browser compatibility', () => {
+ const aliasConfig = config.vite?.resolve?.alias;
+ const alias = getAlias(aliasConfig, 'dayjs');
+ const aliasEntry = getAliasEntry(aliasConfig, 'dayjs');
+
+ expect(alias).toBe(getExpectedEntry('node_modules/dayjs/esm/index.js', 'node_modules/.pnpm/dayjs@*/node_modules/dayjs/esm/index.js'));
+ expect(alias && existsSync(alias)).toBe(true);
+ expect(Array.isArray(aliasConfig)).toBe(true);
+ expect(aliasEntry && typeof aliasEntry === 'object' && 'find' in aliasEntry && aliasEntry.find instanceof RegExp).toBe(true);
+ expect(aliasEntry && typeof aliasEntry === 'object' && 'find' in aliasEntry && aliasEntry.find instanceof RegExp && aliasEntry.find.test('dayjs/plugin/duration.js')).toBe(false);
+ });
+
+ it('aliases sanitize-url to a browser-loadable source entry', () => {
+ const alias = getAlias(config.vite?.resolve?.alias, '@braintree/sanitize-url');
+
+ expect(alias).toBe(
+ getExpectedEntry(
+ 'node_modules/@braintree/sanitize-url/src/index.ts',
+ 'node_modules/.pnpm/@braintree+sanitize-url@*/node_modules/@braintree/sanitize-url/src/index.ts',
+ ),
+ );
+ expect(alias && existsSync(alias)).toBe(true);
+ });
+});
diff --git a/docs/.vitepress/config.ts b/docs/.vitepress/config.ts
index e00330f..e79909c 100644
--- a/docs/.vitepress/config.ts
+++ b/docs/.vitepress/config.ts
@@ -1,14 +1,56 @@
+import { existsSync, globSync } from 'node:fs';
+import { resolve } from 'node:path';
+import { fileURLToPath } from 'node:url';
import { defineConfig } from 'vitepress';
import { withMermaid } from 'vitepress-plugin-mermaid';
+const repoRoot = fileURLToPath(new URL('../..', import.meta.url));
+const resolveDependencyEntry = (hoistedRelativePath: string, pnpmPattern: string) => {
+ const hoistedEntry = resolve(repoRoot, hoistedRelativePath);
+ if (existsSync(hoistedEntry)) return hoistedEntry;
+
+ const [pnpmEntry] = globSync(resolve(repoRoot, pnpmPattern));
+ return pnpmEntry;
+};
+
+const dayjsEsmEntry = resolveDependencyEntry(
+ 'node_modules/dayjs/esm/index.js',
+ 'node_modules/.pnpm/dayjs@*/node_modules/dayjs/esm/index.js',
+);
+const sanitizeUrlSourceEntry = resolveDependencyEntry(
+ 'node_modules/@braintree/sanitize-url/src/index.ts',
+ 'node_modules/.pnpm/@braintree+sanitize-url@*/node_modules/@braintree/sanitize-url/src/index.ts',
+);
+
+if (!dayjsEsmEntry) {
+ throw new Error('Unable to resolve the dayjs ESM entry required by vitepress-plugin-mermaid.');
+}
+
+if (!sanitizeUrlSourceEntry) {
+ throw new Error('Unable to resolve the sanitize-url source entry required by vitepress-plugin-mermaid.');
+}
+
export default withMermaid(
defineConfig({
lang: 'zh-CN',
title: 'Metapi 文档',
description: 'Metapi 使用文档、FAQ 与维护协作指南',
+ head: [
+ ['link', { rel: 'icon', type: 'image/png', sizes: '32x32', href: '/favicon.png' }],
+ ['link', { rel: 'icon', type: 'image/png', sizes: '64x64', href: '/favicon-64.png' }],
+ ['link', { rel: 'shortcut icon', href: '/favicon.ico' }],
+ ],
cleanUrls: true,
lastUpdated: true,
ignoreDeadLinks: true,
+ vite: {
+ resolve: {
+ alias: [
+ { find: /^dayjs$/, replacement: dayjsEsmEntry },
+ { find: /^@braintree\/sanitize-url$/, replacement: sanitizeUrlSourceEntry },
+ ],
+ },
+ },
themeConfig: {
siteTitle: 'Metapi Docs',
logo: '/logos/logo-icon-512.png',
diff --git a/docs/client-integration.md b/docs/client-integration.md
index 4e28ba9..ab0efd4 100644
--- a/docs/client-integration.md
+++ b/docs/client-integration.md
@@ -13,10 +13,13 @@ Metapi 暴露标准 OpenAI / Claude 兼容接口,下游客户端通常只需
| 配置项 | 值 |
|--------|-----|
| **Base URL** | 按客户端字段行为填写:会自动补 `/v1` 的字段填 `https://your-domain.com`;要求完整 API URL 的字段填 `https://your-domain.com/v1` |
-| **API Key** | 你设置的 `PROXY_TOKEN` 值,或创建的下游 API Key |
+| **API Key** | 你设置的 `PROXY_TOKEN` 值,或创建的[下游 API Key](./configuration.md#下游-api-key-策略) |
模型列表自动从 `GET /v1/models` 获取,无需手动配置。
+> [!TIP]
+> 如果不确定客户端是否自动补 `/v1`,先试根域名,报 404 再改成带 `/v1` 的完整路径。
+
## 支持的接口
| 接口 | 方法 | 说明 |
@@ -82,9 +85,19 @@ Metapi 暴露标准 OpenAI / Claude 兼容接口,下游客户端通常只需
}
```
-> 说明:`ANTHROPIC_BASE_URL` 这里填根域名,不要手动拼接 `/v1`;不同版本客户端可能读取 `ANTHROPIC_API_KEY` 或 `ANTHROPIC_AUTH_TOKEN`,建议同时设置。
-> 上述变量由 Claude Code 客户端读取,属于客户端行为开关;
-> `metapi` 服务端无法替代客户端自行设置这些变量,只能处理已经发来的请求。
+**环境变量说明:**
+
+| 变量 | 作用 |
+|------|------|
+| `ANTHROPIC_BASE_URL` | 指向 Metapi 的根域名,Claude Code 会自动拼接 `/v1/messages` |
+| `ANTHROPIC_API_KEY` | 认证令牌,填 `PROXY_TOKEN` 值 |
+| `ANTHROPIC_AUTH_TOKEN` | 部分版本读取此变量而非 `ANTHROPIC_API_KEY`,建议两个都设 |
+| `CLAUDE_CODE_ATTRIBUTION_HEADER` | 设为 `0` 禁用 Attribution 头,避免部分上游不支持该头导致报错 |
+| `CLAUDE_CODE_DISABLE_NONESSENTIAL_TRAFFIC` | 设为 `1` 减少非必要请求(遥测等),降低 Token 消耗 |
+
+> [!IMPORTANT]
+> `ANTHROPIC_BASE_URL` 填根域名即可,**不要**手动拼接 `/v1`。
+> 上述变量由 Claude Code 客户端读取,属于客户端行为开关;Metapi 服务端只能处理已经发来的请求。
### Codex CLI
@@ -115,7 +128,17 @@ base_url = "https://your-domain.com/v1"
### 其他客户端
-所有支持 OpenAI API 格式的客户端均可接入,只需找到 Base URL 和 API Key 的配置位置即可:如果客户端会自动补 `/v1`,填根域名;如果字段要求完整 OpenAI API URL,就填 `https://your-domain.com/v1`。
+所有支持 OpenAI API 格式的客户端均可接入,只需找到 Base URL 和 API Key 的配置位置即可:
+
+| 你的客户端... | 填法 |
+|--------------|------|
+| 有 "Base URL" 字段,会自动补 `/v1` | 填 `https://your-domain.com` |
+| 有 "OpenAI API URL" 字段,要求完整路径 | 填 `https://your-domain.com/v1` |
+| 有 "Anthropic" 选项 | 填 `https://your-domain.com`,Metapi 自动处理 `/v1/messages` |
+| 只能填 API Key | 填 `PROXY_TOKEN` 值即可 |
+
+> [!TIP]
+> 不确定选哪种?先用 `/v1/models` 测试连通性,再配置模型。
## 下游 API Key 策略
@@ -188,5 +211,7 @@ curl -sS https://your-domain.com/v1/chat/completions \
## 下一步
-- [配置说明](./configuration.md) — 环境变量详解
+- [配置说明](./configuration.md) — 环境变量详解与下游 API Key 策略
+- [上游接入](./upstream-integration.md) — 添加和管理上游平台
+- [运维手册](./operations.md) — 日志排查与健康检查
- [常见问题](./faq.md) — 更多故障排查
diff --git a/docs/configuration.md b/docs/configuration.md
index 15d2fee..0d52cb1 100644
--- a/docs/configuration.md
+++ b/docs/configuration.md
@@ -87,12 +87,19 @@ Metapi 的路由引擎按多因子加权选择最优通道。
### 路由预设建议
-| 场景 | COST_WEIGHT | BALANCE_WEIGHT | USAGE_WEIGHT |
-|------|:-----------:|:--------------:|:------------:|
-| **成本优先** | 0.7 | 0.2 | 0.1 |
-| **均衡(默认)** | 0.4 | 0.3 | 0.3 |
-| **稳定优先** | 0.2 | 0.5 | 0.3 |
-| **轮转均匀** | 0.1 | 0.1 | 0.8 |
+| 场景 | COST_WEIGHT | BALANCE_WEIGHT | USAGE_WEIGHT | 说明 |
+|------|:-----------:|:--------------:|:------------:|------|
+| **成本优先** | 0.7 | 0.2 | 0.1 | 适合预算敏感场景,总是选最便宜的通道 |
+| **均衡(默认)** | 0.4 | 0.3 | 0.3 | 兼顾成本、余额和负载均衡,推荐大多数用户 |
+| **稳定优先** | 0.2 | 0.5 | 0.3 | 适合生产环境,优先选余额充足的通道避免中断 |
+| **轮转均匀** | 0.1 | 0.1 | 0.8 | 适合测试场景,尽量让每个通道都被使用到 |
+
+**调参建议:**
+
+- 如果某个站点总是被选中导致余额很快耗尽 → 调高 `BALANCE_WEIGHT`
+- 如果你有几个很便宜的站点想优先用 → 调高 `COST_WEIGHT`
+- 如果你想让请求均匀分散到所有站点 → 调高 `USAGE_WEIGHT`
+- 如果你需要对特定项目偏好某个站点 → 使用[下游 API Key 的 `siteWeightMultipliers`](#下游-api-key-策略) 而非调全局权重
## 代理日志保留
@@ -209,3 +216,5 @@ Metapi 的路由引擎按多因子加权选择最优通道。
- [部署指南](./deployment.md) — Docker Compose 与反向代理
- [客户端接入](./client-integration.md) — 对接下游应用
+- [上游接入](./upstream-integration.md) — 添加和管理上游平台
+- [运维手册](./operations.md) — 备份、日志与健康检查
diff --git a/docs/getting-started.md b/docs/getting-started.md
index 09f02fd..f521a62 100644
--- a/docs/getting-started.md
+++ b/docs/getting-started.md
@@ -87,6 +87,11 @@ docker compose up -d
> - Windows 下常见路径是 `%APPDATA%\Metapi\data` 和 `%APPDATA%\Metapi\logs`。
> - 如果你要把本机其他客户端接到桌面版内置后端,先到日志里查当前端口,不要写死 `4000`。
+> [!WARNING]
+> **端口冲突排障:** 如果桌面版启动后报端口被占用,可能是 `4310..4399` 范围内的端口全被其他应用占用了。
+> - 设置环境变量 `METAPI_DESKTOP_SERVER_PORT=<指定端口>` 固定到一个空闲端口
+> - 或关闭占用这些端口的应用后重启 Metapi Desktop
+
> [!NOTE]
> 服务器部署统一推荐 Docker / Docker Compose,不再提供裸 Node.js 的 Release 压缩包。
@@ -127,15 +132,9 @@ npm run dev
### 步骤 2:添加账号
-首先前往你想添加的公益站,进入下图界面:
-
-
-
进入 **账号管理**,为每个站点添加已注册的账号:
-
-
-
+
- 填入用户名和访问凭证
@@ -143,7 +142,7 @@ npm run dev
- 系统会自动登录并获取余额信息
-
+ 
- 启用自动签到(如站点支持)
@@ -163,6 +162,10 @@ npm run dev
- 系统会自动发现模型并生成路由规则
- 可以手动调整通道的优先级和权重
+- 关于路由权重参数调优,参考 [配置说明 → 智能路由](./configuration.md#智能路由)
+
+
+
### 步骤 5:验证代理
diff --git a/docs/operations.md b/docs/operations.md
index 4b0ce06..e2df8a0 100644
--- a/docs/operations.md
+++ b/docs/operations.md
@@ -30,12 +30,35 @@ cp -r data/ data-backup-$(date +%Y%m%d)/
### 方式二:数据库原生备份(MySQL / PostgreSQL)
-如果当前运行库已经切到 MySQL / Postgres,请使用数据库自己的备份工具或云快照,例如 `mysqldump`、`pg_dump`、RDS 快照等。
+如果当前运行库已经切到 MySQL / Postgres,请使用数据库自己的备份工具或云快照。
+
+**MySQL 备份示例:**
+
+```bash
+# 全量导出(替换为你的实际连接信息)
+mysqldump -h -u -p metapi > metapi-backup-$(date +%Y%m%d).sql
+
+# 自动备份(crontab,每天凌晨 3 点)
+0 3 * * * mysqldump -h -u -p metapi | gzip > /path/to/backups/metapi-$(date +\%Y\%m\%d).sql.gz
+```
+
+**PostgreSQL 备份示例:**
+
+```bash
+# 全量导出
+pg_dump -h -U -d metapi -F c -f metapi-backup-$(date +%Y%m%d).dump
+
+# 自动备份(crontab,每天凌晨 3 点,使用 .pgpass 免交互密码)
+0 3 * * * pg_dump -h -U -d metapi -F c -f /path/to/backups/metapi-$(date +\%Y\%m\%d).dump
+```
+
+**云托管数据库:** RDS、PlanetScale、Neon 等可直接使用平台的自动快照功能。
建议:
- 升级、迁移、执行「重新初始化系统」前先做一次库级备份
- 备份对象是当前 metapi 正在使用的运行库,而不只是本地 `data/`
- 恢复后重启 Metapi 一次,确认它重新连接到了正确的运行库
+- 建议保留最近 7~30 天的备份,定期清理过期文件
### 方式三:应用内导出
@@ -104,11 +127,16 @@ npm run dev
| 关键词 | 含义 | 处理方式 |
|--------|------|----------|
-| `auth failed` | 上游站点鉴权失败 | 检查账号凭证是否过期 |
-| `no available channel` | 路由无可用通道 | 检查 Token 是否同步、通道是否被冷却 |
-| `notify failed` | 通知发送失败 | 检查通知渠道配置 |
+| `auth failed` | 上游站点鉴权失败 | 检查账号凭证是否过期,系统会自动尝试重登录 |
+| `no available channel` | 路由无可用通道 | 检查 Token 是否同步、通道是否被冷却;可在路由页查看冷却状态 |
+| `channel cooling` | 通道进入冷却期 | 通道在请求失败后自动冷却 10 分钟,期间不会被路由选中;无需干预,会自动恢复 |
+| `upstream 429` | 上游限流 | 该上游站点触发了速率限制;路由引擎会自动切换其他通道,冷却期后重试 |
+| `upstream 5xx` | 上游服务器错误 | 上游站点临时不可用,路由引擎会自动故障转移到其他通道 |
+| `notify failed` | 通知发送失败 | 检查 [通知渠道配置](./configuration.md#通知渠道) |
| `checkin failed` | 签到失败 | 检查账号状态和站点连通性 |
-| `balance refresh failed` | 余额刷新失败 | 检查账号凭证 |
+| `balance refresh failed` | 余额刷新失败 | 检查账号凭证,可能需要重新登录 |
+| `proxy timeout` | 代理请求超时 | 上游响应过慢;检查网络延迟或考虑切换其他通道 |
+| `token expired` | Token 过期 | 系统会自动尝试续签;若反复出现,手动刷新 Token |
## 健康检查
@@ -168,9 +196,14 @@ curl -sS http://localhost:4000/v1/chat/completions \
### 清理缓存并重建路由
-- 「设置 → 清除缓存并重建路由」会清空模型发现缓存、自动路由和自动通道,再后台触发一次模型刷新与路由重建
-- 「TokenRoutes → 重建路由」适合在调整账号、Token、路由规则后手动重新生成自动路由
-- 如果 `GET /v1/models`、路由列表或选择概率明显滞后,优先执行这一操作
+当模型列表(`GET /v1/models`)、路由列表或选择概率明显滞后时,使用以下操作:
+
+| 操作 | 位置 | 适用场景 |
+|------|------|----------|
+| **清除缓存并重建路由** | 设置 → 清除缓存并重建路由 | 全局刷新:清空模型发现缓存、自动路由和自动通道,后台触发模型刷新与路由重建 |
+| **重建路由** | TokenRoutes → 重建路由 | 局部刷新:调整账号、Token、路由规则后手动重新生成自动路由 |
+
+优先使用「重建路由」做局部刷新,问题持续时再用全局清除。
### 批量操作
@@ -206,3 +239,5 @@ curl -sS http://localhost:4000/v1/chat/completions \
- [常见问题](./faq.md) — 常见报错与修复
- [配置说明](./configuration.md) — 环境变量详解
+- [上游接入](./upstream-integration.md) — 平台特定的连接与排障
+- [客户端接入](./client-integration.md) — 下游客户端对接
diff --git a/docs/public/favicon-64.png b/docs/public/favicon-64.png
new file mode 100644
index 0000000..85eb059
Binary files /dev/null and b/docs/public/favicon-64.png differ
diff --git a/docs/public/favicon.ico b/docs/public/favicon.ico
new file mode 100644
index 0000000..85eb059
Binary files /dev/null and b/docs/public/favicon.ico differ
diff --git a/docs/public/favicon.png b/docs/public/favicon.png
new file mode 100644
index 0000000..101e6f3
Binary files /dev/null and b/docs/public/favicon.png differ
diff --git a/docs/upstream-integration.md b/docs/upstream-integration.md
index e69de29..80cf434 100644
--- a/docs/upstream-integration.md
+++ b/docs/upstream-integration.md
@@ -0,0 +1,487 @@
+# 🔌 上游接入指南
+
+本文档详细说明如何将不同类型的 AI 中转站接入 Metapi。
+
+[返回文档中心](./README.md)
+
+---
+
+## 概述
+
+Metapi 支持两大类上游站点:
+
+1. **中转聚合平台** — New API / One API / OneHub / DoneHub / Veloera / AnyRouter / Sub2API 等
+2. **官方 API 端点** — OpenAI / Claude (Anthropic) / Gemini (Google) 直连
+
+每种站点类型的接入方式略有不同,本文档按站点类型分别说明。
+
+---
+
+## 🎯 快速接入流程
+
+### 通用步骤
+
+1. **登录管理后台** — 访问 `http://your-metapi-host:4000`,使用 `AUTH_TOKEN` 登录
+2. **进入站点管理** — 点击左侧菜单「站点管理」
+3. **添加站点** — 点击「添加站点」按钮
+4. **填写站点信息** — 根据站点类型填写对应字段(见下文详细说明)
+5. **添加账号** — 站点创建后,在站点详情页添加账号凭证
+6. **验证连接** — 系统自动验证账号可用性并获取模型列表
+
+---
+
+## 📦 中转聚合平台接入
+
+### New API
+
+**适用平台:** New API 及其衍生版本(Wong-Gongyi、VO-API、Super-API、RIX-API、Neo-API 等)
+
+#### 站点配置
+
+| 字段 | 说明 | 示例 |
+|------|------|------|
+| **站点名称** | 自定义名称,便于识别 | `我的 New API` |
+| **站点 URL** | New API 部署地址(**不含** `/v1` 后缀) | `https://api.example.com` |
+| **平台类型** | 选择 `new-api` | - |
+| **代理 URL** | (可选)该站点专用代理地址 | `http://proxy.example.com:7890` |
+| **使用系统代理** | 是否使用全局 `SYSTEM_PROXY_URL` | 默认关闭 |
+
+#### 账号凭证类型
+
+New API 支持三种凭证类型:
+
+##### 1. 用户名密码登录
+
+- **适用场景:** 有完整账号权限,需要自动签到、余额查询、Token 管理
+- **填写方式:**
+ - 用户名:`your-username`
+ - 密码:`your-password`
+- **自动获取:** 系统自动登录并获取 Access Token 和 API Token
+
+##### 2. Access Token / Session Cookie
+
+- **适用场景:** 已有登录凭证,无需密码
+- **填写方式:**
+ - 在「Access Token」字段填入以下任一格式:
+ - JWT Token:`eyJhbGciOiJIUzI1NiIsInR5cCI6IkpXVCJ9...`
+ - Session Cookie:`session=MTczNjQxMjM0NXxEdi1CQUFFQ180SUFBUkFCRUFBQVB2LUNBQUVHYzNSeWFXNW5EQThBRFhObGMzTnBiMjVmZEdGaWJHVUdjM1J5YVc1bkRBSUFBQT09fGRlYWRiZWVmMTIzNDU2Nzg5MGFiY2RlZjEyMzQ1Njc4OTBhYmNkZWY=`
+ - Cookie 字符串:`session=xxx; token=yyy`
+- **自动解析:** 系统自动识别凭证类型并提取用户信息
+
+##### 3. API Token(仅代理)
+
+- **适用场景:** 仅用于模型调用,不需要管理功能
+- **填写方式:**
+ - 在「API Token」字段填入:`sk-xxxxxxxxxxxxxx`
+- **限制:** 无法使用签到、余额刷新、Token 管理等功能
+
+#### 特殊说明
+
+**User ID 自动探测:** New API 的某些衍生版本(如 Wong-Gongyi、VO-API)需要在请求头中携带 `New-API-User` / `Veloera-User` / `voapi-user` 等字段。Metapi 会自动:
+1. 从 JWT Token 中解码 User ID
+2. 从 Session Cookie 中提取 User ID(支持 Gob 编码解析)
+3. 通过探测常见 ID 范围验证可用性
+
+**防护盾穿透:** 自动处理阿里云盾 / Cloudflare 等 JS 挑战(`acw_sc__v2` / `cdn_sec_tc`),无需手动配置。
+
+---
+
+### One API
+
+**适用平台:** One API 原版及兼容分支
+
+#### 站点配置
+
+| 字段 | 说明 | 示例 |
+|------|------|------|
+| **站点名称** | 自定义名称 | `One API 主站` |
+| **站点 URL** | One API 部署地址 | `https://oneapi.example.com` |
+| **平台类型** | 选择 `one-api` | - |
+
+#### 账号凭证
+
+One API 支持与 New API 相同的三种凭证类型(用户名密码 / Access Token / API Token),配置方式相同。
+
+---
+
+### OneHub
+
+**适用平台:** OneHub(One API 增强分支)
+
+#### 站点配置
+
+| 字段 | 说明 | 示例 |
+|------|------|------|
+| **站点名称** | 自定义名称 | `OneHub 站点` |
+| **站点 URL** | OneHub 部署地址 | `https://onehub.example.com` |
+| **平台类型** | 选择 `one-hub` | - |
+
+#### 账号凭证
+
+OneHub 继承 One API 的凭证体系,支持用户名密码、Access Token、API Token 三种方式。
+
+**额外功能:** OneHub 支持 Token 分组(`token_group`),Metapi 会自动识别并保留分组信息。
+
+---
+
+### DoneHub
+
+**适用平台:** DoneHub(OneHub 增强分支)
+
+#### 站点配置
+
+| 字段 | 说明 | 示例 |
+|------|------|------|
+| **站点名称** | 自定义名称 | `DoneHub 站点` |
+| **站点 URL** | DoneHub 部署地址 | `https://donehub.example.com` |
+| **平台类型** | 选择 `done-hub` | - |
+
+#### 账号凭证
+
+DoneHub 完全兼容 OneHub 的凭证体系,配置方式相同。
+
+---
+
+### Veloera
+
+**适用平台:** Veloera API 网关
+
+#### 站点配置
+
+| 字段 | 说明 | 示例 |
+|------|------|------|
+| **站点名称** | 自定义名称 | `Veloera 网关` |
+| **站点 URL** | Veloera 部署地址 | `https://veloera.example.com` |
+| **平台类型** | 选择 `veloera` | - |
+
+#### 账号凭证
+
+Veloera 基于 New API 架构,支持相同的凭证类型。特别注意:
+- Veloera 需要 `Veloera-User` 请求头,Metapi 会自动添加
+- 支持 Session Cookie 和 JWT Token
+
+---
+
+### AnyRouter
+
+**适用平台:** AnyRouter 通用路由平台
+
+#### 站点配置
+
+| 字段 | 说明 | 示例 |
+|------|------|------|
+| **站点名称** | 自定义名称 | `AnyRouter 平台` |
+| **站点 URL** | AnyRouter 部署地址 | `https://anyrouter.example.com` |
+| **平台类型** | 选择 `anyrouter` | - |
+
+#### 账号凭证
+
+AnyRouter 基于 New API 架构,凭证配置方式相同。
+
+---
+
+### Sub2API
+
+**适用平台:** Sub2API 订阅制中转平台
+
+#### 站点配置
+
+| 字段 | 说明 | 示例 |
+|------|------|------|
+| **站点名称** | 自定义名称 | `Sub2API 订阅站` |
+| **站点 URL** | Sub2API 部署地址 | `https://sub2api.example.com` |
+| **平台类型** | 选择 `sub2api` | - |
+
+#### 账号凭证
+
+Sub2API 支持:
+- **用户名密码登录**
+- **Access Token**
+- **API Token**(订阅密钥)
+
+配置方式与 New API 相同。
+
+---
+
+## 🌐 官方 API 端点接入
+
+### OpenAI
+
+**适用场景:** 直连 OpenAI 官方 API 或 OpenAI 兼容端点
+
+#### 站点配置
+
+| 字段 | 说明 | 示例 |
+|------|------|------|
+| **站点名称** | 自定义名称 | `OpenAI 官方` |
+| **站点 URL** | OpenAI API 端点(**不含** `/v1` 后缀) | `https://api.openai.com` |
+| **平台类型** | 选择 `openai` | - |
+| **代理 URL** | (推荐)配置代理以访问 OpenAI | `http://proxy.example.com:7890` |
+
+#### 账号凭证
+
+**仅支持 API Key:**
+- 在「API Token」字段填入:`sk-proj-xxxxxxxxxxxxxx`
+- 不支持用户名密码登录(OpenAI 无此接口)
+
+#### 功能限制
+
+| 功能 | 支持情况 |
+|------|----------|
+| 模型列表获取 | ✅ 支持(`/v1/models`) |
+| 代理调用 | ✅ 支持 |
+| 余额查询 | ❌ 不支持(OpenAI 无公开接口) |
+| 自动签到 | ❌ 不适用 |
+| Token 管理 | ❌ 不适用 |
+
+---
+
+### Claude (Anthropic)
+
+**适用场景:** 直连 Anthropic Claude API
+
+#### 站点配置
+
+| 字段 | 说明 | 示例 |
+|------|------|------|
+| **站点名称** | 自定义名称 | `Claude 官方` |
+| **站点 URL** | Anthropic API 端点 | `https://api.anthropic.com` |
+| **平台类型** | 选择 `claude` | - |
+
+#### 账号凭证
+
+**仅支持 API Key:**
+- 在「API Token」字段填入:`sk-ant-api03-xxxxxxxxxxxxxx`
+
+#### 功能限制
+
+| 功能 | 支持情况 |
+|------|----------|
+| 模型列表获取 | ✅ 支持(内置模型目录) |
+| 代理调用 | ✅ 支持(自动转换 OpenAI ⇄ Claude 格式) |
+| 余额查询 | ❌ 不支持 |
+| 自动签到 | ❌ 不适用 |
+| Token 管理 | ❌ 不适用 |
+
+**协议转换:** Metapi 自动处理 OpenAI 格式与 Claude Messages API 格式的双向转换,下游客户端可使用 OpenAI SDK 调用 Claude 模型。
+
+---
+
+### Gemini (Google)
+
+**适用场景:** 直连 Google Gemini API
+
+#### 站点配置
+
+| 字段 | 说明 | 示例 |
+|------|------|------|
+| **站点名称** | 自定义名称 | `Gemini 官方` |
+| **站点 URL** | Gemini API 端点 | `https://generativelanguage.googleapis.com` |
+| **平台类型** | 选择 `gemini` | - |
+
+#### 账号凭证
+
+**仅支持 API Key:**
+- 在「API Token」字段填入:`AIzaSyxxxxxxxxxxxxxx`
+
+#### 功能限制
+
+| 功能 | 支持情况 |
+|------|----------|
+| 模型列表获取 | ✅ 支持(`/v1beta/models`) |
+| 代理调用 | ✅ 支持(自动转换 OpenAI ⇄ Gemini 格式) |
+| 余额查询 | ❌ 不支持 |
+| 自动签到 | ❌ 不适用 |
+| Token 管理 | ❌ 不适用 |
+
+**协议转换:** Metapi 自动处理 OpenAI 格式与 Gemini `generateContent` API 格式的双向转换。
+
+---
+
+## 🔧 高级配置
+
+### 站点级代理
+
+每个站点可单独配置代理,优先级高于全局 `SYSTEM_PROXY_URL`:
+
+```
+站点专用代理 > 全局系统代理 > 直连
+```
+
+**配置方式:**
+1. 在站点编辑页面填写「代理 URL」字段
+2. 格式:`http://proxy-host:port` 或 `socks5://proxy-host:port`
+3. 支持 HTTP / HTTPS / SOCKS5 代理
+
+### 站点权重
+
+**全局权重(`global_weight`):** 影响该站点下所有通道的路由概率。
+
+- 默认值:`1.0`
+- 范围:`0.1` ~ `10.0`
+- 示例:
+ - 设置为 `2.0` — 该站点通道被选中的概率翻倍
+ - 设置为 `0.5` — 该站点通道被选中的概率减半
+
+**配置位置:** 站点编辑页面 → 高级设置 → 全局权重
+
+### 外部签到 URL
+
+**适用场景:** 某些站点的签到接口非标准路径,或需要通过外部服务触发签到。
+
+**配置方式:**
+1. 在站点编辑页面填写「外部签到 URL」
+2. Metapi 会向该 URL 发送 POST 请求执行签到
+3. 请求头自动携带账号凭证
+
+---
+
+## 🔍 站点自动检测
+
+Metapi 支持自动识别站点类型,检测优先级如下:
+
+### 1. URL 特征检测
+
+根据 URL 中的关键字自动识别:
+
+| URL 特征 | 识别为 |
+|----------|--------|
+| `api.openai.com` | OpenAI |
+| `api.anthropic.com` | Claude |
+| `generativelanguage.googleapis.com` | Gemini |
+| `anyrouter` | AnyRouter |
+| `donehub` / `done-hub` | DoneHub |
+| `onehub` / `one-hub` | OneHub |
+| `veloera` | Veloera |
+| `sub2api` | Sub2API |
+
+### 2. 页面标题检测
+
+访问站点首页,解析 `` 标签识别平台类型。
+
+### 3. API 探测
+
+依次尝试各平台的特征接口:
+- New API:`/api/status` 返回 `system_name`
+- One API:`/api/status` 返回特定结构
+- OpenAI:`/v1/models` 返回模型列表
+
+**手动指定:** 如果自动检测失败,可在添加站点时手动选择平台类型。
+
+---
+
+## 📊 账号健康状态
+
+Metapi 自动追踪每个账号的健康状态:
+
+| 状态 | 说明 | 触发条件 |
+|------|------|----------|
+| `healthy` | 健康 | 最近请求成功,余额充足 |
+| `degraded` | 降级 | 部分模型不可用,或余额不足 |
+| `unhealthy` | 不健康 | 连续失败,或凭证过期 |
+| `disabled` | 已禁用 | 手动禁用或站点禁用 |
+
+**自动恢复:** `unhealthy` 状态的账号会定期重试,成功后自动恢复为 `healthy`。
+
+---
+
+## 🛠️ 故障排查
+
+### 问题:添加站点后无法获取模型列表
+
+**可能原因:**
+1. 站点 URL 填写错误(检查是否包含 `/v1` 后缀,应去除)
+2. 网络不通(检查代理配置或防火墙)
+3. 凭证无效(重新验证账号密码或 Token)
+
+**解决方法:**
+- 在站点详情页点击「测试连接」
+- 查看「事件日志」中的错误信息
+- 检查「代理日志」中的请求详情
+
+### 问题:New API 账号提示「需要 New-API-User 头」
+
+**原因:** 该站点是 New API 衍生版本,需要 User ID。
+
+**解决方法:**
+1. Metapi 会自动探测 User ID,通常无需手动配置
+2. 如果自动探测失败,可在账号编辑页面的「额外配置」中手动填写:
+ ```json
+ {
+ "platformUserId": 12345
+ }
+ ```
+
+### 问题:签到失败
+
+**可能原因:**
+1. 凭证过期(Access Token 有效期到期)
+2. 站点签到接口变更
+3. 已经签到过(部分站点限制每日一次)
+
+**解决方法:**
+- 查看「签到记录」中的失败原因
+- 尝试重新登录获取新凭证
+- 配置「外部签到 URL」使用备用签到方式
+
+### 问题:余额显示不准确
+
+**原因:** 不同平台的余额单位不同。
+
+**说明:**
+- New API 系列:余额单位为「美元」,内部存储为 `quota / 500000`
+- OpenAI / Claude / Gemini:官方 API 无余额查询接口,显示为 `N/A`
+
+---
+
+## 📝 最佳实践
+
+### 1. 凭证选择建议
+
+| 场景 | 推荐凭证类型 | 原因 |
+|------|-------------|------|
+| 个人站点,需要完整功能 | 用户名密码 | 支持自动签到、Token 管理 |
+| 共享账号,只读权限 | Access Token | 避免密码泄露 |
+| 仅用于模型调用 | API Token | 最小权限原则 |
+
+### 2. 站点命名规范
+
+建议使用清晰的命名规则,便于管理:
+
+```
+[平台类型] - [站点特征] - [用途]
+```
+
+示例:
+- `New API - 主站 - 生产环境`
+- `OneHub - 备用 - 测试`
+- `OpenAI - 官方 - 高优先级`
+
+### 3. 代理配置策略
+
+- **国内访问 OpenAI / Claude / Gemini:** 必须配置代理
+- **国内中转站:** 通常不需要代理
+- **海外中转站:** 根据网络情况选择
+
+### 4. 定期维护
+
+- **每周检查:** 账号健康状态、余额预警
+- **每月清理:** 禁用长期不可用的站点和账号
+- **凭证轮换:** 定期更新 Access Token 和 API Key
+
+---
+
+## 🔗 相关文档
+
+- [配置说明](./configuration.md) — 环境变量与路由参数
+- [客户端接入](./client-integration.md) — 下游应用配置
+- [常见问题](./faq.md) — 故障排查与优化建议
+
+---
+
+## 💡 提示
+
+- 添加站点后,系统会自动发现可用模型并生成路由表,无需手动配置
+- 支持同时接入多个相同类型的站点(如多个 New API 实例)
+- 站点禁用后,关联的所有账号和路由通道会自动禁用
+- 删除站点会级联删除所有关联账号、Token 和路由配置,请谨慎操作
diff --git a/src/server/routes/proxy/architecture-boundaries.test.ts b/src/server/routes/proxy/architecture-boundaries.test.ts
index 547b868..fe51847 100644
--- a/src/server/routes/proxy/architecture-boundaries.test.ts
+++ b/src/server/routes/proxy/architecture-boundaries.test.ts
@@ -114,6 +114,7 @@ describe('proxy route architecture boundaries', () => {
expect(source).not.toContain('const consumeSseBuffer = (incoming: string): string => {');
expect(source).not.toContain('openAiResponsesTransformer.aggregator.complete(');
expect(source).not.toContain('reply.raw.end();');
+ expect(source).toContain('reply.hijack();');
expect(source).toContain('openAiResponsesTransformer.proxyStream.createSession(');
});
});
diff --git a/src/server/routes/proxy/responses.compact-upstream.test.ts b/src/server/routes/proxy/responses.compact-upstream.test.ts
index 9c6c244..4193f7d 100644
--- a/src/server/routes/proxy/responses.compact-upstream.test.ts
+++ b/src/server/routes/proxy/responses.compact-upstream.test.ts
@@ -137,4 +137,49 @@ describe('responses proxy compact upstream routing', () => {
const [targetUrl] = fetchMock.mock.calls[0] as [string, any];
expect(targetUrl).toContain('/v1/responses/compact');
});
+
+ it('preserves native response.compaction payloads instead of coercing them into object=response', async () => {
+ fetchMock.mockResolvedValue(new Response(JSON.stringify({
+ id: 'cmp_123',
+ object: 'response.compaction',
+ input_tokens: 1234,
+ output_tokens: 321,
+ total_tokens: 1555,
+ output: [
+ {
+ id: 'rs_123',
+ type: 'compaction',
+ encrypted_content: 'enc-compact-payload',
+ },
+ ],
+ }), {
+ status: 200,
+ headers: { 'content-type': 'application/json' },
+ }));
+
+ const response = await app.inject({
+ method: 'POST',
+ url: '/v1/responses/compact',
+ payload: {
+ model: 'gpt-5.2',
+ input: 'hello',
+ },
+ });
+
+ expect(response.statusCode).toBe(200);
+ expect(response.json()).toEqual({
+ id: 'cmp_123',
+ object: 'response.compaction',
+ input_tokens: 1234,
+ output_tokens: 321,
+ total_tokens: 1555,
+ output: [
+ {
+ id: 'rs_123',
+ type: 'compaction',
+ encrypted_content: 'enc-compact-payload',
+ },
+ ],
+ });
+ });
});
diff --git a/src/server/routes/proxy/responses.compact.test.ts b/src/server/routes/proxy/responses.compact.test.ts
index 0927df2..c5a1cfa 100644
--- a/src/server/routes/proxy/responses.compact.test.ts
+++ b/src/server/routes/proxy/responses.compact.test.ts
@@ -29,4 +29,24 @@ describe('responses proxy compact route', () => {
},
});
});
+
+ it('rejects streaming /v1/responses/compact requests because compact is non-streaming', async () => {
+ const response = await app.inject({
+ method: 'POST',
+ url: '/v1/responses/compact',
+ payload: {
+ model: 'gpt-5.2',
+ input: 'hello',
+ stream: true,
+ },
+ });
+
+ expect(response.statusCode).toBe(400);
+ expect(response.json()).toEqual({
+ error: {
+ message: 'stream is not supported on /v1/responses/compact',
+ type: 'invalid_request_error',
+ },
+ });
+ });
});
diff --git a/src/server/transformers/openai/responses/aggregator.test.ts b/src/server/transformers/openai/responses/aggregator.test.ts
index b8ba0b9..36266ed 100644
--- a/src/server/transformers/openai/responses/aggregator.test.ts
+++ b/src/server/transformers/openai/responses/aggregator.test.ts
@@ -502,4 +502,265 @@ describe('serializeConvertedResponsesEvents', () => {
},
});
});
+
+ it('does not synthesize duplicate message done events after original text completion already arrived', () => {
+ const state = createOpenAiResponsesAggregateState('gpt-5');
+ const streamContext = createStreamTransformContext('gpt-5');
+ const usage = {
+ promptTokens: 2,
+ completionTokens: 4,
+ totalTokens: 6,
+ };
+
+ serializeConvertedResponsesEvents({
+ state,
+ streamContext,
+ usage,
+ event: {
+ responsesEventType: 'response.output_item.added',
+ responsesPayload: {
+ type: 'response.output_item.added',
+ output_index: 0,
+ item: {
+ id: 'msg_1',
+ type: 'message',
+ role: 'assistant',
+ status: 'in_progress',
+ content: [],
+ },
+ },
+ },
+ });
+
+ serializeConvertedResponsesEvents({
+ state,
+ streamContext,
+ usage,
+ event: {
+ responsesEventType: 'response.content_part.added',
+ responsesPayload: {
+ type: 'response.content_part.added',
+ output_index: 0,
+ item_id: 'msg_1',
+ content_index: 0,
+ part: {
+ type: 'output_text',
+ text: '',
+ },
+ },
+ },
+ });
+
+ serializeConvertedResponsesEvents({
+ state,
+ streamContext,
+ usage,
+ event: {
+ responsesEventType: 'response.output_text.delta',
+ responsesPayload: {
+ type: 'response.output_text.delta',
+ output_index: 0,
+ item_id: 'msg_1',
+ delta: 'hello ',
+ },
+ },
+ });
+
+ serializeConvertedResponsesEvents({
+ state,
+ streamContext,
+ usage,
+ event: {
+ responsesEventType: 'response.output_text.done',
+ responsesPayload: {
+ type: 'response.output_text.done',
+ output_index: 0,
+ item_id: 'msg_1',
+ text: 'hello world',
+ },
+ },
+ });
+
+ serializeConvertedResponsesEvents({
+ state,
+ streamContext,
+ usage,
+ event: {
+ responsesEventType: 'response.content_part.done',
+ responsesPayload: {
+ type: 'response.content_part.done',
+ output_index: 0,
+ item_id: 'msg_1',
+ content_index: 0,
+ part: {
+ type: 'output_text',
+ text: 'hello world',
+ },
+ },
+ },
+ });
+
+ const completionLines = completeResponsesStream(state, streamContext, usage);
+ const events = parseSseEvents(completionLines);
+
+ expect(events.map((entry) => entry.event ?? (entry.payload === '[DONE]' ? '[DONE]' : 'data'))).toEqual([
+ 'response.output_item.done',
+ 'response.completed',
+ '[DONE]',
+ ]);
+
+ expect(events[0]?.payload).toMatchObject({
+ type: 'response.output_item.done',
+ output_index: 0,
+ item: {
+ id: 'msg_1',
+ type: 'message',
+ status: 'completed',
+ },
+ });
+ expect(events[1]?.payload).toMatchObject({
+ type: 'response.completed',
+ response: {
+ status: 'completed',
+ output_text: 'hello world',
+ },
+ });
+ });
+
+ it('does not synthesize duplicate reasoning done events after original reasoning completion already arrived', () => {
+ const state = createOpenAiResponsesAggregateState('gpt-5');
+ const streamContext = createStreamTransformContext('gpt-5');
+ const usage = {
+ promptTokens: 2,
+ completionTokens: 4,
+ totalTokens: 6,
+ };
+
+ serializeConvertedResponsesEvents({
+ state,
+ streamContext,
+ usage,
+ event: {
+ responsesEventType: 'response.output_item.added',
+ responsesPayload: {
+ type: 'response.output_item.added',
+ output_index: 0,
+ item: {
+ id: 'rs_1',
+ type: 'reasoning',
+ status: 'in_progress',
+ summary: [],
+ },
+ },
+ },
+ });
+
+ serializeConvertedResponsesEvents({
+ state,
+ streamContext,
+ usage,
+ event: {
+ responsesEventType: 'response.reasoning_summary_part.added',
+ responsesPayload: {
+ type: 'response.reasoning_summary_part.added',
+ item_id: 'rs_1',
+ output_index: 0,
+ summary_index: 0,
+ part: {
+ type: 'summary_text',
+ text: '',
+ },
+ },
+ },
+ });
+
+ serializeConvertedResponsesEvents({
+ state,
+ streamContext,
+ usage,
+ event: {
+ responsesEventType: 'response.reasoning_summary_text.delta',
+ responsesPayload: {
+ type: 'response.reasoning_summary_text.delta',
+ item_id: 'rs_1',
+ output_index: 0,
+ summary_index: 0,
+ delta: 'plan ',
+ },
+ },
+ });
+
+ serializeConvertedResponsesEvents({
+ state,
+ streamContext,
+ usage,
+ event: {
+ responsesEventType: 'response.reasoning_summary_text.done',
+ responsesPayload: {
+ type: 'response.reasoning_summary_text.done',
+ item_id: 'rs_1',
+ output_index: 0,
+ summary_index: 0,
+ text: 'plan first',
+ },
+ },
+ });
+
+ serializeConvertedResponsesEvents({
+ state,
+ streamContext,
+ usage,
+ event: {
+ responsesEventType: 'response.reasoning_summary_part.done',
+ responsesPayload: {
+ type: 'response.reasoning_summary_part.done',
+ item_id: 'rs_1',
+ output_index: 0,
+ summary_index: 0,
+ part: {
+ type: 'summary_text',
+ text: 'plan first',
+ },
+ },
+ },
+ });
+
+ const completionLines = completeResponsesStream(state, streamContext, usage);
+ const events = parseSseEvents(completionLines);
+
+ expect(events.map((entry) => entry.event ?? (entry.payload === '[DONE]' ? '[DONE]' : 'data'))).toEqual([
+ 'response.output_item.done',
+ 'response.completed',
+ '[DONE]',
+ ]);
+
+ expect(events[0]?.payload).toMatchObject({
+ type: 'response.output_item.done',
+ output_index: 0,
+ item: {
+ id: 'rs_1',
+ type: 'reasoning',
+ status: 'completed',
+ },
+ });
+ expect(events[1]?.payload).toMatchObject({
+ type: 'response.completed',
+ response: {
+ status: 'completed',
+ output: [
+ {
+ id: 'rs_1',
+ type: 'reasoning',
+ status: 'completed',
+ summary: [
+ {
+ type: 'summary_text',
+ text: 'plan first',
+ },
+ ],
+ },
+ ],
+ },
+ });
+ });
});
diff --git a/src/server/transformers/openai/responses/aggregator.ts b/src/server/transformers/openai/responses/aggregator.ts
index 0ef3e87..701ad6b 100644
--- a/src/server/transformers/openai/responses/aggregator.ts
+++ b/src/server/transformers/openai/responses/aggregator.ts
@@ -55,6 +55,12 @@ type ResponsesUsageSummary = {
};
type AggregateOutputItem = Record<string, unknown>;
+type AggregateOutputMetaCarrier = AggregateOutputItem & { [key: symbol]: true | undefined };
+
+const outputTextDoneMarker = Symbol('responses.output_text.done');
+const contentPartDoneMarker = Symbol('responses.content_part.done');
+const reasoningSummaryTextDoneMarker = Symbol('responses.reasoning_summary_text.done');
+const reasoningSummaryPartDoneMarker = Symbol('responses.reasoning_summary_part.done');
export type OpenAiResponsesAggregateState = {
modelName: string;
@@ -90,6 +96,14 @@ export function createOpenAiResponsesAggregateState(modelName: string): OpenAiRe
};
}
+function markTerminalMarker(item: AggregateOutputItem, marker: symbol): void {
+ (item as AggregateOutputMetaCarrier)[marker] = true;
+}
+
+function hasTerminalMarker(item: AggregateOutputItem, marker: symbol): boolean {
+ return (item as AggregateOutputMetaCarrier)[marker] === true;
+}
+
function mergeUsageExtras(
state: OpenAiResponsesAggregateState,
usagePayload: unknown,
@@ -523,8 +537,20 @@ function applyOriginalResponsesPayload(
const message = ensureMessageItem(state, outputIndex).item;
const content = Array.isArray(message.content) ? message.content as AggregateOutputItem[] : [];
if (!Array.isArray(message.content)) message.content = content;
- const part = cloneRecord(payload.part);
- if (part) content[contentIndex] = part;
+ const existingPart = isRecord(content[contentIndex]) ? content[contentIndex] as AggregateOutputItem : null;
+ const incomingPart = cloneRecord(payload.part);
+ if (incomingPart) {
+ content[contentIndex] = existingPart
+ ? {
+ ...existingPart,
+ ...incomingPart,
+ }
+ : incomingPart;
+ }
+ const part = isRecord(content[contentIndex]) ? content[contentIndex] as AggregateOutputItem : existingPart;
+ if (eventType === 'response.content_part.done' && part) {
+ markTerminalMarker(part, contentPartDoneMarker);
+ }
return serializeOriginalResponsesEvent(eventType, payload);
}
case 'response.output_text.delta':
@@ -533,6 +559,7 @@ function applyOriginalResponsesPayload(
const textPart = ensureMessageOutputTextPart(state, outputIndex);
if (eventType === 'response.output_text.done') {
textPart.part.text = typeof payload.text === 'string' ? payload.text : String(payload.text ?? '');
+ markTerminalMarker(textPart.part, outputTextDoneMarker);
} else {
textPart.part.text = `${typeof textPart.part.text === 'string' ? textPart.part.text : ''}${typeof payload.delta === 'string' ? payload.delta : ''}`;
}
@@ -580,6 +607,11 @@ function applyOriginalResponsesPayload(
...part,
};
summaryState.item.summary = summary;
+ if (eventType === 'response.reasoning_summary_part.done') {
+ markTerminalMarker(summary[summaryState.summaryIndex] as AggregateOutputItem, reasoningSummaryPartDoneMarker);
+ }
+ } else if (eventType === 'response.reasoning_summary_part.done') {
+ markTerminalMarker(summaryState.summary, reasoningSummaryPartDoneMarker);
}
return serializeOriginalResponsesEvent(eventType, payload);
}
@@ -588,6 +620,7 @@ function applyOriginalResponsesPayload(
const summaryState = ensureReasoningSummaryPart(state, payload.item_id, payload.summary_index, payload.output_index);
if (eventType === 'response.reasoning_summary_text.done') {
summaryState.summary.text = typeof payload.text === 'string' ? payload.text : String(payload.text ?? '');
+ markTerminalMarker(summaryState.summary, reasoningSummaryTextDoneMarker);
} else {
summaryState.summary.text = `${typeof summaryState.summary.text === 'string' ? summaryState.summary.text : ''}${typeof payload.delta === 'string' ? payload.delta : ''}`;
}
@@ -790,39 +823,51 @@ function buildSyntheticTerminalItemDoneEvents(
const part = content[0];
if (isRecord(part)) {
const text = typeof part.text === 'string' ? part.text : String(part.text ?? '');
- lines.push(serializeSse('response.output_text.done', {
- type: 'response.output_text.done',
- output_index: index,
- item_id: itemId,
- text,
- }));
- lines.push(serializeSse('response.content_part.done', {
- type: 'response.content_part.done',
- output_index: index,
- item_id: itemId,
- content_index: 0,
- part: cloneJson(part),
- }));
+ if (!hasTerminalMarker(part, outputTextDoneMarker)) {
+ lines.push(serializeSse('response.output_text.done', {
+ type: 'response.output_text.done',
+ output_index: index,
+ item_id: itemId,
+ text,
+ }));
+ markTerminalMarker(part, outputTextDoneMarker);
+ }
+ if (!hasTerminalMarker(part, contentPartDoneMarker)) {
+ lines.push(serializeSse('response.content_part.done', {
+ type: 'response.content_part.done',
+ output_index: index,
+ item_id: itemId,
+ content_index: 0,
+ part: cloneJson(part),
+ }));
+ markTerminalMarker(part, contentPartDoneMarker);
+ }
}
} else if (itemType === 'reasoning') {
const summary = Array.isArray(item.summary) ? item.summary as AggregateOutputItem[] : [];
const part = summary[0];
if (isRecord(part)) {
const text = typeof part.text === 'string' ? part.text : String(part.text ?? '');
- lines.push(serializeSse('response.reasoning_summary_text.done', {
- type: 'response.reasoning_summary_text.done',
- item_id: itemId,
- output_index: index,
- summary_index: 0,
- text,
- }));
- lines.push(serializeSse('response.reasoning_summary_part.done', {
- type: 'response.reasoning_summary_part.done',
- item_id: itemId,
- output_index: index,
- summary_index: 0,
- part: cloneJson(part),
- }));
+ if (!hasTerminalMarker(part, reasoningSummaryTextDoneMarker)) {
+ lines.push(serializeSse('response.reasoning_summary_text.done', {
+ type: 'response.reasoning_summary_text.done',
+ item_id: itemId,
+ output_index: index,
+ summary_index: 0,
+ text,
+ }));
+ markTerminalMarker(part, reasoningSummaryTextDoneMarker);
+ }
+ if (!hasTerminalMarker(part, reasoningSummaryPartDoneMarker)) {
+ lines.push(serializeSse('response.reasoning_summary_part.done', {
+ type: 'response.reasoning_summary_part.done',
+ item_id: itemId,
+ output_index: index,
+ summary_index: 0,
+ part: cloneJson(part),
+ }));
+ markTerminalMarker(part, reasoningSummaryPartDoneMarker);
+ }
}
} else if (itemType === 'function_call') {
const callId = asTrimmedString(item.call_id) || itemId;
diff --git a/src/server/transformers/openai/responses/outbound.test.ts b/src/server/transformers/openai/responses/outbound.test.ts
index 73c0df6..37d9aac 100644
--- a/src/server/transformers/openai/responses/outbound.test.ts
+++ b/src/server/transformers/openai/responses/outbound.test.ts
@@ -3,6 +3,112 @@ import { describe, expect, it } from 'vitest';
import { serializeResponsesFinalPayload } from './outbound.js';
describe('serializeResponsesFinalPayload', () => {
+ it('preserves native response.compaction payloads when compact serialization is requested', () => {
+ const upstreamPayload = {
+ id: 'cmp_123',
+ object: 'response.compaction',
+ created_at: 1700000000,
+ output: [
+ {
+ id: 'rs_123',
+ type: 'compaction',
+ encrypted_content: 'enc-compact-payload',
+ },
+ ],
+ usage: {
+ input_tokens: 1234,
+ output_tokens: 321,
+ total_tokens: 1555,
+ },
+ };
+
+ const payload = serializeResponsesFinalPayload({
+ upstreamPayload,
+ normalized: {
+ id: 'cmp_123',
+ model: 'gpt-5',
+ created: 1700000000,
+ content: '',
+ reasoningContent: '',
+ finishReason: 'stop',
+ toolCalls: [],
+ },
+ usage: {
+ promptTokens: 1234,
+ completionTokens: 321,
+ totalTokens: 1555,
+ },
+ serializationMode: 'compact',
+ } as any);
+
+ expect(payload).toEqual(upstreamPayload);
+ });
+
+ it('serializes compact mode as response.compaction instead of an ordinary response object', () => {
+ const payload = serializeResponsesFinalPayload({
+ upstreamPayload: {
+ id: 'chatcmpl_compact',
+ object: 'chat.completion',
+ created: 1700000000,
+ model: 'gpt-5',
+ choices: [
+ {
+ index: 0,
+ finish_reason: 'stop',
+ message: {
+ role: 'assistant',
+ content: 'hello',
+ },
+ },
+ ],
+ },
+ normalized: {
+ id: 'chatcmpl_compact',
+ model: 'gpt-5',
+ created: 1700000000,
+ content: 'hello',
+ reasoningContent: '',
+ finishReason: 'stop',
+ toolCalls: [],
+ },
+ usage: {
+ promptTokens: 11,
+ completionTokens: 7,
+ totalTokens: 18,
+ },
+ serializationMode: 'compact',
+ } as any);
+
+ expect(payload).toEqual({
+ id: 'resp_chatcmpl_compact',
+ object: 'response.compaction',
+ created_at: 1700000000,
+ output: [
+ {
+ id: 'msg_chatcmpl_compact',
+ type: 'message',
+ role: 'assistant',
+ status: 'completed',
+ content: [
+ {
+ type: 'output_text',
+ text: 'hello',
+ },
+ ],
+ },
+ ],
+ usage: {
+ input_tokens: 11,
+ output_tokens: 7,
+ total_tokens: 18,
+ },
+ });
+ expect(payload).not.toHaveProperty('created');
+ expect(payload).not.toHaveProperty('status');
+ expect(payload).not.toHaveProperty('model');
+ expect(payload).not.toHaveProperty('output_text');
+ });
+
it('preserves top-level chat annotations on synthetic assistant messages', () => {
const payload = serializeResponsesFinalPayload({
upstreamPayload: {
diff --git a/src/server/transformers/openai/responses/outbound.ts b/src/server/transformers/openai/responses/outbound.ts
index ddcd066..be581e8 100644
--- a/src/server/transformers/openai/responses/outbound.ts
+++ b/src/server/transformers/openai/responses/outbound.ts
@@ -64,6 +64,8 @@ export type ResponsesToolCall = {
arguments: string;
};
+export type ResponsesFinalSerializationMode = 'response' | 'compact';
+
type ResponsesOutputItem = Record<string, unknown>;
function extractToolCallsFromUpstream(payload: unknown): ResponsesToolCall[] {
@@ -280,14 +282,45 @@ export function normalizeResponsesFinalPayload(
return normalizeUpstreamFinalResponse(payload, modelName, fallbackText);
}
+function buildResponsesUsagePayload(
+ usage: ResponsesUsageSummary,
+ syntheticUsageDetails: {
+ inputTokensDetails?: Record<string, unknown>;
+ outputTokensDetails?: Record<string, unknown>;
+ },
+): Record<string, unknown> {
+ return {
+ input_tokens: usage.promptTokens,
+ output_tokens: usage.completionTokens,
+ total_tokens: usage.totalTokens,
+ ...(usage.inputTokensDetails ?? syntheticUsageDetails.inputTokensDetails
+ ? { input_tokens_details: cloneJson(usage.inputTokensDetails ?? syntheticUsageDetails.inputTokensDetails) }
+ : {}),
+ ...(usage.outputTokensDetails ?? syntheticUsageDetails.outputTokensDetails
+ ? { output_tokens_details: cloneJson(usage.outputTokensDetails ?? syntheticUsageDetails.outputTokensDetails) }
+ : {}),
+ };
+}
+
export function serializeResponsesFinalPayload(input: {
upstreamPayload: unknown;
normalized: NormalizedFinalResponse;
usage: ResponsesUsageSummary;
+ serializationMode?: ResponsesFinalSerializationMode;
}): Record<string, unknown> {
- const { upstreamPayload, normalized, usage } = input;
- if (isRecord(upstreamPayload) && upstreamPayload.object === 'response') {
- return upstreamPayload;
+ const {
+ upstreamPayload,
+ normalized,
+ usage,
+ serializationMode = 'response',
+ } = input;
+ if (isRecord(upstreamPayload)) {
+ if (upstreamPayload.object === 'response.compaction') {
+ return upstreamPayload;
+ }
+ if (serializationMode === 'response' && upstreamPayload.object === 'response') {
+ return upstreamPayload;
+ }
}
const normalizedId = typeof normalized.id === 'string' && normalized.id.trim()
@@ -371,6 +404,17 @@ export function serializeResponsesFinalPayload(input: {
}
}
+ const usagePayload = buildResponsesUsagePayload(usage, syntheticUsageDetails);
+ if (serializationMode === 'compact') {
+ return {
+ id: responseId,
+ object: 'response.compaction',
+ created_at: normalized.created,
+ output,
+ usage: usagePayload,
+ };
+ }
+
return {
id: responseId,
object: 'response',
@@ -379,17 +423,7 @@ export function serializeResponsesFinalPayload(input: {
model: normalized.model,
output,
output_text: normalized.content || collectOutputTextFromItems(output),
- usage: {
- input_tokens: usage.promptTokens,
- output_tokens: usage.completionTokens,
- total_tokens: usage.totalTokens,
- ...(usage.inputTokensDetails ?? syntheticUsageDetails.inputTokensDetails
- ? { input_tokens_details: cloneJson(usage.inputTokensDetails ?? syntheticUsageDetails.inputTokensDetails) }
- : {}),
- ...(usage.outputTokensDetails ?? syntheticUsageDetails.outputTokensDetails
- ? { output_tokens_details: cloneJson(usage.outputTokensDetails ?? syntheticUsageDetails.outputTokensDetails) }
- : {}),
- },
+ usage: usagePayload,
};
}