From 420565779590b2cabd34d3f85f4bb20d1b7068af Mon Sep 17 00:00:00 2001
From: Zhang Zelun <33217105+BluebirdStory@users.noreply.github.com>
Date: Wed, 3 Jun 2026 14:43:14 +0800
Subject: [PATCH] add PaddleOCR-VL-1.6 docs (#18095)
---
README.md | 10 ++
.../PaddleOCR-VL/PaddleOCR-VL-1.6.en.md | 147 ++++++++++++++++++
.../PaddleOCR-VL/PaddleOCR-VL-1.6.md | 147 ++++++++++++++++++
mkdocs.yml | 3 +-
4 files changed, 306 insertions(+), 1 deletion(-)
create mode 100644 docs/version3.x/algorithm/PaddleOCR-VL/PaddleOCR-VL-1.6.en.md
create mode 100644 docs/version3.x/algorithm/PaddleOCR-VL/PaddleOCR-VL-1.6.md
diff --git a/README.md b/README.md
index 94f7820cf7..aeb7f7e9a3 100644
--- a/README.md
+++ b/README.md
@@ -289,4 +289,14 @@ This project is released under the [Apache 2.0 license](LICENSE).
primaryClass={cs.CV},
url={https://arxiv.org/abs/2601.21957},
}
+
+@misc{zhang2026paddleocrvl16expandingfrontierdocument,
+ title={PaddleOCR-VL-1.6: Expanding the Frontier of Document Parsing with Under-Optimized Region Refinement and Progressive Post-Training},
+ author={Zelun Zhang and Hongen Liu and Suyin Liang and Yubo Zhang and Yiqing Xiang and Jiaxuan Liu and Ting Sun and Manhui Lin and Yue Zhang and Changda Zhou and Tingquan Gao and Cheng Cui and Yi Liu and Dianhai Yu and Yanjun Ma},
+ year={2026},
+ eprint={2606.03264},
+ archivePrefix={arXiv},
+ primaryClass={cs.CV},
+ url={https://arxiv.org/abs/2606.03264},
+}
```
diff --git a/docs/version3.x/algorithm/PaddleOCR-VL/PaddleOCR-VL-1.6.en.md b/docs/version3.x/algorithm/PaddleOCR-VL/PaddleOCR-VL-1.6.en.md
new file mode 100644
index 0000000000..25229898e7
--- /dev/null
+++ b/docs/version3.x/algorithm/PaddleOCR-VL/PaddleOCR-VL-1.6.en.md
@@ -0,0 +1,147 @@
+## 1. Introduction to PaddleOCR-VL-1.6
+
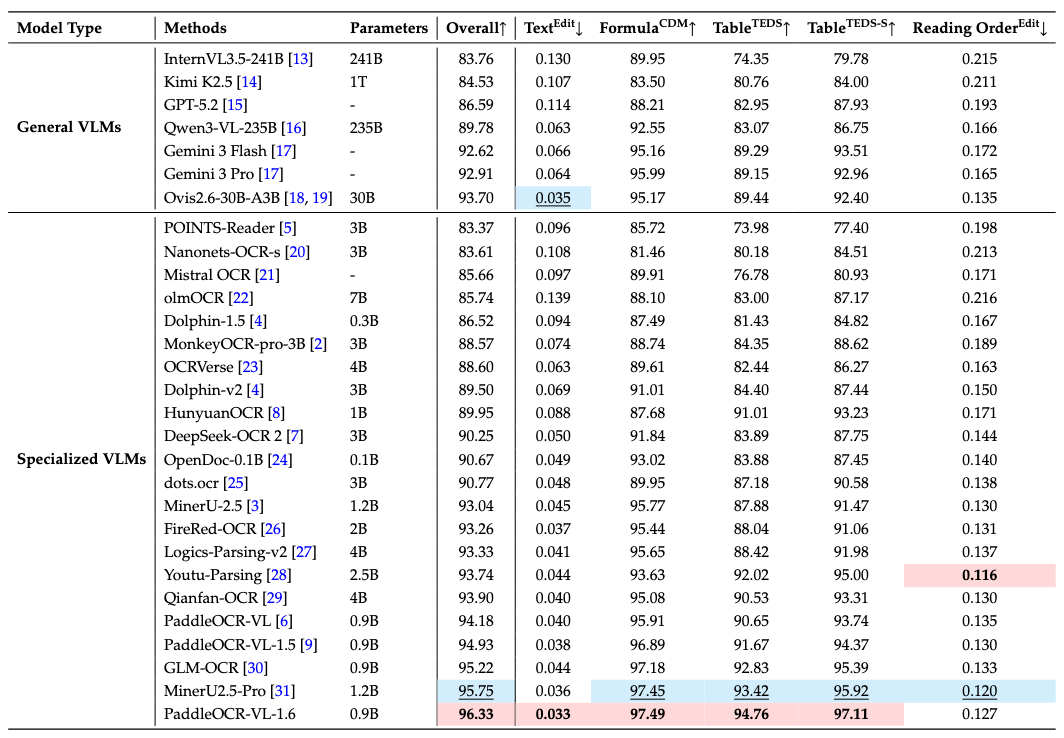
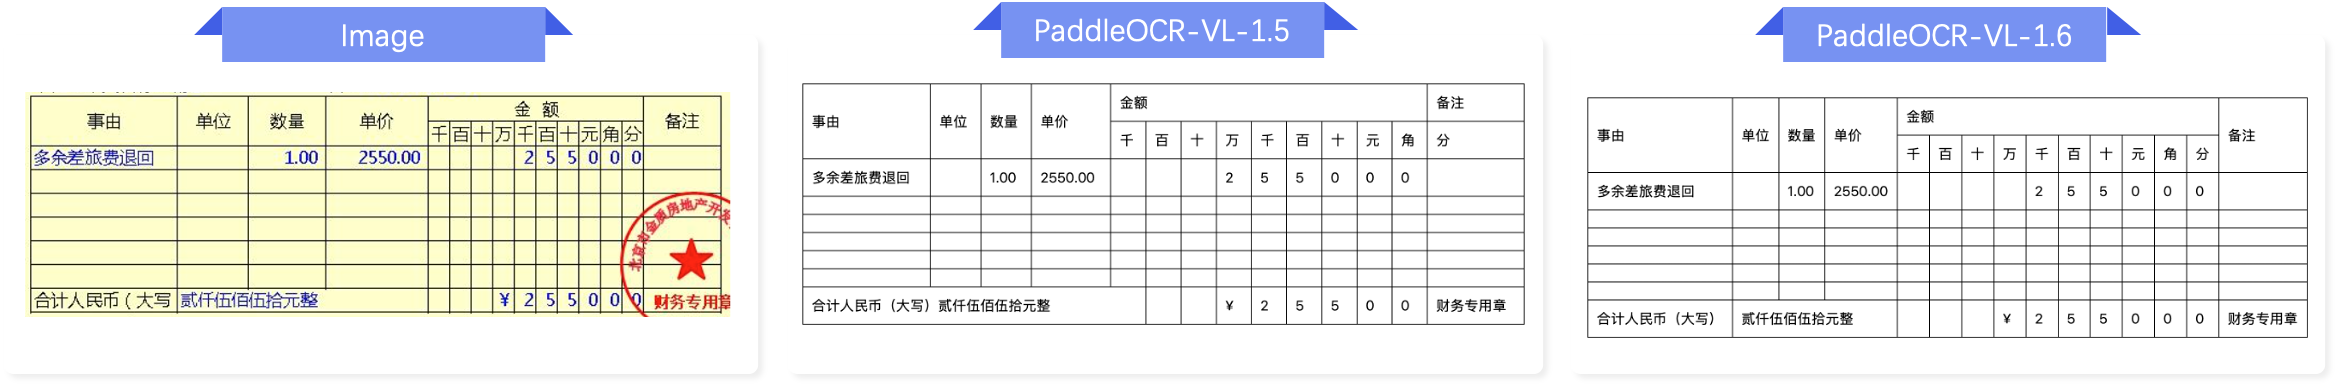
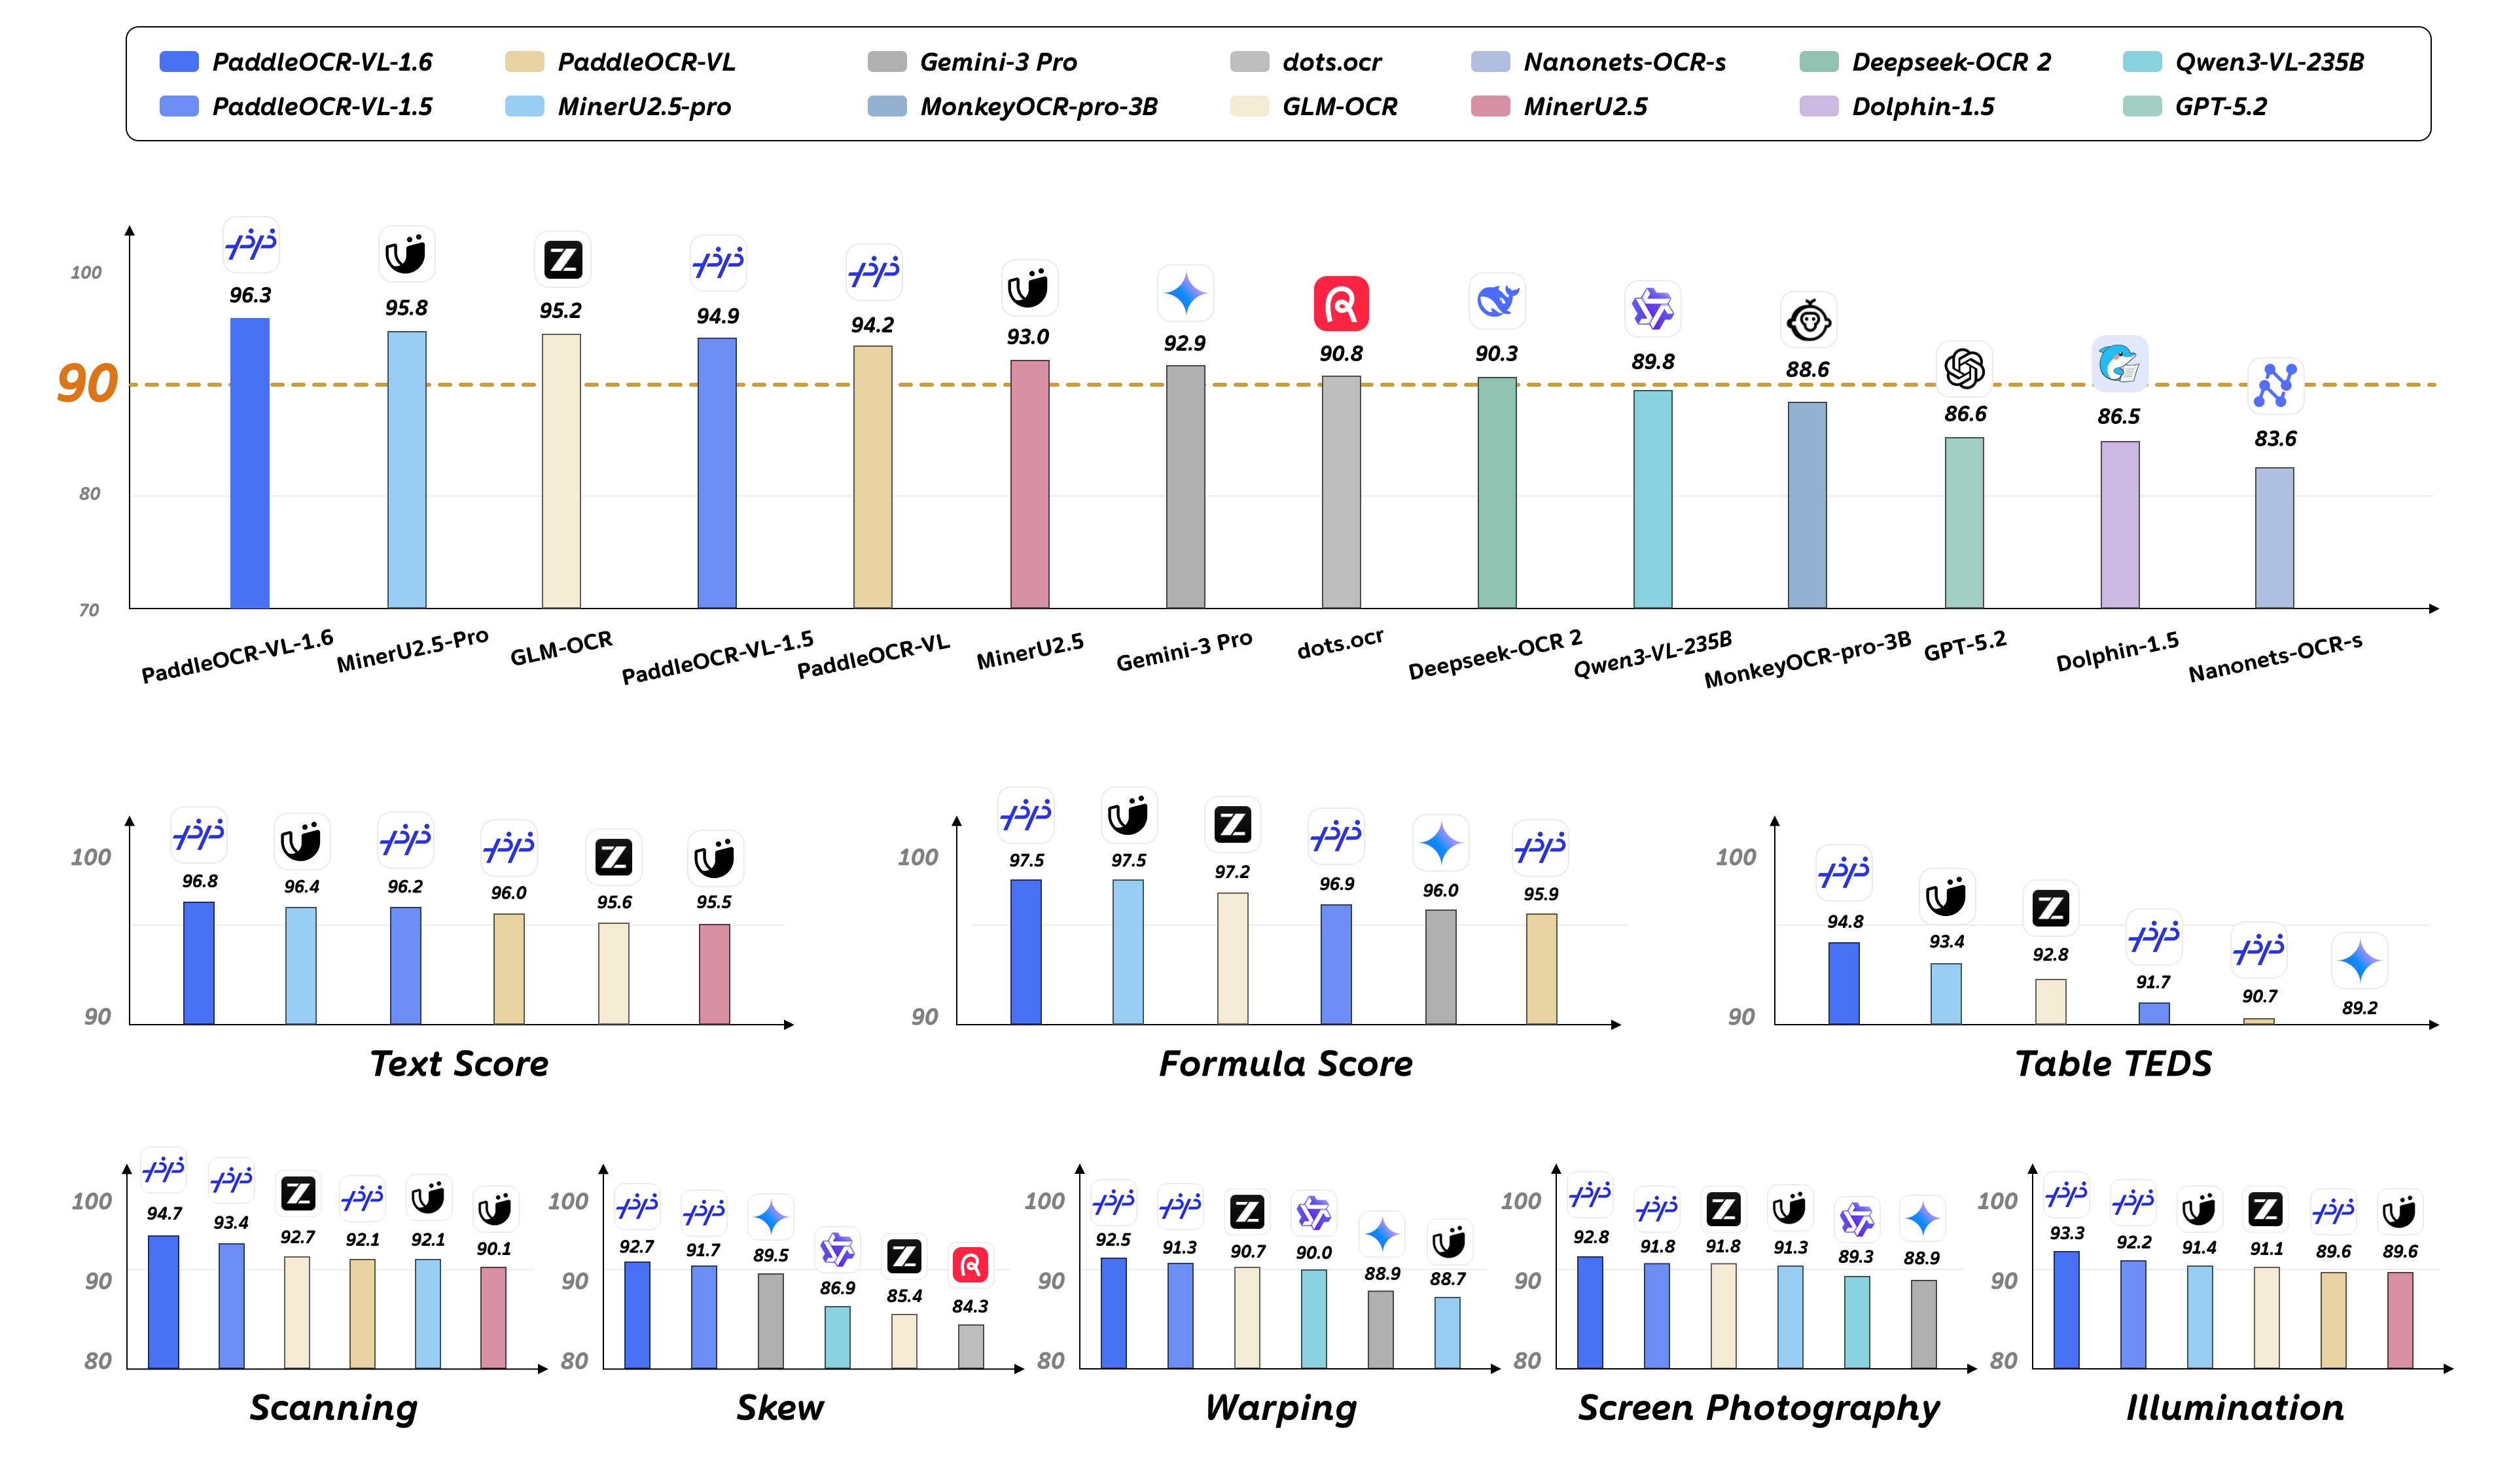
+**PaddleOCR-VL-1.6** further optimizes PaddleOCR-VL-1.5 by systematically analyzing under-optimized areas in the current model, applying targeted data optimization, and adopting refined post-training strategies. It achieves a new state-of-the-art (SOTA) result of 96.33% on the OmniDocBench v1.6 document parsing benchmark. PaddleOCR-VL-1.6 also reaches SOTA performance across all scenarios on Real5-OmniDocBench, a benchmark designed to evaluate robustness against real-world physical distortions. In addition, PaddleOCR-VL-1.6 outperforms PaddleOCR-VL-1.5 on three subtasks: seal recognition, text detection and recognition, and chart recognition, while still maintaining an ultra-compact 0.9B-parameter VLM and high efficiency.
+
+### **Key Metrics:**
+
+
+
+
+
+
+### **Core Features:**
+
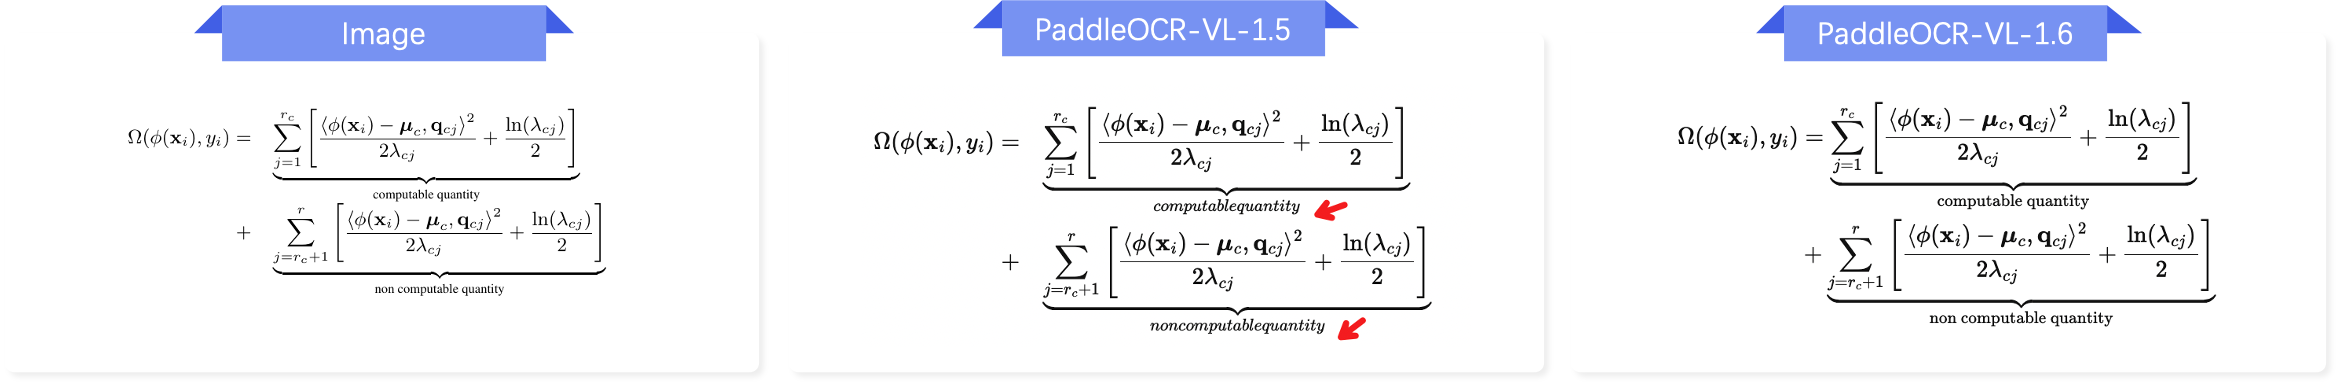
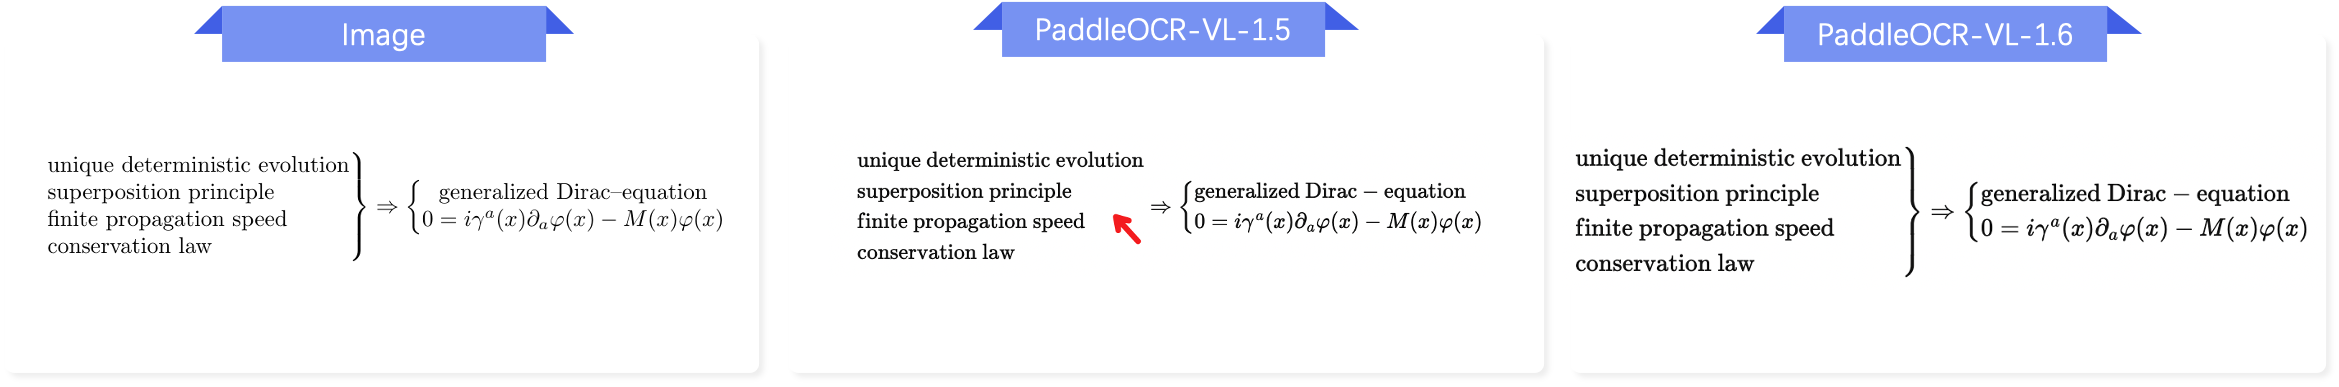
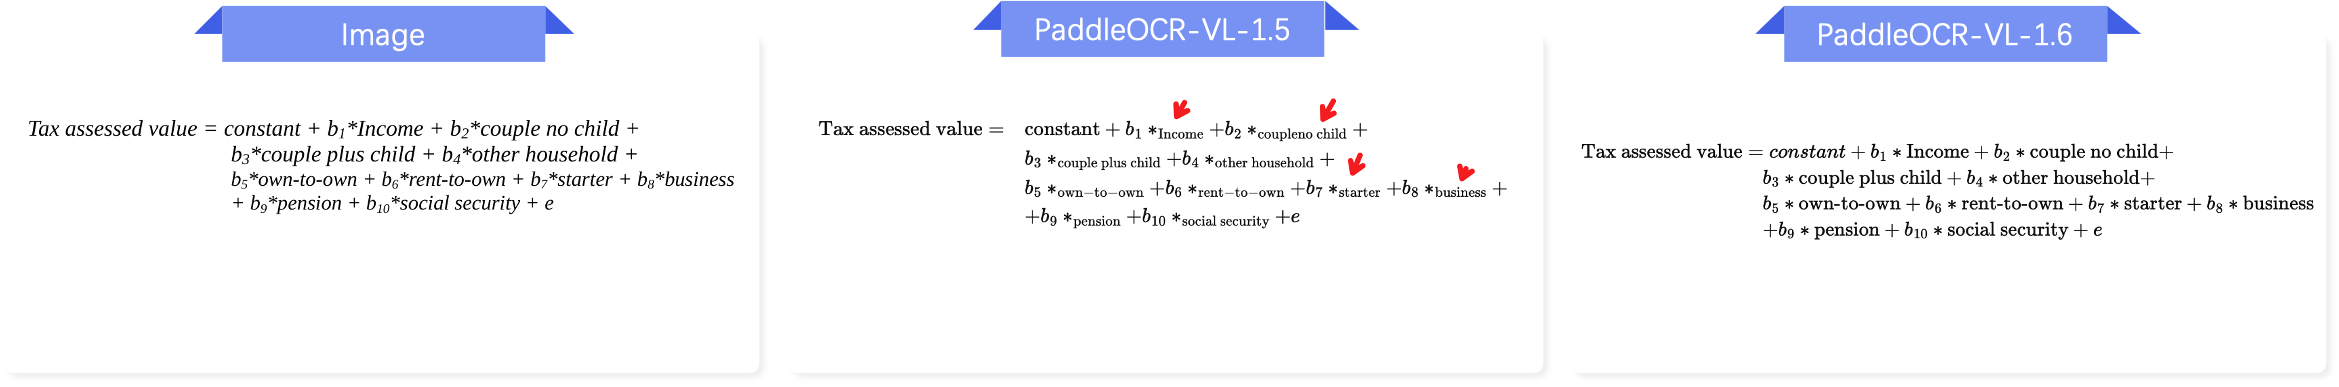
+1. **SOTA performance in document parsing:** With only 0.9B parameters, PaddleOCR-VL-1.6 achieves 96.33% accuracy on OmniDocBench v1.6, surpassing the previous SOTA model, PaddleOCR-VL-1.5. Significant improvements are observed in table, formula, and text recognition.
+
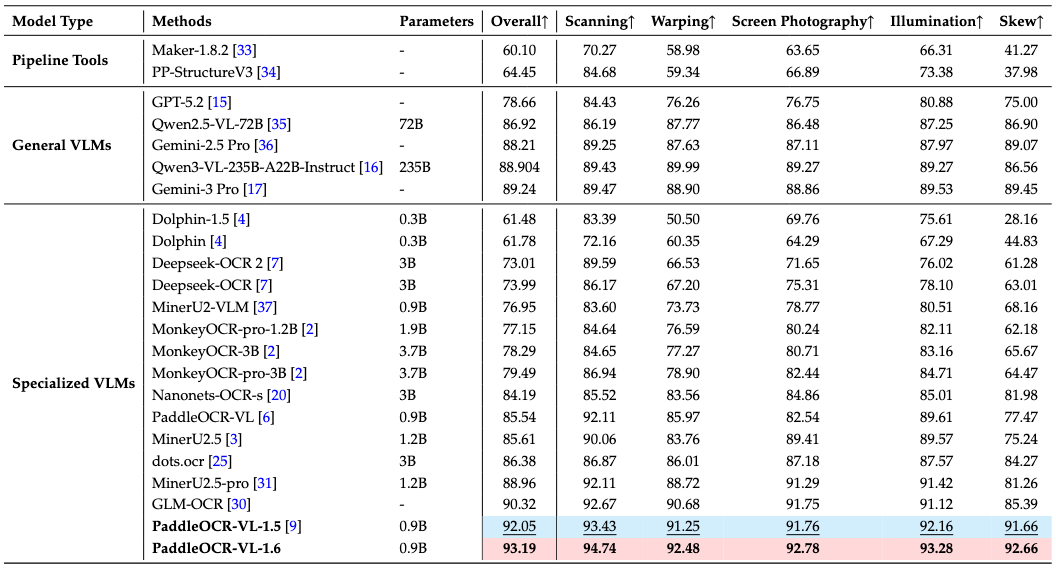
+2. **SOTA performance for document parsing across five real-world scenarios:** PaddleOCR-VL-1.6 offers stronger robustness and practicality in real-world use cases. In evaluations across five real-world distortion scenarios—scanning, warping, skew, screen photography, and illumination variation—it outperforms mainstream open-source and closed-source models.
+
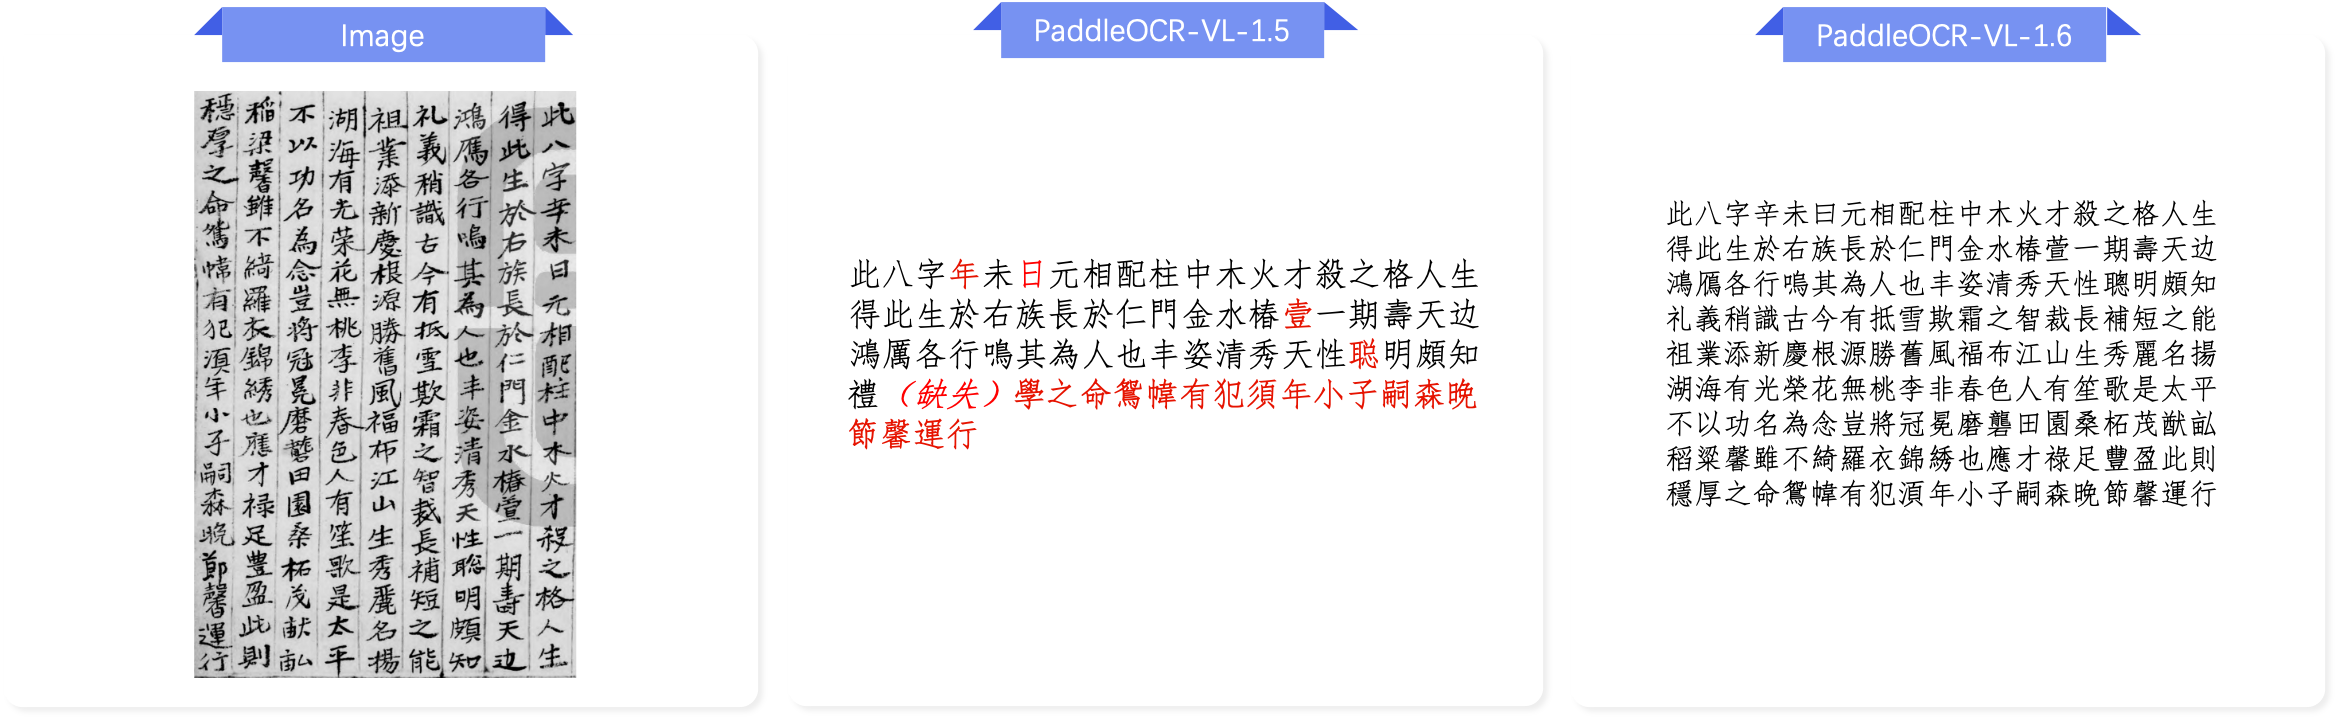
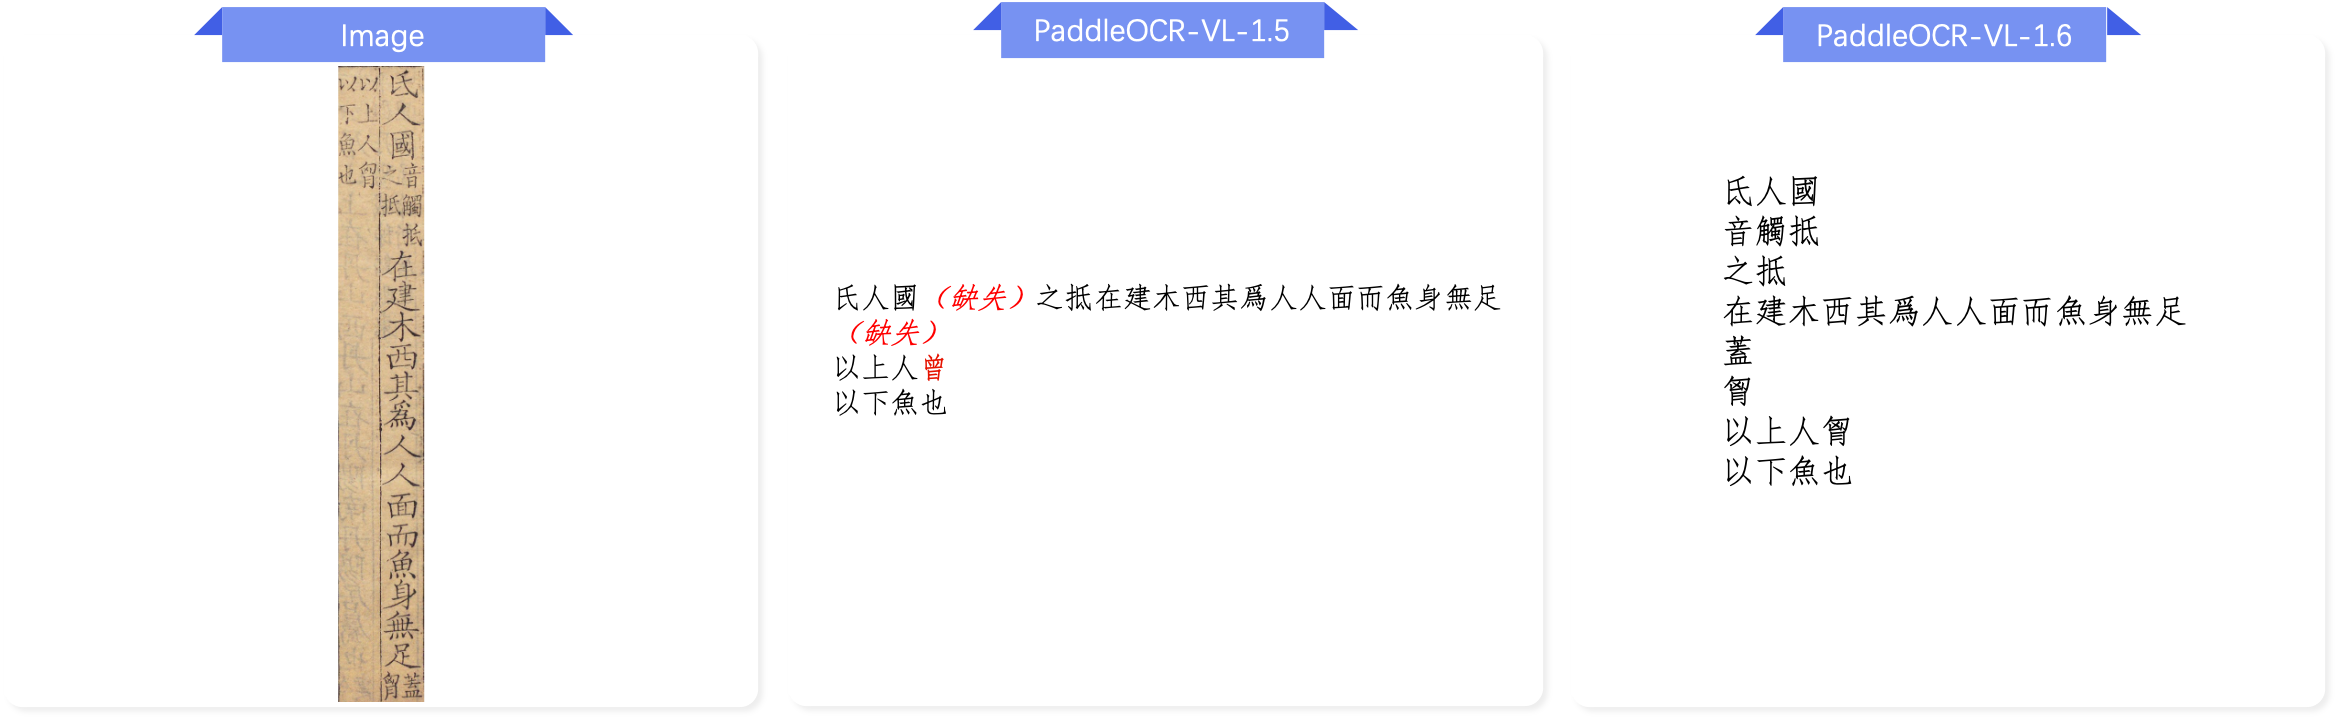
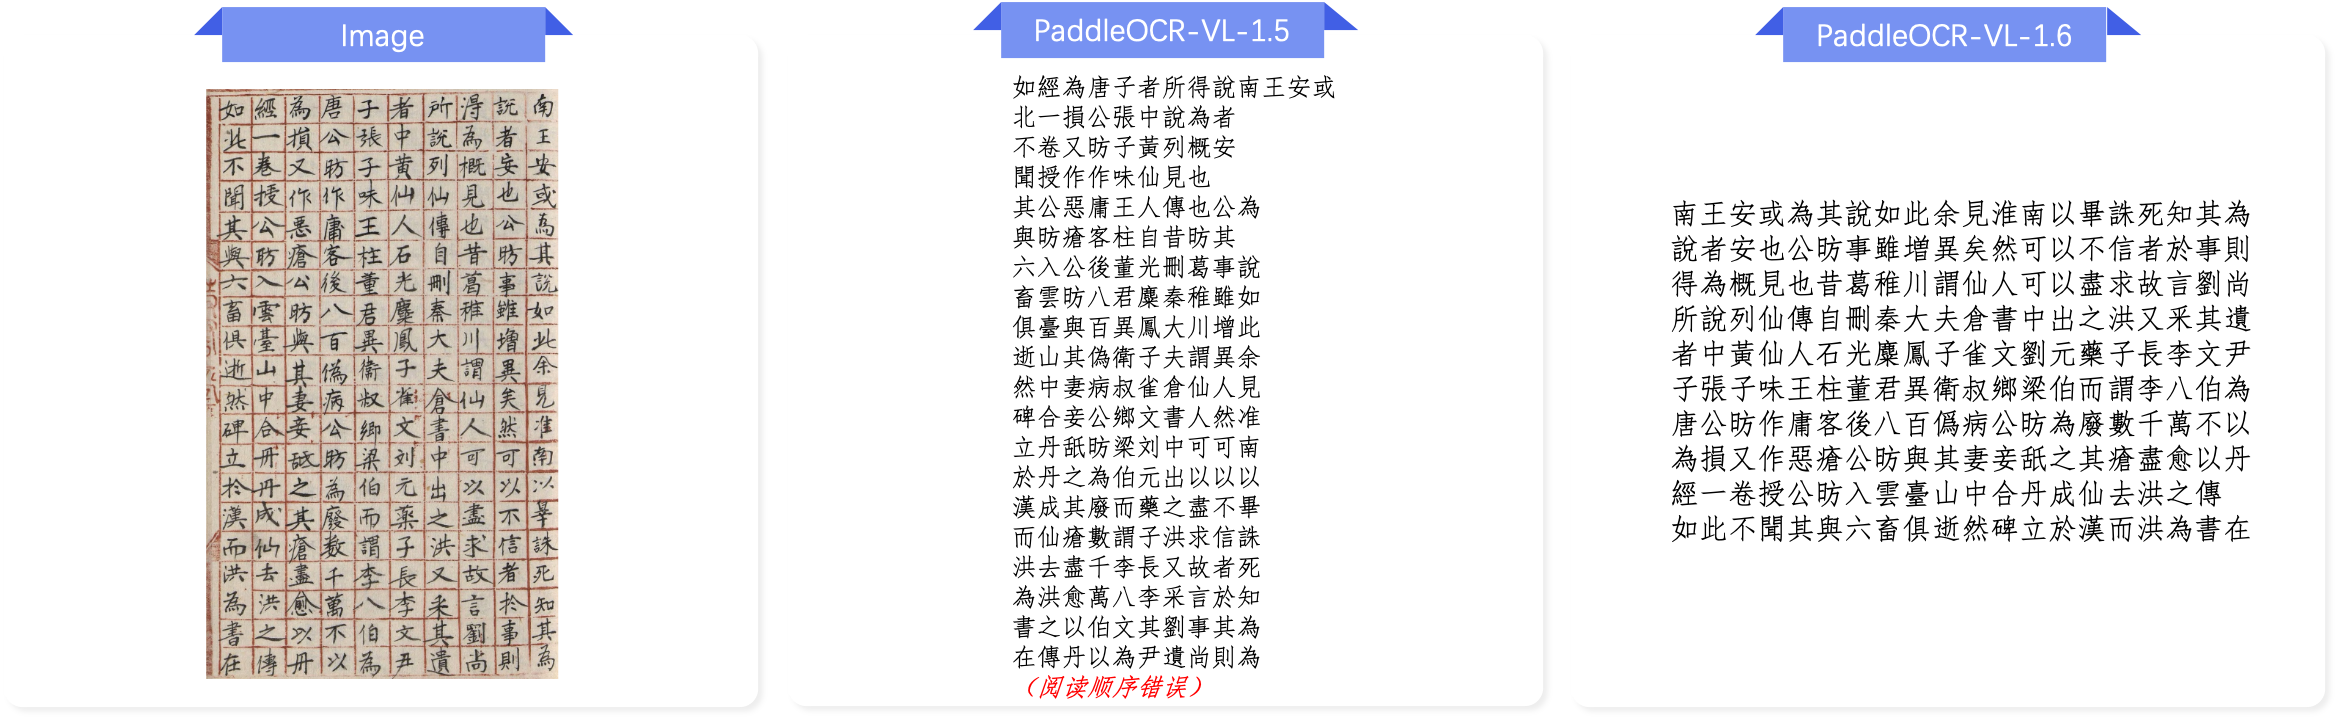
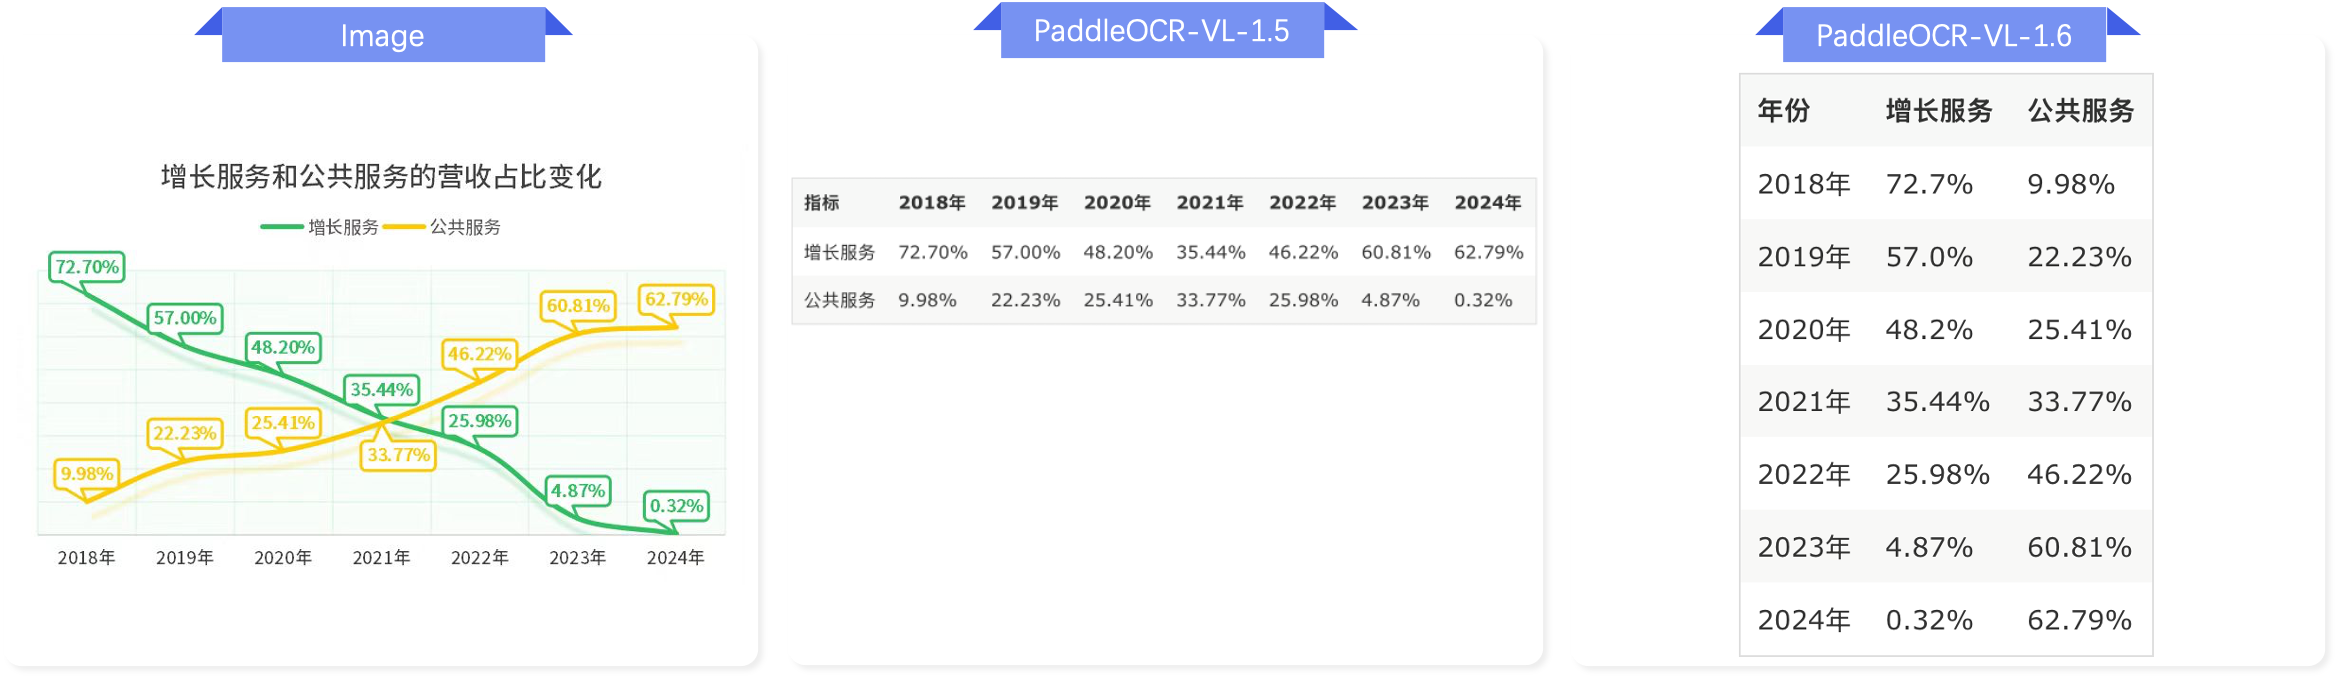
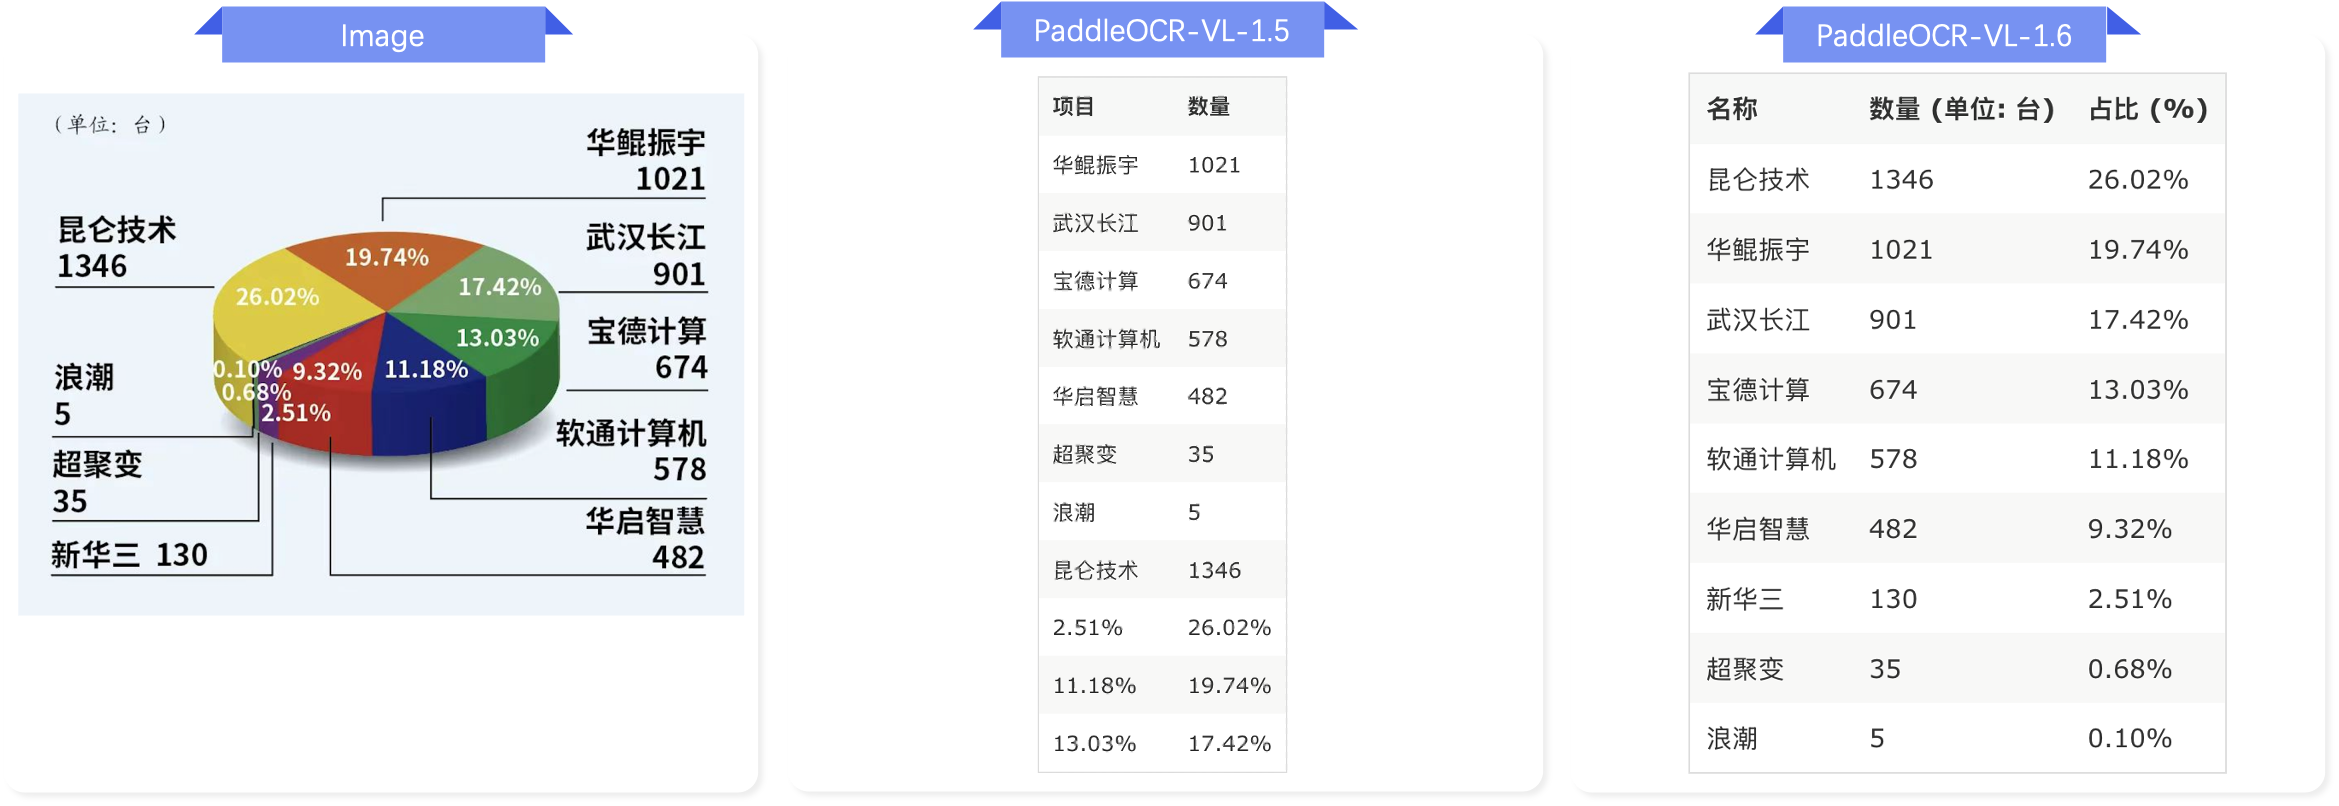
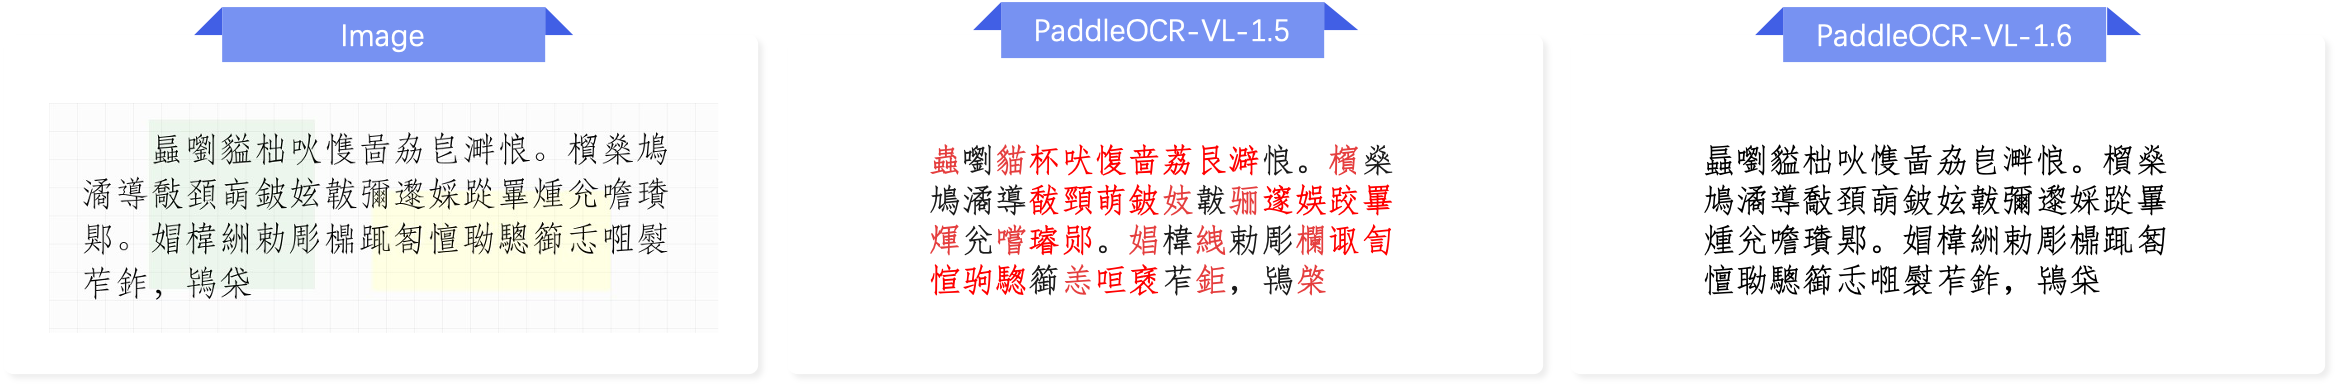
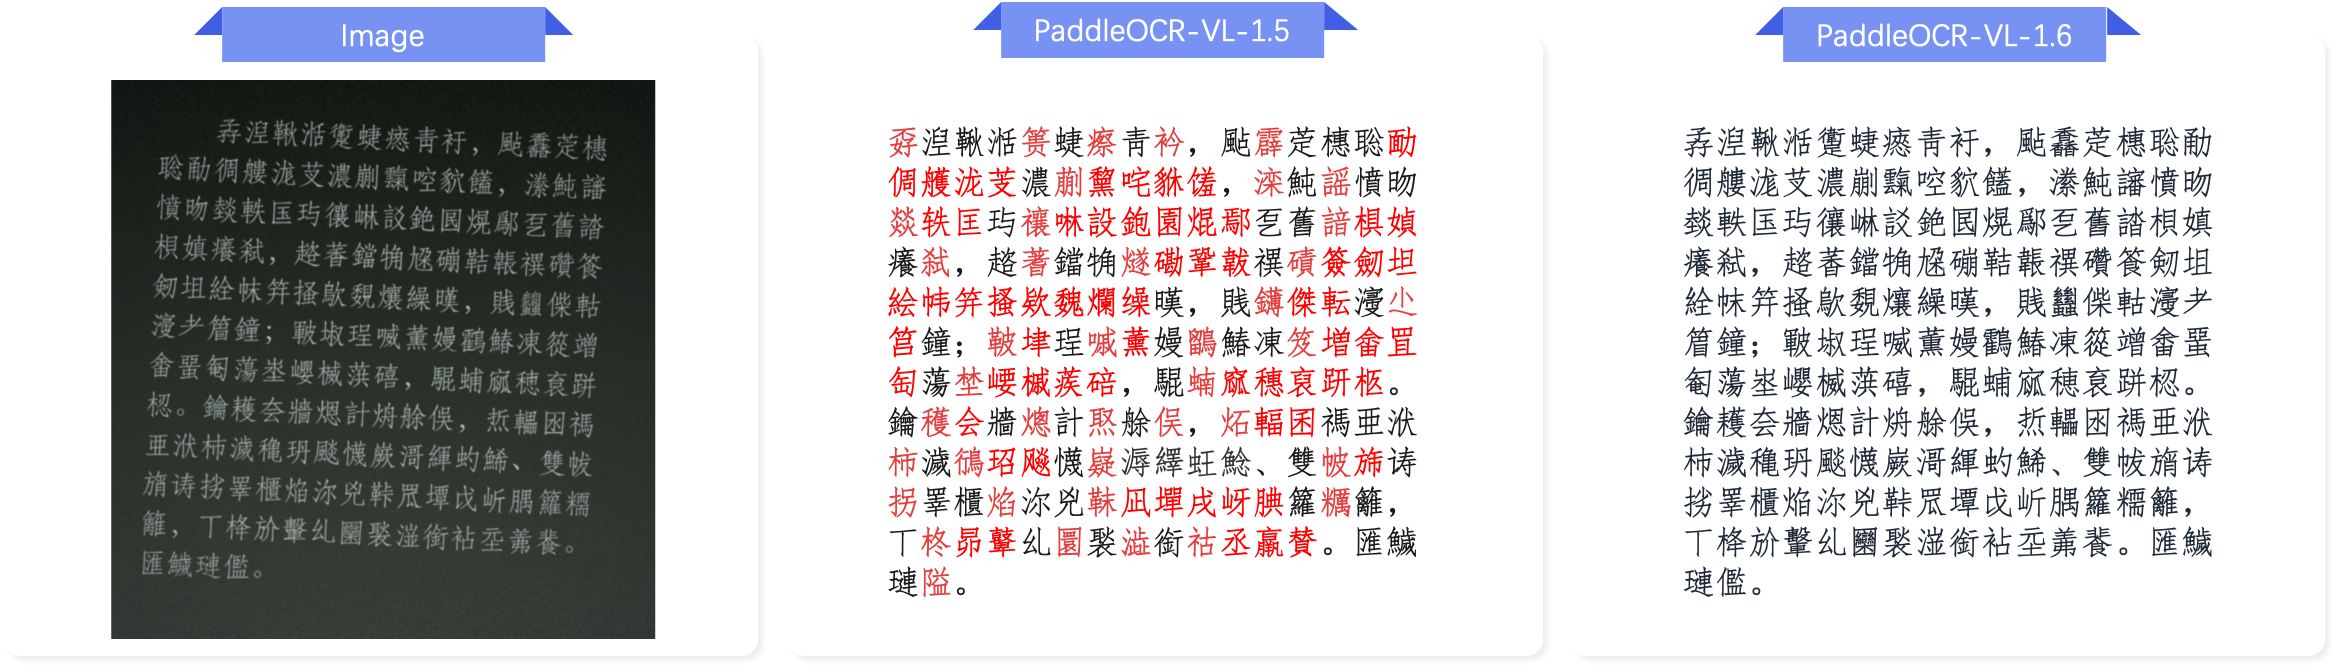
+3. **Enhanced multi-element recognition capabilities:** Beyond improved layout parsing, PaddleOCR-VL-1.6 substantially strengthens recognition of complex tables, ancient books, and rare Chinese characters, while further improving three existing capabilities: chart parsing, seal recognition, and text detection and recognition.
+
+4. **Compact 0.9B architecture:** PaddleOCR-VL-1.6 follows the compact 0.9B architecture of the PaddleOCR-VL series, enabling zero-cost adaptation and drop-in replacement.
+
+
+## 2. Technical Architecture
+
+
+

+
+
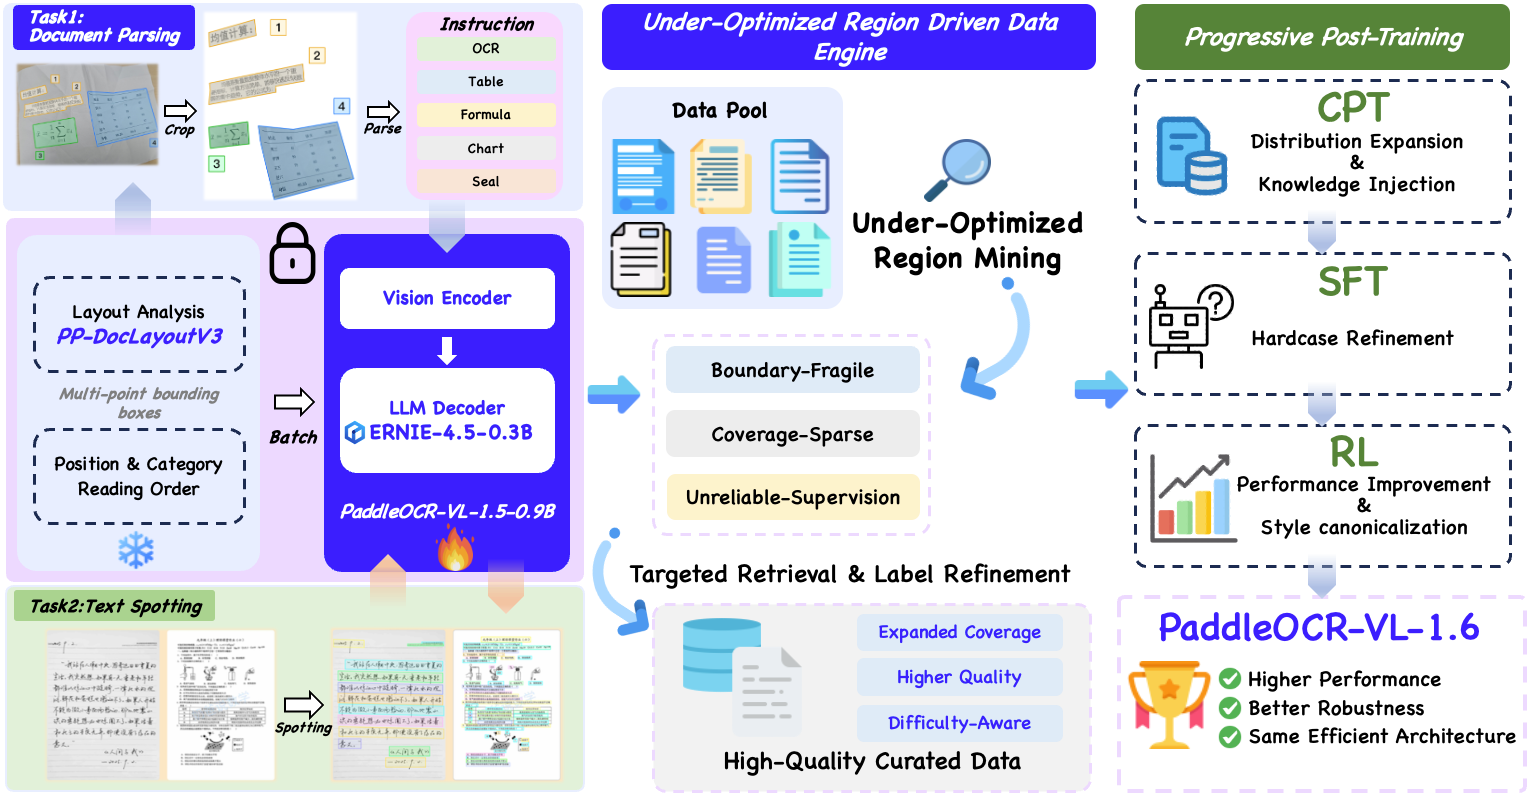
+1. **Data engine:** Starting from PaddleOCR-VL-1.5, the data engine systematically identifies under-optimized areas in PaddleOCR-VL-1.5, designs strategies for obtaining high-quality labels, and performs targeted data optimization.
+2. **Progressive post-training strategy:** Data is carefully categorized from three perspectives: quality, difficulty, and improvement value. The training weights of PaddleOCR-VL-1.5 are loaded, and a three-stage post-training strategy—continued pre-training, supervised fine-tuning, and reinforcement learning—is applied according to different data quality levels to steadily improve model performance.
+
+
+## 3. Model Performance
+
+### 1. OmniDocBench v1.6
+
+#### PaddleOCR-VL-1.6 achieves state-of-the-art performance on OmniDocBench v1.6 in overall metrics, text, formulas, and tables. It also delivers leading results in reading order.
+
+
+
+

+
+
+> **Note:**
+> - Performance metrics are cited from the [official OmniDocBench leaderboard](https://opendatalab.com/omnidocbench).
+
+
+### 2. Real5-OmniDocBench
+
+#### PaddleOCR-VL-1.6 sets new SOTA records across five diverse and challenging scenarios: scanning, warping, screen photography, illumination, and skew.
+
+
+
+

+
+
+> **Note:**
+> - Real5-OmniDocBench is a new real-world benchmark built by the PaddleOCR team based on the OmniDocBench v1.5 dataset. It contains five scenarios: Scanning, Warping, Screen-photography, Illumination, and Skew. For more details, see [Real5-OmniDocBench](https://huggingface.co/datasets/PaddlePaddle/Real5-OmniDocBench).
+
+
+
+## 4. Inference and Deployment Performance
+
+PaddleOCR-VL-1.6 and PaddleOCR-VL-1.5 use exactly the same model architecture design, so they have identical inference speeds. For details about the inference speed of PaddleOCR-VL-1.5, refer to [PaddleOCR-VL-1.5 inference speed](./PaddleOCR-VL-1.5.md#4推理部署性能).
+
+
+## 5. Visualization
+
+### Comparison with PaddleOCR-VL-1.5
+
+
+#### Ancient Book Recognition
+
+
+

+
+
+
+

+
+
+
+

+
+
+
+#### Chart Parsing
+
+
+

+
+
+
+

+
+
+
+#### Formula Recognition
+
+
+

+
+
+
+

+
+
+
+

+
+
+#### Rare Chinese Character Recognition
+
+
+

+
+
+
+

+
+
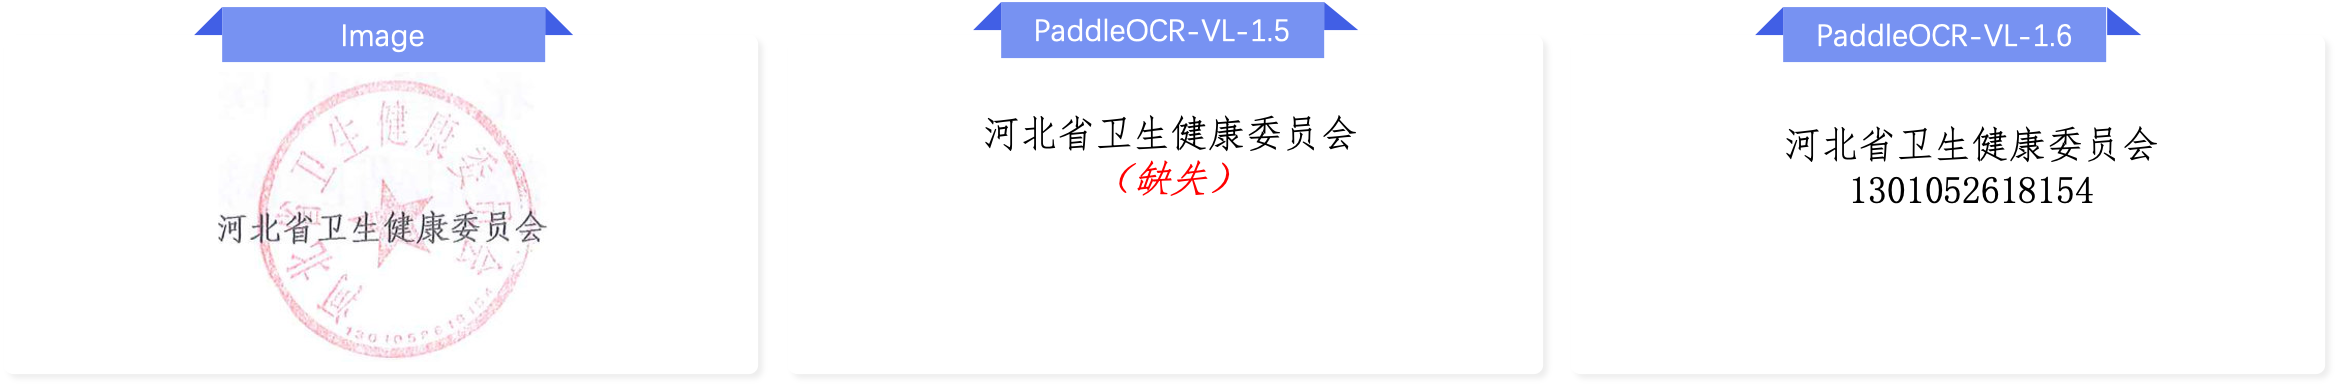
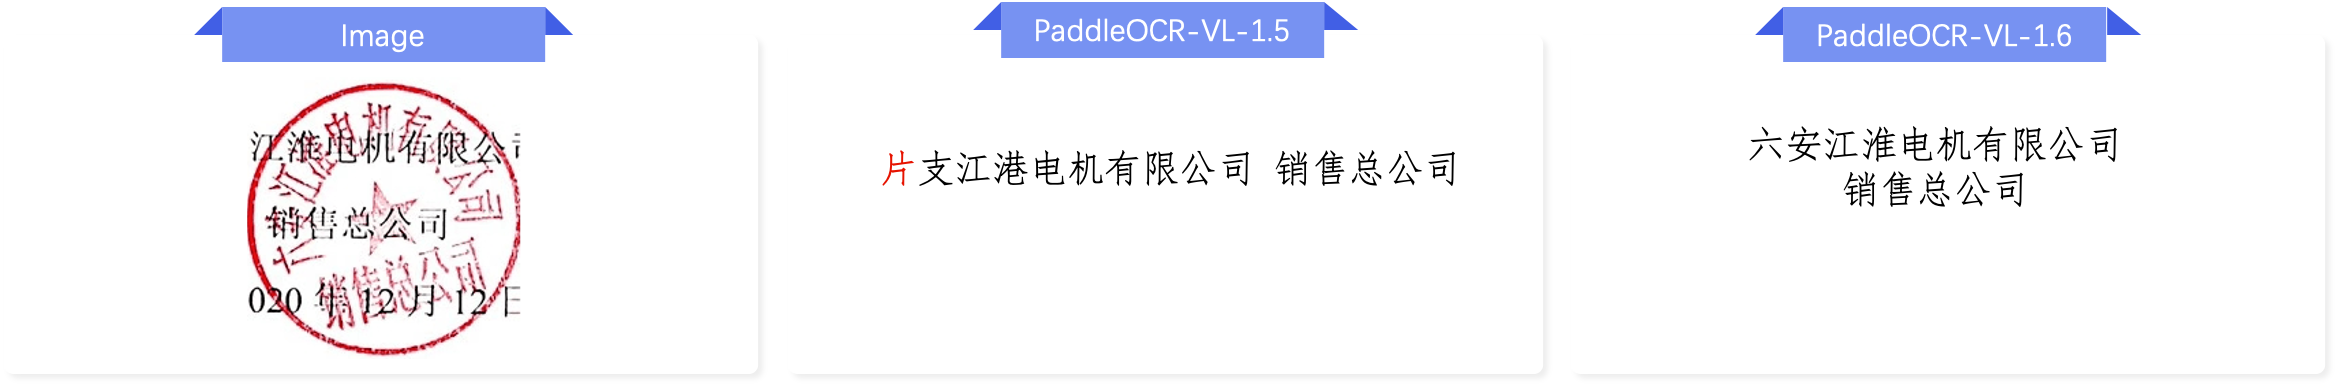
+#### Seal Recognition
+
+
+

+
+
+
+

+
+
+
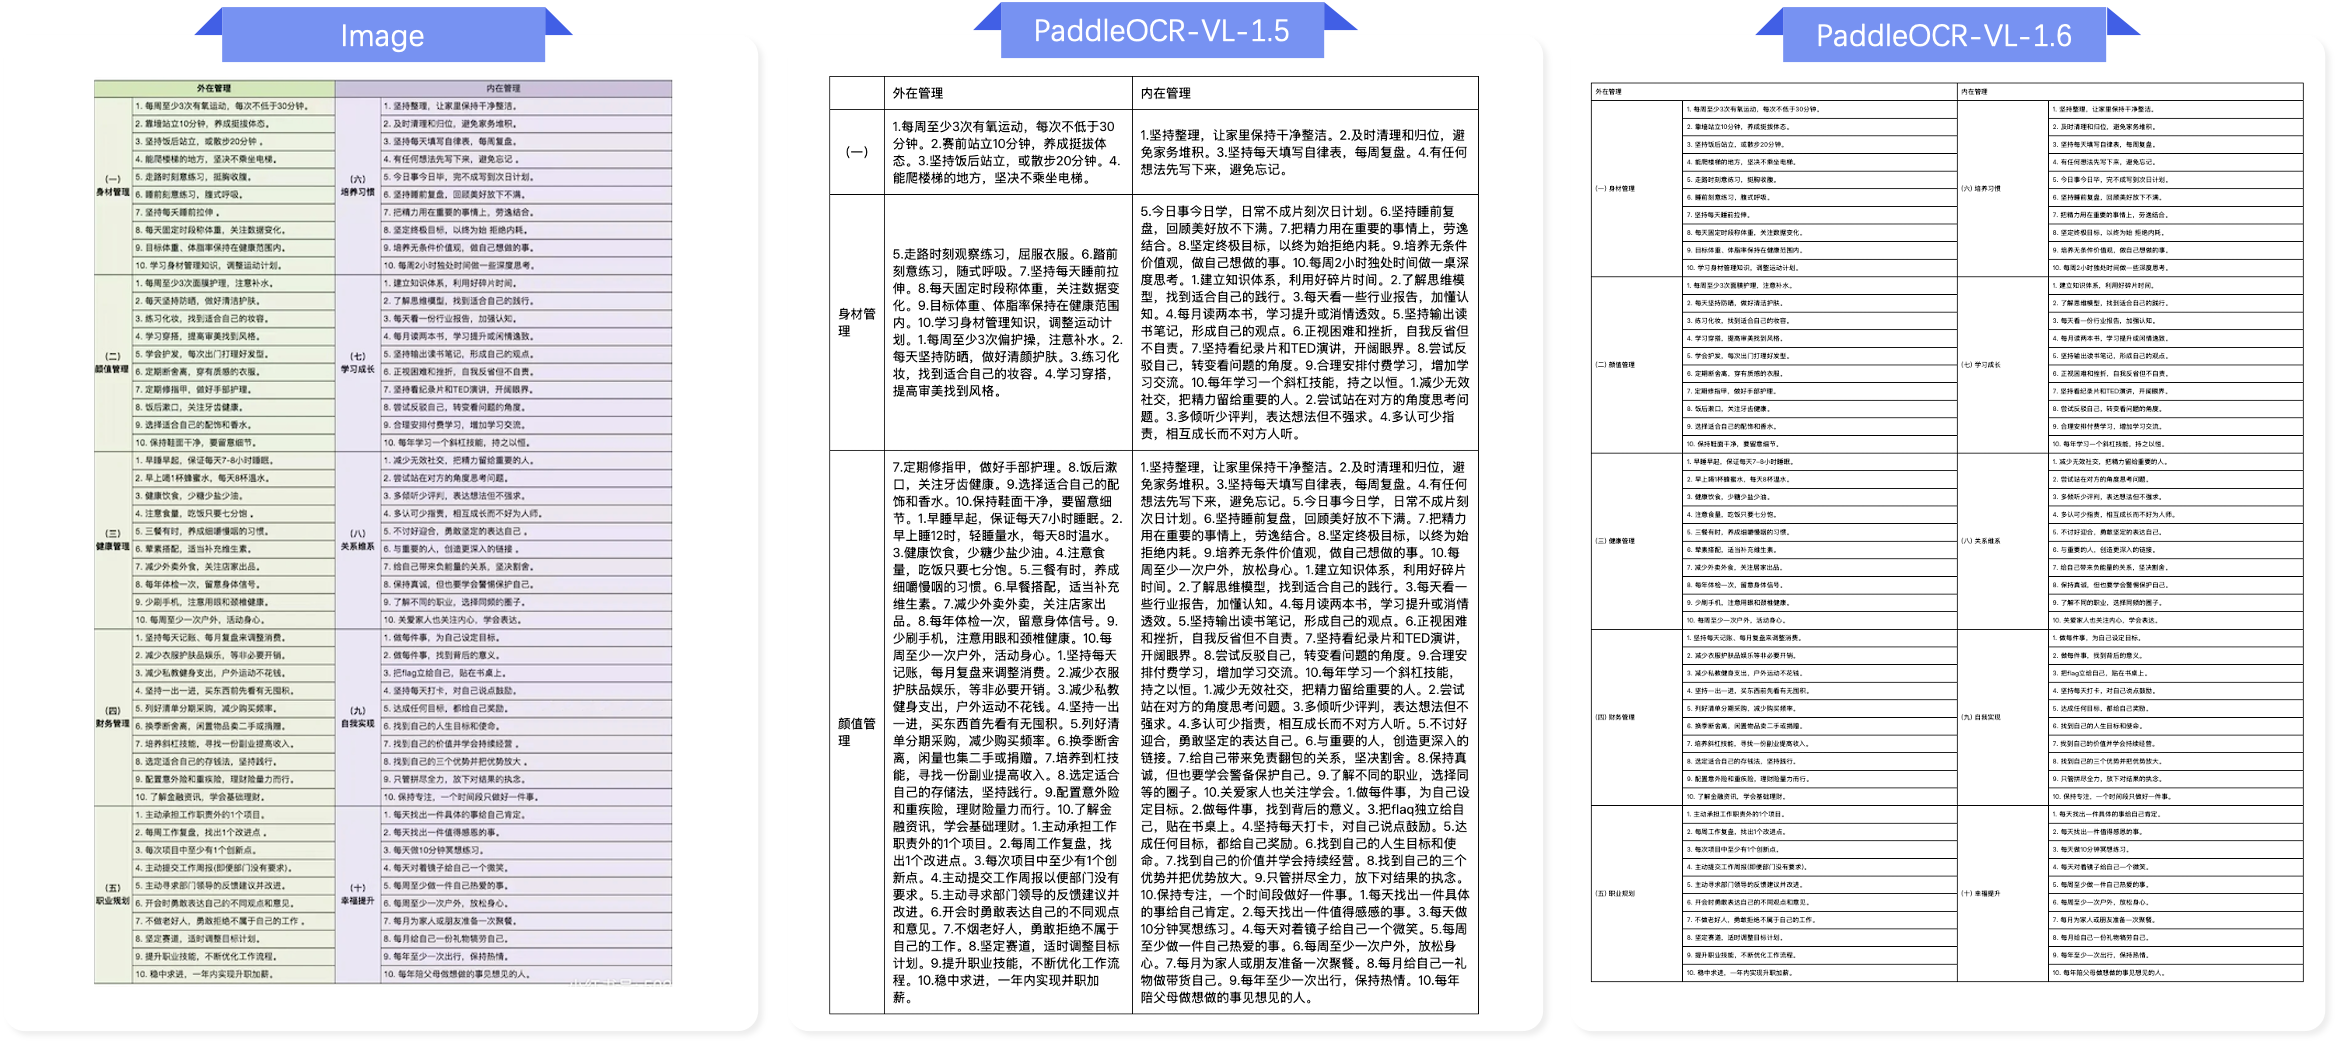
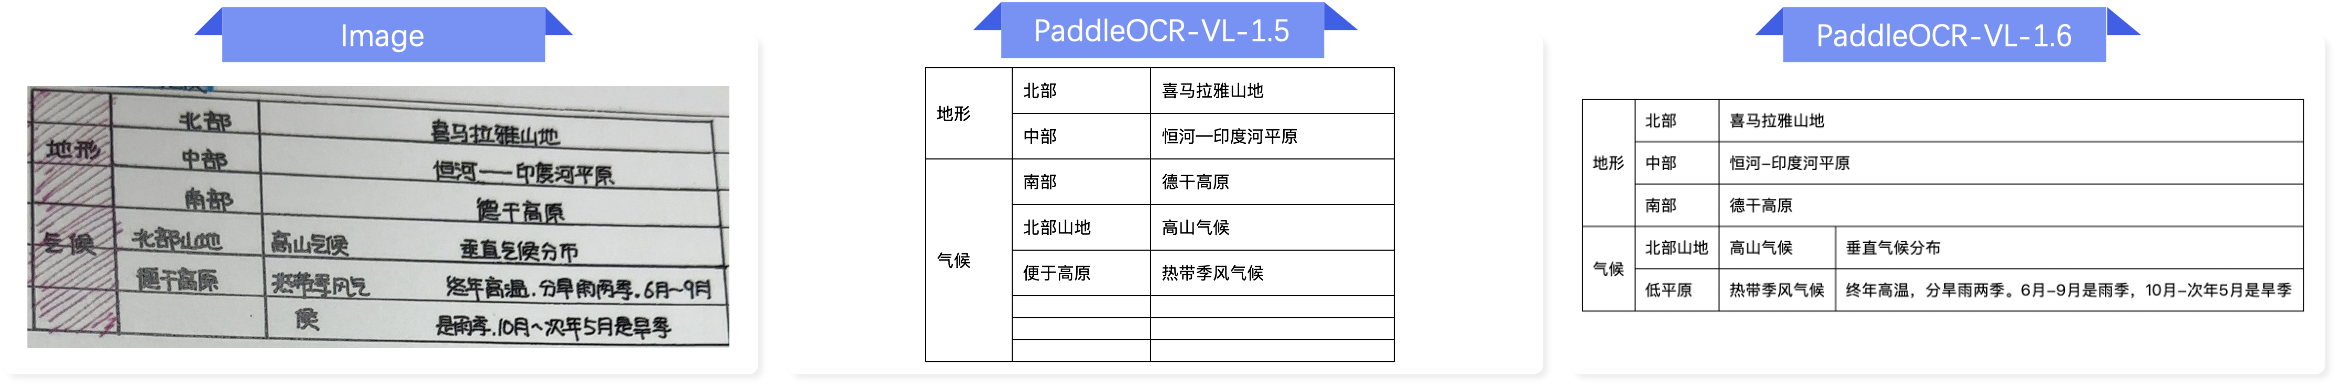
+### Table Recognition
+
+
+
+

+
+
+
+

+
+
+
+

+
+
diff --git a/docs/version3.x/algorithm/PaddleOCR-VL/PaddleOCR-VL-1.6.md b/docs/version3.x/algorithm/PaddleOCR-VL/PaddleOCR-VL-1.6.md
new file mode 100644
index 0000000000..d5e7adc984
--- /dev/null
+++ b/docs/version3.x/algorithm/PaddleOCR-VL/PaddleOCR-VL-1.6.md
@@ -0,0 +1,147 @@
+## 1. PaddleOCR-VL-1.6 简介
+
+**PaddleOCR-VL-1.6** 在 PaddleOCR-VL-1.5 的基础上进一步优化,通过系统分析当前模型中的欠优化区域,进行针对性数据优化,并采用精细化的后训练策略,在文档解析基准 OmniDocBench v1.6 上取得 96.33% 的最新 SOTA(最佳)结果。同时,PaddleOCR-VL-1.6 在面向真实世界物理畸变鲁棒性的 Real5-OmniDocBench 基准测试中,也在各个场景下均达到 SOTA 性能。此外,在印章识别、文字检测识别和图表识别三个子任务上,PaddleOCR-VL-1.6 均领先 PaddleOCR-VL-1.5,同时依然保持 0.9B 超紧凑 VLM 参数量和高效率。
+
+### **关键指标:**
+
+
+

+
+
+
+### **核心特性:**
+
+1. **文档解析的SOTA性能:** 凭借 0.9B 的参数量,PaddleOCR-VL-1.6 在 OmniDocBench v1.6 上达到了 96.33% 的准确率,超越了之前的 SOTA 模型 PaddleOCR-VL-1.5。在表格、公式和文本识别方面观察到了显著提升。
+
+2. **现实5大场景文档解析的SOTA性能:** 具备更强的鲁棒性和真实场景的实用性。在扫描、弯曲、倾斜、屏摄和光照变化这五个真实扰动场景的评估中,表现优于主流的开源和闭源模型。
+
+3. **强化多元素识别能力:** 除了版面解析能力的提升外,PaddleOCR-VL-1.6 进一步大幅度增强了对复杂表格,古籍 和 生僻字的识别能力,同时在 图表解析,印章识别,文字检测识别这三个原有能力上进一步提升。
+
+4. **0.9B紧凑架构:** 沿用 PaddleOCR-VL系列的 0.9B 紧凑构架,零成本适配,即换即用。
+
+
+## 二、技术架构
+
+
+

+
+
+1. **数据引擎:** 以 PaddleOCR-VL-1.5 为出发点,系统性定位 PaddleOCR-VL-1.5 的欠优化区域,并设计高质量标签获取策略,针对性的进行数据优化。
+2. **渐进式后训练策略** 从质量,难度,提升价值三个角度精细化划分数据,加载 PaddleOCR-VL-1.5 训练权重,结合不同的数据质量进行 继续预训练,监督微调,强化学习 三阶段的后训练策略,稳步提升模型性能。
+
+
+## 三、 模型性能
+
+### 1. OmniDocBench v1.6
+
+#### PaddleOCR-VL-1.6 在 OmniDocBench v1.6 上的整体指标、文本、公式、表格均达到最先进的性能,其中在在阅读顺序方面,PaddleOCR-VL-1.6也取得了较为领先的指标。
+
+
+
+

+
+
+> **注:**
+> - 性能指标引自 [OmniDocBench 官方排行榜](https://opendatalab.com/omnidocbench)。
+
+
+### 2. Real5-OmniDocBench
+
+#### 在扫描、扭曲、屏摄、光照和倾斜这五个多样化且具挑战性的场景中,PaddleOCR-VL-1.6 均创下了新的 SOTA 记录。
+
+
+
+

+
+
+> **注:**
+> - Real5-OmniDocBench 是 PaddleOCR团队 基于 OmniDocBench v1.5 数据集构建的、面向真实场景的全新基准测试。该数据集包含五个不同场景:扫描 (Scanning)、扭曲 (Warping)、屏摄 (Screen-photography)、光照 (Illumination) 和倾斜 (Skew)。更多详情请参阅 [Real5-OmniDocBench](https://huggingface.co/datasets/PaddlePaddle/Real5-OmniDocBench).
+
+
+
+## 四、推理部署性能
+
+PaddleOCR-VL-1.6 和 PaddleOCR-VL-1.5 采用完全相同的模型架构设计,因此有完全相同的推理速度。关于PaddleOCR-VL-1.5推理速度的说明可以参考 [PaddleOCR-VL-1.5推理速度](./PaddleOCR-VL-1.5.md#4推理部署性能) 。
+
+
+## 5. 可视化
+
+### 和 PaddleOCR-VL-1.5 的对比
+
+
+#### 古籍识别
+
+
+

+
+
+
+

+
+
+
+

+
+
+
+#### 图表解析
+
+
+

+
+
+
+

+
+
+
+#### 公式识别
+
+
+

+
+
+
+

+
+
+
+

+
+
+#### 生僻字识别
+
+
+

+
+
+
+

+
+
+#### 印章识别
+
+
+

+
+
+
+

+
+
+
+### 表格识别
+
+
+
+

+
+
+
+

+
+
+
+

+
+
diff --git a/mkdocs.yml b/mkdocs.yml
index 9527f1eed3..6a64d1ed04 100644
--- a/mkdocs.yml
+++ b/mkdocs.yml
@@ -9,7 +9,7 @@ repo_url: https://github.com/PaddlePaddle/PaddleOCR
copyright: Copyright © 2024 Maintained by PaddleOCR PMC.
-edit_uri: !ENV [DOCS_EDIT_URI, edit/main/docs/]
+edit_uri: edit/main/docs/
theme:
name: material
@@ -332,6 +332,7 @@ nav:
- PaddleOCR-VL:
- 使用教程: version3.x/pipeline_usage/PaddleOCR-VL.md
- PaddleOCR-VL-1.5简介: version3.x/algorithm/PaddleOCR-VL/PaddleOCR-VL-1.5.md
+ - PaddleOCR-VL-1.6简介: version3.x/algorithm/PaddleOCR-VL/PaddleOCR-VL-1.6.md
- PaddleOCR-VL简介: version3.x/algorithm/PaddleOCR-VL/PaddleOCR-VL.md
- PaddleOCR-VL NVIDIA Blackwell 架构 GPU 使用教程: version3.x/pipeline_usage/PaddleOCR-VL-NVIDIA-Blackwell.md
- PaddleOCR-VL 昆仑芯 XPU 使用教程: version3.x/pipeline_usage/PaddleOCR-VL-Kunlunxin-XPU.md