@@ -26,6 +47,8 @@ Layout recovery combines [layout analysis](../layout/README.md)、[table recogni
## 2. Install
@@ -61,17 +84,47 @@ git clone https://gitee.com/paddlepaddle/PaddleOCR
# Note: Code cloud hosting code may not be able to synchronize the update of this github project in real time, there is a delay of 3 to 5 days, please use the recommended method first.
````
-- **(2) Install recovery's `requirements`**
+- **(2) Install recovery `requirements`**
-The layout restoration is exported as docx and PDF files, so python-docx and docx2pdf API need to be installed, and PyMuPDF api([requires Python >= 3.7](https://pypi.org/project/PyMuPDF/)) need to be installed to process the input files in pdf format.
+The layout restoration is exported as docx files, so python-docx API need to be installed, and PyMuPDF api([requires Python >= 3.7](https://pypi.org/project/PyMuPDF/)) need to be installed to process the input files in pdf format.
+
+Install all the libraries by running the following command:
```bash
python3 -m pip install -r ppstructure/recovery/requirements.txt
````
+ And if using pdf parse method, we need to install pdf2docx api.
+
+```bash
+wget https://paddleocr.bj.bcebos.com/whl/pdf2docx-0.0.0-py3-none-any.whl
+pip3 install pdf2docx-0.0.0-py3-none-any.whl
+```
+
-## 3. Quick Start
+## 3. Quick Start using standard PDF parse
+
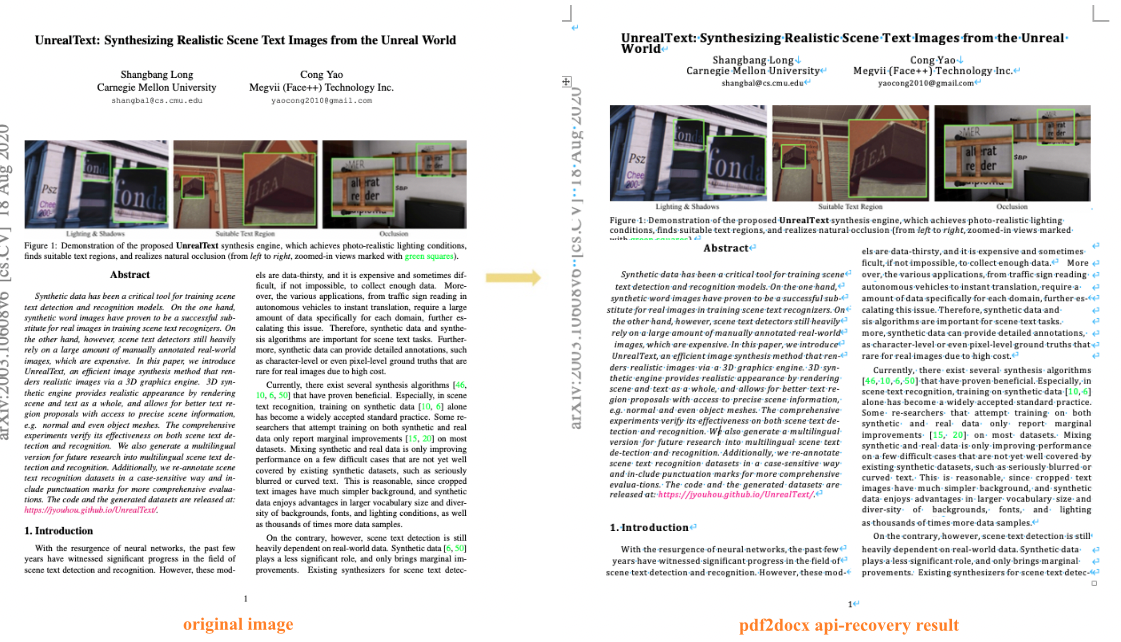
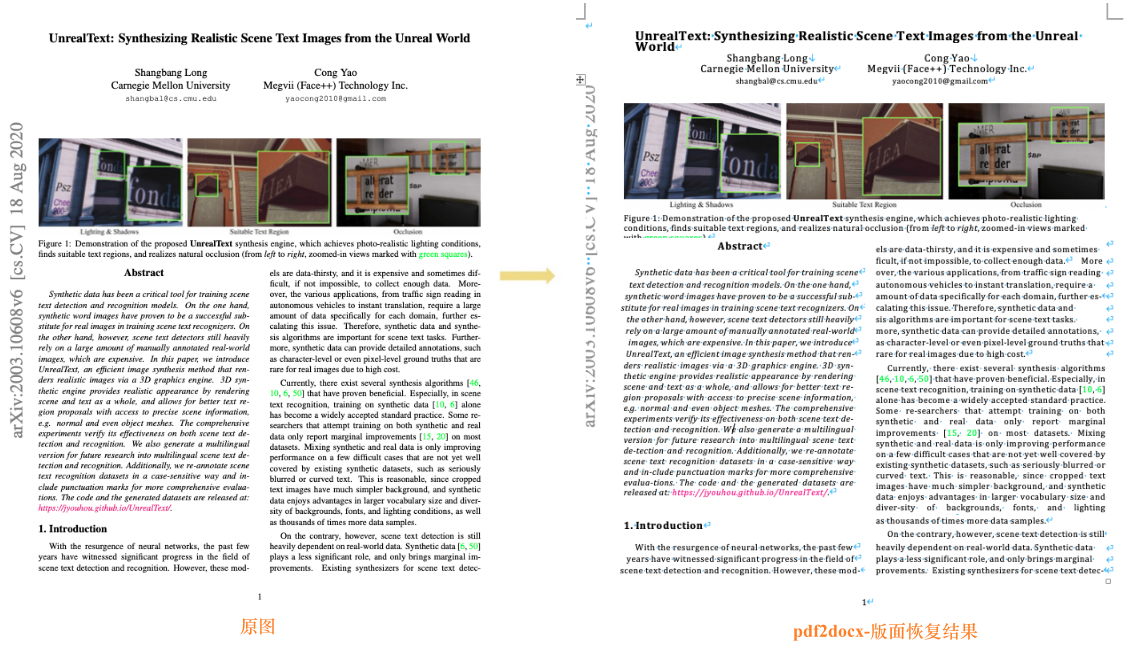
+`use_pdf2docx_api` use PDF parse for layout recovery, The whl package is also provided for quick use, follow the above code, for more infomation please refer to [quickstart](../docs/quickstart_en.md) for details.
+
+```bash
+# install paddleocr
+pip3 install "paddleocr>=2.6"
+paddleocr --image_dir=ppstructure/recovery/UnrealText.pdf --type=structure --recovery=true --use_pdf2docx_api=true
+```
+
+Command line:
+
+```bash
+python3 predict_system.py \
+ --image_dir=ppstructure/recovery/UnrealText.pdf \
+ --recovery=True \
+ --use_pdf2docx_api=True \
+ --output=../output/
+```
+
+
+## 4. Quick Start using image format PDF parse
Through layout analysis, we divided the image/PDF documents into regions, located the key regions, such as text, table, picture, etc., and recorded the location, category, and regional pixel value information of each region. Different regions are processed separately, where:
@@ -88,8 +141,8 @@ The whl package is also provided for quick use, follow the above code, for more
paddleocr --image_dir=ppstructure/docs/table/1.png --type=structure --recovery=true --lang='en'
```
-
+### 4.1 Download models
If input is English document, download English models:
@@ -111,10 +164,10 @@ tar xf picodet_lcnet_x1_0_fgd_layout_infer.tar
cd ..
```
If input is Chinese document,download Chinese models:
-[Chinese and English ultra-lightweight PP-OCRv3 model](https://github.com/PaddlePaddle/PaddleOCR/blob/dygraph/README.md#pp-ocr-series-model-listupdate-on-september-8th)、[表格识别模型](https://github.com/PaddlePaddle/PaddleOCR/blob/dygraph/ppstructure/docs/models_list.md#22-表格识别模型)、[版面分析模型](https://github.com/PaddlePaddle/PaddleOCR/blob/dygraph/ppstructure/docs/models_list.md#1-版面分析模型)
+[Chinese and English ultra-lightweight PP-OCRv3 model](https://github.com/PaddlePaddle/PaddleOCR/blob/dygraph/README.md#pp-ocr-series-model-listupdate-on-september-8th)、[table recognition model](https://github.com/PaddlePaddle/PaddleOCR/blob/dygraph/ppstructure/docs/models_list.md#22-表格识别模型)、[layout analysis model](https://github.com/PaddlePaddle/PaddleOCR/blob/dygraph/ppstructure/docs/models_list.md#1-版面分析模型)
-
+### 4.2 Layout recovery
```bash
@@ -129,7 +182,6 @@ python3 predict_system.py \
--layout_dict_path=../ppocr/utils/dict/layout_dict/layout_publaynet_dict.txt \
--vis_font_path=../doc/fonts/simfang.ttf \
--recovery=True \
- --save_pdf=False \
--output=../output/
```
@@ -137,7 +189,7 @@ After running, the docx of each picture will be saved in the directory specified
Field:
-- image_dir:test file测试文件, can be picture, picture directory, pdf file, pdf file directory
+- image_dir:test file, can be picture, picture directory, pdf file, pdf file directory
- det_model_dir:OCR detection model path
- rec_model_dir:OCR recognition model path
- rec_char_dict_path:OCR recognition dict path. If the Chinese model is used, change to "../ppocr/utils/ppocr_keys_v1.txt". And if you trained the model on your own dataset, change to the trained dictionary
@@ -146,12 +198,11 @@ Field:
- layout_model_dir:layout analysis model path
- layout_dict_path:layout analysis dict path. If the Chinese model is used, change to "../ppocr/utils/dict/layout_dict/layout_cdla_dict.txt"
- recovery:whether to enable layout of recovery, default False
-- save_pdf:when recovery file, whether to save pdf file, default False
- output:save the recovery result path
-
-## 4. More
+## 5. More
For training, evaluation and inference tutorial for text detection models, please refer to [text detection doc](https://github.com/PaddlePaddle/PaddleOCR/blob/dygraph/doc/doc_en/detection_en.md).
diff --git a/ppstructure/recovery/README_ch.md b/ppstructure/recovery/README_ch.md
index bc8913adca..5a60bd8190 100644
--- a/ppstructure/recovery/README_ch.md
+++ b/ppstructure/recovery/README_ch.md
@@ -6,19 +6,37 @@
- [2. 安装](#2)
- [2.1 安装PaddlePaddle](#2.1)
- [2.2 安装PaddleOCR](#2.2)
-- [3. 使用](#3)
- - [3.1 下载模型](#3.1)
- - [3.2 版面恢复](#3.2)
-- [4. 更多](#4)
-
+- [3.使用标准PDF解析进行版面恢复](#3)
+- [4. 使用图片格式PDF解析进行版面恢复](#4)
+ - [4.1 下载模型](#4.1)
+ - [4.2 版面恢复](#4.2)
+- [5. 更多](#5)
## 1. 简介
-版面恢复就是在OCR识别后,内容仍然像原文档图片那样排列着,段落不变、顺序不变的输出到word文档中等。
+版面恢复就是将输入的图片、pdf内容仍然像原文档那样排列着,段落不变、顺序不变的输出到word文档中等。
-版面恢复结合了[版面分析](../layout/README_ch.md)、[表格识别](../table/README_ch.md)技术,从而更好地恢复图片、表格、标题等内容,支持中、英文pdf文档、文档图片格式的输入文件,下图分别展示了英文文档和中文文档版面恢复的效果:
+提供了2种版面恢复方法,可根据输入PDF的格式进行选择:
+
+- **标准PDF解析(输入须为标准PDF)**:基于Python的pdf转word库[pdf2docx](https://github.com/dothinking/pdf2docx)进行优化,该方法通过PyMuPDF获取页面元素,然后利用规则解析章节、段落、表格等布局及样式,最后通过python-docx将解析的内容元素重建到word文档中。
+- **图片格式PDF解析(输入可为标准PDF或图片格式PDF)**:结合[版面分析](../layout/README_ch.md)、[表格识别](../table/README_ch.md)技术,从而更好地恢复图片、表格、标题等内容,支持中、英文pdf文档、文档图片格式的输入文件。
+
+2种方法输入格式、适用场景如下:
+
+| 方法 | 支持输入文件 | 适用场景/存在问题 |
+| :-------------: | :----------: | :----------------------------------------------------------: |
+| 标准PDF解析 | pdf | 优点:非论文文档恢复效果更优、每一页内容恢复后仍在同一页
缺点:有些中文文档中的英文乱码、仍存在内容超出当前页面的情况、整页内容恢复为表格格式、部分图片恢复效果不佳 |
+| 图片格式PDF解析 | pdf、图片 | 优点:更适合论文文档正文内容的恢复、中英文文档OCR识别效果好

@@ -64,15 +82,46 @@ git clone https://gitee.com/paddlepaddle/PaddleOCR
- **(2)安装recovery的`requirements`**
-版面恢复导出为docx、pdf文件,所以需要安装python-docx、docx2pdf API,同时处理pdf格式的输入文件,需要安装PyMuPDF API([要求Python >= 3.7](https://pypi.org/project/PyMuPDF/))。
+版面恢复导出为docx文件,所以需要安装Python处理word文档的python-docx API,同时处理pdf格式的输入文件,需要安装PyMuPDF API([要求Python >= 3.7](https://pypi.org/project/PyMuPDF/))。
+
+通过如下命令安装全部库:
```bash
python3 -m pip install -r ppstructure/recovery/requirements.txt
```
+使用pdf2docx库解析的方式恢复文档需要安装优化的pdf2docx。
+
+```bash
+wget https://paddleocr.bj.bcebos.com/whl/pdf2docx-0.0.0-py3-none-any.whl
+pip3 install pdf2docx-0.0.0-py3-none-any.whl
+```
+
-## 3. 使用
+## 3.使用标准PDF解析进行版面恢复
+
+`use_pdf2docx_api`表示使用PDF解析的方式进行版面恢复,通过whl包的形式方便快速使用,代码如下,更多信息详见 [quickstart](../docs/quickstart.md)。
+
+```bash
+# 安装 paddleocr,推荐使用2.6版本
+pip3 install "paddleocr>=2.6"
+paddleocr --image_dir=ppstructure/recovery/UnrealText.pdf --type=structure --recovery=true --use_pdf2docx_api=true
+```
+
+通过命令行的方式:
+
+```bash
+python3 predict_system.py \
+ --image_dir=ppstructure/recovery/UnrealText.pdf \
+ --recovery=True \
+ --use_pdf2docx_api=True \
+ --output=../output/
+```
+
+
+
+## 4.使用图片格式PDF解析进行版面恢复
我们通过版面分析对图片/pdf形式的文档进行区域划分,定位其中的关键区域,如文字、表格、图片等,记录每个区域的位置、类别、区域像素值信息。对不同的区域分别处理,其中:
@@ -86,6 +135,8 @@ python3 -m pip install -r ppstructure/recovery/requirements.txt
提供如下代码实现版面恢复,也提供了whl包的形式方便快速使用,代码如下,更多信息详见 [quickstart](../docs/quickstart.md)。
```bash
+# 安装 paddleocr,推荐使用2.6版本
+pip3 install "paddleocr>=2.6"
# 中文测试图
paddleocr --image_dir=ppstructure/docs/table/1.png --type=structure --recovery=true
# 英文测试图
@@ -94,9 +145,9 @@ paddleocr --image_dir=ppstructure/docs/table/1.png --type=structure --recovery=t
paddleocr --image_dir=ppstructure/recovery/UnrealText.pdf --type=structure --recovery=true --lang='en'
```
-
+
-### 3.1 下载模型
+### 4.1 下载模型
如果输入为英文文档类型,下载OCR检测和识别、版面分析、表格识别的英文模型
@@ -122,9 +173,9 @@ cd ..
[PP-OCRv3中英文超轻量文本检测和识别模型](https://github.com/PaddlePaddle/PaddleOCR/blob/dygraph/README_ch.md#pp-ocr%E7%B3%BB%E5%88%97%E6%A8%A1%E5%9E%8B%E5%88%97%E8%A1%A8%E6%9B%B4%E6%96%B0%E4%B8%AD)、[表格识别模型](https://github.com/PaddlePaddle/PaddleOCR/blob/dygraph/ppstructure/docs/models_list.md#22-表格识别模型)、[版面分析模型](https://github.com/PaddlePaddle/PaddleOCR/blob/dygraph/ppstructure/docs/models_list.md#1-版面分析模型)
-
+
-### 3.2 版面恢复
+### 4.2 版面恢复
使用下载的模型恢复给定文档的版面,以英文模型为例,执行如下命令:
@@ -140,7 +191,6 @@ python3 predict_system.py \
--layout_dict_path=../ppocr/utils/dict/layout_dict/layout_publaynet_dict.txt \
--vis_font_path=../doc/fonts/simfang.ttf \
--recovery=True \
- --save_pdf=False \
--output=../output/
```
@@ -157,12 +207,11 @@ python3 predict_system.py \
- layout_model_dir:版面分析模型路径
- layout_dict_path:版面分析字典,如果更换为中文模型,需要更改为"../ppocr/utils/dict/layout_dict/layout_cdla_dict.txt"
- recovery:是否进行版面恢复,默认False
-- save_pdf:进行版面恢复导出docx文档的同时,是否保存为pdf文件,默认为False
- output:版面恢复结果保存路径
-
+
-## 4. 更多
+## 5. 更多
关于OCR检测模型的训练评估与推理,请参考:[文本检测教程](https://github.com/PaddlePaddle/PaddleOCR/blob/dygraph/doc/doc_ch/detection.md)
diff --git a/ppstructure/recovery/requirements.txt b/ppstructure/recovery/requirements.txt
index 7ddc339133..4e4239a14a 100644
--- a/ppstructure/recovery/requirements.txt
+++ b/ppstructure/recovery/requirements.txt
@@ -1,3 +1,5 @@
python-docx
-PyMuPDF
-beautifulsoup4
\ No newline at end of file
+PyMuPDF==1.19.0
+beautifulsoup4
+fonttools>=4.24.0
+fire>=0.3.0
\ No newline at end of file
diff --git a/ppstructure/table/predict_structure.py b/ppstructure/table/predict_structure.py
index 0bf100852b..08e381a846 100755
--- a/ppstructure/table/predict_structure.py
+++ b/ppstructure/table/predict_structure.py
@@ -68,6 +68,7 @@ def build_pre_process_list(args):
class TableStructurer(object):
def __init__(self, args):
+ self.args = args
self.use_onnx = args.use_onnx
pre_process_list = build_pre_process_list(args)
if args.table_algorithm not in ['TableMaster']:
@@ -89,8 +90,31 @@ class TableStructurer(object):
self.predictor, self.input_tensor, self.output_tensors, self.config = \
utility.create_predictor(args, 'table', logger)
+ if args.benchmark:
+ import auto_log
+ pid = os.getpid()
+ gpu_id = utility.get_infer_gpuid()
+ self.autolog = auto_log.AutoLogger(
+ model_name="table",
+ model_precision=args.precision,
+ batch_size=1,
+ data_shape="dynamic",
+ save_path=None, #args.save_log_path,
+ inference_config=self.config,
+ pids=pid,
+ process_name=None,
+ gpu_ids=gpu_id if args.use_gpu else None,
+ time_keys=[
+ 'preprocess_time', 'inference_time', 'postprocess_time'
+ ],
+ warmup=0,
+ logger=logger)
+
def __call__(self, img):
starttime = time.time()
+ if self.args.benchmark:
+ self.autolog.times.start()
+
ori_im = img.copy()
data = {'image': img}
data = transform(data, self.preprocess_op)
@@ -99,6 +123,8 @@ class TableStructurer(object):
return None, 0
img = np.expand_dims(img, axis=0)
img = img.copy()
+ if self.args.benchmark:
+ self.autolog.times.stamp()
if self.use_onnx:
input_dict = {}
input_dict[self.input_tensor.name] = img
@@ -110,6 +136,8 @@ class TableStructurer(object):
for output_tensor in self.output_tensors:
output = output_tensor.copy_to_cpu()
outputs.append(output)
+ if self.args.benchmark:
+ self.autolog.times.stamp()
preds = {}
preds['structure_probs'] = outputs[1]
@@ -125,6 +153,8 @@ class TableStructurer(object):
'', '', '
'
] + structure_str_list + ['
', '', '']
elapse = time.time() - starttime
+ if self.args.benchmark:
+ self.autolog.times.end(stamp=True)
return (structure_str_list, bbox_list), elapse
@@ -164,6 +194,8 @@ def main(args):
total_time += elapse
count += 1
logger.info("Predict time of {}: {}".format(image_file, elapse))
+ if args.benchmark:
+ table_structurer.autolog.report()
if __name__ == "__main__":
diff --git a/ppstructure/table/predict_table.py b/ppstructure/table/predict_table.py
index aeec66deca..8f9c717490 100644
--- a/ppstructure/table/predict_table.py
+++ b/ppstructure/table/predict_table.py
@@ -14,7 +14,6 @@
import os
import sys
-import subprocess
__dir__ = os.path.dirname(os.path.abspath(__file__))
sys.path.append(__dir__)
@@ -58,48 +57,28 @@ def expand(pix, det_box, shape):
class TableSystem(object):
def __init__(self, args, text_detector=None, text_recognizer=None):
+ self.args = args
if not args.show_log:
logger.setLevel(logging.INFO)
-
- self.text_detector = predict_det.TextDetector(
- args) if text_detector is None else text_detector
- self.text_recognizer = predict_rec.TextRecognizer(
- args) if text_recognizer is None else text_recognizer
-
+ args.benchmark = False
+ self.text_detector = predict_det.TextDetector(copy.deepcopy(
+ args)) if text_detector is None else text_detector
+ self.text_recognizer = predict_rec.TextRecognizer(copy.deepcopy(
+ args)) if text_recognizer is None else text_recognizer
+ args.benchmark = True
self.table_structurer = predict_strture.TableStructurer(args)
if args.table_algorithm in ['TableMaster']:
self.match = TableMasterMatcher()
else:
self.match = TableMatch(filter_ocr_result=True)
- self.benchmark = args.benchmark
self.predictor, self.input_tensor, self.output_tensors, self.config = utility.create_predictor(
args, 'table', logger)
- if args.benchmark:
- import auto_log
- pid = os.getpid()
- gpu_id = utility.get_infer_gpuid()
- self.autolog = auto_log.AutoLogger(
- model_name="table",
- model_precision=args.precision,
- batch_size=1,
- data_shape="dynamic",
- save_path=None, #args.save_log_path,
- inference_config=self.config,
- pids=pid,
- process_name=None,
- gpu_ids=gpu_id if args.use_gpu else None,
- time_keys=[
- 'preprocess_time', 'inference_time', 'postprocess_time'
- ],
- warmup=0,
- logger=logger)
def __call__(self, img, return_ocr_result_in_table=False):
result = dict()
time_dict = {'det': 0, 'rec': 0, 'table': 0, 'all': 0, 'match': 0}
start = time.time()
-
structure_res, elapse = self._structure(copy.deepcopy(img))
result['cell_bbox'] = structure_res[1].tolist()
time_dict['table'] = elapse
@@ -118,24 +97,16 @@ class TableSystem(object):
toc = time.time()
time_dict['match'] = toc - tic
result['html'] = pred_html
- if self.benchmark:
- self.autolog.times.end(stamp=True)
end = time.time()
time_dict['all'] = end - start
- if self.benchmark:
- self.autolog.times.stamp()
return result, time_dict
def _structure(self, img):
- if self.benchmark:
- self.autolog.times.start()
structure_res, elapse = self.table_structurer(copy.deepcopy(img))
return structure_res, elapse
def _ocr(self, img):
h, w = img.shape[:2]
- if self.benchmark:
- self.autolog.times.stamp()
dt_boxes, det_elapse = self.text_detector(copy.deepcopy(img))
dt_boxes = sorted_boxes(dt_boxes)
@@ -233,12 +204,13 @@ def main(args):
f_html.close()
if args.benchmark:
- text_sys.autolog.report()
+ table_sys.table_structurer.autolog.report()
if __name__ == "__main__":
args = parse_args()
if args.use_mp:
+ import subprocess
p_list = []
total_process_num = args.total_process_num
for process_id in range(total_process_num):
diff --git a/ppstructure/utility.py b/ppstructure/utility.py
index 7f8a06d2ec..d909f1a8a1 100644
--- a/ppstructure/utility.py
+++ b/ppstructure/utility.py
@@ -93,6 +93,11 @@ def init_args():
type=str2bool,
default=False,
help='Whether to enable layout of recovery')
+ parser.add_argument(
+ "--use_pdf2docx_api",
+ type=str2bool,
+ default=False,
+ help='Whether to use pdf2docx api')
return parser
diff --git a/requirements.txt b/requirements.txt
index d795e06f0f..8c5b12f831 100644
--- a/requirements.txt
+++ b/requirements.txt
@@ -16,4 +16,4 @@ openpyxl
attrdict
Polygon3
lanms-neo==1.0.2
-PyMuPDF==1.18.7
+PyMuPDF==1.19.0
\ No newline at end of file
diff --git a/test_tipc/configs/layoutxlm_ser/train_pact_infer_python.txt b/test_tipc/configs/layoutxlm_ser/train_pact_infer_python.txt
index fbf2a88026..c19b4b73a9 100644
--- a/test_tipc/configs/layoutxlm_ser/train_pact_infer_python.txt
+++ b/test_tipc/configs/layoutxlm_ser/train_pact_infer_python.txt
@@ -7,14 +7,14 @@ Global.auto_cast:fp32
Global.epoch_num:lite_train_lite_infer=1|whole_train_whole_infer=17
Global.save_model_dir:./output/
Train.loader.batch_size_per_card:lite_train_lite_infer=4|whole_train_whole_infer=8
-Architecture.Backbone.checkpoints:pretrain_models/ser_LayoutXLM_xfun_zh
+Architecture.Backbone.pretrained:pretrain_models/ser_LayoutXLM_xfun_zh
train_model_name:latest
train_infer_img_dir:ppstructure/docs/kie/input/zh_val_42.jpg
null:null
##
trainer:pact_train
norm_train:null
-pact_train:deploy/slim/quantization/quant.py -c test_tipc/configs/layoutxlm_ser/ser_layoutxlm_xfund_zh.yml -o
+pact_train:deploy/slim/quantization/quant.py -c test_tipc/configs/layoutxlm_ser/ser_layoutxlm_xfund_zh.yml -o Global.eval_batch_step=[2000,10]
fpgm_train:null
distill_train:null
null:null
diff --git a/test_tipc/configs/rec_d28_can/rec_d28_can.yml b/test_tipc/configs/rec_d28_can/rec_d28_can.yml
new file mode 100644
index 0000000000..5501865863
--- /dev/null
+++ b/test_tipc/configs/rec_d28_can/rec_d28_can.yml
@@ -0,0 +1,122 @@
+Global:
+ use_gpu: True
+ epoch_num: 240
+ log_smooth_window: 20
+ print_batch_step: 10
+ save_model_dir: ./output/rec/can/
+ save_epoch_step: 1
+ # evaluation is run every 1105 iterations (1 epoch)(batch_size = 8)
+ eval_batch_step: [0, 1105]
+ cal_metric_during_train: True
+ pretrained_model:
+ checkpoints:
+ save_inference_dir:
+ use_visualdl: False
+ infer_img: doc/datasets/crohme_demo/hme_00.jpg
+ # for data or label process
+ character_dict_path: ppocr/utils/dict/latex_symbol_dict.txt
+ max_text_length: 36
+ infer_mode: False
+ use_space_char: False
+ save_res_path: ./output/rec/predicts_can.txt
+
+Optimizer:
+ name: Momentum
+ momentum: 0.9
+ clip_norm_global: 100.0
+ lr:
+ name: TwoStepCosine
+ learning_rate: 0.01
+ warmup_epoch: 1
+ weight_decay: 0.0001
+
+Architecture:
+ model_type: rec
+ algorithm: CAN
+ in_channels: 1
+ Transform:
+ Backbone:
+ name: DenseNet
+ growthRate: 24
+ reduction: 0.5
+ bottleneck: True
+ use_dropout: True
+ input_channel: 1
+ Head:
+ name: CANHead
+ in_channel: 684
+ out_channel: 111
+ max_text_length: 36
+ ratio: 16
+ attdecoder:
+ is_train: True
+ input_size: 256
+ hidden_size: 256
+ encoder_out_channel: 684
+ dropout: True
+ dropout_ratio: 0.5
+ word_num: 111
+ counting_decoder_out_channel: 111
+ attention:
+ attention_dim: 512
+ word_conv_kernel: 1
+
+Loss:
+ name: CANLoss
+
+PostProcess:
+ name: CANLabelDecode
+
+Metric:
+ name: CANMetric
+ main_indicator: exp_rate
+
+Train:
+ dataset:
+ name: SimpleDataSet
+ data_dir: ./train_data/CROHME_lite/training/images/
+ label_file_list: ["./train_data/CROHME_lite/training/labels.txt"]
+ transforms:
+ - DecodeImage:
+ channel_first: False
+ - NormalizeImage:
+ mean: [0,0,0]
+ std: [1,1,1]
+ order: 'hwc'
+ - GrayImageChannelFormat:
+ inverse: True
+ - CANLabelEncode:
+ lower: False
+ - KeepKeys:
+ keep_keys: ['image', 'label']
+ loader:
+ shuffle: True
+ batch_size_per_card: 8
+ drop_last: False
+ num_workers: 4
+ collate_fn: DyMaskCollator
+
+Eval:
+ dataset:
+ name: SimpleDataSet
+ data_dir: ./train_data/CROHME_lite/evaluation/images/
+ label_file_list: ["./train_data/CROHME_lite/evaluation/labels.txt"]
+ transforms:
+ - DecodeImage:
+ channel_first: False
+ - NormalizeImage:
+ mean: [0,0,0]
+ std: [1,1,1]
+ order: 'hwc'
+ - GrayImageChannelFormat:
+ inverse: True
+ - CANLabelEncode:
+ lower: False
+ - KeepKeys:
+ keep_keys: ['image', 'label']
+ loader:
+ shuffle: False
+ drop_last: False
+ batch_size_per_card: 1
+ num_workers: 4
+ collate_fn: DyMaskCollator
diff --git a/test_tipc/configs/rec_d28_can/train_infer_python.txt b/test_tipc/configs/rec_d28_can/train_infer_python.txt
new file mode 100644
index 0000000000..731d327cd0
--- /dev/null
+++ b/test_tipc/configs/rec_d28_can/train_infer_python.txt
@@ -0,0 +1,53 @@
+===========================train_params===========================
+model_name:rec_d28_can
+python:python3.7
+gpu_list:0|0,1
+Global.use_gpu:True|True
+Global.auto_cast:null
+Global.epoch_num:lite_train_lite_infer=2|whole_train_whole_infer=240
+Global.save_model_dir:./output/
+Train.loader.batch_size_per_card:lite_train_lite_infer=2|whole_train_whole_infer=8
+Global.pretrained_model:null
+train_model_name:latest
+train_infer_img_dir:./doc/datasets/crohme_demo
+null:null
+##
+trainer:norm_train
+norm_train:tools/train.py -c test_tipc/configs/rec_d28_can/rec_d28_can.yml -o
+pact_train:null
+fpgm_train:null
+distill_train:null
+null:null
+null:null
+##
+===========================eval_params===========================
+eval:tools/eval.py -c test_tipc/configs/rec_d28_can/rec_d28_can.yml -o
+null:null
+##
+===========================infer_params===========================
+Global.save_inference_dir:./output/
+Global.checkpoints:
+norm_export:tools/export_model.py -c test_tipc/configs/rec_d28_can/rec_d28_can.yml -o
+quant_export:null
+fpgm_export:null
+distill_export:null
+export1:null
+export2:null
+##
+train_model:./inference/rec_d28_can_train/best_accuracy
+infer_export:tools/export_model.py -c test_tipc/configs/rec_d28_can/rec_d28_can.yml -o
+infer_quant:False
+inference:tools/infer/predict_rec.py --rec_char_dict_path=./ppocr/utils/dict/latex_symbol_dict.txt --rec_algorithm="CAN"
+--use_gpu:True|False
+--enable_mkldnn:False
+--cpu_threads:6
+--rec_batch_num:1
+--use_tensorrt:False
+--precision:fp32
+--rec_model_dir:
+--image_dir:./doc/datasets/crohme_demo
+--save_log_path:./test/output/
+--benchmark:True
+null:null
+===========================infer_benchmark_params==========================
+random_infer_input:[{float32,[1,100,100]}]
diff --git a/test_tipc/configs/slanet/train_pact_infer_python.txt b/test_tipc/configs/slanet/train_pact_infer_python.txt
index 42ed0cf599..98546afa69 100644
--- a/test_tipc/configs/slanet/train_pact_infer_python.txt
+++ b/test_tipc/configs/slanet/train_pact_infer_python.txt
@@ -34,7 +34,7 @@ distill_export:null
export1:null
export2:null
##
-infer_model:./inference/en_ppocr_mobile_v2.0_table_structure_infer
+infer_model:./inference/en_ppstructure_mobile_v2.0_SLANet_infer
infer_export:null
infer_quant:True
inference:ppstructure/table/predict_table.py --det_model_dir=./inference/en_ppocr_mobile_v2.0_table_det_infer --rec_model_dir=./inference/en_ppocr_mobile_v2.0_table_rec_infer --rec_char_dict_path=./ppocr/utils/dict/table_dict.txt --table_char_dict_path=./ppocr/utils/dict/table_structure_dict.txt --image_dir=./ppstructure/docs/table/table.jpg --det_limit_side_len=736 --det_limit_type=min --output ./output/table
diff --git a/test_tipc/prepare.sh b/test_tipc/prepare.sh
index 346e9b1dff..b76332af93 100644
--- a/test_tipc/prepare.sh
+++ b/test_tipc/prepare.sh
@@ -146,6 +146,7 @@ if [ ${MODE} = "lite_train_lite_infer" ];then
python_name=${array[0]}
${python_name} -m pip install -r requirements.txt
${python_name} -m pip install https://paddleocr.bj.bcebos.com/libs/auto_log-1.2.0-py3-none-any.whl
+ ${python_name} -m pip install paddleslim
# pretrain lite train data
wget -nc -P ./pretrain_models/ https://paddle-imagenet-models-name.bj.bcebos.com/dygraph/MobileNetV3_large_x0_5_pretrained.pdparams --no-check-certificate
wget -nc -P ./pretrain_models/ https://paddleocr.bj.bcebos.com/dygraph_v2.0/en/det_mv3_db_v2.0_train.tar --no-check-certificate
@@ -241,6 +242,9 @@ if [ ${MODE} = "lite_train_lite_infer" ];then
if [ ${model_name} == "ch_ppocr_mobile_v2_0_det_FPGM" ]; then
${python_name} -m pip install paddleslim
fi
+ if [ ${model_name} == "det_r50_vd_pse_v2_0" ]; then
+ wget -nc -P ./pretrain_models/ https://paddle-imagenet-models-name.bj.bcebos.com/dygraph/ResNet50_vd_ssld_pretrained.pdparams --no-check-certificate
+ fi
if [ ${model_name} == "det_mv3_east_v2_0" ]; then
wget -nc -P ./pretrain_models/ https://paddleocr.bj.bcebos.com/dygraph_v2.0/en/det_mv3_east_v2.0_train.tar --no-check-certificate
cd ./pretrain_models/ && tar xf det_mv3_east_v2.0_train.tar && cd ../
@@ -257,7 +261,7 @@ if [ ${MODE} = "lite_train_lite_infer" ];then
wget -nc -P ./pretrain_models/ https://paddleocr.bj.bcebos.com/rec_r32_gaspin_bilstm_att_train.tar --no-check-certificate
cd ./pretrain_models/ && tar xf rec_r32_gaspin_bilstm_att_train.tar && cd ../
fi
- if [ ${model_name} == "layoutxlm_ser" ]; then
+ if [[ ${model_name} =~ "layoutxlm_ser" ]]; then
${python_name} -m pip install -r ppstructure/kie/requirements.txt
${python_name} -m pip install opencv-python -U
wget -nc -P ./train_data/ https://paddleocr.bj.bcebos.com/ppstructure/dataset/XFUND.tar --no-check-certificate
@@ -286,6 +290,9 @@ if [ ${MODE} = "lite_train_lite_infer" ];then
if [ ${model_name} == "sr_telescope" ]; then
wget -nc -P ./train_data/ https://paddleocr.bj.bcebos.com/dataset/TextZoom.tar --no-check-certificate
cd ./train_data/ && tar xf TextZoom.tar && cd ../
+ if [ ${model_name} == "rec_d28_can" ]; then
+ wget -nc -P ./train_data/ https://paddleocr.bj.bcebos.com/dataset/CROHME_lite.tar --no-check-certificate
+ cd ./train_data/ && tar xf CROHME_lite.tar && cd ../
fi
elif [ ${MODE} = "whole_train_whole_infer" ];then
diff --git a/test_tipc/readme.md b/test_tipc/readme.md
index 1442ee1c86..9f02c2e308 100644
--- a/test_tipc/readme.md
+++ b/test_tipc/readme.md
@@ -44,6 +44,7 @@
| SAST |det_r50_vd_sast_totaltext_v2.0 | 检测 | 支持 | 多机多卡
混合精度 | - | - |
| Rosetta|rec_mv3_none_none_ctc_v2.0 | 识别 | 支持 | 多机多卡
混合精度 | - | - |
| Rosetta|rec_r34_vd_none_none_ctc_v2.0 | 识别 | 支持 | 多机多卡
混合精度 | - | - |
+| CAN |rec_d28_can | 识别 | 支持 | 多机多卡
混合精度 | - | - |
| CRNN |rec_mv3_none_bilstm_ctc_v2.0 | 识别 | 支持 | 多机多卡
混合精度 | - | - |
| CRNN |rec_r34_vd_none_bilstm_ctc_v2.0| 识别 | 支持 | 多机多卡
混合精度 | - | - |
| StarNet|rec_mv3_tps_bilstm_ctc_v2.0 | 识别 | 支持 | 多机多卡
混合精度 | - | - |
diff --git a/tools/eval.py b/tools/eval.py
index 3d1d3813d3..21f4d94d5e 100755
--- a/tools/eval.py
+++ b/tools/eval.py
@@ -74,7 +74,9 @@ def main():
config['Architecture']["Head"]['out_channels'] = char_num
model = build_model(config['Architecture'])
- extra_input_models = ["SRN", "NRTR", "SAR", "SEED", "SVTR", "VisionLAN", "RobustScanner"]
+ extra_input_models = [
+ "SRN", "NRTR", "SAR", "SEED", "SVTR", "VisionLAN", "RobustScanner"
+ ]
extra_input = False
if config['Architecture']['algorithm'] == 'Distillation':
for key in config['Architecture']["Models"]:
@@ -83,7 +85,10 @@ def main():
else:
extra_input = config['Architecture']['algorithm'] in extra_input_models
if "model_type" in config['Architecture'].keys():
- model_type = config['Architecture']['model_type']
+ if config['Architecture']['algorithm'] == 'CAN':
+ model_type = 'can'
+ else:
+ model_type = config['Architecture']['model_type']
else:
model_type = None
@@ -92,7 +97,7 @@ def main():
# amp
use_amp = config["Global"].get("use_amp", False)
amp_level = config["Global"].get("amp_level", 'O2')
- amp_custom_black_list = config['Global'].get('amp_custom_black_list',[])
+ amp_custom_black_list = config['Global'].get('amp_custom_black_list', [])
if use_amp:
AMP_RELATED_FLAGS_SETTING = {
'FLAGS_cudnn_batchnorm_spatial_persistent': 1,
@@ -120,7 +125,8 @@ def main():
# start eval
metric = program.eval(model, valid_dataloader, post_process_class,
- eval_class, model_type, extra_input, scaler, amp_level, amp_custom_black_list)
+ eval_class, model_type, extra_input, scaler,
+ amp_level, amp_custom_black_list)
logger.info('metric eval ***************')
for k, v in metric.items():
logger.info('{}:{}'.format(k, v))
diff --git a/tools/export_model.py b/tools/export_model.py
index 52f05bfcba..4b90fcae43 100755
--- a/tools/export_model.py
+++ b/tools/export_model.py
@@ -123,6 +123,17 @@ def export_single_model(model,
]
]
model = to_static(model, input_spec=other_shape)
+ elif arch_config["algorithm"] == "CAN":
+ other_shape = [[
+ paddle.static.InputSpec(
+ shape=[None, 1, None, None],
+ dtype="float32"), paddle.static.InputSpec(
+ shape=[None, 1, None, None], dtype="float32"),
+ paddle.static.InputSpec(
+ shape=[None, arch_config['Head']['max_text_length']],
+ dtype="int64")
+ ]]
+ model = to_static(model, input_spec=other_shape)
elif arch_config["algorithm"] in ["LayoutLM", "LayoutLMv2", "LayoutXLM"]:
input_spec = [
paddle.static.InputSpec(
diff --git a/tools/infer/predict_rec.py b/tools/infer/predict_rec.py
index bffeb25534..b3ef557c09 100755
--- a/tools/infer/predict_rec.py
+++ b/tools/infer/predict_rec.py
@@ -108,6 +108,13 @@ class TextRecognizer(object):
}
elif self.rec_algorithm == "PREN":
postprocess_params = {'name': 'PRENLabelDecode'}
+ elif self.rec_algorithm == "CAN":
+ self.inverse = args.rec_image_inverse
+ postprocess_params = {
+ 'name': 'CANLabelDecode',
+ "character_dict_path": args.rec_char_dict_path,
+ "use_space_char": args.use_space_char
+ }
self.postprocess_op = build_post_process(postprocess_params)
self.predictor, self.input_tensor, self.output_tensors, self.config = \
utility.create_predictor(args, 'rec', logger)
@@ -351,6 +358,30 @@ class TextRecognizer(object):
return resized_image
+ def norm_img_can(self, img, image_shape):
+
+ img = cv2.cvtColor(
+ img, cv2.COLOR_BGR2GRAY) # CAN only predict gray scale image
+
+ if self.inverse:
+ img = 255 - img
+
+ if self.rec_image_shape[0] == 1:
+ h, w = img.shape
+ _, imgH, imgW = self.rec_image_shape
+ if h < imgH or w < imgW:
+ padding_h = max(imgH - h, 0)
+ padding_w = max(imgW - w, 0)
+ img_padded = np.pad(img, ((0, padding_h), (0, padding_w)),
+ 'constant',
+ constant_values=(255))
+ img = img_padded
+
+ img = np.expand_dims(img, 0) / 255.0 # h,w,c -> c,h,w
+ img = img.astype('float32')
+
+ return img
+
def __call__(self, img_list):
img_num = len(img_list)
# Calculate the aspect ratio of all text bars
@@ -430,6 +461,17 @@ class TextRecognizer(object):
word_positions = np.array(range(0, 40)).astype('int64')
word_positions = np.expand_dims(word_positions, axis=0)
word_positions_list.append(word_positions)
+ elif self.rec_algorithm == "CAN":
+ norm_img = self.norm_img_can(img_list[indices[ino]],
+ max_wh_ratio)
+ norm_img = norm_img[np.newaxis, :]
+ norm_img_batch.append(norm_img)
+ norm_image_mask = np.ones(norm_img.shape, dtype='float32')
+ word_label = np.ones([1, 36], dtype='int64')
+ norm_img_mask_batch = []
+ word_label_list = []
+ norm_img_mask_batch.append(norm_image_mask)
+ word_label_list.append(word_label)
else:
norm_img = self.resize_norm_img(img_list[indices[ino]],
max_wh_ratio)
@@ -527,6 +569,33 @@ class TextRecognizer(object):
if self.benchmark:
self.autolog.times.stamp()
preds = outputs[0]
+ elif self.rec_algorithm == "CAN":
+ norm_img_mask_batch = np.concatenate(norm_img_mask_batch)
+ word_label_list = np.concatenate(word_label_list)
+ inputs = [norm_img_batch, norm_img_mask_batch, word_label_list]
+ if self.use_onnx:
+ input_dict = {}
+ input_dict[self.input_tensor.name] = norm_img_batch
+ outputs = self.predictor.run(self.output_tensors,
+ input_dict)
+ preds = outputs
+ else:
+ input_names = self.predictor.get_input_names()
+ input_tensor = []
+ for i in range(len(input_names)):
+ input_tensor_i = self.predictor.get_input_handle(
+ input_names[i])
+ input_tensor_i.copy_from_cpu(inputs[i])
+ input_tensor.append(input_tensor_i)
+ self.input_tensor = input_tensor
+ self.predictor.run()
+ outputs = []
+ for output_tensor in self.output_tensors:
+ output = output_tensor.copy_to_cpu()
+ outputs.append(output)
+ if self.benchmark:
+ self.autolog.times.stamp()
+ preds = outputs
else:
if self.use_onnx:
input_dict = {}
diff --git a/tools/infer/utility.py b/tools/infer/utility.py
index f6a44e35a5..34cad2590f 100644
--- a/tools/infer/utility.py
+++ b/tools/infer/utility.py
@@ -84,6 +84,7 @@ def init_args():
# params for text recognizer
parser.add_argument("--rec_algorithm", type=str, default='SVTR_LCNet')
parser.add_argument("--rec_model_dir", type=str)
+ parser.add_argument("--rec_image_inverse", type=str2bool, default=True)
parser.add_argument("--rec_image_shape", type=str, default="3, 48, 320")
parser.add_argument("--rec_batch_num", type=int, default=6)
parser.add_argument("--max_text_length", type=int, default=25)
diff --git a/tools/infer_rec.py b/tools/infer_rec.py
index cb8a6ec305..29aab9b578 100755
--- a/tools/infer_rec.py
+++ b/tools/infer_rec.py
@@ -141,6 +141,11 @@ def main():
paddle.to_tensor(valid_ratio),
paddle.to_tensor(word_positons),
]
+ if config['Architecture']['algorithm'] == "CAN":
+ image_mask = paddle.ones(
+ (np.expand_dims(
+ batch[0], axis=0).shape), dtype='float32')
+ label = paddle.ones((1, 36), dtype='int64')
images = np.expand_dims(batch[0], axis=0)
images = paddle.to_tensor(images)
if config['Architecture']['algorithm'] == "SRN":
@@ -149,6 +154,8 @@ def main():
preds = model(images, img_metas)
elif config['Architecture']['algorithm'] == "RobustScanner":
preds = model(images, img_metas)
+ elif config['Architecture']['algorithm'] == "CAN":
+ preds = model([images, image_mask, label])
else:
preds = model(images)
post_result = post_process_class(preds)
diff --git a/tools/program.py b/tools/program.py
index 5d2bd5bfb0..a0594e950d 100755
--- a/tools/program.py
+++ b/tools/program.py
@@ -273,6 +273,8 @@ def train(config,
preds = model(images, data=batch[1:])
elif model_type in ["kie"]:
preds = model(batch)
+ elif algorithm in ['CAN']:
+ preds = model(batch[:3])
else:
preds = model(images)
preds = to_float32(preds)
@@ -286,6 +288,8 @@ def train(config,
preds = model(images, data=batch[1:])
elif model_type in ["kie", 'sr']:
preds = model(batch)
+ elif algorithm in ['CAN']:
+ preds = model(batch[:3])
else:
preds = model(images)
loss = loss_class(preds, batch)
@@ -302,6 +306,9 @@ def train(config,
elif model_type in ['table']:
post_result = post_process_class(preds, batch)
eval_class(post_result, batch)
+ elif algorithm in ['CAN']:
+ model_type = 'can'
+ eval_class(preds[0], batch[2:], epoch_reset=(idx == 0))
else:
if config['Loss']['name'] in ['MultiLoss', 'MultiLoss_v2'
]: # for multi head loss
@@ -496,6 +503,8 @@ def eval(model,
preds = model(images, data=batch[1:])
elif model_type in ["kie"]:
preds = model(batch)
+ elif model_type in ['can']:
+ preds = model(batch[:3])
elif model_type in ['sr']:
preds = model(batch)
sr_img = preds["sr_img"]
@@ -508,6 +517,8 @@ def eval(model,
preds = model(images, data=batch[1:])
elif model_type in ["kie"]:
preds = model(batch)
+ elif model_type in ['can']:
+ preds = model(batch[:3])
elif model_type in ['sr']:
preds = model(batch)
sr_img = preds["sr_img"]
@@ -532,6 +543,8 @@ def eval(model,
eval_class(post_result, batch_numpy)
elif model_type in ['sr']:
eval_class(preds, batch_numpy)
+ elif model_type in ['can']:
+ eval_class(preds[0], batch_numpy[2:], epoch_reset=(idx == 0))
else:
post_result = post_process_class(preds, batch_numpy[1])
eval_class(post_result, batch_numpy)
@@ -629,7 +642,7 @@ def preprocess(is_train=False):
'CLS', 'PGNet', 'Distillation', 'NRTR', 'TableAttn', 'SAR', 'PSE',
'SEED', 'SDMGR', 'LayoutXLM', 'LayoutLM', 'LayoutLMv2', 'PREN', 'FCE',
'SVTR', 'ViTSTR', 'ABINet', 'DB++', 'TableMaster', 'SPIN', 'VisionLAN',
- 'Gestalt', 'SLANet', 'RobustScanner', 'CT', 'RFL', 'DRRG'
+ 'Gestalt', 'SLANet', 'RobustScanner', 'CT', 'RFL', 'DRRG', 'CAN'
]
if use_xpu:
 +

 +